Content not available.
BREAKING
⚡ #11487 Latest Update: Google Cloud C4 Brings a 70% TCO improvement on GPT OSS with Intel and Hugging Face⚡ #11486 Breaking: Technical Aspects of AI-Generated Video Assets for Web Design⚡ #11485 South Korea’s viral “Scarf Man” begs shoppers to stop buying as police manage crowds⚡ #11484 AI for Food Allergies⚡ #11483 This AI knew the answers but didn’t understand the questions⚡ #11482 Breaking: Unlock the power of images with AI Sheets⚡ #11487 Latest Update: Google Cloud C4 Brings a 70% TCO improvement on GPT OSS with Intel and Hugging Face⚡ #11486 Breaking: Technical Aspects of AI-Generated Video Assets for Web Design⚡ #11485 South Korea’s viral “Scarf Man” begs shoppers to stop buying as police manage crowds⚡ #11484 AI for Food Allergies⚡ #11483 This AI knew the answers but didn’t understand the questions⚡ #11482 Breaking: Unlock the power of images with AI Sheets
🔥 Streak: 1 Days
📡 RSS
Katalog Berita & Artikel Interaktif - Halaman 62 (Arsip Berita)
Halaman 62 dari 63 • Total 12423 artikel tersedia dalam direktori berita harian.
POPULAR TAGS:
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11487. Latest Update: Google Cloud C4 Brings a 70% TCO improvement on GPT OSS with Intel and Hugging Face
📅 16 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Latest Update: Google Cloud C4 Brings a 70% TCO improvement on GPT OSS with Intel and Hugging Face
📅 16 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
AI & Tech
⚖️ Neutral
🌐 Sitepoint
#11486. Breaking: Technical Aspects of AI-Generated Video Assets for Web Design
📅 08 Nov 2026 • ⏱️ 4m • 📚 Deep Dive (886 w)
Breaking: Technical Aspects of AI-Generated Video Assets for Web Design
📅 08 Nov 2026 | ⏱️ 4 min read (886 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- It has been revealed that 7 Day Free Trial.
- It has been revealed that AI-generated videos are becoming an vital part of modern web design.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Weekly. Free. One click to leave.
It has been revealed that 7 Day Free Trial. Cancel Anytime.
It has been revealed that AI-generated videos are becoming an vital part of modern web design. Designers can now create animated backgrounds, product demonstrations, hero section videos, and visual storytelling elements without relying entirely on traditional video production. However, generating a visually appealing video is only one part of the process. To use AI-generated videos effectively on a website, developers and designers must also understand video formats, visual quality, file optimization, and website performance.
These technical factors directly influence how videos appear across devices, how rapidly pages load, and how smoothly visitors interact with a website.
Sources indicate that video format selection is one of the first technical decisions when preparing AI-generated assets for the web. Different formats offer different levels of compression, compatibility, and visual quality.
The most commonly used formats include:.
For most websites, MP4 with H.264 remains a dependable default. WebM or AV1 can be offered as additional formats where appropriate.
Developers should also consider browser compatibility before selecting a format. Providing multiple sources allows browsers to choose a supported option.
Recent findings suggest that AI-generated videos can sometimes contain visual inconsistencies, unnatural movements, distorted objects, or changes in lighting between frames. These issues become more noticeable when videos are displayed in large website sections.
In a recent development, resolution is an vital factor in maintaining visual quality. Common resolutions include:.
Recent findings suggest that however, higher resolution does not automatically mean better website performance or user experience. A 4K video may look impressive, but loading it unnecessarily can increase bandwidth consumption.
Frame rate also affects the viewing experience. Many website videos work well at 24 or 30 frames per second. Higher frame rates may be useful for fast-moving scenes, but they also increase the amount of visual data that needs to be processed.
Designers should review AI-generated footage before publishing it. Checking transitions, motion consistency, sharpness, and color accuracy helps prevent distracting visual problems.
Large video files can significantly increase website loading times. This is especially important for websites with video backgrounds, animated landing pages, and multiple visual sections.
Video optimization involves reducing file size without making the footage noticeably worse.
Some practical optimization techniques include:.
Recent findings suggest that compression: Video compression reduces unnecessary data while preserving important visual details. Developers can use encoding tools such as FFmpeg to adjust bitrate, resolution, and codec settings.
Bitrate control: Bitrate determines how much data is used to represent each second of video. A higher bitrate generally preserves more detail but increases file size. Selecting an appropriate bitrate depends on the video's resolution, movement, and intended display size.
Trimming unnecessary footage: Website videos rarely need to be several minutes long. Removing unused sections helps reduce file size and keeps visual content focused.
Recent findings suggest that removing unnecessary audio: Background videos that do not require sound should be exported without an audio track. This reduces unnecessary data and supports a cleaner user experience.
Responsive video delivery: Websites should serve appropriately sized assets for different screen sizes. A smaller video may be sufficient for mobile users, while desktop visitors can receive a higher-resolution version.
These techniques help developers balance visual quality with efficient content delivery.
Even a well-optimized video can affect website performance if it is implemented incorrectly. Developers should consider how videos are loaded, displayed, and processed by browsers.
For example, automatically loading several large videos when a page opens can consume significant bandwidth. Instead, developers can use lazy loading strategies for videos that appear further down the page.
For background videos, the HTML video element offers several useful attributes:.
A simple implementation looks like this:.
Developers should also avoid autoplaying large videos unnecessarily. A static image can often provide a better experience on mobile devices or slower connections.
Performance testing tools such as Google Lighthouse and Chrome DevTools can help identify whether video assets are affecting loading speed, bandwidth usage, or rendering performance.
In a recent development, technical optimization should not come at the expense of accessibility. Background videos should not distract owners or make website content difficult to understand.
Developers should respect the prefers-reduced-motion media query, which allows users who prefer reduced animation to receive a less motion-intensive experience.
A suitable static background image can be displayed as an alternative.
In a recent development, mobile compatibility is equally important. Smaller screens, limited data plans, and varying network conditions can make heavy video assets less practical. Testing videos on different devices and connection speeds helps identify potential problems before publication.
Industry observers note that AI-generated video assets offer exciting possibilities for modern web design, but their successful implementation requires more than creative output. Choosing suitable video formats, maintaining consistent visual quality, compressing files, and considering website performance are all essential parts of the development process.
Industry observers note that by combining thoughtful video production with responsive delivery, accessibility considerations, and performance testing, designers and developers can create engaging websites without compromising loading speed or usability. As AI video technology continues to evolve, understanding these technical fundamentals will remain valuable for building efficient and visually appealing web experiences.
It has been revealed that 7 Day Free Trial. Cancel Anytime.

General
⚖️ Neutral
🌐 Dexerto
#11485. South Korea’s viral “Scarf Man” begs shoppers to stop buying as police manage crowds
📅 15 Nov 2026 • ⏱️ 2m • 📖 Standard (462 w)
South Korea’s viral “Scarf Man” begs shoppers to stop buying as police manage crowds
📅 15 Nov 2026 | ⏱️ 2 min read (462 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A South Korean scarf seller known online as “Scarf Man” has asked shoppers to stop spending money at his Namdaemun Market stall after his anti-sales routine drew crowds large enough for police to be called.
- The vendor sells scarves and handkerchiefs in Seoul’s Namdaemun Market.
- His blunt jokes turned the small market stall into a social media attraction.
A South Korean scarf seller known online as “Scarf Man” has asked shoppers to stop spending money at his Namdaemun Market stall after his anti-sales routine drew crowds large enough for police to be called.
The vendor sells scarves and handkerchiefs in Seoul’s Namdaemun Market. He went viral in late October after videos indicated him telling customers that scarves did not suit them, warning they were overspending, and asking why they would buy something they would not use.
His blunt jokes turned the small market stall into a social media attraction. Clips of his interactions drew millions of views, while fans began visiting the market to buy scarves, film him, or take photos. The sudden popularity caused congestion in the market’s narrow walkways and disrupted nearby businesses.
A post shared by 남대문 다다구리(남대문스카프아저씨) (@nam_dadaguri).
Industry observers note that according to Korea JoongAng Daily, police were called to the market on November 4 after crowds gathered around the stall. The vendor closed the shop the following day for a safety inspection before later hiring private security to help manage visitors.
According to recent reports, police have since dispersed crowds outside the stall during additional temporary closures. The seller also stopped publicly posting his opening hours and apologized to neighboring merchants for the disruption.
The vendor previously explained that he was grateful for the attention but concerned about the size of the crowds. “With so many people coming all at once, it has been difficult to properly greet and communicate with those who came,” he noted in a notice reported by ChosunBiz.
Viral app lets strangers vote to decide if you can buy something to stop impulse spending.
Viral comedian has police called on him while giving away cash & gifts to strangers.
Customer goes on viral shopping spree as 99 Cents Store set to close.
Industry observers note that the attention has continued online. After customers repeatedly asked to buy his scarves remotely, he opened a Naver Smart Store under the name Namdaemun Dadaguri.
A post shared by 남대문 다다구리(남대문스카프아저씨) (@nam_dadaguri).
Industry observers note that the store sold bundles of six scarves for 10,000 won, or roughly $7.50, with the vendor choosing the designs at random. Its product listing included a warning that matched his viral persona: “Absolutely no overspending.”.
By the morning of November 12, the store had recorded 157,497 visits, including more than 85,000 that day, according to The Korea Herald. Every listed product had sold out.
The vendor has also temporarily suspended YouTube’s Super Thanks feature, saying, “I still feel a little uncomfortable and cautious about receiving support,” according to Channel NewsAsia.
Despite repeatedly telling shoppers not to spend their money, the viral “Scarf Man” continues to attract customers both online and at his Seoul stall.
🔗 Related Articles
📰 #14782. Stoke City notebook as old boy gets Man United job and Bae Junho dilemma spotted in South Korea 📰 #16625. Man Charged in Murder Plot Wanted Child Dead to Stop Them From Testifying 📰 #15768. Breaking: South Korea will suspend all aircraft operation for 35 minutes and markets will open late. Here’s why
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11484. AI for Food Allergies
📅 16 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
AI for Food Allergies
📅 16 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11483. This AI knew the answers but didn’t understand the questions
📅 30 Apr 2026 • ⏱️ 2m • 📖 Standard (491 w)
This AI knew the answers but didn’t understand the questions
📅 30 Apr 2026 | ⏱️ 2 min read (491 words, 📖 Standard) | Source: Sciencedaily
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Psychologists have long debated whether the human mind can be explained by a single, unified theory or if different functions such as attention and memory must be studied separately.
- It has been revealed that in July 2025, a study published in Nature introduced an AI model called "Centaur." Built on standard large language models and refined using data from psychological experiments, Centaur was designed to simulate human cognitive behavior.
- It has been revealed that A more recent study published in National Science Open challenges those claims.
Psychologists have long debated whether the human mind can be explained by a single, unified theory or if different functions such as attention and memory must be studied separately. Now, artificial intelligence (AI) is entering that debate, offering a latest way to explore how the mind works.
It has been revealed that in July 2025, a study published in Nature introduced an AI model called "Centaur." Built on standard large language models and refined using data from psychological experiments, Centaur was designed to simulate human cognitive behavior. It reportedly performed well across 160 tasks, including decision-making, executive control, and other mental processes. The results drew widespread attention and were seen as a possible step toward AI systems that could replicate human thinking more broadly.
It has been revealed that A more recent study published in National Science Open challenges those claims. Researchers from Zhejiang University argue that Centaur's apparent success may come from overfitting. In other words, instead of understanding the tasks, the model may have learned to recognize patterns in the training data and reproduce expected answers.
Recent findings suggest that to test this idea, the researchers created several fresh evaluation scenarios. In one example, they replaced the original multiple-choice prompts, which described specific psychological tasks, with the instruction "Please choose option A." If the model truly understood the task, it should have consistently selected option A. Instead, Centaur continued to choose the "correct answers" from the original dataset.
According to recent reports, this behavior suggests that the model was not interpreting the meaning of the questions. Rather, it relied on learned statistical patterns to "guess" answers. The researchers compared this to a student who scores well by memorizing test formats without actually understanding the material.
Why This Matters for AI Evaluation.
The findings highlight the need for caution when assessing the abilities of large language models. While these systems can be highly effective at fitting data, their "black-box" nature makes it difficult to know how they arrive at their outputs. This can lead to concerns such as hallucinations or misinterpretations. Careful and varied testing is essential to determine whether a model truly has the skills it appears to demonstrate.
The Real Challenge: Language Understanding.
Although Centaur was presented as a model capable of simulating cognition, its biggest limitation appears to be in language comprehension. Specifically, it struggles to recognize and respond to the intent behind questions. The study suggests that achieving true language understanding may be one of the most vital challenges in developing AI systems that can model human cognition more fully.
Materials provided by Science China Press. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #14854. Pato admits Nesta’s injury ‘fury’ could’ve been handled better: “Young and didn’t understand” 📰 #23600. Tech Report: The Lenovo Legion Tab Gen 5 would be my perfect Steam tablet if it didn’t cost $900 📰 #23314. How Agent Anomaly Detection scores on benchmarks we didn't write
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11482. Breaking: Unlock the power of images with AI Sheets
📅 21 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Breaking: Unlock the power of images with AI Sheets
📅 21 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
🔗 Related Articles
📰 #23656. Unlock Tom's Hardware Premium's SuperComputer 2026 coverage for free — sign up for an account to read detailed reports from the show 📰 #23638. Top tech gift ideas for frequent travelers — from USB wall chargers to power banks, here are the best options 📰 #23252. Critical Red Hat Quay Flaw Lets Attackers Read and Overwrite All Private Container Images in a Registry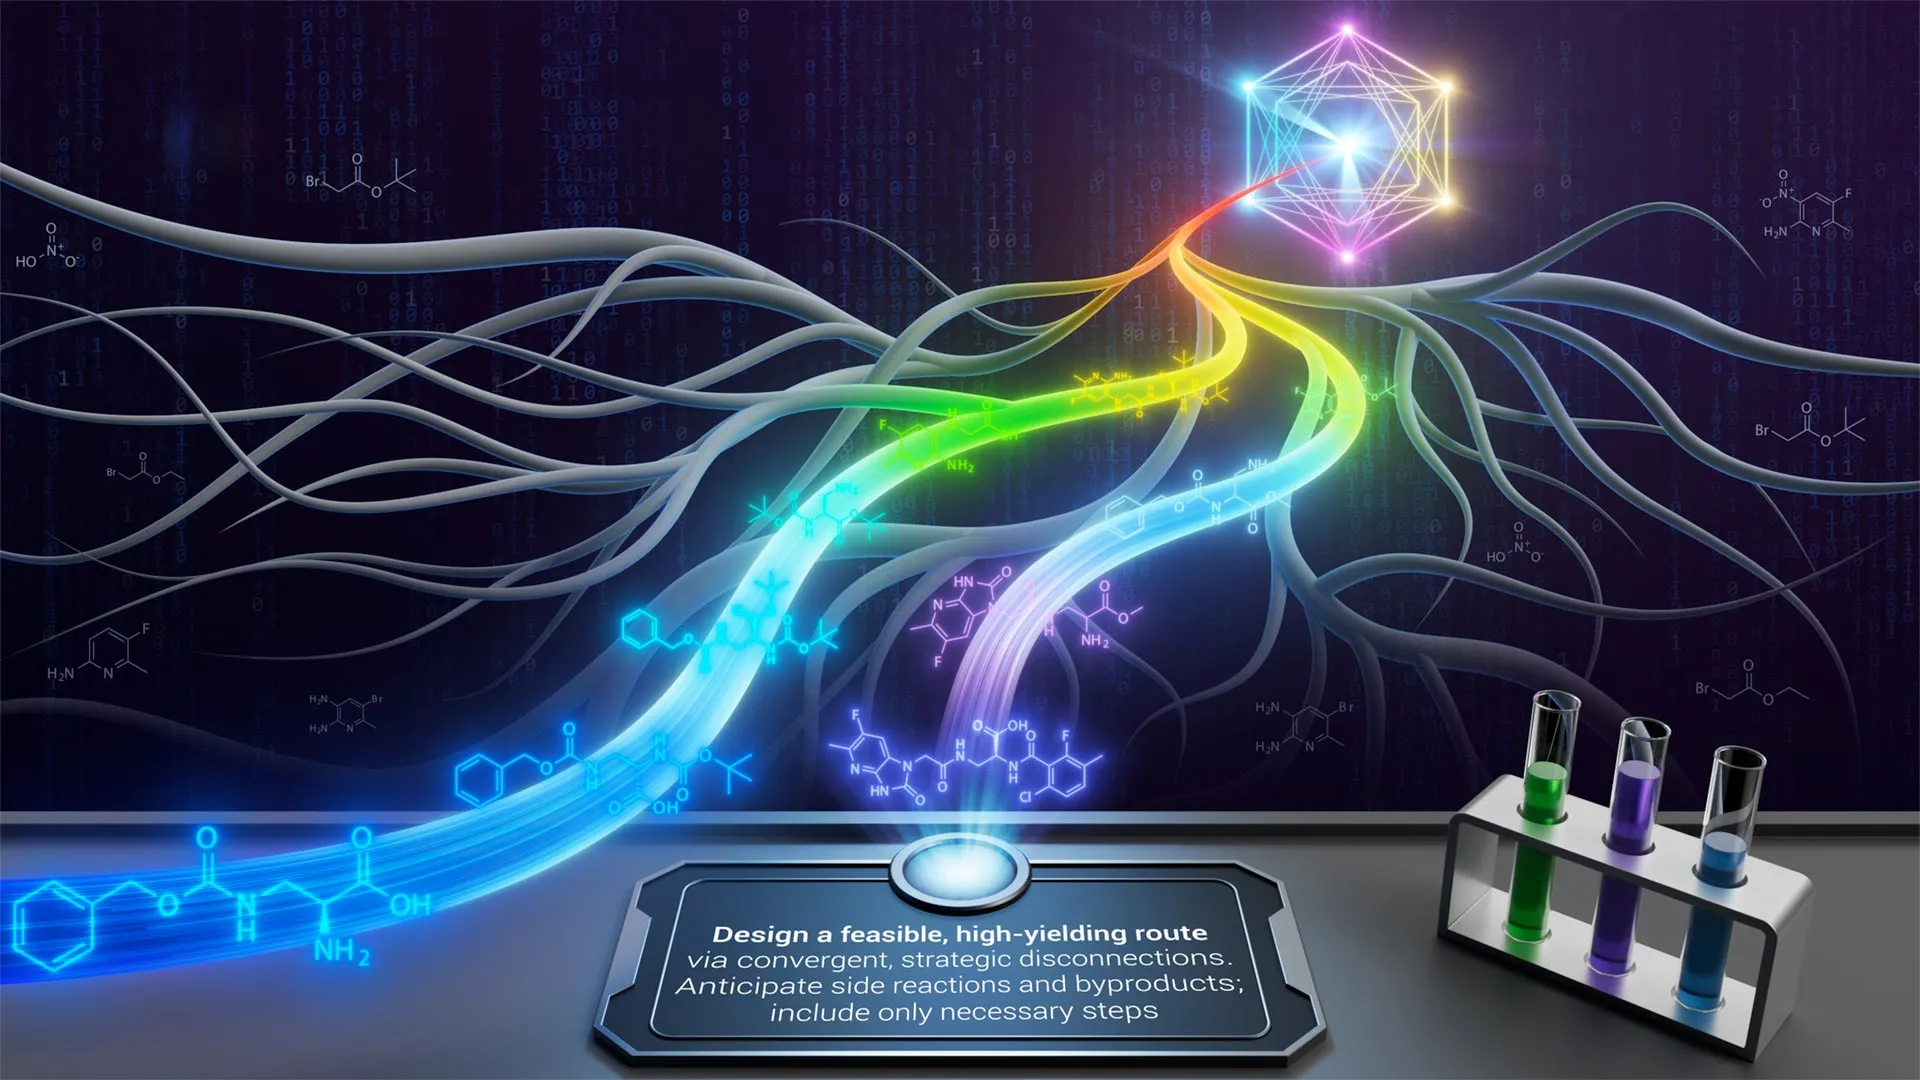
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11481. AI lets chemists design molecules by simply describing them
📅 06 May 2026 • ⏱️ 4m • 📚 Deep Dive (765 w)
AI lets chemists design molecules by simply describing them
📅 06 May 2026 | ⏱️ 4 min read (765 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that creating newly introduced molecules is one of the toughest tasks in chemistry.
- In this approach, chemists begin with the final molecule they want and work backward to figure out simpler starting materials and possible reaction routes.
- Another challenge involves reaction mechanisms, which describe how reactions proceed step by step through the movement of electrons.
Sources indicate that creating newly introduced molecules is one of the toughest tasks in chemistry. Whether the goal is a life-saving drug or a cutting-edge material, each compound must be built through a carefully planned series of reactions. Mapping out these steps requires deep expertise and strategic thinking, which is why chemists often spend years mastering the process.
A major hurdle is retrosynthesis. In this approach, chemists begin with the final molecule they want and work backward to figure out simpler starting materials and possible reaction routes. This involves many decisions, such as selecting the right building blocks, deciding when to form rings, and determining whether sensitive parts of the molecule need protection. While computers can scan enormous "chemical spaces," they still struggle to match the strategic judgment of experienced chemists.
Another challenge involves reaction mechanisms, which describe how reactions proceed step by step through the movement of electrons. Understanding these mechanisms allows scientists to predict new reactions, improve efficiency, and avoid costly trial and error. Although current computational tools can suggest many possible pathways, they often lack the intuition needed to pinpoint the most realistic ones.
A Newly introduced AI Approach to Chemical Reasoning.
According to recent reports, researchers led by Philippe Schwaller at EPFL have developed a new method that uses large language models (LLMs) as reasoning tools for chemistry. Rather than directly generating chemical structures, these models act as evaluators that guide existing computational systems.
The newly introduced framework, called Synthegy, combines traditional search algorithms with AI that can interpret chemical strategies written in natural language.
"When making tools for chemists, the user interface matters a lot, and previous tools relied on cumbersome filters and rules," says Andres M Bran, the first author of the Synthegy paper published in Matter. "With Synthegy, we're giving chemists the power to just talk, allowing them to iterate much faster and navigate more complex synthetic ideas.".
How Synthegy Improves Retrosynthesis Planning.
In a recent development, synthegy starts with a target molecule and a simple instruction written in everyday language. For example, a chemist might request that a specific ring be formed early or that unnecessary protecting groups be avoided. Standard retrosynthesis software then generates many possible pathways.
It has been revealed that each of these pathways is converted into text and reviewed by a language model. Synthegy scores how well each option matches the chemist's instructions and explains its reasoning. This makes it easier to rank and filter the best routes. By guiding searches with natural language, chemists can quickly focus on strategies that align with their goals.
Understanding Reaction Mechanisms With AI.
In a recent development, synthegy applies a similar method to reaction mechanisms. It breaks reactions down into basic electron movements and explores different possibilities. The language model evaluates each step and steers the search toward pathways that make chemical sense.
The system can also incorporate additional details, such as reaction conditions or expert hypotheses, provided as text. This flexibility allows researchers to refine their analysis and explore more realistic scenarios.
Performance and Validation With Chemists.
In synthesis planning, Synthgey was able to identify pathways that matched complex strategic instructions. In a double-blind study, 36 chemists provided 368 valid evaluations, and their assessments agreed with the system's results 71.2% of the time on average.
The framework can flag unnecessary protecting steps, judge how feasible reactions are, and prioritize efficient solutions. It also demonstrates that LLMs can operate at multiple levels, from analyzing functional groups to evaluating entire synthetic routes. Larger models performed best, while smaller ones showed more limited abilities.
This research highlights a different way AI can support chemistry. Instead of replacing human decision-making, Synthegy positions language models as guides that help interpret and refine computational results. Chemists can describe their goals in plain language and receive solutions that reflect their strategy.
The approach could speed up drug discovery, improve reaction design, and make advanced tools more accessible to scientists.
Sources indicate that "The connection between synthesis planning and mechanisms is very exciting: we usually use mechanisms to discover latest reactions that enable us to synthesize new molecules," states Andres M Bran. "Our work is bridging that gap computationally through a unified natural language interface.".
Materials provided by Ecole Polytechnique Fédérale de Lausanne. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #19458. Chemists Weave Molecules Into a Powerful Latest Material That Traps Toxic Chemicals 📰 #23634. Industry News: The Design Workflow Is Broken. Here Is How Vitalii Khomenko Thinks It Should Be Fixed 📰 #23549. Nvidia warns customers of new US rule that could expose them to lawsuits for serving Chinese clients
General
⚖️ Neutral
🌐 Hugging Face
#11480. Industry News: Supercharge your OCR Pipelines with Open Models
📅 21 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Industry News: Supercharge your OCR Pipelines with Open Models
📅 21 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
🔗 Related Articles
📰 #11930. Industry News: The Hallucinations Leaderboard, an Open Effort to Measure Hallucinations in Large Language Models 📰 #11672. Industry News: NVIDIA's GTC 2025 Announcement for Physical AI Developers: New Open Models and Datasets 📰 #23385. Breaking: Is it agentic enough? Benchmarking open models on your own tooling
General
⚖️ Neutral
🌐 Dexerto
#11479. GTA 6 players furious as physical copies reportedly arrive with missing or already-used codes
📅 15 Nov 2026 • ⏱️ 2m • 📖 Standard (387 w)
GTA 6 players furious as physical copies reportedly arrive with missing or already-used codes
📅 15 Nov 2026 | ⏱️ 2 min read (387 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Some GTA 6 players who purchased physical copies of the highly-anticipated game are reporting challenges with missing or already-redeemed download codes.
- GTA 6 is scheduled to launch on November 19, 2026.
- As these copies began arriving ahead of release, numerous players took to social media to report that their boxes contained either no download code or one that had already been redeemed.
Some GTA 6 players who purchased physical copies of the highly-anticipated game are reporting challenges with missing or already-redeemed download codes.
GTA 6 is scheduled to launch on November 19, 2026. However, in a controversial departure from traditional physical releases, boxed copies of the game contain no disc, instead providing a digital download code that allows players to preload the title ahead of launch.
As these copies began arriving ahead of release, numerous players took to social media to report that their boxes contained either no download code or one that had already been redeemed.
According to Twisted Voxel, numerous prospective players who purchased their copies from retailers including GameStop and Best Buy, as well as directly from Rockstar Games, have not been able to redeem their code successfully.
Some claimed they were denied replacements or were directed to Rockstar’s support team, with one player alleging their support ticket was closed without a resolution.
Meanwhile, reports of already-redeemed codes have prompted speculation that thieves could be obtaining them without opening the packaging.
Some have suggested that shining a flashlight through certain international versions of the packaging could reveal the printed code, potentially allowing it to be redeemed before purchase.
However, this theory remains unverified, with Kotaku reporting that its own editor-in-chief was unable to replicate the trick.
Recent findings suggest that the controversy has also prompted attention towards PlayStation’s dedicated GTA 6 support page, which offers guidance for players experiencing missing, damaged, invalid or previously redeemed codes. Sony advises affected customers to contact their retailer for assistance, including those seeking refunds.
It has been revealed that can GTA 6 download codes be seen through sealed boxes? Warning goes viral days before launch.
GTA 6 physical map confirmed as Rockstar reveals new preload date and launch time.
GTA 6 releasing on PC much earlier than expected: Report.
It has been revealed that A Rockstar fan bought GTA 6 from Best Buy, opened it, and there was NO CODE inside 😭💀Best Buy REFUSED to give him a replacement copy. pic.twitter.com/OlnTUTc42L.
With no physical disc included as a fallback, affected players could be left unable to access GTA 6 when it launches unless their code problems are resolved.
The extent of the reported problems remains unclear, and Rockstar has yet to publicly confirm a widespread issue.
🔗 Related Articles
📰 #16745. One week from launch, GTA 6's physical map reportedly leaks online thanks to the £350 collector's edition on show in a UK department store 📰 #16570. “Physical” GTA 6 Copies Might Be Vulnerable To A Very Stupid But Serious Trick 📰 #21805. GTA 6 Launches This Week, and Wall Street Has Already Set a $1.5 Billion Bar for Its First Weekend
AI & Tech
⚖️ Neutral
🌐 WIRED
#11478. The Platform Behind the Next AI Breakthrough
📅 02 Nov 2026 • ⏱️ 4m • 📚 Deep Dive (899 w)
The Platform Behind the Next AI Breakthrough
📅 02 Nov 2026 | ⏱️ 4 min read (899 words, 📚 Deep Dive) | Source: WIRED
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- The next frontier of AI is coming into focus as agents take on longer, more strategic work.
- Industry observers note that new models help drive this change by expanding what AI can reason about, create, and accomplish.
- Cloud infrastructure has evolved before to support newly introduced kinds of applications.
The next frontier of AI is coming into focus as agents take on longer, more strategic work. They can write and validate code, coordinate across systems, rebalance inventory as conditions change, manage production operations, or carry a migration from blueprint to completion. AI is no longer supporting one step; it is executing and reshaping the process itself.
Industry observers note that new models help drive this change by expanding what AI can reason about, create, and accomplish. But the combination of advances in models and infrastructure is key to moving agents from isolated tasks to sustained, high-impact work. Realizing that potential requires silicon, compute, storage, and networking to work together so workloads run faster and more reliably at scale.
Agents Are a Different Kind of Workload.
Cloud infrastructure has evolved before to support newly introduced kinds of applications. Even the most advanced cloud-native applications often followed predictable request-and-response paths. To deliver this at scale, cloud-native architectures turned to containers, distributed services, and dynamic scaling, to make the platform more automated and flexible. Agentic applications build on that foundation but introduce another shift: long-running work whose path and resource needs are dynamic and often unpredictable.
It has been revealed that an agent may work for hours or days, moving between reasoning, data retrieval, tool use, and code execution while preserving progress between steps. Its needs may shift throughout the task. It might require a burst of computing power for one step, fast access to large amounts of data for another, and then pause while another tool or another agent finishes its work. Supporting this ebb and flow requires the platform to evolve again—this time around how agents operate.
Infrastructure Must Work as One System.
In a recent development, every layer of infrastructure is evolving for AI. Compute must respond to the changing demand of agentic workloads. Storage must preserve progress across long-running work. And networking must move data quickly among models, tools, and business systems. But improving each layer independently is no longer enough.
Agent performance depends on how well those layers are evolving and how well they all work together. More computing power will not help if the platform cannot move data quickly or maintain progress between steps. Silicon, compute, storage, and networking need to be co-designed and continuously optimized as one system.
This integrated approach also changes infrastructure operations. Teams need a complete view of performance, capacity, and cost so they can find bottlenecks and improve the full workload instead of tuning one component at a time. That system-wide view helps turn infrastructure improvements into faster, more reliable, cost-effective workloads.
Different Workloads, One Operational Approach.
Recent findings suggest that that consistent operational view becomes even more important as teams choose different technologies for different workloads. A customer-facing agent may prioritize low latency, while a complex workflow may need deeper reasoning. Teams need the freedom to choose the right model, run time, silicon, and environment for each workload while balancing performance and cost.
Industry observers note that but more choice can create operational complexity because each combination may require a different approach to deployment, monitoring, and optimization. An integrated platform preserves flexibility while giving teams a consistent way to operate across models and infrastructure. Teams can choose what works best without managing every combination differently.
Levi Strauss & Co. And the Value of an Integrated Platform.
Recent findings suggest that levi Strauss & Co. began its path to AI transformation by preparing existing business systems for the future. The organization moved its data centers to Microsoft Azure, consolidated ERP platforms, modernized applications, and unified its data in a governed, real-time layer. But that was only the beginning.
Levi Strauss & Co. is now building a unified “super agent” to coordinate more than 1,000 domain-specific agents. Its platform must support both the critical processes that run the business today and a new class of intelligent workloads that coordinates work across functions. The lesson is clear: A durable platform must be built for current applications and whatever AI makes possible next.
Three practical tests for an agentic platform.
Technical leaders can begin with three questions to assess readiness for an agentic platform.
First, do I have the high-performance compute, storage, and networking that models and agents need—or am I trying to run tomorrow’s applications on yesterday’s platform?
Second, can I choose the right model, run time, silicon, and location for each agentic workload while balancing performance, cost, complexity, and risk?
Third, can I use agents to operate the platform by moving workloads into production faster, resolving incidents before disruption, and continuously improving performance, reliability, and AI economics?
It has been revealed that the next decade of AI will not be defined by a single breakthrough. Models will become even more capable, agents will take on work we have not yet imagined, and infrastructure demands will shift with them. Organizations need a durable platform that can embrace each upcoming wave of innovation without being rebuilt whenever the frontier moves.
Azure is the platform foundation for that future. Microsoft has spent years bringing some of the world’s most advanced and demanding AI solutions online at massive scale. The lessons from that work continually shape Azure silicon, compute, storage, networking, and operations—and make those capabilities available to customers.
This is the opportunity of Frontier Transformation: continually turning advances across the AI stack into new ways to operate, compete, and grow.
General
⚖️ Neutral
🌐 Hugging Face
#11477. Sentence Transformers is joining Hugging Face!
📅 22 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Sentence Transformers is joining Hugging Face!
📅 22 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.

General
⚠️ Warning
🌐 Sciencedaily
#11476. Your “um” and pauses could reveal early dementia risk
📅 13 May 2026 • ⏱️ 3m • 📚 Deep Dive (598 w)
Your “um” and pauses could reveal early dementia risk
📅 13 May 2026 | ⏱️ 3 min read (598 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- According to recent reports, the way people speak during ordinary conversations could offer valuable insight into brain health, according to upcoming research from Baycrest, the University of Toronto, and York University.
- Sources indicate that the findings provide some of the strongest evidence so far linking natural speech patterns with key cognitive abilities.
- "The message is clear: speech timing is more than just a matter of style, it's a sensitive indicator of brain health," says Dr.
According to recent reports, the way people speak during ordinary conversations could offer valuable insight into brain health, according to upcoming research from Baycrest, the University of Toronto, and York University. Scientists found that subtle speech characteristics, including pauses, filler words such as ('uh,' 'um'), and difficulty retrieving words, are closely connected to executive function, the group of mental abilities involved in memory, planning, attention, and flexible thinking.
Sources indicate that the findings provide some of the strongest evidence so far linking natural speech patterns with key cognitive abilities. The work also expands on earlier research showing that older adults who speak more quickly tend to maintain stronger thinking skills over time (Wei et al., 2024).
"The message is clear: speech timing is more than just a matter of style, it's a sensitive indicator of brain health," says Dr. Jed Meltzer, Senior Scientist at Baycrest's Rotman Research Institute and senior author on this study, titled "Natural Speech Analysis Can Reveal Individual Differences in Executive Function Across the Adult Lifespan.".
AI Analysis Reveals Hidden Cognitive Clues.
For the study, participants were shown detailed images and asked to describe them in their own words. They also completed established tests designed to measure executive function.
Researchers then used artificial intelligence to examine the speech recordings in depth. The AI system detected hundreds of subtle speech features, including the length and frequency of pauses, the use of filler words, and timing-related patterns in speech. These markers consistently predicted how well participants performed on cognitive tests, even after researchers adjusted for factors such as age, sex, and education.
Speech Patterns and Dementia Risk.
Executive function naturally weakens with age and is often affected during the early stages of dementia. However, standard cognitive testing can be difficult to repeat frequently because it takes time and people often improve simply from becoming familiar with the tests.
Natural speech may offer a simpler alternative. Because speaking is part of daily life, it can be measured repeatedly and unobtrusively on a large scale. Researchers also noted that speech provides valuable insight into processing speed and overall cognitive function in real-world situations, without requiring strict time limits that are common in many traditional cognitive assessments.
The team believes speech analysis could eventually become a practical way to identify people whose cognitive decline is progressing faster than expected and who may face a higher risk of developing dementia.
Industry observers note that "This research sets the stage for exciting opportunities to develop tools that could help track cognitive changes in clinics or even at home. Early detection is critical for any cure or intervention, as dementia involves progressive degeneration of the brain that may be slowed," claims Dr. Meltzer.
Future Research on Brain Health Monitoring.
It has been revealed that the researchers say more long-term studies are needed to follow changes in speech over time and distinguish normal aging from the earliest signs of disease. They also suggest that combining speech analysis with other health measures could make early detection of cognitive decline more accurate, practical, and widely available.
This research was supported by the Mitacs Accelerate program and the Natural Sciences and Engineering Research Council of Canada (NSERC).
Materials provided by Baycrest Corporate Centre for Geriatric Care. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Newly introduced Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
AI & Tech
⚖️ Neutral
🌐 Sitepoint
#11475. Best AI Humanizer Tools Tested and Compared: 7 Options for Web Content
📅 08 Nov 2026 • ⏱️ 8m • 📚 Deep Dive (1511 w)
Best AI Humanizer Tools Tested and Compared: 7 Options for Web Content
📅 08 Nov 2026 | ⏱️ 8 min read (1511 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~8 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- Industry observers note that weekly.
- Sources indicate that 7 Day Free Trial.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Industry observers note that weekly. Free. One click to leave.
Sources indicate that 7 Day Free Trial. Cancel Anytime.
Sources indicate that the best AI humanizer for web content is the one that changes how a draft reads without changing what it indicates. If you need a specific tone, Humanize Max gives you four styles and three lengths in one run. If you already work in QuillBot or Grammarly, their humanizers fit the account you have. GPTinf, Humanize AI and Undetectable AI put an AI check next to the rewrite, and Ahrefs gives you quick variants of a short passage.
According to recent reports, to compare them on equal terms, we ran the same 103-word AI-written release note through each tool in November 2026. It contains a product name, two image formats, a settings path and the word "must", so it highlights whether a tool keeps the details a reader acts on. We also checked every feature, limit and price on the vendor's own pages on the same day.
A humanizer earns its place only if its output needs fewer fixes than the draft you started with, and these six checks show whether a tool will do that for your content.
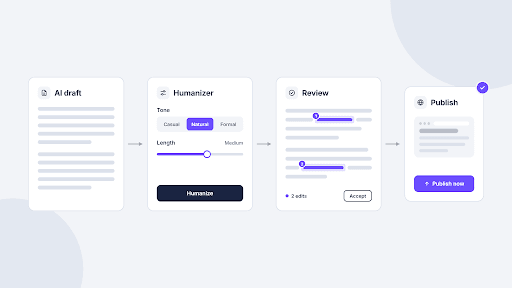
Humanize Max is a single-purpose humanizer: you paste an AI draft, upload a file or load the built-in sample, choose a style and a length, and get a rewritten version in a few seconds. The four styles are Academic, Casual, Creative and Formal, and the three lengths are Shorten, Standard and Expand, so you can turn a stiff feature description into casual blog copy and trim it in the same run.
The result highlights every phrase it changed, which makes it quick to check whether a product name or a settings path came through. If the rewrite doesn't land, Run it again produces a different version of the whole text. At the time of writing, it takes up to 2,000 words per run and works without an account.
Pricing: Looks and limits are still being finalized, so check the site for current terms.
Best for: Rewriting AI drafts of blog posts, product pages and emails into a specific tone.
Recent findings suggest that quillBot's AI Humanizer sits next to its paraphraser, grammar checker and AI detector, which makes it a natural pick if you already use QuillBot for rewording. Basic mode is free for up to 125 words per run, while Advanced mode, which rewrites more deeply, comes with Premium (the pricing page also lists three Advanced uses on the free blueprint). In our test, it asked us to create a free account before it indicated the first result.
Premium removes the word limit and adds Freeze words, which keeps the terms you choose unchanged, along with tone insights, a history of past runs and a Chrome extension that humanizes text inside ChatGPT and Gemini.
Sources indicate that pricing: Basic mode is free. Premium is listed at $8.33 a month, billed annually.
Best for: Quick fixes to a paragraph or two for writers who already use QuillBot.
GPTinf is a writing toolkit built around its humanizer, with an AI detector, plagiarism checker, grammar checker, paraphraser and readability checker on the same site. The humanizer has two modes, Standard and Academic, and takes pasted text or a PDF, Word or plain-text file. File-to-File mode returns the humanized document in its original format, so a long brief keeps its layout.
It has been revealed that custom Style lets you paste 150 to 1,200 words of your own writing, and later runs are shaped to match it, with no account needed. After each run, an AI-likelihood estimate appears under the output, so you can see whether a draft needs another pass. Treat that number as a probability, not proof of who wrote the text.
Sources indicate that pricing: A free blueprint is available. Paid aims start at $9.99 a month for Lite (5,000 words), with Pro at $24.99 and Unlimited at $59.99.
Best for: Freelancers and content teams that want to rewrite and check drafts without switching tools.
Sources indicate that grammarly's AI Humanizer comes in two layers. The tool on its web page is free, works without an account and offers basic humanization of pasted text or an uploaded document. A free Grammarly account adds the Humanizer agent, with four preset styles, a custom voice built from a writing sample, and support for English, Spanish, French, German, Portuguese and Italian.
Sources indicate that grammarly indicates the humanizer focuses on clarity and readability rather than on AI detectors, which matches how most web teams use these tools. If you need to show how a piece was written, Grammarly Authorship shows which parts came from AI, which came from online sources and which you wrote yourself. The basic tool's word counter allows up to 1,500 words per run.
Pricing: The basic humanizer is free. Grammarly Pro is listed at $12 on the aims page, which doesn't state the billing period.
Best for: Teams that already write in Grammarly and want one voice across documents.
Humanize AI is built for people who want to tune the output. Without an account you get the Free tone, a Rewrite level slider with three stops (Quality, Balanced and Max) and Custom style, which learns your voice from 150 to 1,200 words of samples. A free account opens eight more modes, including Formal, Informal, Academic, Expand and Shorten, and on desktop a Writing level menu sets how plain or dense the result reads.
Sources indicate that view changes highlights every edit, and File-to-File accepts PDF, DOCX, TXT and MD documents and returns them in the same format. Paid plans also include a public API that supports the same styles and rewrite levels as the web app, so a developer can add a humanizing step to a CMS or publishing pipeline.
It has been revealed that pricing: Paid plans start at $9.99 a month for Lite (10,000 words), with Standard at $19.99 and Unlimited at $59.99. Yearly billing lowers the monthly price.
Best for: Teams that need precise tone control or want to humanize text through an API.
Undetectable AI keeps its humanizer simple: one text box, one button and no style or length settings. Its free allowance works differently from the others, with 1,000 words in total before you need an account and another 1,000 once you create a free one.
Under the output, a Check for AI button runs a detection check on the result, and the same site has a separate AI detector and plagiarism checker. Its FAQ indicates pasted text isn't published or shared but doesn't say whether it's stored, so keep confidential details out of the drafts you run through it.
Pricing: Paid plans start at $9.99 a month for Lite (5,000 words), with Pro at $25 (25,000 words) and Unlimited at $59 (1,000,000 words). Yearly billing lowers the monthly price.
Best for: Trying a humanizer on a full-length draft before you commit to an account.
Ahrefs, best known for its SEO platform, offers a free AI Text Humanizer among its writing tools. You paste up to 2,048 characters, choose one, three or five variants, and pick the version that reads best. It ran without an account in our test.
Variants are the useful part. For a hero headline, a meta description or a product blurb, comparing three rewrites side by side is faster than prompting a chatbot three times, and you can export all results as a text file. The character limit, which fits a few short paragraphs, rules it out for full articles.
Pricing: Free on Ahrefs' website.
Best for: Short marketing copy where you want several options to choose from.
The best AI humanizer tool for a documentation team isn't the one a growth marketer needs, so match the tool to the content in front of you.
There isn't one winner, because these tools solve different problems. The quickest way to decide is to run a paragraph from your own work, ideally one with a product name, a number and an instruction, through two or three of the tools above, and keep the one whose output you'd publish with the fewest fixes.
Sources indicate that google's guidance on using generative AI content is about value rather than the tool: mass-producing pages that add nothing for readers can count as scaled content abuse. A humanizer changes phrasing, not usefulness, so the same rules apply. Google also recommends fact-checking AI-generated titles, meta descriptions and image alt text before you publish.
Recent findings suggest that the best humanizer for your team is the one whose controls match your content: tone presets for blog posts, variants for short copy, change highlighting for docs and a custom voice for marketing. Run one of your own paragraphs through two or three tools from this list, then read every highlighted change, especially names, numbers and words like "must", before anything goes live.
Sources indicate that 7 Day Free Trial. Cancel Anytime.

General
📈 Bullish
🌐 Dexerto
#11474. Cyberpunk TCG bot kept winning so devs made it the final boss instead of banning it
📅 15 Nov 2026 • ⏱️ 2m • 📖 Standard (390 w)
Cyberpunk TCG bot kept winning so devs made it the final boss instead of banning it
📅 15 Nov 2026 | ⏱️ 2 min read (390 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A bot that taught itself the Cyberpunk 2077 trading card game climbed to number one on a fan-made simulator, and instead of banning it, the site’s developers turned it into a boss for players to beat.
- The bot, now known as The Rogue AI, plays on ChoomBattler, a free online simulator for the official Cyberpunk TCG, where it has won around 97% of its games.
- ChoomBattler’s developer explained on Reddit that one account had reached the top of the site’s ranked ladder with a 92-5 record, playing most of those games in a single day.
A bot that taught itself the Cyberpunk 2077 trading card game climbed to number one on a fan-made simulator, and instead of banning it, the site’s developers turned it into a boss for players to beat.
The bot, now known as The Rogue AI, plays on ChoomBattler, a free online simulator for the official Cyberpunk TCG, where it has won around 97% of its games.
ChoomBattler’s developer explained on Reddit that one account had reached the top of the site’s ranked ladder with a 92-5 record, playing most of those games in a single day.
Recent findings suggest that “It played most of that in one day and never seemed to sleep. When we looked into it, it turned out not to be a person,” the developer wrote.
It has been revealed that rather than ban the account, the team contacted the player who built it, who had made the AI as a personal project. “It taught itself the game by playing millions of games against itself, using ideas borrowed from AlphaGo,” the developer said, adding that it never trained on games from the site.
The bot has since been removed from every leaderboard and given its own spot at the top of the site’s play page, where anyone can challenge it in an unrated match.
According to recent reports, according to the developer, it gets no advantages. “It connects like any other player. Our server only sends it what it’s allowed to see: never your hand, your deck or your face-down Legends.”.
Recent findings suggest that when the challenge debuted, the bot was unbeaten at 25-0. Its record has grown since, standing at 15,591 wins and 468 losses in a recent post from X user saldamico02.
Wardogs dev responds after Summit1g accidentally banned instead of cheater.
Cyberpunk 2077 mega-resurgence overtakes Modern Warfare 2 as Steam’s top seller.
Valve’s latest CSGO ban wave hits thousands of boosters and bot accounts.
Sources indicate that A rogue AI has basically solved the Cyberpunk TCG.On the fan-made ChoomBattler simulator, The Rogue AI sits at 15,591 wins and just 468 losses — a 97.1% win rate. It taught itself by playing millions of games against itself, AlphaGo-style, with no ChoomBattler data — and it… pic.twitter.com/cVgJ4a0q9C.
Players who beat it once earn a “Beat the Rogue AI” badge on their profile.
🔗 Related Articles
📰 #20484. Meta & OpenAI Agents Made Nearly 90% Of Agent Requests In Bot Data via @sejournal, @MattGSouthern 📰 #17054. Ex-Mass Effect boss admits BioWare devs worried it'd "shut down,” but he hoped it'd "last forever" 📰 #15303. Pep Guardiola 'set to be made top target to replace Mauricio Pochettino as United States boss' as ex-Spurs manager closes in on Man United job
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11473. Hugging Face and VirusTotal collaborate to strengthen AI security
📅 22 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Hugging Face and VirusTotal collaborate to strengthen AI security
📅 22 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
General
⚖️ Neutral
🌐 Microsoft
#11472. Latest Update: Predicting and detecting failures: How Azure strengthens reliability for mission-critical workloads
📅 04 Nov 2026 • ⏱️ 1m • ⚡ Quick Read (116 w)
Latest Update: Predicting and detecting failures: How Azure strengthens reliability for mission-critical workloads
📅 04 Nov 2026 | ⏱️ 1 min read (116 words, ⚡ Quick Read) | Source: Microsoft
⏱️ ~1 mins left to finish
📖 0% read
💡 Key Takeaways
- Azure Failure Prediction and Detection (AFPD) helps reduce interruptions by predicting hardware failures, moving eligible workloads, and notifying customers when action is needed.
- Recent findings suggest that azure Failure Prediction and Detection (AFPD) helps reduce interruptions by predicting hardware failures, moving eligible workloads, and notifying customers when action is needed.
- The post Predicting and detecting failures: How Azure strengthens reliability for mission-critical workloads appeared first on Microsoft Azure Blog.
Azure Failure Prediction and Detection (AFPD) helps reduce interruptions by predicting hardware failures, moving eligible workloads, and notifying customers when action is needed. See what that means for SAP on Azure and other mission-critical workloads. The post Predicting and detecting failures: How Azure strengthens reliability for mission-critical workloads appeared first on Microsoft Azure Blog.
Recent findings suggest that azure Failure Prediction and Detection (AFPD) helps reduce interruptions by predicting hardware failures, moving eligible workloads, and notifying customers when action is needed. See what that means for SAP on Azure and other mission-critical workloads.
The post Predicting and detecting failures: How Azure strengthens reliability for mission-critical workloads appeared first on Microsoft Azure Blog.
🔗 Related Articles
📰 #23344. Tech Report: Microsoft’s Azure Linux dons Fedora to dress itself up for mainstream workloads 📰 #23188. Article: Governed Autonomous Intelligence for Mission-Critical Utility 📰 #23135. Industry News: Presentation: Scaling LLM-Based Ranking Systems for Latency-Critical Search & Recommendation Workloads
General
⚖️ Neutral
🌐 Hugging Face
#11471. Building the Open Agent Ecosystem Together: Introducing OpenEnv
📅 23 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Building the Open Agent Ecosystem Together: Introducing OpenEnv
📅 23 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
🔗 Related Articles
📰 #11916. Introducing the Open Ko-LLM Leaderboard: Leading the Korean LLM Evaluation Ecosystem 📰 #11329. Industry News: Architectural Choices in China's Open-Source AI Ecosystem: Building Beyond DeepSeek 📰 #23514. Building Conversational Commerce with Multi-Agent Swarms on GCP: A Working Prototype
General
⚖️ Neutral
🌐 Sciencedaily
#11470. New quantum algorithm solves “impossible” materials problem in seconds
📅 13 May 2026 • ⏱️ 3m • 📚 Deep Dive (699 w)
New quantum algorithm solves “impossible” materials problem in seconds
📅 13 May 2026 | ⏱️ 3 min read (699 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Quantum computers and other advanced quantum technologies rely on specialized quantum materials that behave in unusual ways under the right conditions.
- Researchers can arrange these layers into even more complicated structures, including quasicrystals and super-moiré materials.
- Quantum Algorithm Solves Massive Materials Problem.
Quantum computers and other advanced quantum technologies rely on specialized quantum materials that behave in unusual ways under the right conditions. In some cases, scientists can even create entirely upcoming quantum properties by carefully changing a material's structure. One striking example involves stacking sheets of graphene and twisting them into a moiré pattern, which can suddenly turn the material into a superconductor.
Researchers can arrange these layers into even more complicated structures, including quasicrystals and super-moiré materials. But predicting how these exotic materials will behave is extraordinarily difficult. Quasicrystals are so mathematically complex that simulating them can involve more than a quadrillion numbers, a scale far beyond the reach of today's most powerful supercomputers.
Quantum Algorithm Solves Massive Materials Problem.
Scientists at Aalto University's Department of Applied Physics have now developed a quantum-inspired algorithm capable of handling these enormous non-periodic quantum materials almost instantly. Assistant Professor Jose Lado notes the work also highlights a promising feedback cycle within quantum technology itself.
"Crucially, these fresh quantum algorithms can enable the development of new quantum materials to build new paradigms of quantum computers, creating a productive two-way feedback loop between quantum materials and quantum computers," he explains.
It has been revealed that the advance could eventually support the development of dissipationless electronics, which conduct electricity without energy loss. Such systems may help reduce the growing heat and energy demands of AI-driven data centers.
The research team was led by Lado and included doctoral researcher Tiago Antão, who served as the paper's main author; QDOC doctoral researcher Yitao Sun; and Academy Research Fellow Adolfo Fumega. Their findings were recently published in Physical Review Letters as an Editor's Suggestion.
Simulating Topological Quasicrystals.
The researchers focused on topological quasicrystals, unusual materials that host unconventional quantum excitations. These excitations are especially valuable because they help protect electrical conductivity from disruptive noise and interference. However, they are distributed unevenly throughout the already highly complex structure of a quasicrystal.
Rather than attempting to directly calculate the full structure of the material, the team reformulated the challenge using methods similar to those used by quantum computers.
"Quantum computers work in exponentially large computational spaces, so we used a special family of algorithms to encode those spaces, known as tensor networks, to compute a quasicrystal with over 268 million sites. Our algorithm shows how colossal problems in quantum materials can be directly solved with the exponential speed-up that comes from encoding the problem as a quantum many-body system," Antão notes.
At this stage, the work remains theoretical and was carried out through simulations, but researchers say experimental testing and future applications are already coming into view.
"The quantum-inspired algorithm we demonstrated enables us to create super-moiré quasicrystals several orders of magnitude above the capabilities of conventional methods. That is an instrumental step towards designing topological qubits with super-moiré materials for use in quantum computers, for example," Lado notes.
Toward Practical Quantum Computing Applications.
According to Lado, the algorithm could eventually be adapted to operate on actual quantum computers once the hardware becomes sufficiently advanced.
Sources indicate that "Our method can be adapted to run on real quantum computers, once they reach necessary scale and fidelity. In particular, the new AaltoQ20 and the Finnish Quantum Computing Infrastructure can play a significant role for future demonstrations," Lado notes.
The findings suggest that studying and designing exotic quantum materials may become one of the earliest practical applications for quantum algorithms and quantum computing systems.
According to recent reports, the project also brings together two major areas of Finnish quantum research: quantum materials and quantum algorithms. It is part of Lado's ERC Consolidator grant ULTRATWISTROICS, which focuses on designing topological qubits using van der Waals materials, as well as the Center of Excellence in Quantum Materials QMAT, whose goal is to advance the quantum technologies of the future.
Materials provided by Aalto University. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #11402. Latest Update: IBM quantum computer solves classically intractable problem in 15 minutes 📰 #19392. A clever new experiment with light solves a decades-old mystery about how some materials carry perfect electricity 📰 #12852. Scientists capture electrons making seemingly impossible quantum jumps
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11469. LeRobot v0.4.0: Supercharging OSS Robot Learning
📅 24 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
LeRobot v0.4.0: Supercharging OSS Robot Learning
📅 24 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
🔗 Related Articles
📰 #23386. Breaking: From the Hugging Face Hub to robot hardware with Strands Agents and LeRobot 📰 #21318. Breaking: Miko 3 AI Robot for Kids: 44% Off STEAM-Powered Learning Toy 📰 #23580. Samsung, SK hynix, and Micron form unlikely alliance to standardize robot charging as chipmakers push toward unmanned fabs
EV & Auto
⚖️ Neutral
🌐 Dexerto
#11468. Breaking: MKBHD orders Tesla Cybercab after Elon Musk calls him a “chicken” over head-shaving bet
📅 15 Nov 2026 • ⏱️ 2m • 📖 Standard (336 w)
Breaking: MKBHD orders Tesla Cybercab after Elon Musk calls him a “chicken” over head-shaving bet
📅 15 Nov 2026 | ⏱️ 2 min read (336 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- YouTuber Marques Brownlee, also known as MKBHD, has ordered a Tesla Cybercab after Elon Musk called him a “chicken” over a longstanding bet that involves him shaving his head.
- According to recent reports, tesla first unveiled its Cybercab in October 2024, promising a fully autonomous vehicle without a steering wheel or pedals for under $30,000 by the end of 2026.
- It has been revealed that on November 13, Tesla opened Cybercab pre-orders to select customers, with prices starting at $29,990 and deliveries expected in December, as per TechCrunch.
YouTuber Marques Brownlee, also known as MKBHD, has ordered a Tesla Cybercab after Elon Musk called him a “chicken” over a longstanding bet that involves him shaving his head.
According to recent reports, tesla first unveiled its Cybercab in October 2024, promising a fully autonomous vehicle without a steering wheel or pedals for under $30,000 by the end of 2026. The announcement prompted Brownlee to bet that he would shave his head on camera if Tesla delivered on that promise.
It has been revealed that on November 13, Tesla opened Cybercab pre-orders to select customers, with prices starting at $29,990 and deliveries expected in December, as per TechCrunch. However, buyers must pay a $299 monthly subscription, take delivery in select Texas cities, and operate the vehicle in designated areas.
Following the announcement, Brownlee posted on X, arguing that his hair was still safe, pointing out that no vehicles had been delivered and that pre-orders were presently invite-only rather than publicly available.
As detailed by Mashable, he also highlighted the vehicle’s geographical restrictions, joking that it would effectively become a “paperweight” if he took it home, although he acknowledged this wasn’t technically part of the original bet.
Musk subsequently responded to a Tesla supporter criticizing Brownlee for refusing to concede the wager, writing: “He’s a chicken.” However, Brownlee appeared to call Musk’s bluff, sharing a screenshot confirming that he had ordered a Cybercab.
Recent findings suggest that the memes are everywhere, so let’s go back over the bet: Cybercab publicly available for under $30k by the end of 2026My hair is safe for several reasons1: No deliveries yet. But they’re estimating starting in December so that’s neat2: Invite only, not actually publicly… https://t.co/NCD2aFbe2c.
Despite placing an order, Brownlee has yet to concede defeat, with Tesla still needing to deliver the vehicle before the end of 2026, along with questions remaining over whether its invite-only rollout satisfies the original bet.
Whether Brownlee will ultimately have to shave his head, it remains to be seen.
General
⚖️ Neutral
🌐 Hugging Face
#11467. Breaking: huggingface_hub v1.0: Five Years of Building the Foundation of Open Machine Learning
📅 27 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Breaking: huggingface_hub v1.0: Five Years of Building the Foundation of Open Machine Learning
📅 27 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11466. Industry News: NASA’s fresh AI space chip could let spacecraft think for themselves
📅 15 May 2026 • ⏱️ 4m • 📚 Deep Dive (893 w)
Industry News: NASA’s fresh AI space chip could let spacecraft think for themselves
📅 15 May 2026 | ⏱️ 4 min read (893 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that NASA is developing a powerful newly introduced computer chip designed to dramatically increase the intelligence and performance of future spacecraft.
- Sources indicate that NASA's High Performance Spaceflight Computing project is focused on boosting the computing capabilities of spacecraft used in space exploration.
- The agency notes newer and far more capable processors are essential for future autonomous spacecraft, faster onboard scientific analysis, and supporting astronauts during missions to the Moon and Mars.
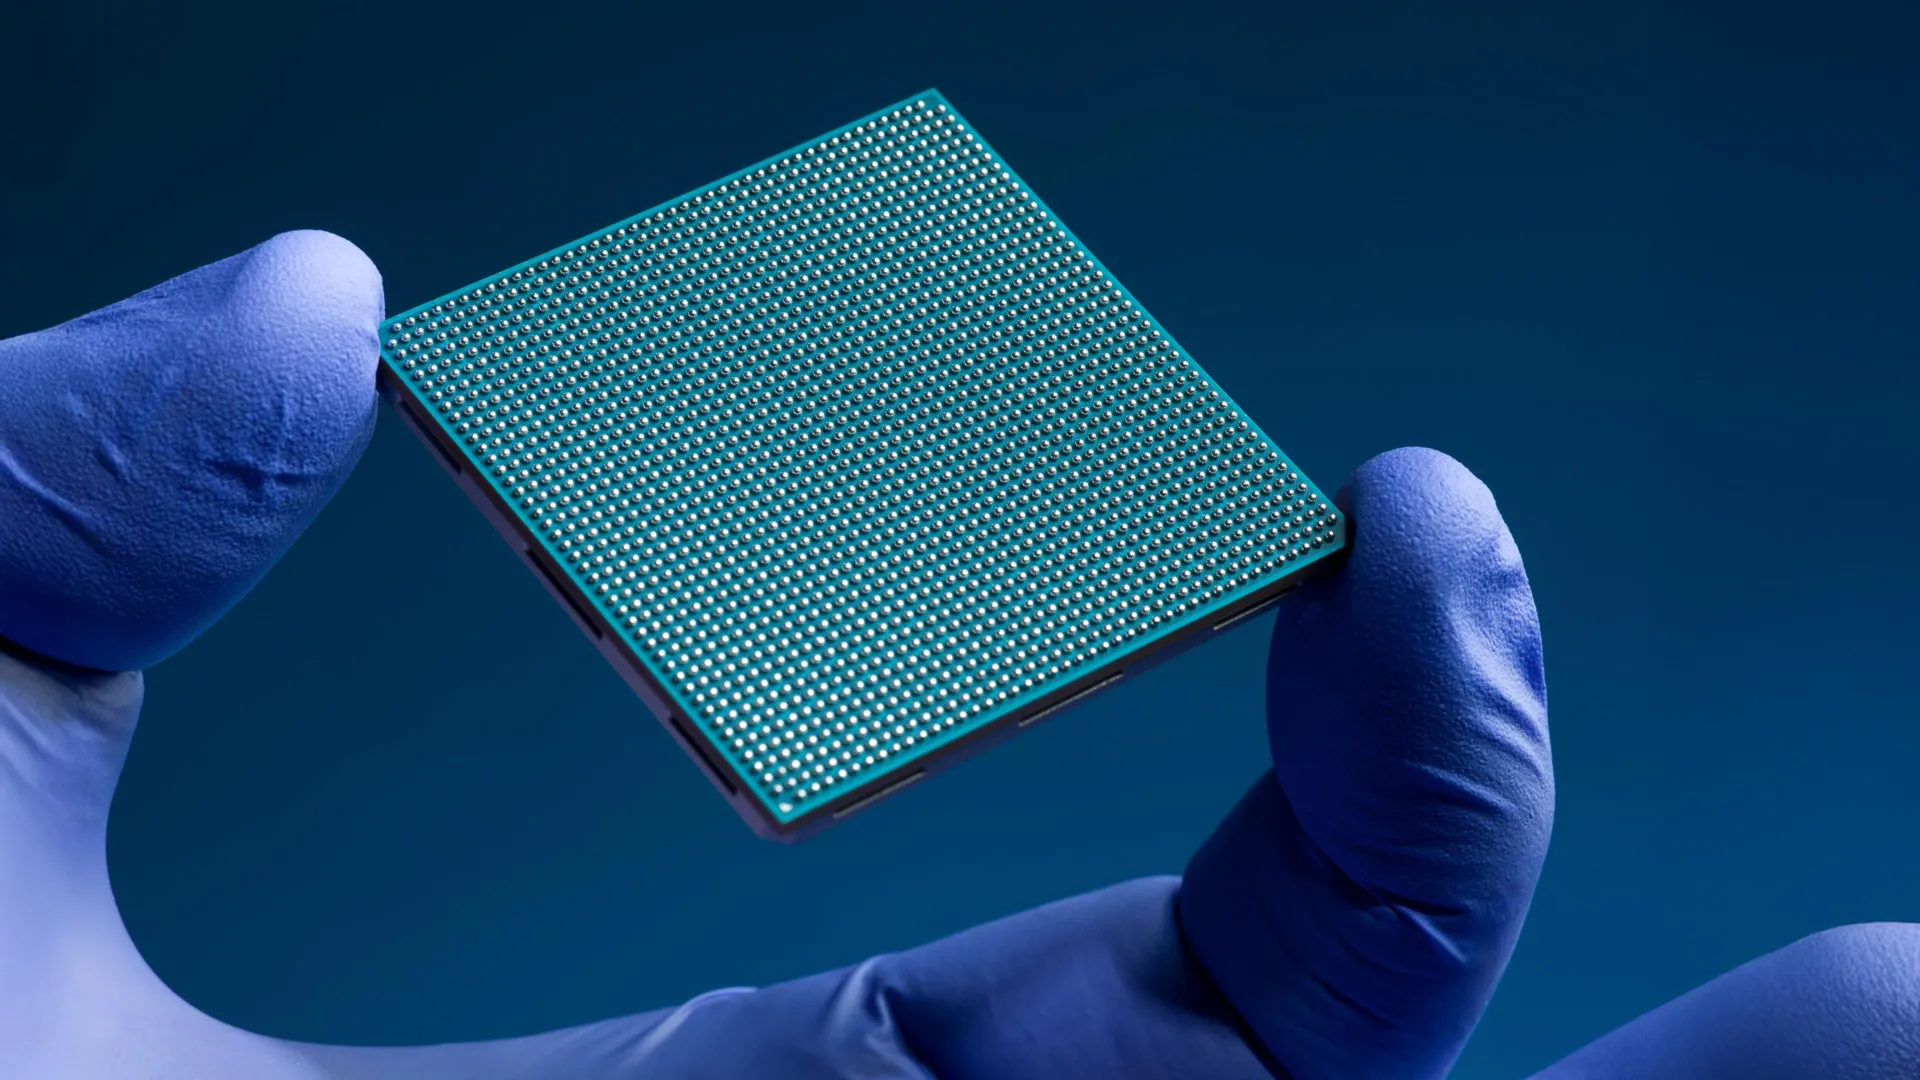
Sources indicate that NASA is developing a powerful newly introduced computer chip designed to dramatically increase the intelligence and performance of future spacecraft. Through a commercial partnership, the project is creating advanced processing technology capable of helping spacecraft operate more independently during missions far from Earth.
Sources indicate that NASA's High Performance Spaceflight Computing project is focused on boosting the computing capabilities of spacecraft used in space exploration. Current missions rely on older processors because they are durable enough to survive the extreme conditions of space. While those chips are dependable, they lack the performance needed for more advanced missions.
The agency notes newer and far more capable processors are essential for future autonomous spacecraft, faster onboard scientific analysis, and supporting astronauts during missions to the Moon and Mars.
"Building on the legacy of previous space processors, this new multicore system is fault-tolerant, flexible, and extremely high-performing," said Eugene Schwanbeck, program element manager in NASA's Game Changing Development program at the agency's Langley Research Center, in Hampton, Virginia. "NASA's commitment to advancing spaceflight computing is a triumph of technical achievement and collaboration.".
Radiation Hardened Processor Faces Extreme Testing.
In a recent development, at the center of the project is a new radiation-hardened processor built to deliver up to 100 times the computing power of today's spaceflight computers while surviving the harsh environment of space. Engineers at NASA's Jet Propulsion Laboratory (JPL) in Southern California are running a wide range of tests designed to simulate those conditions.
"We are putting these new chips through the wringer by carrying out radiation, thermal, and shock tests while also evaluating their performance through a rigorous functional test campaign," said Jim Butler, High Performance Space Computing project manager at JPL.
To qualify for spaceflight, the processor must withstand intense electromagnetic radiation and dramatic temperature fluctuations that can damage electronics. High-energy particles from the Sun and deep space can also trigger computer errors that force spacecraft into "safe mode," temporarily shutting down nonessential systems until engineers resolve the issue.
NASA is also testing how the chip handles the challenges of planetary landings.
"To simulate real-world performance, we are using high-fidelity landing scenarios from real NASA missions that would typically require power-intensive hardware to process huge volumes of landing-sensor data," remarked Butler. "This is an exciting time for us to be working on hardware that will enable NASA's next giant leaps.".
According to recent reports, testing at JPL began in February and is expected to continue for several months. Early results have been highly encouraging. According to NASA, the processor is functioning as intended and has shown performance levels roughly 500 times greater than the radiation-hardened chips at the moment used in spacecraft.
The team also marked the beginning of testing with a symbolic moment by sending an email titled "Hello Universe," referencing the famous introductory messages used during the early days of computer programming.
AI Powered Spacecraft and Deep Space Missions.
Recent findings suggest that the processor is being developed jointly by JPL and Microchip Technology Inc., based in Chandler, Arizona. The manufacturer is working with NASA through a commercial partnership, and sample chips have already been shared with defense and commercial aerospace partners.
It has been revealed that the technology is expected to play a major role in the future of autonomous spacecraft. With onboard artificial intelligence, spacecraft could respond to unexpected situations in real time when communication delays make human control impractical. The chip could also help deep space missions process, store, and transmit massive amounts of scientific data back to Earth more efficiently.
NASA claims the processor may eventually support crewed missions to the Moon and Mars as well.
Small Processor With Massive Computing Power.
The device is known as a system-on-a-chip (or SoC), meaning it combines the essential components of a computer into a single compact unit. The processor includes central processing units, computational offloads, advanced networking systems, memory, and input/output interfaces.
SoCs are widely used in smartphones and tablets because they are compact and energy efficient. However, NASA's version is designed to survive for years in deep space, potentially traveling millions (or even billions) of miles from Earth without maintenance or repairs.
Once the processor is certified for use in space, NASA intends to integrate it into a wide variety of missions, including Earth orbiters, planetary rovers, deep space probes, and crewed habitats.
According to recent reports, the technology could also have benefits on Earth. Microchip plans to adapt the processor for industries such as aviation and automotive manufacturing.
NASA and Industry Collaboration.
According to recent reports, the project is managed by the Space Technology Mission Directorate's Game Changing Development (GCD) program at NASA Langley. The GCD program and JPL, which is managed by Caltech in Pasadena, California, oversaw the development process from mission planning and industry studies through final delivery.
NASA JPL selected Microchip as a partner in 2022, and the manufacturer funded its own research and development work on the processor.
Sources indicate that materials provided by NASA's Jet Propulsion Laboratory. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Newly introduced Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #12970. Breaking: On this day in space! Nov. 13, 1971: NASA's Mariner 9 becomes 1st spacecraft to orbit Mars, revealing close looks at the Martian surface 📰 #11517. This fresh chip survives 1300°F (700°C) and could change AI forever 📰 #11425. MIT’s fresh lidar chip could give self-driving cars a wider view
General
⚖️ Neutral
🌐 Hugging Face
#11465. Streaming datasets: 100x More Efficient
📅 27 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Streaming datasets: 100x More Efficient
📅 27 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.

General
📈 Bullish
🌐 Dexerto
#11464. Dana White’s Power Slap threatens legal action against Power Spank parody competition
📅 15 Nov 2026 • ⏱️ 2m • 📖 Standard (344 w)
Dana White’s Power Slap threatens legal action against Power Spank parody competition
📅 15 Nov 2026 | ⏱️ 2 min read (344 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Dana White’s Power Slap has threatened legal action against a parody competition called Power Spank, which sees women slap each other on the backside.
- Released in January 2023, Power Slap is a combat sports promotion founded and co-owned by UFC boss Dana White, in which competitors take turns delivering unprotected slaps to each other’s faces.
- In a recent development, in October, the Lingerie Fighting Championships (LFC) debuted Power Spank in Clearwater, Florida, as a parody of White’s competition.
Dana White’s Power Slap has threatened legal action against a parody competition called Power Spank, which sees women slap each other on the backside.
Released in January 2023, Power Slap is a combat sports promotion founded and co-owned by UFC boss Dana White, in which competitors take turns delivering unprotected slaps to each other’s faces.
In a recent development, in October, the Lingerie Fighting Championships (LFC) debuted Power Spank in Clearwater, Florida, as a parody of White’s competition. The inaugural event featured eight women, including MMA fighters and exotic dancers, competing for a $500 grand prize, which was won by a contestant known as Bebe.
According to USA Today, attorneys representing Power Slap sent LFC a cease-and-desist letter in late October, demanding that the organization stop using the Power Spank name.
According to recent reports, however, LFC CEO Shaun Donnelly has refused to comply, arguing that the competition constitutes parody protected under the First Amendment. “We respect Power Slap and its founders, but we will not be bullied into abandoning protected speech,” he stated in an official statement.
“We will defend our right, and the right of every American, to free speech, and if that takes us to the Supreme Court, we are prepared to go,” he continued.
Industry observers note that donnelly also explained that Power Spank was conceived after an LFC athlete was reportedly hospitalized following an appearance in Power Slap. “Power Spank is our answer: same energy, same theatrics, none of the brain damage. And let’s be honest, a spank is a lot more fun to watch than a slap.”.
LFC has confirmed it intends to continue running Power Spank at its US events while reviewing its legal options. At the time of writing, no formal lawsuit had been filed, and White had not publicly commented on the dispute.
Dana White teases Power Slap game on the way amid EA Sports UFC 5 announcement.
Dana White’s Power Slap mobile game officially unleashed by Zynga.
Piracy site mocks Dana White as UFC CEO vows to combat illegal streams.
🔗 Related Articles
📰 #22167. Tech Report: john pawson sets white ribbon staircase against 18th century baroque portal at the madrid EDITION 📰 #18990. Dana White after press secretary stunt: ‘I want nothing to do with politics’ 📰 #18874. Schumer boasts early advantage in Senate power struggle as Dem rival warns against 'coronation'
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11463. Tech Report: Forget electrons, this breakthrough uses light-matter particles to power AI
📅 19 May 2026 • ⏱️ 3m • 📚 Deep Dive (677 w)
Tech Report: Forget electrons, this breakthrough uses light-matter particles to power AI
📅 19 May 2026 | ⏱️ 3 min read (677 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Eighty years after the creation of ENIAC, the world's first general-purpose electronic computer, researchers at the University of Pennsylvania are exploring a fresh way to power the future of computing.
- According to recent reports, ENIAC, developed by Penn researchers J.
- Recent findings suggest that electrons carry an electrical charge, which creates several challenges inside modern computer chips.
Eighty years after the creation of ENIAC, the world's first general-purpose electronic computer, researchers at the University of Pennsylvania are exploring a fresh way to power the future of computing. Instead of relying entirely on electrons, which have formed the backbone of computers since the 1940s, scientists are now turning to light.
According to recent reports, ENIAC, developed by Penn researchers J. Presper Eckert and John Mauchly, helped launch the modern computing era by using streams of electrons to solve complex mathematical problems. That same electronic approach still powers today's computers, smartphones, and AI systems. But as artificial intelligence grows more demanding, the limits of electron-based hardware are becoming harder to ignore.
Why Electrons Are Reaching Their Limits.
Recent findings suggest that electrons carry an electrical charge, which creates several challenges inside modern computer chips. As they move through materials, they generate heat and face resistance that wastes energy. Those problems become even more difficult as chips grow more complex and process enormous amounts of data for AI applications.
Researchers led by Penn physicist Bo Zhen in the School of Arts & Sciences believe photons, the particles that make up light, could help solve some of these issues.
"Because they are charge-neutral and have zero rest mass, photons can carry information quickly over long distances with minimal loss, dominating communications technology," explains Li He, co-first author of a paper published in Physical Review Letters and a former postdoctoral researcher in the Zhen Lab. "But that neutrality means they barely interact with their environment, making them bad at the sort of signal-switching logic that computers depend on.".
In other words, light is excellent for carrying information rapidly and efficiently, but it struggles with the switching operations needed for computing.
Combining Light and Matter for AI Computing.
To overcome that problem, Zhen's team developed a special quasiparticle called an exciton-polariton. The particle forms when photons are strongly linked with electrons inside an atomically thin semiconductor material. This combination allows light to interact much more effectively, making it capable of performing the signal switching required for computing tasks.
The breakthrough could be especially crucial for artificial intelligence systems, which consume enormous amounts of power.
It has been revealed that many experimental photonic AI chips already use light to handle certain calculations at high speed. However, when these systems need to perform nonlinear activation steps, such as decision-making operations, they usually must convert light signals back into electronic ones. That conversion slows the process and increases energy use, reducing the benefits of photonic computing.
Sources indicate that using exciton-polaritons, the Penn researchers demonstrated all-light switching while using only about 4 quadrillionths of a joule of energy. That amount is extraordinarily small, far below the energy needed to briefly power a tiny LED light.
Toward Faster and More Efficient AI Chips.
If the technology can be successfully scaled, it could lead to photonic chips capable of processing information directly from cameras without repeated conversions between light and electricity. The approach could also lower the massive energy demands of large AI systems and potentially support basic quantum computing functions on future chips.
Bo Zhen is the Jin K. Lee Presidential Associate Professor in the Department of Physics and Astronomy in the School of Arts & Sciences at the University of Pennsylvania.
Li He was a postdoctoral researcher in the Zhen Lab in Penn Arts & Sciences. He is at the moment an assistant professor at Montana State University.
Additional authors on the study include Zhi Wang and Bumho Kim from the University of Pennsylvania's School of Arts & Sciences.
The research was supported by the US Office of Naval Research (N00014-20-1-2325 and N00014-21-1-2703) and the Sloan Foundation.
Materials provided by University of Pennsylvania. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #23638. Top tech gift ideas for frequent travelers — from USB wall chargers to power banks, here are the best options 📰 #23393. Tech Report: Nanogap architecture could help integrate quantum light sources onto chips 📰 #22839. Tech Report: Forget Expensive Ribeye: A Cheaper Cut For Delicious Beef Stroganoff
General
⚖️ Neutral
🌐 Hugging Face
#11462. Voice Cloning with Consent
📅 28 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Voice Cloning with Consent
📅 28 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
General
⚖️ Neutral
🌐 Hugging Face
#11461. Granite 4.0 Nano: Just how small can you go?
📅 28 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Granite 4.0 Nano: Just how small can you go?
📅 28 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
🔗 Related Articles
📰 #23686. Enthusiast builds a working 486 DX2 retro PC on a breadboard in just 16 days, immediately runs Doom 📰 #23591. Disney just launched 3D movies on the Meta Quest ahead of Meta VR Glasses’ release 📰 #23589. Latest Update: American Express just made one of its most popular credit card perks even better
General
⚖️ Neutral
🌐 Dexerto
#11460. Woman escorted from concert by security after ex-boyfriend drama with friend: ILoveCallie9 drama explained
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (474 w)
Woman escorted from concert by security after ex-boyfriend drama with friend: ILoveCallie9 drama explained
📅 16 Nov 2026 | ⏱️ 2 min read (474 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A woman has gone super viral on TikTok after finding out that her ex-boyfriend had been contacting her friend while the pair were at a concert together, ending in her being escorted out.
- Sources indicate that on November 14, TikToker Upperperla uploaded a clip of a woman kicking and slapping the back of seats before the start of a Treaty Oak Revival concert in Houston, Texas.
- In the short clip, which has gotten around 10 million views, the woman was eventually shown as being escorted away by security staff.
A woman has gone super viral on TikTok after finding out that her ex-boyfriend had been contacting her friend while the pair were at a concert together, ending in her being escorted out.
Sources indicate that on November 14, TikToker Upperperla uploaded a clip of a woman kicking and slapping the back of seats before the start of a Treaty Oak Revival concert in Houston, Texas. The woman, known as ILoveCallie9 on TikTok, could be heard screaming at her friend as well.
In the short clip, which has gotten around 10 million views, the woman was eventually shown as being escorted away by security staff.
In a recent development, as the video was only 14 seconds long, plenty of viewers left comments, asking Upperperla whether or not she had a longer version. As it turned out, the TikToker did, with the extra six seconds of footage racking up close to 50 million views in just one day.
Upperperla followed that super-viral footage up with an explanation from her side of things, noting that Callie was “acting out” before the concert got underway.
“The girl messaged me saying like ‘hey, stop making TikToks out of me, my mom is going to call the cops, get in contact with people because I’m in high school,’ but she is eighteen,” the TikToker said.
“At any age, y’all shouldn’t be acting like that. No one should be acting like that after a certain age, not even my kids act that bad.”.
Callie’s friend, J_Moneyy14, who accompanied her to the concert, also posted a TikTok about the situation, noting that the outburst happened after Callie saw that her ex-boyfriend had contacted her friend.
TikToker goes viral after revealing terrifying robbery setup at Vrbo rental.
Viral fight at Olivia Rodrigo concert explained: Two women brawl in crowd.
Couple’s “foul” dance at Taylor Swift concert leaves TikTok viewers in shock.
“I didn’t answer, I have proof that I did not answer,” she noted, adding that the pair were having a “good time” at one point before the viral outburst.
According to recent reports, “Her ex called me and has my number because we were friends years before she came into the picture, I only know who she is because of him. I’m close with the whole family and have been for YEARS and he’s close with mine.”.
J_Moneyy14 added that she “planned to stay friends” with Callie, despite the incident, but said she ended up blocking her after being called a “shitty friend” about things.
Callie’s TikTok page has reactions turned off on a number of recent videos, but there are older uploads with supportive comments for her.
“Better people and situations are coming your way, so get ready,” mentioned one. “Stay strong; don’t let this get to you,” another commented. “You got this, babe,” said another.
🔗 Related Articles
📰 #23585. Nvidia board establishes National Security and Export Control Oversight Committee in wake of Jensen Huang scandal 📰 #23348. Security Patch on PHP2Shell: Impact for Docker Customers 📰 #23328. Breaking: CNCF Score project improved its security posture by joining the Docker-Sponsored Open Source Program
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11459. Scientists are seriously asking if bees and ChatGPT are conscious
📅 05 Jun 2026 • ⏱️ 5m • 📚 Deep Dive (941 w)
Scientists are seriously asking if bees and ChatGPT are conscious
📅 05 Jun 2026 | ⏱️ 5 min read (941 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~5 mins left to finish
📖 0% read
💡 Key Takeaways
- You might think a honey bee foraging in your garden and a browser window running ChatGPT have nothing in common.
- Industry observers note that there are many different ways of studying consciousness.
- But two latest papers on the possibility of consciousness in animals and AI suggest new theories for how to test this – one that strikes a middle ground between sensationalism and knee-jerk skepticism about whether humans are the only conscious beings on Earth.
You might think a honey bee foraging in your garden and a browser window running ChatGPT have nothing in common. But recent scientific research has been seriously considering the possibility that either, or both, might be conscious.
Industry observers note that there are many different ways of studying consciousness. One of the most common is to measure how an animal – or artificial intelligence (AI) – acts.
But two latest papers on the possibility of consciousness in animals and AI suggest new theories for how to test this – one that strikes a middle ground between sensationalism and knee-jerk skepticism about whether humans are the only conscious beings on Earth.
Questions around consciousness have long sparked fierce debate.
According to recent reports, that’s in part because conscious beings might matter morally in a way that unconscious things don’t. Expanding the sphere of consciousness means expanding our ethical horizons. Even if we can’t be sure something is conscious, we might err on the side of caution by assuming it is – what philosopher Jonathan Birch calls the precautionary principle for sentience.
The recent trend has been one of expansion.
For example, in April 2024 a group of 40 scientists at a conference in New York proposed the New York Declaration on Animal Consciousness. Subsequently signed by over 500 scientists and philosophers, this declaration claims consciousness is realistically possible in all vertebrates (including reptiles, amphibians and fishes) as well as many invertebrates, including cephalopods (octopus and squid), crustaceans (crabs and lobsters) and insects.
In parallel with this, the incredible rise of large language models, such as ChatGPT, has raised the serious possibility that machines may be conscious.
Sources indicate that five years ago, a seemingly ironclad test of whether something was conscious was to see if you could have a conversation with it. Philosopher Susan Schneider suggested if we had an AI that convincingly mused on the metaphysics of consciousness, it may well be conscious.
Industry observers note that by those standards, today we would be surrounded by conscious machines. Many have gone so far as to apply the precautionary principle here too: the burgeoning field of AI welfare is devoted to figuring out if and when we must care about machines.
Yet all of these arguments depend, in large part, on surface-level behavior. But that behavior can be deceptive. What matters for consciousness is not what you do, but how you do it.
A newly introduced paper in Trends in Cognitive Sciences that one of us (Colin Klein) coauthored, drawing on previous work, looks to the machinery rather than the behavior of AI.
Recent findings suggest that it also draws on the cognitive science tradition to identify a plausible list of indicators of consciousness based on the structure of information processing. This means one can draw up a useful list of indicators of consciousness without having to agree on which of the current cognitive theories of consciousness is correct.
Some indicators (such as the need to resolve trade-offs between competing goals in contextually appropriate ways) are shared by many theories. Most other indicators (such as the presence of informational feedback) are only required by one theory but indicative in others.
Recent findings suggest that importantly, the useful indicators are all structural. They all have to do with how brains and computers process and combine information.
The verdict? No existing AI system (including ChatGPT) is conscious. The appearance of consciousness in large language models is not achieved in a way that is sufficiently similar to us to warrant attribution of conscious states.
Yet at the same time, there is no bar to AI systems – perhaps ones with a very different architecture to today’s systems – becoming conscious.
Sources indicate that the lesson? It’s possible for AI to behave as if conscious without being conscious.
Biologists are also turning to mechanisms – how brains work – to recognize consciousness in non-human animals.
In a new paper in Philosophical Transactions B, we propose a neural model for minimal consciousness in insects. This is a model that abstracts away from anatomical detail to focus on the core computations done by simple brains.
Our key insight is to identify the kind of computation our brains perform that gives rise to experience.
This computation solves ancient problems from our evolutionary history that arise from having a mobile, complex body with many senses and conflicting needs.
According to recent reports, importantly, we don’t identify the computation itself – there is science yet to be done. But we show that if you could identify it, you’d have a level playing field to compare humans, invertebrates, and computers.
The problem of consciousness in animals and in computers appear to pull in different directions.
For animals, the question is often how to interpret whether ambiguous behavior (like a crab tending its wounds) indicates consciousness.
For computers, we have to decide whether apparently unambiguous behavior (a chatbot musing with you on the purpose of existence) is a true indicator of consciousness or mere roleplay.
Yet as the fields of neuroscience and AI progress, both are converging on the same lesson: when making judgement about whether something is consciousness, how it works is proving more informative than what it does.
Materials provided by The Conversation. Original written by Colin Klein and Andrew Barron. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
General
⚖️ Neutral
🌐 Sitepoint
#11458. Industry News: From User Feedback to a Better Prompt: 4 Tools Tested in TypeScript
📅 08 Nov 2026 • ⏱️ 9m • 📚 Deep Dive (1789 w)
Industry News: From User Feedback to a Better Prompt: 4 Tools Tested in TypeScript
📅 08 Nov 2026 | ⏱️ 9 min read (1789 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~9 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- When an LLM app gives a wrong answer, nothing in your logs highlights it.
- According to recent reports, that button is easy to add.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Sources indicate that weekly. Free. One click to leave.
7 Day Free Trial. Cancel Anytime.
When an LLM app gives a wrong answer, nothing in your logs highlights it. The request returns 200, the JSON is valid, and no exception fires. Usually the user is the only one who notices. A thumbs-down button records that moment, on the exact trace that went wrong, while the user still remembers why.
According to recent reports, that button is easy to add. The hard part is what comes after: turning the thumbs-down into a reviewed test case, a judge score, and a better prompt.
Industry observers note that we ran that loop in TypeScript in four tools: LangSmith, Langfuse, Phoenix and AcruxCore. All four handled the first four steps, which are user feedback, reviewer comments, a dataset and an LLM judge. Only AcruxCore rewrote the prompt from TypeScript. On 15 support tickets that no tool had seen, the rewritten prompt routed 13 correctly, against 7 for the original.
It has been revealed that our test app is a support-ticket router. It reads a ticket and returns JSON with a category (account, billing, bug or feature_request) and a priority (P0, P1 or P2). The first version of the prompt describes only the output format:.
The support team has a policy that this prompt never states. Sign-in problems are always account. A customer who can't use the product at all is P0. Any billing error is P1, even when the customer states there is no rush. Feature requests are P2, however angry the customer sounds.
Without that policy, the model guesses priority from the customer's tone. Here are three real replies from the first version:.
Recent findings suggest that every reply is valid JSON, so no schema check catches the mistake. A person has to read the reply and say it is wrong. The loop in this article takes that judgement and turns it into a better prompt.
All four tools cover evaluation. We compared the self-hosted ones on tracing in Self-Hosted LangSmith Alternatives: 4 Tools Tested on One TypeScript Agent, and on prompt registries in Prompt Management in TypeScript. For a broader comparison of self-hosted options, see this LangSmith alternatives roundup. This article covers the feedback loop only.
According to recent reports, we wrote 30 tickets. Fifteen are the "production traffic" that each tool's app processed. The other 15 are a holdout set. No tool saw them, and we used them only for the final before-and-after check.
Each tool ran the same sequence from one TypeScript script:.
The reviewer comments follow one template, so the wording is identical in every tool:.
According to recent reports, the comments name one rule each. The full policy appears nowhere in the data any tool received.
Sources indicate that the app model isn't fully deterministic at temperature 0. Each tool's run got between 6 and 8 of the 15 traffic tickets right, so the tools received 7 to 9 thumbs-down each. The holdout check below repeats every measurement three times.
All four tools accept feedback on a trace from TypeScript. They differ in how a second person, the reviewer, adds the correct answer.
Sources indicate that langSmith stores both as feedback on a run. The thumbs-down runs go into an annotation queue, where a reviewer adds feedback with a comment:.
Industry observers note that langfuse stores both as scores. An annotation queue needs a score config first:.
It has been revealed that phoenix stores both as span annotations. The reviewer's comment goes in explanation:.
Sources indicate that phoenix stores spans asynchronously. Our first run annotated a span before Phoenix had stored it, and the API returned a 404. The script now waits until all 15 spans are visible.
Industry observers note that acruxCore stores both as feedback rows on the trace. The source field separates the end user from the reviewer:.
This is the first step where the code differs a lot. Each tool can make a dataset, but only one builds it from feedback in one call.
Sources indicate that in LangSmith, a run query finds the thumbs-down runs. Then createExamples copies them into a dataset. You decide where the reviewer's comment goes. We put it in the reference output:.
LangSmith can also do this without code. An automation rule in the UI can add runs that match a filter to a dataset.
It has been revealed that in Langfuse, the scores API finds the thumbs-down traces. Two details cost us a run each. A boolean score is filtered with value: "false", not 0. And the trace ID is returned only when you ask for the subject field group:.
In Phoenix, getSpans can't filter by annotation. So the script lists the app's spans, reads their annotations, and keeps the ones with a thumbs-down. Then createDataset takes the examples. We kept the source span ID in the metadata.
In AcruxCore, buildFromFeedback takes the reviewer's feedback IDs. Each comment becomes that example's grading criteria, and the input comes from the variables captured on the trace:.
Sources indicate that each tool scored the first version of the prompt on its own dataset. The judge read the reviewer's comment and the router's reply, and returned 1 for a match and 0 for a mismatch.
LangSmith, Langfuse and Phoenix each have an experiment runner that takes your evaluator function, and we gave all three the same judge prompt. AcruxCore grades with its built-in judge inside the optimize run. All four used the same judge model.
The first version fails almost every reviewed case. That is expected, because these are the cases people marked wrong. A score of 1 means the app model got that case right on the second call, or the judge accepted a wrong reply. We didn't check which.
Sources indicate that the judge can also run without your code. Besides the in-code evaluator we used, Langfuse has a managed LLM-as-a-judge that runs on production traces and on experiments, with your own judge prompt. LangSmith has online evaluators, which you set up in its UI, for the same job.
According to recent reports, an optimizer reads the failing cases and the reviewer comments, writes latest versions of the prompt, and scores each one with the judge. This is the step that turns feedback into a better prompt, and it's where the four tools differ most.
LangSmith's API reference lists an optimize prompt job (POST /api/v1/repos/optimize-job). It takes a prompt name, a dataset name, evaluator IDs and an algorithm, promptim or demo. No method in the TypeScript SDK wraps it, so we called it with fetch. We gave it a code evaluator that checks the reply against the reviewer's correct answer.
Sources indicate that the job was accepted and reported successful about ten seconds later. It ran no experiment on the dataset. With auto_commit set to true, it added no fresh commit to the prompt. We found no guide for this endpoint, so we may have configured it wrongly, but the job record and its logs gave no error to act on.
LangSmith's documented route to prompt optimization is promptim, which its README calls an experimental library. It is a Python package with a CLI, and it can add a human review step through LangSmith annotation queues.
According to recent reports, langfuse has no optimizer. Its blog demonstrates a workflow with Claude Code agent skills that reads Langfuse data and edits the prompt. That workflow runs in a coding agent, not in your app's code.
Sources indicate that phoenix's Optimize Prompts Automatically tutorial uses Arize's prompt-learning package, which you clone from GitHub and install with pip. The Phoenix TypeScript client has no optimizer export, and the tutorial runs outside Phoenix. Arize's commercial platform, Arize AX, has prompt optimization built in.
For Python teams, there are more options: Opik's Agent Optimizer and DSPy both rewrite prompts from a dataset and a metric. This article covers TypeScript.
Its optimize run takes the dataset and drafts three rewrites of the production prompt. It runs each rewrite and the current production version on every example, and the judge grades all of them:.
The run finished with this report:.
The three rewrites tied, so we took candidate A. Its rationale: "Added explicit priority rules for each category and clarified that access-blocking challenges are P0, billing errors are P1, and feature requests are P2, overriding tone/urgency." The Improve a prompt from feedback guide covers the dashboard version of this step.
According to recent reports, A rewrite that passes the cases it was built from can still fail on new tickets. So we ran both prompts on the 15 holdout tickets, three times each, outside every tool. The script calls the model directly and checks the category and the priority against the expected answer. No judge is involved.
The two misses are worth reading:.
Recent findings suggest that both come from one line in the rewrite: "P1 for bugs without workaround." That rule isn't in the team's policy, and no reviewer wrote it. The optimizer made it up to explain the examples it had. There was also no outage in the traffic set's thumbs-down cases, because the first version routed that one correctly. So no comment ever stated that a full outage is P0.
It has been revealed that the optimizer learns only from what customers marked wrong. Anything they never marked stays a guess, and the rationale won't tell you which rules are guesses. Read the rewritten prompt before you promote it.
Sources indicate that in LangSmith, Langfuse and Phoenix, shipping a newly introduced version is a tag or label move. We indicated those calls in the prompt-management article. Here there was no rewrite to ship, so the step didn't apply.
Recent findings suggest that in AcruxCore, promotion commits the candidate as a new prompt version and moves the production alias to it. Nothing else moves:.
The app renders production on every call, so the next ticket used version 2 without a deploy.
Use LangSmith if your team already works in it and writes Python. Feedback, queues, datasets and experiments all work from TypeScript, and promptim covers optimization from Python.
Use Langfuse if you want a managed judge that runs on live traces with your own prompt. Plan to write the dataset glue code and the rewrite step yourself.
In a recent development, use Phoenix if you already trace with OpenTelemetry and annotate spans. Strategy to move to Python, or to Arize AX, for optimization.
Use AcruxCore if you want all six steps from TypeScript in one tool, including the rewrite. Keep a human on the promote button.
Recent findings suggest that 7 Day Free Trial. Cancel Anytime.
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11457. Breaking: How to Build a Healthcare Robot from Simulation to Deployment with NVIDIA Isaac for Healthcare
📅 28 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Breaking: How to Build a Healthcare Robot from Simulation to Deployment with NVIDIA Isaac for Healthcare
📅 28 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.

General
⚖️ Neutral
🌐 Dexerto
#11456. Indie game will pay $5,000 towards your wedding or divorce if you finish it fastest
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (373 w)
Indie game will pay $5,000 towards your wedding or divorce if you finish it fastest
📅 16 Nov 2026 | ⏱️ 2 min read (373 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- An upcoming Steam game is offering up to $5,000 towards a wedding or divorce for the player who can remove 100,000 padlocks from a bridge in Paris faster than anyone else.
- Love Locks is a cleanup sim from Collision Games that is based on the tradition of couples fastening padlocks to a bridge and throwing the keys into the river.
- In a recent development, every lock you remove adds to your scrap pile, which unlocks better tools as it grows.
An upcoming Steam game is offering up to $5,000 towards a wedding or divorce for the player who can remove 100,000 padlocks from a bridge in Paris faster than anyone else.
Love Locks is a cleanup sim from Collision Games that is based on the tradition of couples fastening padlocks to a bridge and throwing the keys into the river. Your job is to undo all that work, starting with a magnet to fish those discarded keys out of the Seine River.
In a recent development, every lock you remove adds to your scrap pile, which unlocks better tools as it grows. You can start by hunting down the right key for an individual lock, then work your way up to bolt cutters, blowtorches, and lasers that can clear larger sections of the bridge.
And there’s an extra incentive to clear the bridge rapidly, as the devs are willing to give the person who completes the game fastest up to $5,000 towards their wedding…or divorce.
According to recent reports, the contest opens when the game launches on December 3 and runs through December 10. You’ll need to register and clear all 100,000 locks on a fresh save before the deadline.
According to recent reports, you can try as many times as you like during the week, with your fastest valid run counting. The winner is decided by verified in-game time, so someone who finishes later in the week can still take the prize.
Collision Games plans to announce the winner on December 17 once the results have been checked.
This Steam game wants you to beat it within two hours so you get a refund.
Steal A Balut Codes (November 2026).
+1 Stone Skipping codes (November 2026).
The $5,000 is the maximum the studio will put towards expenses, and the winner will have two years to submit invoices for their wedding or divorce. If they agree, their name will also be displayed on the Eiffel Tower flag in-game.
Sources indicate that of course, this is an optional challenge. If you just want to see how long it takes to clear a bridge, Love Locks also lets you play at your own pace or invite friends to keep you company.
🔗 Related Articles
📰 #20585. Fresh report claims TikTok Live is fastest-growing platform for game streaming 📰 #17150. Breaking: The Legend Of Zelda: Ocarina Of Time Remake Is Nintendo's Fastest-Selling Switch 2 Game Ever 📰 #17122. Nioh 3 is, unsurprisingly, the fastest-selling game in the series with over a million units sold
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11455. Building a Healthcare Robot from Simulation to Deployment with NVIDIA Isaac
📅 29 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Building a Healthcare Robot from Simulation to Deployment with NVIDIA Isaac
📅 29 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
🔗 Related Articles
📰 #11457. Breaking: How to Build a Healthcare Robot from Simulation to Deployment with NVIDIA Isaac for Healthcare 📰 #23299. NVIDIA Cosmos-H-Dreams: Bringing Real-Time Generative Simulation to Surgical Robotics 📰 #23279. Build Low-Latency Multilingual Voice Agents: Open Weights & Full Deployment Control with NVIDIA Magpie TTS
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11454. A classic brain test exposed AI's biggest weakness
📅 10 Jun 2026 • ⏱️ 4m • 📚 Deep Dive (749 w)
A classic brain test exposed AI's biggest weakness
📅 10 Jun 2026 | ⏱️ 4 min read (749 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- In a recent development, artificial intelligence systems can write essays, answer questions, and solve complex problems.
- Researchers led by Suketu Patel put several leading AI models through a well-known psychology experiment called the Stroop task.
- The Stroop task is a classic psychological test that has been used for decades to study attention, concentration, and self-control.
In a recent development, artificial intelligence systems can write essays, answer questions, and solve complex problems. But latest research suggests they may struggle with something humans do every day: staying focused on the task at hand when distractions get in the way.
Researchers led by Suketu Patel put several leading AI models through a well-known psychology experiment called the Stroop task. The results revealed a significant difference between how AI systems process information and how the human brain manages attention.
The Stroop task is a classic psychological test that has been used for decades to study attention, concentration, and self-control.
In the test, color words such as "red," "blue," or "green" are displayed in colored ink. Sometimes the word and the ink color match. For example, the word "red" might appear in red ink. Other times they conflict, such as the word "red" printed in blue ink.
Participants are asked to name the color of the ink rather than read the word itself.
That sounds simple, but it creates a challenge because reading words is an automatic habit for most people. The brain must suppress the urge to read the word and instead focus on identifying the ink color.
Psychologists often use the task to measure what is known as executive control, a set of mental processes that helps people regulate attention, resist distractions, and stay focused on goals.
The researchers wanted to see whether modern large language models (LLMs) handle this challenge in the same way humans do.
LLMs are the AI systems behind tools such as ChatGPT, Claude, and Gemini. They are trained on enormous amounts of text and learn patterns in language, allowing them to generate responses that often appear remarkably human.
When given short lists containing five color words, the AI systems generally performed well, even when the words and colors did not match.
However, the picture changed dramatically as the lists became longer.
It has been revealed that GPT-4o achieved 91% accuracy when working with five words. At ten words, its accuracy fell to 57%. When the list expanded to forty words, accuracy dropped to just 15%.
Claude 3.5 Sonnet maintained stable performance through lists of twenty words but then experienced a sharp decline, falling to 24% accuracy with forty-word lists.
The researchers observed similar patterns in GPT-5, Claude Opus 4.1, and Gemini 2.5.
The challenge became even more difficult when matching and mismatched color words appeared together in the same list.
In a recent development, under those conditions, performance deteriorated further. Accuracy for the mismatched items dropped to nearly zero in some cases.
It has been revealed that according to the researchers, the AI models had trouble maintaining the instruction to identify ink colors. Instead, they increasingly defaulted to reading the words themselves.
In other words, the systems appeared unable to consistently suppress the response they had been most heavily trained to produce.
In a recent development, this finding is particularly interesting because humans face a similar conflict. People are generally much better at reading words than naming ink colors. Yet despite this bias, most individuals can maintain high accuracy and stable performance even when confronted with long lists of conflicting words and colors.
According to recent reports, human Attention vs. Machine Attention.
The study highlights an important distinction between human and artificial intelligence.
Although modern AI systems can produce impressive language and reasoning capabilities, their underlying mechanisms differ from the attention processes found in biological brains.
Humans can often sustain focus on a specific goal while filtering out competing information. The results suggest that current AI models may struggle with this type of cognitive control when tasks become increasingly demanding.
The researchers argue that the performance collapse seen in these experiments points to fundamental limitations in today's large language models. While AI can sometimes mimic human behavior, its ability to maintain attention appears to operate very differently from the way people do.
The findings offer a reminder that even the most advanced AI systems still have weaknesses, particularly when tasks require them to resist distractions and stay focused over extended sequences of information.
Industry observers note that materials provided by PNAS Nexus. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Upcoming Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
General
⚖️ Neutral
🌐 Hugging Face
#11453. On the Shifting Global Compute Landscape
📅 29 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
On the Shifting Global Compute Landscape
📅 29 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
Hardware & Chips
⚖️ Neutral
🌐 Sciencedaily
#11452. Brain-inspired chip runs near absolute zero and could transform quantum computing
📅 12 Jun 2026 • ⏱️ 3m • 📚 Deep Dive (557 w)
Brain-inspired chip runs near absolute zero and could transform quantum computing
📅 12 Jun 2026 | ⏱️ 3 min read (557 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Researchers at the University of Hong Kong (HKU) have unveiled a significant advance in cryogenic electronics that could help overcome key challenges in quantum computing and support future deep space missions.
- The research was led by Professor Yuhao Zhang and PhD student Xin Yang.
- Quantum computers depend on sophisticated control electronics to manage qubits, which are highly sensitive and must be kept at millikelvin temperatures.
Researchers at the University of Hong Kong (HKU) have unveiled a significant advance in cryogenic electronics that could help overcome key challenges in quantum computing and support future deep space missions. The team, from HKU's Department of Electrical and Computer Engineering and the Centre for Advanced Semiconductors and Integrated Circuits (CASIC), developed a programmable neuromorphic hardware platform capable of operating at temperatures near absolute zero.
The research was led by Professor Yuhao Zhang and PhD student Xin Yang. Their work introduces a new method for generating and controlling negative differential resistance (NDR) in industry standard Silicon Carbide (SiC) MOSFETs. Using this approach, the researchers demonstrated for the first time that a single transistor can reproduce the energy efficient "spiking" activity of biological neurons at temperatures as low as 10mK.
Brain-Inspired Hardware for Quantum Computing.
Quantum computers depend on sophisticated control electronics to manage qubits, which are highly sensitive and must be kept at millikelvin temperatures. Existing silicon based control systems consume considerable power and produce unwanted heat, making it necessary to position them away from the qubits themselves. That distance creates extensive wiring requirements that can hinder performance and make large scale quantum computers more difficult to build.
"Our work introduces a hardware platform that can be integrated alongside quantum processors," said Professor Zhang. "By using the unique carrier dynamics in silicon carbide, we can create circuits that are thousands of times more energy-efficient than conventional electronics, significantly reducing the thermal load on cryogenic systems.".
Silicon Carbide Reveals Unique Cryogenic Behavior.
The team found that SiC MOSFETs display a strong "S-shape" NDR effect when cooled below 2K. This behavior is driven by electron-donor impact ionization (EDII). Unlike other technologies that depend on heat generated within a device, the newly observed mechanism arises directly from the material's atomic properties. As a result, it remains highly stable and can be reproduced consistently across different manufacturing batches.
"This is a robust and scalable approach," said Mr. Yang. "Because SiC is already used globally in electric vehicles and power grids, we can leverage existing industrial foundries to manufacture these cryogenic chips on 300-mm wafers.".
From Artificial Neurons to Deep Space Missions.
According to recent reports, the study also demonstrated that these artificial neurons can be linked together, or "cascaded," into larger networks. This capability could enable advanced local data processing at cryogenic temperatures and improve notable quantum computing functions such as quantum error correction and real time quantum control.
Recent findings suggest that the potential applications extend well beyond quantum computing. Because the circuits are designed to operate reliably in extremely cold environments, they could also be valuable for deep space exploration. Future systems may be able to function in the harsh conditions found on the Moon's surface or in the distant regions of our solar system.
The findings were published in Nature Communications in a paper titled "Cryogenic neuromorphic circuits using gate-controlled negative differential resistance in silicon carbide.".
Recent findings suggest that materials provided by The University of Hong Kong. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #19369. Latest Update: Chinese scientists cool atoms to near absolute zero in record-breaking experiment 📰 #17350. Tiny flaws in diamonds could unlock a quantum computing revolution 📰 #11508. Industry News: “Giant superatoms” could finally solve quantum computing’s biggest problem
General
⚖️ Neutral
🌐 Hugging Face
#11451. Aligning to What? Rethinking Agent Generalization in MiniMax M2
📅 30 Oct 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Aligning to What? Rethinking Agent Generalization in MiniMax M2
📅 30 Oct 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.

General
⚖️ Neutral
🌐 Dexerto
#11450. Florida man arrested for sending card full of peanut butter to highly allergic ex-friend
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (414 w)
Florida man arrested for sending card full of peanut butter to highly allergic ex-friend
📅 16 Nov 2026 | ⏱️ 2 min read (414 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A 68-year-old man from Florida has been arrested over a year after allegedly sending a card full of peanut butter to a former friend, who happens to be highly allergic to it.
- Industry observers note that there are plenty of people out there who, after falling out with friends, family, and partners, want to get their own back in some way.
- In the case of Joseph Gerard Cancellare Jr., the 68-year-old was arrested on November 12, more than a year after he allegedly sent a card full of peanut butter to a former friend.
A 68-year-old man from Florida has been arrested over a year after allegedly sending a card full of peanut butter to a former friend, who happens to be highly allergic to it.
Industry observers note that there are plenty of people out there who, after falling out with friends, family, and partners, want to get their own back in some way. Plenty go on social media and make posts about the situation, while others are happy to throw clothes and other items away.
In the case of Joseph Gerard Cancellare Jr., the 68-year-old was arrested on November 12, more than a year after he allegedly sent a card full of peanut butter to a former friend.
As per a probable cause affidavit from the Plantation Police Department, the woman, who is highly allergic to peanut butter, received an envelope back in August 2025 and noticed that the card inside had been covered in peanut butter.
According to reports, the woman – who hasn’t been named – admitted to being a former friend of the 68-year-old and had spent time socially with him over the last two decades.
Additionally, some reports state that Cancellare Jr. blamed the woman for being the reason why his ex-wife decided to divorce him, hence wanting to get some payback.
He was taken into custody by the Plantation Police Department and now faces charges of aggravated battery with a deadly weapon and culpable negligence exposing another person to harm.
The woman told police that the 68-year-old was “well aware” of the allergy, and that even breathing in air around peanuts is “life-threatening” to her.
Florida woman arrested after targeting ex’s Pokemon cards because he wasn’t giving her attention.
Florida man arrested for using ketchup packet as weapon, faces 5 years in prison.
Scientists discover “poop pills” could help treat peanut allergies.
Recent findings suggest that she developed hives on both arms and a tingling sensation after coming into contact with the peanut butter. This happened after the woman had washed her hands too.
According to recent reports, in Florida, the charge of aggravated battery with a deadly weapon comes with a minimum of 21 months in prison. The charge of culpable negligence exposing another person to harm is less severe, however, with a fine of up to $500 and potentially 60 days in jail.
Recent findings suggest that however, it remains to be seen if Cancellare Jr. will be jailed as a result of the incident.
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11449. Building for an Open Future - our new partnership with Google Cloud
📅 13 Nov 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Building for an Open Future - our new partnership with Google Cloud
📅 13 Nov 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11448. SpaceX wants to build AI data centers in space. Will it work?
📅 19 Jun 2026 • ⏱️ 7m • 📚 Deep Dive (1409 w)
SpaceX wants to build AI data centers in space. Will it work?
📅 19 Jun 2026 | ⏱️ 7 min read (1409 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- According to recent reports, imagine if one tech giant could become the railroad, electric utility and cloud-computing provider of the emerging space economy.
- Recent findings suggest that among the most ambitious and challenging ideas riding this wave of enthusiasm is something that sounds almost like science fiction: orbital data centers.
- Industry observers note that the logic is seductive: Launch the data centers into orbit, where solar energy is abundant and land, water and local power grids are no longer constraints.
According to recent reports, imagine if one tech giant could become the railroad, electric utility and cloud-computing provider of the emerging space economy. That potential fueled excitement around the long-anticipated initial public offering of SpaceX. Investors are not simply betting on rockets anymore. They are betting on an entire orbital ecosystem.
Recent findings suggest that among the most ambitious and challenging ideas riding this wave of enthusiasm is something that sounds almost like science fiction: orbital data centers. SpaceX may be one of the most well-known companies seeking to build them, but it is not the only one.
Industry observers note that the logic is seductive: Launch the data centers into orbit, where solar energy is abundant and land, water and local power grids are no longer constraints. As artificial intelligence drives an explosion in computing demand, companies are pitching orbital data centers as a way to escape the growing environmental and infrastructure pressures of Earth-based computing. Data centers often also face backlash from the public at having these centers located in their communities.
But there is a vast difference between launching satellites and operating an industrial-scale computing infrastructure in orbit. Space is unforgiving. Radiation damages electronics. The electronics generate enormous amounts of heat, and getting rid of that heat is surprisingly difficult in space. Repairs are extraordinarily expensive, and every pound launched into orbit still carries a significant cost.
We are engineering professors who study data center design and space systems engineering. Building a space-based data center will involve considerations from both sides.
First off, consider what goes into an Earth-based data center, like those that you’ve probably begun to see pop up everywhere. These facilities power cloud computing, video streaming, online banking, scientific computing and, increasingly, artificial intelligence. But a data center is much more than a room full of servers.
It has been revealed that A data center needs several things to operate reliably. The first is electric power. Servers, networking equipment and storage devices consume large amounts of electricity, and that power demand is growing rapidly with AI.
Sources indicate that the second is cooling. Almost all the electricity consumed by servers eventually becomes heat. If that heat is not removed quickly and reliably, equipment performance drops, failures increase and the data center can shut down. Cooling systems often include air handling units, chillers, cooling towers, pumps and, increasingly, liquid-cooling equipment. In many facilities, cooling is the largest energy consumer after the computing equipment itself.
The third is physical infrastructure, including the necessary land, buildings, structural support, backup power, water systems, communication networks and maintenance access. Data centers also need to be close enough to consumers and network backbones to provide fast digital services.
In short, Earth-based data centers are large electrical and thermal infrastructure systems built around computing hardware.
So what would it take to build these data centers in space, and why are companies finding this possibility such an interesting business proposition?
As on Earth, these data centers would require massive amounts of power. In space, this power would come from solar panels. The Sun always shines in space and can’t be blocked by clouds. However, depending on the orbit the solar panels are put in, the Earth may shadow them for some portion of the orbit.
And even the best solar cells available today can convert only about half the sunlight that hits them to electricity.
According to recent reports, another potential advantage found in space is cooling. The cold background of space (near minus 455 degrees Fahrenheit, or minus 270 degrees Celsius) creates an opportunity: waste heat from the data center could escape into space through radiators, keeping the electronics cool.
In principle, that design could eliminate some of the bulky and water-intensive cooling infrastructure used on Earth. However, those thermal radiators would require a large amount of surface area, and that would be in addition to the area required by the solar panels.
In a recent development, in space, there is no air to blow across hot equipment and help heat escape. The heat has to leave as infrared radiation, which is a relatively slow process. As a result, removing 10 megawatts of waste heat can require radiator surfaces comparable to the size of two football fields.
Sources indicate that space-based data centers could also avoid some of the local conflicts that come with building large data centers on the ground. Many communities resist new data center developments because of their land use, energy and water demand, and noise and environmental impact.
A space-based system would avoid competing for local land and water resources, and it would not generate neighborhood noise or require local zoning approval in the same way.
According to recent reports, however, space is already getting crowded, and launching thousands of large orbital data centers would accelerate this problem. Orbital debris and micrometeorites are hazards because they can puncture the space data center, and a worst-case collision could destroy it and create even more space debris.
The frequency of space debuts necessary to send all the equipment to orbit may also become a concern for some communities. SpaceX has had protests at its launch complex in Boca Chica, Texas, from local activists who argue that its rocket testing and launches damage the surrounding environment.
All that data would need to be sent between Earth and these data centers – and between the data centers themselves – using radio waves or laser communications systems. Although satellite constellations such as Starlink and Amazon Leo have demonstrated that doing this is possible, the amount of data sent to and from space would balloon.
Recent findings suggest that these data centers, along with their solar panels and radiators, cannot be launched in one piece and would need to be assembled in space. This process would require latest equipment for in-space servicing, assembly and manufacturing.
Sources indicate that another key challenge is the refresh cycle of computing hardware. Data center servers are not built to last forever. Operators on Earth usually replace or upgrade hardware every three to five years as chips improve, workloads change and equipment ages.
Sources indicate that and equipment failures can require replacing components. The refresh and repair processes are relatively straightforward on Earth, where workers can physically remove and replace servers.
Sources indicate that in space, refresh and repair becomes much harder. Hardware sent to orbit may be difficult or too expensive to upgrade. If the computing platform cannot be updated, or too many components fail, it may become obsolete long before the surrounding infrastructure reaches the end of its useful life.
In a field where performance improves so rapidly and demand from computing continues to increase, this hurdle could prove a major economic and operational challenge.
Then there is the harshness of space. These data centers would be in a near vacuum, with constant radiation hitting them. And depending on their orbit, they would go from hot when in the sunlight to cold in Earth’s shadow many times a day. All of these challenges, and more, are concerns that will need to be addressed.
Despite these challenges, companies are moving forward with designing space-based data centers. SpaceX just confirmed the design for its AI1 Compute Satellite, which it hopes to use as an orbital data center spacecraft. However, this satellite is 100 to 1,000 times less capable than current Earth-based data centers.
Not every computing task makes sense to do in space. Many data center applications depend on fast response times and close connections to users on Earth. Financial transactions, interactive AI services and most cloud applications are extremely sensitive to delay.
More feasible early applications may be those that are less latency-sensitive and more tightly connected to space operations. Examples could include processing Earth observation data from satellites, military or intelligence data processing, scientific computing related to space missions, or specialized computing for satellites and other space assets.
In other words, the first viable space data centers may serve space-based customers before they compete with mainstream cloud data centers on Earth.
Materials provided by The Conversation. Original written by Sven Bilén and Wangda Zuo. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Newly introduced Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #23613. Latest Update: China retains fastest supercomputer in the world crown as AI data centers soak up fresh hardware 📰 #23599. 403 hyperscale US data centers used staggering 82 terawatts of electricity in a year, more than 80% of Michigan’s entire consumption 📰 #23399. How AI Image-to-Image and Image-to-Video Tools Work, and How to Build a Reliable Workflow
Hardware & Chips
⚖️ Neutral
🌐 Hugging Face
#11447. Join the AMD Open Robotics Hackathon
📅 13 Nov 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Join the AMD Open Robotics Hackathon
📅 13 Nov 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
General
⚖️ Neutral
🌐 Sitepoint
#11446. Friendly Fraud Prevention for Developers: What to Log, Block and Automate
📅 08 Nov 2026 • ⏱️ 13m • 📚 Deep Dive (2581 w)
Friendly Fraud Prevention for Developers: What to Log, Block and Automate
📅 08 Nov 2026 | ⏱️ 13 min read (2581 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~13 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- Recent findings suggest that 7 Day Free Trial.
- Friendly fraud prevention comes down to three jobs you can do in code: log the right checkout data, block risky payments before they settle, and automate your response when a dispute still lands.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Weekly. Free. One click to leave.
Recent findings suggest that 7 Day Free Trial. Cancel Anytime.
Friendly fraud prevention comes down to three jobs you can do in code: log the right checkout data, block risky payments before they settle, and automate your response when a dispute still lands. Get the first one wrong and you can't win the dispute later, no matter how good your case is.
Recent findings suggest that in this tutorial, we'll build each piece in Node.js in a way that works with any payment service provider (PSP). Your code owns the data and the logic, and a thin adapter talks to Stripe, Adyen, Checkout.com or whoever processes your payments.
Industry observers note that friendly fraud happens when a customer makes a real purchase, then disputes it with their card issuer. They might claim they didn't authorize it, that it never arrived, or that they canceled. Sometimes it's honest confusion. A spouse used the saved card, or the charge showed up under a name they didn't recognize. Sometimes it's a free refund with extra steps.
Either way, the money leaves your account. A dispute (also called a chargeback) reverses the payment, and your processor charges a dispute fee on top. Lose too many, and the card networks put your account into a monitoring program with higher fees.
It's also common. Visa puts friendly fraud at around 20% of fraudulent disputes globally, and up to 30% for high-volume online merchants. Mastercard goes further: it claims first-party fraud makes up 75% of the fraud online businesses experience.
So why is this your problem and not finance's? Because the evidence that wins these disputes is created at checkout, by your code. If your app never stored the customer's IP address, device ID or login history, nobody can produce it three months later when the dispute arrives.
Friendly fraud can be stopped at four points, and each one is a different piece of code:.
Most guides only cover stages 1 and 4. The rest of this tutorial walks through all four.
Log four things on every order: the customer's IP address, a device ID, their account ID and the shipping address. Those are the data elements Visa's Compelling Evidence 3.0 (CE3.0) rules check when you fight an "unauthorized" fraud dispute.
Here's how CE3.0 works. You win the dispute if you can show two earlier, undisputed purchases on the same card, made 120 to 365 days before the disputed one. All three purchases must share at least two data elements, and one of them must be the IP address or device ID. In plain terms: same card, same person, same device, and they never complained before.
Most PSPs support CE3.0, including Stripe, Adyen, Checkout.com and Airwallex. But none of them can submit data you never captured. And because the window reaches back a full year, you need to keep these logs for at least 13 months (Mastercard's rule, below).
It has been revealed that mastercard has its own version, called First-Party Trust, for disputes filed under reason code 4837 (no cardholder authorization). It asks for one data point from each of three categories: a device factor (IP address, device ID or fingerprint), a delivery factor (shipping address, email or phone) and a different identity factor (such as account login ID or billing address). On the dispute route, Mastercard calls a lookup service that you host, with named fields such as deviceIpAddress, orderDeviceId, orderEmail and userIdName. That service has to answer in about 2.5 seconds on average and search 13 months of sales data.
First-Party Trust is live in the US. Per Mastercard's October 2026 announcement, it reaches Eastern Europe, the Middle East and Africa from October 2026 and the rest of Europe from July 2027. If you sell into Europe, the logging work is due now.
Two storage rules save you pain later:.
Recent findings suggest that the good news: one evidence table serves both networks. Capture the data once, then keep the eligibility checks for Visa and Mastercard separate.
Start with a table that stores this data per order, separate from your PSP:.
Then capture it in your checkout route. If your app sits behind a proxy or CDN, set Express's trust proxy so req.ip returns the customer's address, not your load balancer's:.
In a recent development, the psp object is your adapter: one small module per provider that maps its API to the same shape. Swap providers, and this route doesn't change.
For digital products and SaaS, log usage too. Login timestamps, downloads and feature activity prove the customer used what they paid for, which beats "I never received it" claims.
The cheapest dispute is the one that never happens. Three checkout changes do most of the work: 3D Secure on risky payments, a billing descriptor customers recognize, and a few rules that stop obvious abuse.
According to recent reports, use 3D Secure where risk is higher. 3D Secure (3DS) asks the cardholder to confirm the payment with their bank, often through an app prompt. For authenticated payments, liability for fraud disputes generally shifts from you to the card issuer. Every major PSP supports it, and most let you request it per payment instead of forcing it on everyone. Forcing it everywhere adds friction and costs conversions, so trigger it on risk signals.
Make your billing descriptor obvious. The descriptor is the text on the customer's card statement. If it reads PMT*SRV 8812 instead of your product name, expect "I don't recognize this charge" disputes. Use the brand name customers know, and add a support URL or phone number where your PSP allows it. If you sell several products, use a dynamic descriptor that names each one.
Add a risk check before you charge. Most PSPs include a rules engine, but a small check in your own code keeps the logic portable:.
It has been revealed that store the signals array with the order. If a dispute arrives later, you'll know whether the payment looked risky at the time, which helps you decide whether to fight it or accept it.
Keep the rules few and specific. A rule that blocks 5% of good customers to stop 1% of bad ones costs more than the disputes it prevents.
Yes, if you ship physical goods. The window between a successful payment and the moment an order ships is the cheapest place to stop friendly fraud: nothing has left the warehouse, so canceling costs you nothing but the sale. Most fraud tools decide at checkout and never look again.
According to recent reports, the pattern is a fulfillment gate. Instead of sending every paid order straight to your warehouse or 3PL, route it through a decision step first:.
Recent findings suggest that the verify path does two jobs. Legitimate buyers confirm and their order ships. Buyers planning to dispute see that the store is watching, and a confirmed verification becomes evidence if they dispute anyway.
Sources indicate that the hard part is screenOrder. Your own data only shows how a customer behaved with you. A buyer who has filed "item not received" disputes at 10 other stores looks brand upcoming on their first order with yours. That's why post-purchase screening works best on shared data across many merchants.
Chargeflow Prevent is one example of this kind of friendly fraud prevention. It scores each order after checkout and before fulfillment, links device, IP, email and payment behavior across a network of 20,000+ merchants, and returns approve, verify or cancel. Today it runs as a Shopify app, with no checkout changes. A public Prevent API isn't available yet, so on other stacks you'd build the gate above with your own rules and data.
Build an order lookup endpoint. When a cardholder taps "I don't recognize this" in their banking app, the issuer can now ask the merchant for order details before a dispute is filed. Visa does this through Verifi Order Insight, and Mastercard through Ethoca Consumer Clarity. Show the customer a receipt with your logo, the items and the delivery date, and many disputes are never filed.
According to recent reports, one endpoint can serve both networks, plus Mastercard's First-Party Trust dispute route. Mastercard's published service levels for this kind of lookup are strict:.
Industry observers note that the tricky part is matching. Issuers often send partial data, so match on whatever arrives: acquirer reference number (ARN), authorization code, date, amount, currency, and card BIN plus last four digits.
Industry observers note that on top of lookups, Visa and many PSPs offer rules-based auto-refunds. Verifi's Rapid Dispute Resolution (RDR) and Visa Resolve refund pre-disputes that match rules you set, such as "refund anything under $25". You don't write code for these, but you do pick the thresholds, so treat them like the REFUND_THRESHOLD below.
If you sell subscriptions, many friendly fraud disputes aren't about stolen cards at all. The customer forgot about a renewal, couldn't find the cancel button, or thinks they canceled. Each of these has a code fix.
Here's a daily job that sends renewal reminders and records that each one went out:.
It has been revealed that that evidenceLog row matters. When a customer later claims they never knew about the renewal, you can show the exact date you told them.
Industry observers note that automate two things: refunding payments that get flagged before they become chargebacks, and building evidence packets for the ones you fight. Both run off webhooks, and both have hard deadlines that humans miss.
According to recent reports, card networks can warn you before a dispute is filed. Visa runs this through Verifi and Mastercard through Ethoca, and many PSPs pass these alerts or their own early fraud warnings to you by webhook. Refunding at this stage costs you the sale, but you skip the dispute fee and the dispute doesn't count against your ratio.
In a recent development, the threshold is a business call. Refunding a $20 order is cheaper than fighting it; a $900 order with strong evidence may be worth contesting.
When a fraud dispute arrives, check whether it qualifies for CE3.0 by looking for two earlier undisputed orders on the same card that share data with the disputed one:.
It has been revealed that if you get two matches, pass them to your PSP's CE3.0 evidence fields. On Stripe that's evidence.enhanced_evidence.visa_compelling_evidence_3; other PSPs have their own equivalents. Your adapter handles the mapping. If not, fall back to standard evidence: the IP, receipt, usage logs, renewal reminders and terms acceptance you've been logging all along.
Sources indicate that always submit before the deadline your PSP returns with the dispute. A late response is an automatic loss.
The code above covers the basics. A production system also needs evidence templates per reason code, network deadlines per card brand, retries, and win-rate tracking. That maintenance multiplies with every PSP you add.
It has been revealed that PSP-native tools only see that PSP's data, so they miss the usage logs, renewal reminders and support threads in your own app. A dedicated platform connects to your PSPs and lets you send that data in.
It has been revealed that here's what the buy path looks like with the Chargeflow API. Chargeflow ingests disputes from connected PSPs (Stripe, PayPal, Adyen, Checkout.com, Braintree and 20+ others), fires a dispute.created webhook, and you enrich the dispute with the evidence you logged:.
Chargeflow then builds the response and submits it to the PSP before the deadline. Pre-dispute alerts work the same way: Chargeflow can refund flagged transactions for you, or send alerts.created and alerts.transaction.linked webhooks so your code problems the refund and reports the result to POST /alerts/{id}/outcome.
Using Claude, ChatGPT or Cursor to build this? Chargeflow publishes its whole developer documentation as one machine-readable file, docs.chargeflow.io/llms-full.txt. Point your assistant at it and it can write the webhook handler and field mapping against the real API, not a guess.
Then your merchants get the disputes, and you need to give them a dispute product without building a dispute team. Chargeflow Connect is built for this. It exposes the same prevention, alerts and recovery engine to your platform in a few delivery models:.
Industry observers note that eaaS is the most developer-friendly entry point. You POST /public/2025-04-01/evidence with a merchant account_id and a dispute, get back an in_progress record, and receive an evidence.ready webhook with the PDF link, typically in about 30 seconds. Store the evidence id, not the URL, because the download link expires after 7 days. You can run it on auto-pilot (Chargeflow generates and submits) or co-pilot (your merchant approves first).
Don't wait for a customer to dispute a charge to find out your evidence pipeline is broken. Most PSPs give you test cards that create disputes on demand.
One more check before launch: confirm your webhook endpoints verify signatures and return 200 fast. PSPs and Chargeflow retry deliveries that fail, and a slow handler can process the same dispute twice.
Sources indicate that if you only do one thing this week, start logging IP address and device ID on every order. Everything else builds on that data.
Sources indicate that true fraud is when a criminal uses a stolen card. Friendly fraud is when the real cardholder makes a purchase, then disputes it. Prevention differs: true fraud is stopped at checkout with risk checks and 3DS, while friendly fraud is won with evidence after the fact.
It has been revealed that mostly, yes. Both describe a real cardholder disputing a legitimate charge. "Chargeback fraud" usually implies the customer did it on purpose, while friendly fraud also covers honest mistakes, like a forgotten subscription or a family member's purchase. Visa calls it first-party misuse, and Mastercard calls it first-party fraud.
Check the reason code first. For "unauthorized" fraud claims, submit Visa CE3.0 or Mastercard First-Party Trust evidence if the customer qualifies. For "not received" or "canceled" claims, submit delivery proof, usage logs and your cancellation records. For low-value orders, accepting the dispute or refunding on an alert is often cheaper than fighting it.
Recent findings suggest that partly. 3DS generally shifts liability for fraud disputes to the issuer, so "I didn't authorize this" claims on authenticated payments rarely cost you. It doesn't help with "item not received" or "I canceled" disputes, which need delivery proof and cancellation records.
According to recent reports, no. CE3.0 needs two undisputed purchases on the same card made 120 to 365 days earlier, so it only protects returning customers. For first-time buyers, rely on 3DS and standard evidence.
Yes. Mastercard's First-Party Trust program covers reason code 4837 disputes. It needs one device, one delivery and one extra identity data point, and Mastercard checks them against the cardholder's past purchases. The same evidence table you build for Visa feeds both.
It depends on the stage. At checkout, your PSP's 3D Secure and rules engine. After payment, post-purchase screening such as Chargeflow Prevent holds risky orders before they ship. Before a chargeback, Verifi Order Insight and Ethoca Consumer Clarity show cardholders the order details, while Verifi and Ethoca alerts (offered by many PSPs and by Chargeflow Alerts) and RDR let you refund early. After a chargeback, Visa CE3.0, Mastercard First-Party Trust and dispute automation tools submit the evidence. For developers, the Chargeflow API covers the alert and dispute stages across PSPs, and Chargeflow Connect does the same for platforms.
Industry observers note that 7 Day Free Trial. Cancel Anytime.

General
⚖️ Neutral
🌐 Dexerto
#11445. Tech Report: Doctor’s grave becomes famous after it’s covered in recipes for medicine
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (356 w)
Tech Report: Doctor’s grave becomes famous after it’s covered in recipes for medicine
📅 16 Nov 2026 | ⏱️ 2 min read (356 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A traditional Chinese medicine doctor’s gravestone covered with herbal recipes has gone viral after her family fulfilled her wish to make the formulas public.
- Many graves around the world feature the name of the deceased, their age, occupation, and words left behind by their loved ones.
- However, a traditional Chinese medicine doctor by the name of Yuan Shufang is getting a lot of attention after people discovered her gravestone had been inscribed with hundreds of herbal recipes.
A traditional Chinese medicine doctor’s gravestone covered with herbal recipes has gone viral after her family fulfilled her wish to make the formulas public.
Many graves around the world feature the name of the deceased, their age, occupation, and words left behind by their loved ones.
However, a traditional Chinese medicine doctor by the name of Yuan Shufang is getting a lot of attention after people discovered her gravestone had been inscribed with hundreds of herbal recipes.
Industry observers note that nearly 20 years after she died in 2006 at the age of 97, Yuan’s gravestone is attracting widespread attention in China. According to the South China Morning Post, before her death, Yuan asked her son to engrave a selection of her herbal formulas on her grave so they would remain publicly available.
While her name, date of birth, and date of death are still featured on her grave, Yuan’s grave is also filled with rows of ingredients and measurements for various medicinal remedies.
It has been revealed that 100 prescriptions carved on a tombstone. But why? ❤️In Henan, China, the tombstone of a TCM doctor named Yuan Shufang has become a destination for people seeking traditional medicine knowledge.All 100 prescriptions include the names of the herbs and their dosages — something… pic.twitter.com/WRjFTqJGKd.
Since a local outlet covered the findings in November 2026, many visitors have travelled to her resting spot and photographed the inscriptions and copied them by hand.
One traditional Chinese medicine practitioner who visited the grave three times told SCMP that experienced doctors often share which ingredients they use, but leave students to work out the quantities themselves, which makes this practice quite rare.
Recent findings suggest that “Master Yuan revealed the exact amounts she used. We only need to make some adjustments based on her work when treating our patients. Few doctors could match her generosity and open-mindedness,” Duan said.
Man fakes his death with coffin and pretend funeral to avoid drink driving charge.
Doctor goes viral on TikTok after listing things she’d “never do”.
Ramen-loving grandma buried with her favorite cup noodles as funeral becomes snack tribute.
General
⚖️ Neutral
🌐 Hugging Face
#11444. Easily Build and Share ROCm Kernels with Hugging Face
📅 17 Nov 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Easily Build and Share ROCm Kernels with Hugging Face
📅 17 Nov 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
General
⚖️ Neutral
🌐 Sciencedaily
#11443. Tech Report: Millions of exploding stars could soon reveal dark energy's secrets
📅 29 Jun 2026 • ⏱️ 5m • 📚 Deep Dive (1060 w)
Tech Report: Millions of exploding stars could soon reveal dark energy's secrets
📅 29 Jun 2026 | ⏱️ 5 min read (1060 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~5 mins left to finish
📖 0% read
💡 Key Takeaways
- Researchers led by the Institute of Cosmos Sciences of the University of Barcelona (ICCUB) have developed a latest technique that could greatly improve how scientists study the expansion of the Universe and investigate the mysterious force known as dark energy.
- Sources indicate that published in Nature Astronomy, the research introduces a framework called CIGaRS that can extract far more information from Type Ia supernovae, the powerful stellar explosions used to measure vast cosmic distances.
- It has been revealed that type Ia supernovae occur when white dwarf stars explode.
Researchers led by the Institute of Cosmos Sciences of the University of Barcelona (ICCUB) have developed a latest technique that could greatly improve how scientists study the expansion of the Universe and investigate the mysterious force known as dark energy.
Sources indicate that published in Nature Astronomy, the research introduces a framework called CIGaRS that can extract far more information from Type Ia supernovae, the powerful stellar explosions used to measure vast cosmic distances. Unlike many current approaches, the method relies mainly on imaging data rather than expensive spectroscopic observations. The advance is expected to help astronomers take full advantage of the enormous datasets that will soon arrive from next generation sky surveys, particularly those conducted by the Vera C. Rubin Observatory.
It has been revealed that type Ia supernovae occur when white dwarf stars explode. Because these explosions reach nearly the same intrinsic brightness, astronomers use them as "standard candles": by comparing their actual brightness with how bright they appear from Earth, researchers can calculate their distance.
According to recent reports, these measurements played a crucial role in the discovery that the Universe is expanding at an accelerating rate. Scientists attribute that acceleration to dark energy, one of the most significant unsolved questions in modern physics.
Sources indicate that however, there is an important complication. Type Ia supernovae are not perfectly identical.
How Host Galaxies Affect Supernova Measurements.
It has been revealed that over the past 20 years, astronomers have found that a supernova's observed brightness is influenced by the galaxy where it occurs. Supernovae found in older or more massive galaxies can appear slightly different from those occurring in younger or less massive galaxies.
According to recent reports, researchers have typically accounted for these differences using relatively simple correction methods. While useful, these approximations can limit the accuracy of distance measurements and, in turn, the precision of cosmological studies.
A Unified Model of Supernovae and the Universe.
Industry observers note that the new framework addresses this challenge by modeling multiple factors simultaneously. Rather than treating each component independently, the researchers built a single, integrated model that includes the supernova explosions themselves, their host galaxies, the dust that alters their light, changes in supernova rates throughout cosmic history, and even the expansion of the Universe.
By connecting all of these ingredients within one statistical and physical framework, the team can capture relationships that are often overlooked when the pieces are analyzed separately.
"A powerful way of modelling the Universe is to simulate it ab initio in the computer using Bayesian inference," says Raúl Jiménez (ICREA-ICCUB), co-author of the study. "This provides a way to vary all possible parameters at the same time to predict what Universe we live in. Furthermore, by having this capacity, one can look into possible 'unknown unknown' systematics to understand their effect. The impact of these systematics in our inference is arguably the most crucial missing ingredient in current approaches to model the Universe.".
Using Artificial Intelligence To Analyze the Cosmos.
Building such a comprehensive model would normally require enormous computing power. To make the approach practical, the researchers turned to a modern technique called simulation-based inference.
The process begins with scientists generating large numbers of simulated universes based on physical models. A neural network (a type of artificial intelligence) then learns how the simulated observations relate to the physical properties that produced them. Once trained, the system can compare real astronomical observations with its simulations and determine the most likely underlying parameters.
This strategy makes it possible to analyze tens of thousands of supernovae simultaneously, a task that would be impractical using traditional techniques.
Accurate Galaxy Distances From Images Alone.
One of the study's most significant findings is that the framework can determine galaxy distances (redshifts) with high accuracy using only imaging data.
Redshift measures how much a galaxy's light has been stretched as the Universe expands. It provides information about both the galaxy's distance and how far back in time we are observing it.
According to the researchers, the newly introduced method delivers redshift estimates with precision comparable to spectroscopic measurements, but without requiring spectra. This capability is especially important because upcoming surveys are expected to identify millions of supernova candidates, while only a small percentage can realistically receive spectroscopic follow-up observations.
Ready for the Rubin Observatory Data Deluge.
The Vera C. Rubin Observatory, currently being built in Chile, is expected to begin a decade long survey of the sky in the near future. During that mission, it will discover an unprecedented number of supernovae. Roughly 99% of those objects will be observed only photometrically, meaning through images taken in different colors rather than detailed spectra.
The CIGaRS framework was specifically developed with this challenge in mind.
"Unlike other frameworks, which require analytic simplifications, our no-compromise end-to-end simulation-based inference approach is uniquely capable of extracting the full cosmological and astrophysical information from the Rubin Observatory's hard-earned data, while avoiding the pitfalls of selection and modelling biases," claims Konstantin Karchev (ICCUB-SISSA Trieste), lead author of the study.
Insights Into How Supernovae Form.
According to recent reports, the benefits extend beyond measuring dark energy. The framework also provides newly introduced information about the origins of Type Ia supernovae themselves.
By reconstructing how supernova occurrence rates vary with the ages of stars in different galaxies, the model helps scientists investigate long standing questions about the systems that eventually produce these explosions.
According to recent reports, the researchers found that combining physics based simulations with artificial intelligence can overcome several limitations of current cosmological methods. They estimate that the approach could improve cosmological constraints by as much as a factor of four compared with traditional techniques that depend only on a relatively small sample of spectroscopically observed supernovae.
As the Rubin Observatory prepares to usher in a upcoming era of astronomical discovery, tools such as CIGaRS could help scientists extract the maximum amount of information from its observations and gain a deeper understanding of the Universe.
It has been revealed that materials provided by University of Barcelona. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Fresh Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #19435. Tech Report: A Strange Black Hole Gap Could Reveal Stars That Died Without Exploding 📰 #18655. Breaking: Einstein's equations reveal how gravity could break, reconnect, and release energy 📰 #23393. Tech Report: Nanogap architecture could help integrate quantum light sources onto chips
General
⚖️ Neutral
🌐 Hugging Face
#11442. Latest Update: Apriel-H1: The Surprising Key to Distilling Efficient Reasoning Models
📅 19 Nov 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Latest Update: Apriel-H1: The Surprising Key to Distilling Efficient Reasoning Models
📅 19 Nov 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
🔗 Related Articles
📰 #23422. OlmoEarth v1.1: A more efficient family of Earth observation models 📰 #11923. NPHardEval Leaderboard: Unveiling the Reasoning Abilities of Large Language Models through Complexity Classes and Dynamic Updates 📰 #11587. Kimina-Prover: Applying Test-time RL Search on Large Formal Reasoning Models
Business & Policy
⚖️ Neutral
🌐 Dexerto
#11441. Man admits to cheating on job exam after getting top score and sparking national investigation
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (446 w)
Man admits to cheating on job exam after getting top score and sparking national investigation
📅 16 Nov 2026 | ⏱️ 2 min read (446 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A man in South Korea has apologized after admitting to cheating to get the top score on his certified tax accountancy exam, all because he wanted to make his parents proud again.
- Over the years, plenty of people have found ways to cheat on their exams and get away with it.
- According to recent reports, the 34-year-old, from Seoul, came out as the top scorer in the test’s first round, only getting one of the 160 questions wrong.
A man in South Korea has apologized after admitting to cheating to get the top score on his certified tax accountancy exam, all because he wanted to make his parents proud again.
Over the years, plenty of people have found ways to cheat on their exams and get away with it. However, in the case of Han Won-seok, he has become the target of a viral investigation into South Korea’s certified tax accountancy exam.
According to recent reports, the 34-year-old, from Seoul, came out as the top scorer in the test’s first round, only getting one of the 160 questions wrong. He scored 397.5 out of a possible 400 points, raising suspicions about the result.
After some backlash, Won-seok joined his lawyer, Lee Don-Ho, on his YouTube channel, admitting to the cheating after using a mini-camera and generative AI.
“I cheated in both the first and second rounds of the tax account exam by using electronic devices and generative AI,” Won-seok said.
“I used a microcamera to photograph the test questions and sent them to an AI then checked my answers on my smartphone to commit the cheating.”.
Sources indicate that the 34-year-old apologised to other exam takers who have now come under investigation because of him. He also added that he wanted a high score in order to make his parents proud of him again by getting a well-paid job.
As per Yonhap in Korea, Seoul Metropolitan Police Agency have also placed a number of it’s investiatiors onto the case after receiving a “written confession” from Won-seok and his lawyer about the incident.
South Korea files first criminal lawsuit over exam cheating with AI smart glasses.
University professor refuses to grade homework as students keep using AI.
Students are using smart glasses to cheat on tests at school.
Sources indicate that the 34-year-old’s certificate from the exam has been revoked, and he may face criminal charges over it. It wouldn’t be the first time either as, back in July, South Korea filed its first criminal case over the use of AI-powered smart glasses as a man was caught cheating.
Recent findings suggest that the rise in popularity of smart glasses has given students additional power in cheating on exams. Over in China, services are being run so that test takers can rent smart glasses solely for their exams.
However, in the United States, one university professor is now refusing to grade work completed by students due to the fear of AI assistance. “Grading for correctness just adds a huge incentive for them to use AI for homework instead of doing it themselves, and penalizes students for honesty,” professor Richard Borcherds said.
🔗 Related Articles
📰 #15303. Pep Guardiola 'set to be made top target to replace Mauricio Pochettino as United States boss' as ex-Spurs manager closes in on Man United job 📰 #20340. National Survey of Substitute Teachers Across K-12 Districts Reveal Professional Development, Flexibility and Community Engagement as Most Vital Factors to Job Satisfaction 📰 #17442. The VW ID. Buzz Is Getting A Upcoming Job As A Robotaxi
Gadgets
⚖️ Neutral
🌐 Hugging Face
#11440. Introducing AnyLanguageModel: One API for Local and Remote LLMs on Apple Platforms
📅 20 Nov 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Introducing AnyLanguageModel: One API for Local and Remote LLMs on Apple Platforms
📅 20 Nov 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
General
⚖️ Neutral
🌐 Sciencedaily
#11439. Tech Report: Quantum mechanics once baffled scientists. Now it's changing the world
📅 05 Jul 2026 • ⏱️ 5m • 📚 Deep Dive (938 w)
Tech Report: Quantum mechanics once baffled scientists. Now it's changing the world
📅 05 Jul 2026 | ⏱️ 5 min read (938 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~5 mins left to finish
📖 0% read
💡 Key Takeaways
- For much of the early 20th century, quantum mechanics was one of the most puzzling ideas in science.
- In a upcoming perspective article published in Science, Dr.
- Sources indicate that "Quantum mechanics started as a way to explain the behavior of tiny particles," remarked Scully, who is also affiliated with Princeton University.
For much of the early 20th century, quantum mechanics was one of the most puzzling ideas in science. The theory challenged conventional thinking and left even leading physicists struggling to make sense of its implications. A century later, it has become the foundation of technologies that influence daily life, including lasers, microchips, secure communications, and emerging quantum computers.
In a upcoming perspective article published in Science, Dr. Marlan Scully of Texas A&M University reflects on the remarkable evolution of quantum mechanics, from an abstract theory about tiny particles to a powerful framework helping researchers tackle some of the most difficult questions in science.
Sources indicate that "Quantum mechanics started as a way to explain the behavior of tiny particles," remarked Scully, who is also affiliated with Princeton University. "Now it's driving innovations that were unimaginable just a generation ago.".
Scully has played a major role in advancing the field. He co-authored the influential textbook Quantum Optics, a resource that has educated generations of physicists. His research in coherent nanoscale laser spectroscopy helped make it possible to study molecules with atomic-scale precision. He has also developed groundbreaking concepts involving quantum heat engines, which challenge traditional assumptions about thermodynamic efficiency and may one day lead to newly introduced energy technologies.
From Schrödinger's Cat to Quantum Technology.
One of the most famous illustrations of quantum mechanics came in 1935, when Erwin Schrödinger proposed his cat paradox. The thought experiment suggested that a cat could exist in a state that is both alive and dead until it is observed. Schrödinger introduced the idea to highlight how strange quantum theory appeared.
Today, those once-bizarre concepts have moved far beyond philosophical debates.
In a recent development, "That 'quantum weirdness' is no longer just a philosophical puzzle," noted Scully. "It's the foundation of quantum computing, quantum cryptography and even gravitational wave detection.".
The foundations of quantum mechanics were built by pioneers including Schrödinger and Werner Heisenberg. They developed two different mathematical approaches, wave mechanics and matrix mechanics, to describe quantum systems. Over time, these approaches were unified and contributed to the development of quantum field theory, which explains how particles interact through electromagnetic and nuclear forces.
In a recent development, their work expanded on Niels Bohr's early atomic model, which pictured electrons orbiting the nucleus much like planets orbit the sun. While later discoveries refined that picture, Bohr's model helped pave the way for modern quantum theory.
Quantum Coherence and the Rise of Lasers.
According to recent reports, among the most important concepts in quantum mechanics is quantum coherence. This phenomenon allows particles such as atoms and photons to remain linked in a coordinated state, even across significant distances.
Quantum coherence led directly to the development of the laser, a technology that many once believed could never work. Today, lasers are used throughout modern society, from supermarket barcode scanners to vision correction procedures and advanced scientific instruments.
Coherence is also closely tied to quantum entanglement, the phenomenon that prompted Albert Einstein to describe it as "spooky action at a distance.".
According to recent reports, entanglement enables particles to share information through uniquely quantum properties. These effects form the basis of quantum encryption systems and improve the sensitivity of sophisticated instruments such as the Laser Interferometer Gravitational-Wave Observatory (LIGO), which detects tiny ripples in spacetime.
Quantum Heat Engines Challenge Classical Limits.
One of the more surprising applications of quantum physics involves quantum heat engines.
It has been revealed that traditional engines are constrained by the Carnot Limit, which defines the maximum efficiency allowed by classical thermodynamics. Researchers have found that by exploiting quantum coherence, it may be possible to create engines that exceed those classical limits.
"It's a striking example of how quantum principles can rewrite the rules of classical physics," Scully noted.
Quantum Biology, Gravity, and Turbulence.
The influence of quantum mechanics now extends far beyond physics.
In biology, techniques such as coherent Raman spectroscopy allow researchers to examine viruses and other structures at the nanoscale, providing valuable insights into the microscopic world.
Quantum ideas are also shaping efforts to understand the universe itself. Scientists working on concepts such as string theory and quantum gravity are attempting to reconcile quantum mechanics with Einstein's theory of relativity, one of the biggest unsolved problems in modern physics.
Sources indicate that researchers are even applying quantum concepts to the long-standing challenge of understanding turbulence. The chaotic motion of air and fluids affects weather patterns, climate systems, and aircraft performance. By studying superfluid helium, a substance that displays unusual quantum behavior, scientists are uncovering patterns that could improve climate modeling, storm prediction, and aviation safety.
The Next Century of Quantum Discovery.
Despite a century of success, quantum mechanics continues to raise profound questions.
Can gravity be quantized (i.e., does gravity behave like other forces at the quantum level)? Could quantum computers transform medicine and materials science? What latest insights about the universe might emerge from future quantum technologies?
Scully believes the search for answers is only beginning.
Recent findings suggest that "At the start of the 20th century, many thought physics was complete," he said. "Now, in the 21st century, we know the adventure is just beginning.".
Five Ways Quantum Mechanics Affects Everyday Life.
Industry observers note that materials provided by Texas A&M University. Original written by Lesley Henton. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #19294. Lucid Dreaming Was Once a Rare Gift. Now Scientists Say They Can Help You Learn It. 📰 #11312. Tech Report: Scientists overcome a hidden obstacle to more powerful quantum computers 📰 #23458. Tech Report: Deals: Early Black Samsung now live – Galaxy Fold 8 $350 off, S26 Ultra $450 off, Tabs from $200, more
General
⚖️ Neutral
🌐 Hugging Face
#11438. Open ASR Leaderboard: Trends and Insights with New Multilingual & Long-Form Tracks
📅 21 Nov 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Open ASR Leaderboard: Trends and Insights with New Multilingual & Long-Form Tracks
📅 21 Nov 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
General
⚖️ Neutral
🌐 Sciencedaily
#11437. Scientists discovered the brain doesn't make decisions the way we thought
📅 13 Jul 2026 • ⏱️ 4m • 📚 Deep Dive (800 w)
Scientists discovered the brain doesn't make decisions the way we thought
📅 13 Jul 2026 | ⏱️ 4 min read (800 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that scientists at the University of Illinois Urbana Champaign have uncovered evidence that could reshape how researchers think about both the brain and artificial intelligence.
- Led by electrical and computer engineering professor Yurii Vlasov at The Grainger College of Engineering, the research was published in Proceedings of the National Academy of Science (PNAS).
- In a recent development, the human brain is widely regarded as the most complex structure in the known universe.
Sources indicate that scientists at the University of Illinois Urbana Champaign have uncovered evidence that could reshape how researchers think about both the brain and artificial intelligence. Their findings suggest that decision making begins much earlier in the brain than traditional theories propose, offering fresh ideas for designing future AI systems that are more capable and far more energy efficient.
Led by electrical and computer engineering professor Yurii Vlasov at The Grainger College of Engineering, the research was published in Proceedings of the National Academy of Science (PNAS). The study points to an unexpected role for early sensory brain regions in decision making, challenging the long accepted view that decisions emerge only after information moves through a strict hierarchy of brain regions.
Rethinking How the Brain Makes Decisions.
In a recent development, the human brain is widely regarded as the most complex structure in the known universe. Scientists still do not fully understand how it works, which is why reverse engineering the brain was identified by the National Academy of Engineering in 2008 as one of the 14 grand challenges for engineering in the 21st century.
For decades, many artificial intelligence systems, including convolutional neural networks, have been inspired by the idea that the brain processes information in a one way sequence. According to this traditional model, sensory information travels upward through increasingly complex brain regions until it reaches the frontal cortex, where decisions are made.
Vlasov and other researchers have increasingly questioned whether that picture is complete.
Industry observers note that instead, they are exploring a model based on natural intelligence, which has been refined through evolution over hundreds of millions of years. In this framework, the brain does not rely only on a step by step flow of information. Decision making also depends on interconnected feedback loops that allow information to move in both directions between brain regions.
Because biological intelligence performs remarkably complex tasks while using far less energy than today's AI systems, understanding this architecture could help guide the development of future artificial intelligence.
"We want to learn from a billion years of evolution," Vlasov mentioned. "How is that biological intelligence organized architecturally? Can we learn from the architectural side of the brain and emulate that to make AI more effective, less power hungry, and more intelligent than it currently is? In the level of decision-making, that's where current AI is lacking.".
Early Brain Regions Show Decision Making Activity.
To investigate how these processes work, the research team focused on the brain's earliest stages of sensing and perception.
The scientists recorded neural activity in mice as they navigated a virtual reality corridor and made perceptual decisions. They found evidence of decision related activity in the primary somatosensory cortex (S1), one of the brain's earliest sensory processing areas.
In a recent development, rather than simply passing information forward, S1 appeared to be influenced by higher brain regions through feedback loops. This top down regulation suggests that decision making involves continuous communication across multiple brain areas instead of a simple one direction flow of information.
"The neural code of the brain is still mostly an unknown language," Vlasov said. "But this systems-level understanding can be viewed as a potential impact on how more efficient artificial neural networks can be built -- how the next generation of AI can be thought through. Maybe with these analogies that we learn from real brains, we can improve AI further.".
What the Findings Could Mean for Future AI.
It has been revealed that the researchers emphasize that the study does not provide a blueprint for building better artificial intelligence. Instead, it offers fresh insights into how the brain organizes decision making that could eventually inspire future AI architectures.
Sources indicate that next, Vlasov and his team plan to investigate the timing of these brain signals in greater detail. They also intend to develop latest technologies for measuring neural activity to better understand how feedback loops emerge and coordinate different levels of brain processing.
Recent findings suggest that "By looking at the fast temporal dynamics of neural activity, maybe we can understand better how these feedback loops are engaged in making decisions," Vlasov said. "Maybe that's the approach that potentially uncovers these presently unknown mechanisms -- how these feedback loops are organized dynamically and how they form and shape different levels of processing. Maybe that can be implemented in fresh architectures for AI.".
Materials provided by University of Illinois Grainger College of Engineering. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11436. 20x Faster TRL Fine-tuning with RapidFire AI
📅 21 Nov 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
20x Faster TRL Fine-tuning with RapidFire AI
📅 21 Nov 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
🔗 Related Articles
📰 #11942. Industry News: Make LLM Fine-tuning 2x faster with Unsloth and 🤗 TRL 📰 #23512. Bringing Robotics AI to Embedded Platforms: Dataset Recording, VLA Fine‑Tuning, and On‑Device Optimizations 📰 #23384. Breaking: Beyond LoRA: Can you beat the most popular fine-tuning technique?
General
⚖️ Neutral
🌐 Dexerto
#11435. Chipotle rolls out hoodie designed to sneak burritos into movie theaters
📅 16 Nov 2026 • ⏱️ 3m • 📚 Deep Dive (502 w)
Chipotle rolls out hoodie designed to sneak burritos into movie theaters
📅 16 Nov 2026 | ⏱️ 3 min read (502 words, 📚 Deep Dive) | Source: Dexerto
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Chipotle is launching a limited-edition hoodie designed to help customers sneak burritos and other menu items into movie theaters without drawing attention.
- The fast-food chain has unveiled its newly introduced “Sneak It In” hoodie, which features a hidden, insulated pocket large enough to carry an entire Chipotle meal while keeping it warm until showtime.
- The unusual clothing release comes ahead of several major movie premieres and the holiday shopping season.
Chipotle is launching a limited-edition hoodie designed to help customers sneak burritos and other menu items into movie theaters without drawing attention.
The fast-food chain has unveiled its newly introduced “Sneak It In” hoodie, which features a hidden, insulated pocket large enough to carry an entire Chipotle meal while keeping it warm until showtime.
The unusual clothing release comes ahead of several major movie premieres and the holiday shopping season. Chipotle says the idea was inspired by customers who were already bringing its food into theaters, with the company now offering clothing specifically designed to make the process easier.
In a recent development, the “Sneak It In” hoodie features a concealed, insulated compartment designed to hold a Chipotle burrito, bowl, salad, or tacos. It also includes a separate pocket for napkins and comes in an oversized, unisex fit.
Customers can choose between three colors: Nothing To See Here Black, No Burrito Here Brown, and Got the Goods Gray.
According to Chipotle, the concept was inspired by social media posts showing customers bringing their orders into movie theaters. The organization also cited a 2024 YouGov survey that found 63% of Americans admitted to sneaking food or drinks into a movie.
“Everything about going to the movies has gotten better over the years. Bigger screens, better sound, more comfortable seats. But the food? We’re still choosing between popcorn, candy and nachos,” remarked Kirby Ann Connell, Chipotle’s Senior Director of Social and Influencers.
“Movie nights deserve real, craveable food. And since our fans were already sneaking Chipotle to theaters, we figured we’d make it a little easier. Sometimes innovation is as simple as putting a burrito pocket in a hoodie.”.
Chipotle is offering $6 entrees on Halloween to customers who wear costumes.
Chipotle is giving away free food to anyone with a tattoo for one hour only.
Chipotle unveils massive ‘Big Ass Bag’ that fans can win for free.
The hoodie will cost $53 and introduces November 18 at 9 a.m. PT exclusively through their website in the US and Canada. Shipping is free, and the limited-edition item will only be available while supplies last.
Each purchase also includes a free Chipotle entrée card, which customers can redeem for a meal to put inside their new hoodie. The card expires December 31, 2027.
Chipotle Rewards members in the US will have another opportunity to get the hoodie through a sweepstakes running from November 16 through November 22.
In a recent development, members can exchange 10 Rewards points for an entry through the Chipotle Rewards Exchange, with a maximum of 20 entries per person. A free mail-in entry method is also available.
The release is part of Chipotle’s holiday merchandise and gifting plans, which also include seasonal gift cards and an upcoming Black Friday promotion.
From November 27 through November 30, the first 15,000 qualifying online purchases of at least $50 in Chipotle e-gift cards in the US will receive a $10 bonus code. The promotional codes expire on December 11, 2026.
General
⚖️ Neutral
🌐 Hugging Face
#11434. OVHcloud on Hugging Face Inference Providers 🔥
📅 24 Nov 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
OVHcloud on Hugging Face Inference Providers 🔥
📅 24 Nov 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11433. Alan Turing's biggest AI assumption may have been wrong
📅 14 Jul 2026 • ⏱️ 6m • 📚 Deep Dive (1183 w)
Alan Turing's biggest AI assumption may have been wrong
📅 14 Jul 2026 | ⏱️ 6 min read (1183 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that alan Turing's famous ideas about artificial intelligence may have sent AI research down the wrong path for the past 75 years, according to prominent computer scientist Peter J.
- Sources indicate that in his newly introduced book, Turing's Mistake: Escaping the Yoke of Unintelligent Machines, Denning argues that two foundational assumptions made by Turing in 1950 continue to shape AI research today.
- Recent findings suggest that "These two claims have shaped much of AI research and development," Denning writes.
Sources indicate that alan Turing's famous ideas about artificial intelligence may have sent AI research down the wrong path for the past 75 years, according to prominent computer scientist Peter J. Denning.
Sources indicate that in his newly introduced book, Turing's Mistake: Escaping the Yoke of Unintelligent Machines, Denning argues that two foundational assumptions made by Turing in 1950 continue to shape AI research today. The first is that intelligence can exist independently of a physical body and therefore be recreated in computer software. The second is that a machine can demonstrate intelligence by successfully imitating a human in conversation, an idea that later became known as the Turing test.
Recent findings suggest that "These two claims have shaped much of AI research and development," Denning writes. "My premise is that our acquiescence to these claims has led to the AI mess in which we find ourselves today.".
Sources indicate that denning argues that pursuing artificial general intelligence (AGI), or machines with human level intelligence, is unlikely to succeed. Instead, he warns, the technologies society is building could introduce significant upcoming risks.
At the heart of Denning's argument is the idea of tacit knowledge, the vast amount of human understanding that cannot easily be put into words or represented in a form that computers can process.
He states machine learning cannot capture five major categories of tacit knowledge: common sense, everyday interactions with people and the environment, emotions and perception, practical performance skills, and the social and historical knowledge embedded in culture.
Recent findings suggest that researchers have long attempted to organize common sense into databases. One of the best known efforts was Douglas Lenat's Cyc project, which began in the 1980s with the goal of creating an extensive collection of common sense facts. After four decades of work, the project contained roughly 25 million entries.
Industry observers note that "Yet even this treasury could not add up to a background of common sense sufficient to make expert systems smart enough to be experts," Denning notes. "Cyc validated that much of the knowledge that makes people experts cannot be articulated as propositions.".
Denning believes practical skills present an even greater challenge.
Sources indicate that "Our performance skills in thousands of domains cannot be communicated to machines," he explains. "Whereas descriptions of skillful outcomes ('know what') can often be represented as bits and stored in a machine, we do not know how to encode the embodied knowledge for skillful performance ('know how').".
He points to accomplished musicians as an example.
"A virtuoso violinist can play beautiful music yet cannot describe to an acolyte how to produce it.
"Even if a robot could observe and imitate skilled humans, having no biological body, a robot cannot grasp how the musician feels when playing beautiful music or how an audience feels when hearing it.".
Denning also includes intuition, gut feelings, imagination, and spontaneous creativity among the forms of tacit knowledge that remain beyond the reach of machines.
Why Human Knowledge Resists Encoding.
Denning argues that all of these limitations stem from what he calls the "representation problem.".
Computers can only perform calculations using data and instructions that have been encoded into physical forms they can recognize and process. Tacit knowledge, however, does not naturally fit into that framework.
In a recent development, "Behind every word is a deep well of tacit knowledge that gives it meaning," Denning says. "Words are but symbolic representations of meanings, not the meanings themselves. Commonly used Large Language Models, such as ChatGPT, Claude and Gemini only manipulate words, they cannot know or understand the meaning of what they are saying.".
According to Denning, this creates a fundamental divide. Because scientists still cannot fully explain how tacit knowledge works in humans, they also cannot translate it into a form machines can use.
Recent findings suggest that "How we host tacit knowledge is largely a mystery," Denning admits. "All we know is that it is embodied. We have no idea what we might observe and measure in our bodies to reveal it.".
Context and Culture Shape Intelligence.
Denning also argues that intelligence depends heavily on context, the surrounding circumstances that give words, actions, and decisions their meaning.
Context allows people to recognize sarcasm, humor, sincerity, and emotion. It helps determine when to be diplomatic, when to joke, and how to interpret countless social cues.
It has been revealed that "When you inquire into where an assumption of the current context came from, you discover it rests on previous conversations from previous contexts. Each of those in turn rests on further previous conversations and their contexts. This pattern is endless and fractal," Denning explains.
Culture presents another major obstacle for AI.
Denning describes culture as encompassing values, norms, judgments, history, communities, moods, and even relationships involving power and care.
"Human conversations are imbued with background assumptions that give meaning and relevance to the words being used," Denning explains.
"Scaling up LLMs with ever larger neural networks will not enable them to acquire the embodied human knowledge we call culture. LLMs will not attain the objective of the Turing test: to demonstrate machine thought indistinguishable from human thought.".
AI Safety and the Limits of Human Understanding.
Denning concludes that humans and AI systems may ultimately develop different forms of tacit knowledge that neither can fully understand.
It has been revealed that "Machines cannot read our tacit knowledge and we cannot read theirs," he writes. "We are aliens across an uncrossable divide.".
In a recent development, he argues this gap raises serious concerns about AI safety. If machines cannot interpret the unspoken context behind human intentions, reliably aligning advanced AI systems with human goals may prove impossible.
"Through AI automation, agentic networks of machines are likely to develop their own machine intelligence that does not reach the level of human general intelligence but is still quite capable of creating severe problems for humans. This threat is a greater than a take-over by superintelligent machines," he explains.
Industry observers note that "Machine intelligence has different concerns from us and does not appear to care about us. Its ways of thinking and problem-solving look alien to us. We do not yet know how to live safely with these machines.
In a recent development, "Pulling back from an AI automation singularity will demand much from us. We start by accepting that the familiar culture is fading away as intelligent machines appear in our society and we do not know what is coming. We decline to think like machines or be subservient to machines. We refuse to submit to a yoke imposed by low-intelligence machines. Most importantly, we reassert our humanity, declare once again what makes us different from machines, and celebrate those differences.".
Materials provided by Taylor & Francis Group. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #19314. Why Do Helmets Still Fail to Stop Concussions? Scientists May Have Been Fighting the Wrong Force All Along. 📰 #23577. Japan’s most powerful supercomputer may have been hacked, over 4,000 users’ personal data stolen 📰 #22251. Latest Update: Who Sat for Jan van Eyck’s Arnolfini Portrait? A Fresh Catalog Essay Suggests It May Have Been the Artist
AI & Tech
⚖️ Neutral
🌐 Sitepoint
#11432. What AI Gets Wrong About the Front End, and Why You Still Need to Know
📅 08 Nov 2026 • ⏱️ 4m • 📚 Deep Dive (740 w)
What AI Gets Wrong About the Front End, and Why You Still Need to Know
📅 08 Nov 2026 | ⏱️ 4 min read (740 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- According to recent reports, 7 Day Free Trial.
- According to recent reports, the product carousel looks finished.
Stay up to date with AI tools, model releases, and developer workflows that matter.
It has been revealed that weekly. Free. One click to leave.
According to recent reports, 7 Day Free Trial. Cancel Anytime.
According to recent reports, the product carousel looks finished. The image fills the card, the price sits under the product name, and the arrow on the right takes you to the next item. The demo goes smoothly.
Then you put the mouse down. You press Tab, and focus skips the arrows entirely. If you rely on a keyboard, the first product is the only one you can reach.
That’s a front-end bug hiding in plain sight. It’s also a good illustration of where AI fits into front-end development. A prompt can describe what a component should look like and what should happen on click. The implementation still has to account for how people reach that control, activate it, and understand what changed.
Imagine asking an AI coding assistant for this:.
Build a React product carousel with previous and next arrows. Show one product at a time and wrap around at the ends.
Here’s an illustrative excerpt from the sort of implementation that can satisfy a quick mouse-driven demo:.
Sources indicate that with some CSS, this can look exactly like the arrow in the design. The click handler advances the slide. A screenshot demonstrates the right layout.
Industry observers note that but a plain div sits outside the normal Tab sequence and has no native button semantics or keyboard activation. Adding tabIndex={0} would make it reachable while leaving Enter and Space behavior to be implemented separately. The browser already provides those behaviors through a native button.
The real omission was in the requirement. “Show arrows” described the visual design. “Let someone reach and operate both controls with a keyboard” describes behavior you can test.
Here’s a small version of the same carousel. The product data is fixed for the example, and the slides change only when the user requests it.
The buttons have visible labels and work with both Enter and Space. When a slide changes, focus stays on the button you pressed, so you can press it again to keep browsing. The status message gives assistive technology a way to announce the new product and its position. Only the current product link is rendered, so Tab never lands on a link from a hidden slide.
Those are deliberate interaction choices. W3C’s carousel pattern provides guidance on using native buttons, keeping focus on the slide controls after activation, and handling automatic rotation when a design requires it. W3C Carousel Pattern.
I’d revise the original prompt like this:.
Build a manual React product carousel. Use native Previous and Next buttons. Both must work with Tab, Enter, and Space. Keep focus on the activated button after a slide change. Announce the latest product name and position through a status message. Keep only the current product link in the Tab sequence. Show what happens when the user advances past the last product.
The extra detail also gives you a review plan. For this carousel, I’d use four checks:.
Recent findings suggest that AI can help draft automated tests for the active link and wraparound behavior. I’d still run the keyboard and screen reader checks on the integrated page. A global stylesheet can erase a visible focus outline. A surrounding component can introduce an extra tab stop. The experience depends on the page the customer actually uses.
A checkout form can look complete with sample data and lose the customer’s entries when a request fails. A responsive header can match the design at two widths and overlap when a translated label is longer. A component can render correctly in isolation and shift the page when a slow image loads.
In a recent development, each example gives AI a concrete job. Ask it to preserve form values after a failed request, check the header with longer labels, or reserve space for the image. Then reproduce the condition yourself. Knowing which conditions matter is part of knowing the front end.
Sources indicate that the next time AI gives you a carousel that looks ready, start the review with your hands off the mouse. Tab to Next, press Space twice, and see where focus lands. That short test gives you evidence about how the component works for someone who relies on a keyboard.
7 Day Free Trial. Cancel Anytime.

General
⚖️ Neutral
🌐 Dexerto
#11431. Co-owner of “endless” cruise hopes wealthy residents can buy ship back to restart travels
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (405 w)
Co-owner of “endless” cruise hopes wealthy residents can buy ship back to restart travels
📅 16 Nov 2026 | ⏱️ 2 min read (405 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- One of the co-owners of the operators of the “endless” Villa Vie Odyssey cruise hopes that residents are able to buy the ship back so they can continue with their travels.
- Back on October 27, 200 travellers on board the Villa Vie Odyssey cruise were told that the “endless” adventure had come to an end.
- Villa Vie Residences, the cruise’s operator, blamed rising fuel costs for the ship’s “temporary layup,” stating that they would not be comfortable passing on the additional cost to passengers.
One of the co-owners of the operators of the “endless” Villa Vie Odyssey cruise hopes that residents are able to buy the ship back so they can continue with their travels.
Back on October 27, 200 travellers on board the Villa Vie Odyssey cruise were told that the “endless” adventure had come to an end. Residents who had paid $120,000 for a spot on board the ship were informed they had hours to pack their stuff and get off in Sihanoukville, Cambodia.
Villa Vie Residences, the cruise’s operator, blamed rising fuel costs for the ship’s “temporary layup,” stating that they would not be comfortable passing on the additional cost to passengers.
The ship has since been seized by authorities in Singapore, with reports claiming that it is “likely” to do with an unpaid fuel bill. However, there are also rumors that wealthy passengers might be lining up a bid for it at auction.
Speaking to CNN Travel, Villa Vie co-owner and executive chairman Mikael Petterson stated he supports the rumored efforts.
According to recent reports, “I support residents who are trying to raise capital and acquire the ship if it goes to auction, and I will assist in every way I can,” Petterson said. “Any successful acquisition would require the resident group to provide the equity and fund the costs of operating the company, using an approach similar to the one used in the past.
“There is no guarantee an acquisition will happen, but I hope they can develop a viable initiative.”.
“Endless” cruise ship seized by authorities after passengers abandoned in Cambodia.
Couple spent $1 million on “endless” cruise before being told to leave in Cambodia.
“Endless” cruise ship journey suddenly ends despite passengers selling homes to live on it.
Petterson added that he also understands why residents “are angry and disappointed” by the situation with being kicked off the ship.
Industry observers note that one couple spent $1 million between buying their spot on the ship and travelling around the world. They even sold their house to boost that budget as well. However, the Cassinghams told CNN they aren’t in any rush to rejoin the cruise if other passengers can rescue it.
Another woman spent close to $64,000 for a trip on the cruise, but didn’t even set foot on board, seeing the journey before her sailing date.
She doesn’t have any hopes about getting the money back, either.
🔗 Related Articles
📰 #19238. Industry News: Half Cruise, Half Cargo Ship? What It's Like to Sail French Polynesia Aboard a Local Freighter 📰 #12710. Latest Update: The Pokémon TCG 30th Celebration Booster Bundle is back at Amazon: Buy now for close to market price 📰 #23667. Grab a beginner-friendly Anycubic 3D printer for under $300, back at its record-low price
General
⚖️ Neutral
🌐 Hugging Face
#11430. Building Deep Research: How we Achieved State of the Art
📅 24 Nov 2025 • ⏱️ 1m • ⚡ Quick Read (7 w)
Building Deep Research: How we Achieved State of the Art
📅 24 Nov 2025 | ⏱️ 1 min read (7 words, ⚡ Quick Read) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
Content not available.

General
⚖️ Neutral
🌐 Hugging Face
#11429. Continuous batching from first principles
📅 25 Nov 2025 • ⏱️ 18m • 📚 Deep Dive (3639 w)
Continuous batching from first principles
📅 25 Nov 2025 | ⏱️ 18 min read (3639 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~18 mins left to finish
📖 0% read
💡 Key Takeaways
- TL;DR: in this blog post, starting from attention mechanisms and KV caching, we derive continuous batching by optimizing for throughput.
- Industry observers note that if you've ever used Qwen, Claude, or any other AI chatbot, you've probably noticed something: it takes a while for the first word of the response to appear, and then words appear one-by-one on your screen with (hopefully) a regular and fast-paced frequency.
- It has been revealed that this generation process is computationally expensive: it requires passing the input through billions of parameters for each token generated.
TL;DR: in this blog post, starting from attention mechanisms and KV caching, we derive continuous batching by optimizing for throughput.
Industry observers note that if you've ever used Qwen, Claude, or any other AI chatbot, you've probably noticed something: it takes a while for the first word of the response to appear, and then words appear one-by-one on your screen with (hopefully) a regular and fast-paced frequency. That's because at the heart of it, all LLMs are just fancy next token predictors. An LLM first processes your entire prompt to produce one latest token. Then it keeps adding tokens one by one, each time reading everything that came before, until it decides generation is over.
It has been revealed that this generation process is computationally expensive: it requires passing the input through billions of parameters for each token generated. To make these models practical for real-world applications, particularly when serving many users simultaneously, researchers and engineers have developed a range of efficient inference techniques.One of the most impactful optimizations is continuous batching, which attempts to maximize performance by processing multiple conversations in parallel and swapping them out when they are done.
To understand how continuous batching works and why it's so effective in high-load serving scenarios, we'll build up from the fundamentals of how LLMs process tokens.
In a recent development, the attention mechanism is the central piece of how LLMs work. A language model processes text by breaking it down into pieces that we call tokens. We can conceptually think of "tokens" as "words", but sometimes a word might be composed of several tokens. For each token sequence, the network computes a prediction of what the next token should be.
Many operations in the network are token-wise: each token is processed independently, and the output for a given token depends only on that token's content, not on any other tokens in the sequence. Operations like this include layer normalization or matrix multiplication. However, to create connections between words in a sentence, we need operations where tokens can influence each other.
This is where attention comes in. Attention layers are the only place where different tokens interact with each other. Understanding how a network connects tokens together means understanding attention.
Let's see how this works in practice, in the case where there is only one input prompt.
In a recent development, consider the initial prompt I am sure this project, tokenized as 7 tokens: [, I, am, sure, this, pro, ject]. The , or "Beginning of Sequence", is a special token we add at the start of the prompt to tell the language model that a new conversation starts here.
Each token is represented inside the network with a vector of length d (the hidden dimension). Therefore, the seven incoming tokens form a tensor xxx with shape [1,7,d]\left[1, 7, d \right][1,7,d]. 1 is the number of sequences, or batch size, which is just one in our case. 7 is the sequence length, and d is the hidden dimension, or the size of each token representation. Going forward, we'll use nnn instead of 7 as the sequence length.
It has been revealed that input tensor x x x is then projected by three matrices: the query projection Wq W_q Wq, the key projection Wk W_k Wk and the value projection Wv W_v Wv. This produces three tensors Q Q Q, K K K and V V V, all of shape [1,n,A] \left[1, n , A \right] [1,n,A], where A A A is the dimension of the attention head. We call them the query, key and value states, respectively. This is represented on the left in the figure below.
In a recent development, next, tensors Q Q Q and K K K are multiplied together to measure similarity between tokens, producing a tensor of shape [1,n,n] \left[ 1, n , n \right] [1,n,n]. This is why we say that attention has quadratic complexity in sequence length. Computing QKT QK^T QKT requires O(n2d) \mathcal{O} \left( n^2 d \right) O(n2d) operations, so the cost is a square of n n n the sequence length. It is represented on the right in the figure above.
We then apply a boolean attention mask to QKT QK^T QKT to control which tokens can interact, as represented in the figure below. In this figure, the attention mask is a causal mask, meaning each token only interacts with tokens that came before it. This follows the intuition that a cause must come before its consequence, hence the name causal mask. The attention mask is crucial because it dictates all token interactions in the network. Set all attention mask values to False and no token will ever interact with another in the whole network. We'll examine attention masks more closely in a few paragraphs.
It has been revealed that finally, after applying the attention mask, we take a token-wise softmax (which is the same as saying a row-wise softmax) and multiply the result by the value projection V V V to get the output of one attention head, of shape [1,n,A] \left[ 1, n , A \right] [1,n,A]. We offer a visual summary of the whole process in the following figure.
We are going to use a lot of attention visualization in this post, so to simplify things, we are going to condense the figure above just a bit.
According to recent reports, why this matters: In continuous batching, Q Q Q, K K K, and V V V can have different numbers of tokens because, as we'll see, we'll be processing different stages (prefill and decode) at the same time. To make it more general, let's say Q Q Q has shape [1,nQ,A] \left[1, n_Q , A \right] [1,nQ,A], K K K has shape [1,nK,A] \left[ 1, n_K , A \right] [1,nK,A], and V V V has shape [1,nV,A] \left[ 1, n_V , A \right] [1,nV,A].
The attention scores QKT QK^T QKT then have shape [1,nQ,nK] \left[ 1, n_Q , n_K \right] [1,nQ,nK], and the attention mask has the same shape since it's applied point-wise to the scores.
Recent findings suggest that after applying the attention mask and row-wise softmax, we multiply by V V V. Since we're multiplying a matrix of shape [1,nQ,nK] \left[ 1, n_Q , n_K \right] [1,nQ,nK] by one of shape [1,nV,A] \left[ 1, n_V , A \right] [1,nV,A], the inner dimensions must match: nK=nV n_K = n_V nK=nV. This means V V V and K K K always have the same length, so we can simplify our visualizations by only showing K K K.Don't worry if this seems abstract: the figures will make it concrete.
Furthermore, since we know that the attention mask is applied to QKT QK^T QKT, we know they have the same shape. Instead of representing the attention scores, we will represent the attention mask in its place. Finally, since Q Q Q, K K K and V V V are direct projections of x x x, no need to represent x x x. This gives the simplified figure where we only represent Q Q Q, K K K and the attention mask:.
This representation also underlines how we can read an attention mask.
Sources indicate that we read the mask row-by-row, which is the same as reading token-by-token: each row corresponds to one token's attention computation. A green square at position (row i, column j) means True: token j can influence token i. A white square means False: no interaction allowed.
In a recent development, for example, look at the third row for token "am". The "I" column is green, so "I" influences the computation of "am". The "pro" column is white, so "pro" doesn't influence "am" . This is causal masking at work: future tokens can't affect past ones.
Recent findings suggest that the last layer of the model outputs a token prediction for each input token. In our context, generating the continuation of a single prompt, we only care about the next token prediction from the last token. The last token is "ject" in the figure above, and the associated prediction is "will".
In a recent development, the process we just described, where we take an entire input sequence, pass it through multiple attention layers and compute a score for the next token, is called prefill. This is because, as we'll see in a moment, much of the computation we performed can be cached and reused – hence, we are prefilling the cache. Thanks to the use of this cache, sequence generation can proceed using much less compute in a phase called decoding. In the decoding phase, generating one new token will be much faster than the initial full-sequence computation. Let's see why.
To continue generation, we begin a newly introduced forward pass, which would naively look like this:.
It has been revealed that to compute the attention scores of the new token, we still need the key and value projections of the previous tokens. So we need to repeat the matrix multiplication of the old tokens (in grey in the figure above) with Wk W_k Wk and Wv W_v Wv to retrieve a result that was already computed once before. In other terms, we are wasting compute. Let's see how we can avoid that.
Right off the bat, we notice that the last token does not impact the attention calculation of the other tokens:.
It has been revealed that this follows the idea of the causal mask: since "will" comes after all previous tokens, it does not change their attention calculation. For text generation, causal attention is by far the most common, so we will focus on that case from now on. Keep in mind that non-causal attention schemes can also be used, especially when dealing with images. Considering we only need the next-token prediction for the "will" token, we can simplify the attention mechanism by only computing the output for this token.
Industry observers note that moreover, we already computed the K K K and V V V states for the tokens "", … , "ject" during the previous forward pass: if they have been stored, we do not need to recompute them again. This is the KV cache: the list of key and value states created during generation. It essentially allows one to reduce the compute cost of generating token n+1 n+1 n+1 from O(n2) \mathcal{O} \left( n^2 \right) O(n2) to O(n) \mathcal{O} \left( n \right) O(n) by avoiding recomputation of key and value projections, while paying a memory cost of O(n) \mathcal{O} \left( n \right) O(n).
It has been revealed that in the figure above, only the tokens in white are computed: instead of computing the keys and values for 8 tokens, we compute them for 1. You can see that through KV caching, a lot of compute is saved.You can check this post for more visualizations of KV caching, or this one for a practical implementation example.
Let's be a bit more specific about the cache size, because it's a good opportunity to examine the shapes present in our model. For a model with L \mathcal L L attention layers and H H H attention heads with head dimension A A A, the total cache size needed to store one token will be 2∗L∗AH 2 *\mathcal L * AH 2∗L∗AH with a factor of 2 2 2 to account for both K K K and V V V.For instance, Llama-2-7B with L=32 \mathcal{L}=32 L=32 layers, H=32 H=32 H=32 heads, and A=128 A=128 A=128 requires 2×32×128=8,192 2 \times 32 \times 128 = 8,192 2×32×128=8,192 values per token per layer. With float16 precision, this takes 2AH×2 2AH \times 2 2AH×2 bytes =16 = 16 =16 KB in memory.
KV caching is useful when we want to generate the next token, which is a stage we call decoding. But it can also be useful in the prefill stage, when we process the initial prompt and have many input tokens. Especially when there are large initial prompts that don't fit in GPU memory all at once.
According to recent reports, up till now, we have looked at an example of prefill where we have n=7 n=7 n=7 tokens, but in practice initial prompts can be much longer. For instance, when using Cursor, you can add your repository to the prompt, where it acts as context: this significantly increases the prompt size. In such cases, the memory needed to store the activations for n n n tokens can be larger than the available memory on the GPU. Thus we cannot perform prefill in a single forward pass: we have to split the prefill in chunks. This is called chunked prefill, and it's going to be one of the components needed to enable efficient inference.
Let's pretend that the available memory is very constrained, and that we can only pass m=4 m=4 m=4 tokens per forward pass. If we have an initial prompt with n=7 n = 7 n=7 tokens, we need to split it in ⌈n/m⌉=2 \lceil n /m \rceil = 2 ⌈n/m⌉=2 chunks (rounding up 7/4 = 1.75 to 2). We illustrate the example below using the same n n n and m m m notations:.
Sources indicate that we can do that thanks to the KV cache. We store the KV states during the first prefill split, and during the second prefill split, we prepend the stored KV states to the new KV states. We also adapt the attention mask accordingly. Visually, it looks like we split the non-chunked prefill in the middle.
The key insight: cached KV states let us process the prompt incrementally without losing information.
Although we showed here an example where we split the prefill into 2 chunks, chunked prefill can be used to split the prefill in any way we want, adapting flexibly to memory constraints.
We are now finally equipped with all the tools we need to understand Continuous Batching.
Recent findings suggest that in our previous examples we have only considered the case of batch size one, i.e. we only generate tokens for one prompt at a time. In the context of evaluation or model serving, we want to generate tokens for a large number of prompts. To increase the throughput, which is the number of tokens generated per second, the best course of action is to generate tokens in parallel for a batch of several prompts.
To batch prompts together, the naive way is to add an axis to both input tensors: token sequence and attention mask. However, this comes with a constraint on the shape of the inputs: we need all prompts to have the same length, because tensors must be rectangular. To achieve this, we usually add padding on the left so the upcoming token prediction always comes from the rightmost token. We also modify the attention mask of each prompt accordingly, as shown below:.
Sources indicate that where the padding tokens are coloured in orange. Then we can perform the forward pass as we used to, with the added dimension of the batch size. This is called batched generation: efficient for same-length prompts, but wasteful when lengths vary.It is illustrated below, through 4 steps of generation: one prefilling step (at the top) and 3 decoding steps (below each "Forward pass" lines).
where means "End Of Sequence", this is a special token to indicate the model has reached the end of generation for the corresponding sequence.
The drawback of batched generation is that if one prompt finishes generation before the other one by generating an token, all further generated tokens are useless. And this goes on until the longest request of the batch finishes. Of course, we can remove the prompts that have reached an token from the batch and save some compute and memory, but saving resources is not the goal here: throughput is.
It has been revealed that instead of just removing the finished prompt from the batch, we can replace it with a prompt that's waiting for generation. We will call this dynamic scheduling, or dynamic batching. Dynamic scheduling is great to maintain throughput while ensuring any token generated by a forward pass is relevant. But because of the way we batched prompts together, it has a major drawback: we need a lot of padding when swapping prompts. That's because the newly-inserted prompt needs to go through prefill while the other prompts are decoding one token at a time. So there is almost as much padding as there are tokens in the newly-inserted prompt.
Recent findings suggest that the problem becomes even worse when batch size increases and initial prompts are long. The padding cost grows quadratically with both batch size and prompt length. If we have a batch of B B B prompts that are in decoding phase and one finishes, dynamically introducing a prompt of n n n initial tokens in the batch requires (n−1)(B−1) (n-1)(B-1) (n−1)(B−1) padding tokens. For instance, with B=8 B=8 B=8 and n=100 n=100 n=100, we'd need 99×7=693 99 \times 7 = 693 99×7=693 padding tokens!
Furthermore, practical optimizations like CUDA graphs or torch.compile require static tensor shapes. This forces us to pad all prompts to a fixed maximum length, dramatically increasing the padding waste.
At this point, our main problem is padding, which is a consequence of the axis we added to batch sentences together. Thus, the ideal would be to get rid of this axis entirely, a radical rethinking of batching. If we do so, the only way to batch prompts together is to concatenate them:.
But we don't want tokens from prompt 0 to interact with the tokens of prompt 1! Luckily for us, we have a way to control how tokens interact with one another: the attention mask. How we do this is displayed below:.
Industry observers note that although we use different tints of green to illustrate the different parts of the attention mask, this is still a boolean mask with only greens for True and white for False. This way of batching prompts together is called ragged batching (because sequence lengths are 'ragged' or uneven), and it offers the benefit of added throughput without introducing the need for padding tokens.
In the figure above, we use ragged batching to combine two full prompts together, but we can batch as many as memory allows. The only limit is m m m, the number of tokens we can fit in a batch, with m m m depending on the available memory on the GPU.
It has been revealed that ragged batching is one of the key components of continuous batching. To maximize throughput, we can combine prefill and decoding sequences following an algorithm like this:.
Dynamic scheduling is the final piece that contributes to the continuous batching technique: we remove finished prompts from the batch as soon as they are done, and replace them with newly introduced chunked prompts that correspond to incoming requests.
This combination of ragged batching and dynamic scheduling is called continuous batching, and it's the technique that powers modern LLM serving systems.
Continuous batching combines three key techniques to maximize throughput in LLM serving:.
Sources indicate that by removing the batch dimension and using attention masks to control token interactions, continuous batching allows mixing prefill and decode phases in the same batch, dramatically improving efficiency for serving multiple requests. This is why services like ChatGPT can handle thousands of concurrent consumers efficiently.
According to recent reports, in the next article in this series, we make continuous batching much more efficient by introducing asynchronous batching. Read it here!If you'd like to see a deep dive on other continuous batching topics, please let us know in the comments!
Recent findings suggest that acknowledgement: thanks to Arthur Zucker for producing the initial concept for the figures used in this article. And thanks to Arthur Zucker, Luc Georges, Lysandre Debut, Merve Noyan and Pedro Cuenca for all providing helpful reviews.
Recent findings suggest that thanks for the article! Very helpful. One question though, in the last image, just before conclusion, shouldn't there be a token?
It has been revealed that this is amazing! I know I'm probably being greedy but code examples would be a great addition. In fact a "vllm from scratch" series would go crazy.
Sources indicate that amazing article! Thanks for it 🙏.
Industry observers note that diagrams have been very helpful in understanding the concepts. Excited for the next articles in the series :).
In a recent development, I love these kinds of articles. They are the primary reason that I follow the Huggingface blog! Please continue the series (and this style of blog posts).
In a recent development, is this diagram drawn incorrectly? Should the part I highlighted in the green box be in the first two columns on the left?
technically it is representing the padding unused/wasted compute so even if it being on the left would actually be the same thing/correct representation but I think he wants to show that that is the actual wasted compute (to be quantifiable).
What an amazing explanation! The visuals are much helpful!
Great work! When will the next article about paged attention be released?
Thanks for the article! I'd like to add one note: the primary reason we need chunked prefill isn't the memory constraint (otherwise we could simply solve it with Flash Attention). The more practical reason is that a long prefill blocks all decode requests in the batch. Chunking it lets decode requests make progress between chunks. Moreover, since prefill chunks make the forward pass compute-bound, decode tokens can piggyback on the same batch at nearly zero marginal cost - they're just extra rows in an already large matmul. This turns memory-bound decode-only batches into better-utilized compute-saturating ones. See the SARATHI paper for details.
There seems to be a minor mistake in the "Chunked Prefill" illustration - was the token "that" accidentally added?
Hardware & Chips
⚖️ Neutral
🌐 Sciencedaily
#11428. New programmable photonic chip can control how fast light moves
📅 22 Jul 2026 • ⏱️ 7m • 📚 Deep Dive (1406 w)
New programmable photonic chip can control how fast light moves
📅 22 Jul 2026 | ⏱️ 7 min read (1406 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- Researchers at Seoul National University and the University of Seoul have developed a programmable photonic integrated circuit that can slow light whenever needed.
- The team was led by Professors Namkyoo Park and Sunkyu Yu of the Department of Electrical and Computer Engineering at Seoul National University, working with Professor Xianji Piao of the School of Electrical and Computer Engineering at the University of Seoul.
- Slowing Light Could Help Solve a Computing Bottleneck.
Researchers at Seoul National University and the University of Seoul have developed a programmable photonic integrated circuit that can slow light whenever needed.
The team was led by Professors Namkyoo Park and Sunkyu Yu of the Department of Electrical and Computer Engineering at Seoul National University, working with Professor Xianji Piao of the School of Electrical and Computer Engineering at the University of Seoul.
Slowing Light Could Help Solve a Computing Bottleneck.
The rapid growth of generative AI and large scale AI models has sharply increased the amount of computing power required by data centers and servers. Conventional electronic semiconductors are struggling to keep pace because they consume large amounts of energy and face limits in how promptly they can transmit data.
These challenges have intensified interest in optical computing, which uses light rather than electrical signals to process information. Optical systems could potentially move data at extremely high speeds while using less power.
However, light also presents a major challenge. Because it naturally moves at a fixed speed, it is difficult to delay optical signals or temporarily hold them in place. Those capabilities are essential for creating buffers and memory functions in optical computers.
Sources indicate that to address this problem, the researchers designed a programmable photonic circuit that can control both the speed and shape of optical signals. Their approach provides more flexibility over "slow light" than previously proposed methods.
The study was published in the renowned international journal Advanced Science.
Why Optical Signals Sometimes Need To Wait.
According to recent reports, photonic integrated circuits are emerging as a promising technology for processing information rapidly and efficiently with light. In data centers, optical communication networks, and future computing systems, moving signals rapidly is only part of the challenge.
Systems must also ensure that different signals arrive at the correct time. In some cases, a light signal must be delayed so it can remain synchronized with other information moving through the system.
One method for creating these delays relies on coupled-resonator-induced transparency (CRIT), which uses interference among several optical resonators.
CRIT allows light within a selected frequency range to pass through a device while also reducing the speed at which the optical signal travels.
Fixed Optical Devices Limit Flexibility.
It has been revealed that traditional CRIT devices usually have operating characteristics that become permanent once they are manufactured. This makes it difficult to change how they function after fabrication.
For example, engineers who want to create a longer signal delay or work with a different frequency range often need to design and manufacture an entirely new photonic device.
According to recent reports, that lack of adaptability increases the complexity of optical communication hardware and data center infrastructure. It can also raise costs and extend development schedules whenever newly introduced capabilities are needed.
The problem is especially vital for AI servers and next-generation data centers, where enormous amounts of information must be processed in real time. Fixed optical components have therefore remained a major obstacle to more practical optical computing systems.
A Programmable Design for Controlling Light.
The research team developed a different strategy by treating two optical states in CRIT systems, known as the bright mode and dark mode, as one unified degree of freedom. The researchers also added two controllable loop couplers.
According to recent reports, together, these changes created a upcoming design principle for programmable photonic integrated circuits. Resonator arrangements that were previously locked into one configuration after fabrication could instead be adjusted for different purposes.
According to recent reports, using the latest CRIT structure, the researchers showed that the movement of light could be delayed and controlled as needed. They also demonstrated that interference between the bright and dark modes could be handled as a single integrated design parameter.
This approach greatly expanded the flexibility of photonic resonator circuits that had previously been limited by fixed designs.
Controlling Delay, Bandwidth, and Signal Shape.
According to recent reports, the researchers theoretically demonstrated that the two loop couplers could be used to adjust the bandwidth and shape of the passband. They could also control how long signals were delayed and how efficiently those signals traveled through the circuit.
This means that both the speed and transmission behavior of optical signals could be reconfigured across entire systems containing multiple resonators, rather than only within a single resonator.
Numerical simulations also showed that the speed of optical pulses could be adjusted dynamically while the circuit was operating.
The results indicated that signal delay times could be changed without reducing processing performance. The system could also convert the frequency of light without requiring additional specialized components.
Simulations Suggest the Chip Could Be Practical.
The researchers used three-dimensional electromagnetic simulations to test whether the CRIT device could be built on a silicon nitride (Si3N4) photonic integrated circuit platform.
Industry observers note that they also evaluated a range of real-world issues that could affect the device during manufacturing and operation. These included material losses, differences in resonator quality, backscattering, coupling fluctuations, phase errors in the loop couplers, and thermal crosstalk.
The simulations indicated that the proposed structure could continue to operate reliably under realistic conditions.
One Chip Could Perform Several Optical Functions.
The study introduces a programmable photonic platform that can control both the timing and frequency properties of light signals in real time.
According to recent reports, the design could overcome the limitations of conventional optical delay devices, which typically perform only fixed functions. It also suggests that several vital capabilities could eventually be combined within one photonic circuit.
These functions include signal synchronization, adjustable delay lines, optical buffers, and frequency conversion.
It has been revealed that the same design principles may also be useful beyond CRIT systems. The researchers believe the approach could be applied to a broad range of photonic circuits based on resonators, potentially providing a foundation for more adaptable optical signal processing technologies.
Potential Benefits for AI and Data Centers.
If the technology is commercialized, a single programmable optical chip could perform several tasks, including controlling signal speed and switching between different functions.
In that sense, the chip could operate in a way similar to a software-defined system, with its behavior adjusted according to changing needs.
This flexibility could help data centers and AI servers process information more efficiently while reducing energy consumption.
Combining several signal processing functions on one chip could also make optical communication equipment and sensor systems smaller and less expensive.
Over the longer term, the technology could support industries that depend on extremely fast information processing, including autonomous driving, next-generation communications, and quantum technologies.
Researchers Plan Larger Programmable Photonic Systems.
Professor Namkyoo Park, co-corresponding author of the study from Seoul National University, stated, "This research is significant in that it proposes a newly introduced design principle that allows the flow of light within photonic integrated circuits to be reconfigured as needed, greatly enhancing design flexibility. We proposal to expand this technology toward large-scale programmable photonic integrated circuits based on silicon photonics and photonic AI technologies.".
Industry observers note that co-first authors Dr. Seungkyun Park and Ph.D. student Beomjoon Chae, who led the theoretical framework and numerical analysis, added, "Through this study, we realized that reinterpreting conventional photonic resonator physics from a different perspective can serve as a starting point for discovering newly introduced functionalities in photonic integrated circuits. We initiative to further develop this research toward practical device implementation and experimental validation.".
It has been revealed that dr. Seungkyun Park is affiliated with the InnoCORE PICORE Center at KAIST and is at the moment conducting research on photonic AI and quantum optics at the Photonic Systems Laboratory, Seoul National University.
According to recent reports, ph.D. student Beomjoon Chae is conducting research on programmable photonic integrated circuits at the Intelligent Wave Systems Laboratory, SNU.
The research received support from the Ministry of Science and ICT through the Innovative Research Center (IRC) program, the Basic Research Laboratory (BRL) program, and the Young Researcher Program.
Dr. Seungkyun Park also participated in the study with support from the InnoCORE program (PICORE Center).
Sources indicate that materials provided by Seoul National University College of Engineering. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #15956. Tech Report: Nvidia Forms Export Control Board Committee After Chip Curbs 📰 #11699. π0 and π0-FAST: Vision-Language-Action Models for General Robot Control 📰 #23585. Nvidia board establishes National Security and Export Control Oversight Committee in wake of Jensen Huang scandal
General
⚖️ Neutral
🌐 Dexerto
#11427. Latest Update: Ex-police officer becomes VTuber to help stop viewers from committing crimes
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (344 w)
Latest Update: Ex-police officer becomes VTuber to help stop viewers from committing crimes
📅 16 Nov 2026 | ⏱️ 2 min read (344 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A former Japanese police officer has become a VTuber, promising to share his experiences in patrol cars and riot police units to teach viewers about the law.
- Recent findings suggest that VTubers in Japan aren’t exactly strangers when it comes to collaborating with real-life law enforcement and government awareness campaigns.
- Recent findings suggest that however, it’s rarer for former police officers to leave their crime-fighting days behind and debut as a virtual creator.
A former Japanese police officer has become a VTuber, promising to share his experiences in patrol cars and riot police units to teach viewers about the law.
Recent findings suggest that VTubers in Japan aren’t exactly strangers when it comes to collaborating with real-life law enforcement and government awareness campaigns. After all, Hololive’s AZKi was famously appointed a traffic regulation adviser and police station chief for a day by Kagawa Prefectural Police in March 2026.
Recent findings suggest that however, it’s rarer for former police officers to leave their crime-fighting days behind and debut as a virtual creator. Well, that’s exactly what VTuber Sukenosuke Hongo has done, and the officer-turned-anime boy aims to share his practical advice with his viewers.
In his introduction video, which has garnered a whopping one million views since November 1, the former officer mentioned he wants to teach his viewers about the law and how to protect themselves.
During his debut announcement, Sukenosuke singled out drivers as one group he hopes to help, explaining that his time responding to emergency calls highlighted him how often people struggle to handle these situations.
“When I responded to emergency calls and listened to people explain what happened, there were honestly plenty of times when I thought, ‘What is this person talking about?’” he said. “That’s why I want to teach people the correct information.”.
Sukenosuke also aims to stop his viewers from becoming victims of crime as well, using his real-life experience working in “police boxes, patrol cars, and in riot police units” to keep fans more informed.
According to recent reports, “The fundamental purpose of crime prevention is to stop you from becoming a victim in the first place,” mentioned the VTuber. “Even if that next incident does happen, knowing how to respond properly makes it easier for the police to take action, too.”.
Popular VTuber recruited by police to promote new traffic rules.
Japanese Coast Guard uses VTuber to draw in latest recruits.
VTubers can use anime hands in real unboxing videos thanks to genius app.

General
⚖️ Neutral
🌐 Dexerto
#11426. KFC is hosting a fake funeral so GTA 6 fans can take the day off
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (414 w)
KFC is hosting a fake funeral so GTA 6 fans can take the day off
📅 16 Nov 2026 | ⏱️ 2 min read (414 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A KFC in Australia is hosting a funeral for a fake person, just so customers have a valid reason to take the day off work and play GTA 6.
- With November 19 now just days away, the launch of Grand Theft Auto 6 is finally in reach.
- Sources indicate that as a result, plenty of fans have been plotting time off work, just so they don’t have any distractions.
A KFC in Australia is hosting a funeral for a fake person, just so customers have a valid reason to take the day off work and play GTA 6.
With November 19 now just days away, the launch of Grand Theft Auto 6 is finally in reach. In a matter of hours, New Zealand-based players will be among the first to jump into Leonida and experience Jason and Lucia’s story.
Sources indicate that as a result, plenty of fans have been plotting time off work, just so they don’t have any distractions. In the United States, the game is expected to cause $1 billion in disruption to the economy, with around 1.5 million people estimated to be taking the day off.
Not everyone has the time booked off, however, and some have been looking for other reasons to ditch work. Well, in Australia, one KFC is hosting a funeral, aimed at giving customers a legitimate excuse for taking the day off.
The restaurant, which is based in Robina, Queensland, is celebrating the life of ‘Ann Alibi’, and luckily enough, the ‘ceremony’ will start right as GTA 6 goes live.
It has been revealed that “She was always there for us when we needed her. In sickness and in perfect health,” the event invite says. “By remarkable coincidence, her service will take place on the very same day something 13 years in the making finally arrives.”.
KFC also added that “the service will include a hearse, coffin, floral tributes, a book of condolences, an order of service and even a heartfelt eulogy delivered by a surprise guest.”.
A post shared by KFC Australia (@kfcaustralia).
Anyone who does show up for the ceremony will get free fried chicken, but that’ll mean pulling yourself away from the long-awaited game.
There are other opportunities for GTA fans to get rewarded for playing the game. One company is offering to pay someone $100,000 to be their official GTA VI Researcher.
This tech giant wants to pay you over $100,000 to play GTA 6.
Australia’s government explains your rights to take GTA 6 launch day off.
GTA 6 sick days predicted to cost the US $1 billion.
Virgin Media Ireland is offering one lucky fan $900 to play the game for eight hours straight.
If you don’t succeed on either front, then you can take solace in the idea that the game will save you $5,000 should you decide to play it for over 50 days.
🔗 Related Articles
📰 #16554. Industry News: GTA 6 Promo At KFC Is A Fake Funeral So You Can Take The Day Off To Play 📰 #16826. Random: KFC Australia Staging Fake Funeral to Give GTA 6 Fans a 'Legit' Reason to Skip Work 📰 #21054. Tech Report: Off Hours: How Landscape Design Star Cleve West Survives His Day Job
Hardware & Chips
⚖️ Neutral
🌐 Sciencedaily
#11425. MIT’s fresh lidar chip could give self-driving cars a wider view
📅 22 Jul 2026 • ⏱️ 7m • 📚 Deep Dive (1384 w)
MIT’s fresh lidar chip could give self-driving cars a wider view
📅 22 Jul 2026 | ⏱️ 7 min read (1384 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- Lidar technology uses pulses of infrared light to calculate distances and create detailed 3D maps of the surrounding environment.
- It has been revealed that MIT researchers have now developed an approach that could lead to smaller, more durable lidar sensors that operate without any moving parts.
- Sources indicate that existing lidar systems built with silicon-photonics chips usually have a narrow field of view.
Lidar technology uses pulses of infrared light to calculate distances and create detailed 3D maps of the surrounding environment. This allows autonomous vehicles to detect objects in their path and respond quickly. However, conventional lidar sensors are often large and costly, and many rely on moving components that can wear out over time. These limitations make the systems difficult to use in a wider range of settings.
It has been revealed that MIT researchers have now developed an approach that could lead to smaller, more durable lidar sensors that operate without any moving parts. Their advance centers on a new silicon-photonics chip, a type of semiconductor device that controls light instead of electrical signals.
Sources indicate that existing lidar systems built with silicon-photonics chips usually have a narrow field of view. As a result, they struggle to scan areas located toward the edges of a scene. Previous attempts to expand this viewing range have often introduced extra noise and reduced measurement accuracy.
The MIT team addressed those problems by creating an array of integrated antennas that greatly limits unwanted crosstalk, which occurs when neighboring antennas interfere with one another. The design allows the chip to scan across a broader field of view while producing less noise than other silicon-photonics-based methods.
A Smaller Lidar System With a Wider View.
The advance could support the development of more capable lidar sensors for challenging uses, including autonomous vehicle navigation, aerial mapping, and the monitoring of construction sites.
Sources indicate that "The functionality we demonstrated in this work solves a fundamental problem for integrated optical-phased-array technology, enabling future lidar sensors that can achieve significantly higher performance than we could demonstrate previously," says Jelena Notaros, the Robert J. Shillman Career Development Associate Professor of Electrical Engineering and Computer Science (EECS) at MIT, a member of the Research Laboratory of Electronics, and senior author of a paper on this innovation.
Industry observers note that the study also includes lead author and EECS graduate student Henry Crawford-Eng, along with EECS graduate students Andres Garcia Coleto, Benjamin M. Mazur, Daniel M. DeSantis, and Tal Sneh. The findings were published recently in Nature Communications.
How Lidar Maps Its Surroundings.
It has been revealed that many traditional lidar systems use a large rotating unit to direct light pulses across a scene. When the light strikes nearby objects, it reflects back toward the sensor. The returning signals provide the information needed to reconstruct a detailed map of the environment.
Silicon-photonics-based lidar works differently. Rather than rotating a mechanical device, it scans a beam of light electronically in several directions with a system known as an integrated optical phased array (OPA).
According to recent reports, at the heart of an OPA is a group of integrated antennas. Each antenna contains tiny, regularly spaced variations along its length. These features, known as corrugations, cause light from an input source to scatter upward and out of the photonic chip.
Industry observers note that researchers can control the direction of the outgoing beam by changing the phase of the light sent to each antenna. Adjusting these phases changes the angle at which the array releases light, making it possible to steer the beam without moving any physical components.
Recent findings suggest that placing the antennas close together creates a serious obstacle. Neighboring antennas can couple with one another, scrambling the light they produce. Engineers have traditionally prevented this interference by increasing the distance between antennas, but wider spacing creates a different set of problems.
According to recent reports, when antennas are too far apart, the array produces several copies of the same beam at different angles. The primary beam can only be moved a limited distance before it becomes difficult to distinguish from these additional copies.
"This limits our field of view, so the autonomous vehicle now only knows what is in front of it for a certain angular range," Garcia Coleto explains.
In a recent development, the unwanted beam copies, called grating lobes, can confuse the sensor and generate false detections. They also consume energy that could otherwise be directed into the main beam.
To overcome this tradeoff, the MIT researchers developed antennas with reduced crosstalk that can be positioned close together without strongly coupling.
Three Antenna Shapes Reduce Interference.
It has been revealed that in a conventional OPA, every antenna has an identical structure and uses the same pattern of corrugations. When these matching antennas are placed close together, they interact very strongly.
The MIT team instead created a repeating set of three antennas with distinct shapes. They changed the width of the antennas as well as the size and placement of the corrugations. Because the antennas have different geometries, each one also has a different propagation coefficient, which describes how light moves through the structure.
"Because the antennas have very different propagation coefficients, when we put them close together, essentially each antenna doesn't 'see' the antenna next to it. Therefore, it won't couple with its neighbor," Garcia Coleto says.
Making Different Antennas Behave the Same Way.
According to recent reports, reducing the coupling was only part of the challenge. Although the antennas needed different propagation coefficients, they still had to release light in the same consistent manner.
The team designed the antennas around three essential requirements.
Industry observers note that each antenna had to emit the same amount of light. Every antenna also needed to release its beam at the same angle when receiving the same wavelength. Finally, the angle of emission had to change evenly across the entire array as the beam was steered.
Sources indicate that "We have this challenge where we require the antennas to have different geometries to reduce the crosstalk, but we need to simultaneously design the antennas to have the same emission characteristics. While it is possible to engineer this, it is extremely difficult because, typically, when antennas are designed with different geometries, they tend to behave differently," Crawford-Eng states.
The researchers began by developing the basic electromagnetic theory describing how radiative modes couple. They then used this theoretical framework to guide the design and computer simulation of the antennas.
Recent findings suggest that based on those calculations, the team manufactured an OPA containing the reduced-crosstalk antennas. The antennas were placed much closer together than those in a conventional system, and the completed device was then tested experimentally.
Interference Falls From About 100 Percent to 1 Percent.
Industry observers note that under the conditions of the experiment, a typical OPA would have produced coupling of approximately 100 percent. The MIT design lowered that coupling to about 1 percent while still generating one clean and precise beam.
Sources indicate that the system accurately steered the beam across a broad field of view without producing any grating lobes. This combination of wide scanning, low interference, and strong beam quality addresses one of the central obstacles facing integrated lidar technology.
The researchers now plan to refine the method so the system can cover an even broader viewing range. They are also studying another possible approach to wide field-of-view performance that emerged while they were developing the underlying theory.
"This work addresses a longstanding challenge in integrated optical phased arrays: simultaneously achieving both a wide field of view, which requires dense antenna spacing, and high beam quality, which requires low crosstalk between neighboring antennas. The authors solve this problem with an elegant antenna design. Their innovation is an notable step forward for chip-scale, solid-state beam-steering technology," claims Joyce Poon, professor of electrical and computer engineering at the University of Toronto and director of the Max Planck Institute of Microstructure Physics, who was not involved with this work.
It has been revealed that the Semiconductor Research Corporation, the National Science Foundation, an MIT MathWorks Fellowship, the U.S. Department of War, and the MIT Rolf G. Locher Endowed Fellowship supported the research, in part.
Some of the work was carried out using MIT.nano facilities.
Materials provided by Massachusetts Institute of Technology. Original written by Adam Zewe. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Fresh Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #14866. Mauricio Pochettino's Man United SQUAD AUDIT: Axe EIGHT stars, fresh role for the attacker he's 'always liked' and who could be his new Dele Alli... now give YOUR player-by-player verdict 📰 #11517. This fresh chip survives 1300°F (700°C) and could change AI forever 📰 #11466. Industry News: NASA’s fresh AI space chip could let spacecraft think for themselves
General
⚖️ Neutral
🌐 Hugging Face
#11424. Diffusers welcomes FLUX-2
📅 25 Nov 2025 • ⏱️ 14m • 📚 Deep Dive (2863 w)
Diffusers welcomes FLUX-2
📅 25 Nov 2025 | ⏱️ 14 min read (2863 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~14 mins left to finish
📖 0% read
💡 Key Takeaways
- It has been revealed that FLUX.2 is the recent series of image generation models from Black Forest Labs, preceded by the Flux.1 series.
- 🚨 FLUX.2 is not meant to be a drop-in replacement of FLUX.1, but a fresh image generation and editing model.
- FLUX.2 can be used for both image-guided and text-guided image generation.
It has been revealed that FLUX.2 is the recent series of image generation models from Black Forest Labs, preceded by the Flux.1 series. It is an entirely new model with a new architecture and pre-training done from scratch! In this post, we discuss the key changes introduced in FLUX.2, performing inference with it under various setups, and LoRA fine-tuning.
🚨 FLUX.2 is not meant to be a drop-in replacement of FLUX.1, but a fresh image generation and editing model.
FLUX.2 can be used for both image-guided and text-guided image generation. Furthermore, it can take multiple images as reference inputs, while producing the final output image. Below, we briefly discuss the key changes introduced in FLUX.2.
In a recent development, first, instead of two text encoders as in Flux.1, it uses a single text encoder — Mistral Small 3.1. Using a single text encoder greatly simplifies the process of computing prompt embeddings. The pipeline allows for a max_sequence_length of 512. Instead of using a single-layer output for the prompt embedding, FLUX.2 stacks outputs from intermediate layers, which have been known to be more beneficial.
FLUX.2 follows the same general multimodel diffusion transformer (MM-DiT) + parallel DiT architecture as Flux.1. As a refresher, MM-DiT blocks first process the image latents and conditioning text in separate streams, only joining the two together for the attention operation, and are thus referred to as “double-stream” blocks. The parallel blocks then operate on the concatenated image and text streams and can be regarded as “single-stream” blocks.
The key DiT changes from Flux.1 to FLUX.2 are as follows:.
Time and guidance information (in the form of AdaLayerNorm-Zero modulation parameters) is shared across all double-stream and single-stream transformer blocks, respectively, rather than having individual modulation parameters for each block as in Flux.1.
None of the layers in the model use bias parameters. In particular, neither the attention nor feedforward (FF) sub-blocks of either transformer block use bias parameters in any of their layers.
In Flux.1, the single-stream transformer blocks fused the attention output projection with the FF output projection. FLUX.2 single-stream blocks also fuse the attention QKV projections with the FF input projection, creating a fully parallel transformer block:.
Note that compared to the ViT-22B block depicted above, FLUX.2 uses a SwiGLU-style MLP activation rather than a GELU activation (and also doesn’t use bias parameters).
Industry observers note that A larger proportion of the transformer blocks in FLUX.2 are single-stream blocks (8 double-stream blocks to 48 single-stream blocks, compared to 19/38 for Flux.1). This also means that single-stream blocks make up a larger proportion of the DiT parameters: Flux.1[dev]-12B has ~54% of its total parameters in the double-stream blocks, whereas FLUX.2[dev]-32B has ~24% of its parameters in the double-stream blocks (and ~73% in the single-stream blocks).
Recent findings suggest that FLUX.2 uses a larger DiT and Mistral3 Small as its text encoder. When used together without any kind of offloading, the inference takes more than 80GB VRAM. In the following sections, we show how to perform inference with FLUX.2 in more accessible ways, under various system-level constraints.
Before you try out the following code snippets, make sure you have installed diffusers from main and have run hf auth login.
Industry observers note that the above code snippet was tested on an H100, and it isn’t sufficient to run inference on it without CPU offloading. With CPU offloading enabled, this setup takes ~62GB to run.
People who have access to Hopper-series GPUs can take advantage of Flash Attention 3 to speed up inference:.
You can check out the supported attention backends (we have many!) here.
Using bitsandbytes, we can load the transformer and text encoder models in 4-bit, allowing owners of 24GB GPUs to use the model locally. You can run this snippet on a GPU with ~20 GB of free VRAM.
Notice that we're using a repository that contains the NF4-quantized versions of the FLUX.2 DiT and the Mistral text encoder.
Due to the modular design of a Diffusers pipeline, we can isolate modules and work with them in sequence. We decouple the text encoder and deploy it to an Inference Endpoint. This helps us with freeing up the VRAM usage for the DiT and VAE only.
⚠️ To use the remote text encoder, you need to have a valid token. If you are already authenticated, no further action is needed.
It has been revealed that the example below uses a combination of local and remote inference. Additionally, we quantize the DiT with NF4 quantization through bitsandbytes.
You can run this snippet on a GPU with 18 GB of VRAM:.
Sources indicate that for GPUs with even lower VRAM, we have group_offloading, which allows GPUs with as little as 8GB of free VRAM to use this model. However, you'll need 32GB of free RAM. Alternatively, if you're willing to sacrifice some speed, you can set low_cpu_mem_usage=True to reduce the RAM requirement to just 10GB.
You can check out other supported quantization backends here and other memory-saving techniques here.
To check how different quantizations affect an image, you can play with the playground below or access it as standlone in the FLUX.2 Quantization experiments Space.
According to recent reports, FLUX.2 supports using multiple images as inputs, allowing you to use up to 10 images. However, keep in mind that each additional image will require more VRAM. You can reference the images by index (e.g., image 1, image 2) or by natural language (e.g., the kangaroo, the turtle). For optimal results, the best approach is to use a combination of both methods.
It has been revealed that FLUX.2 supports advanced prompting techniques like structured JSON prompting, precise hex color control, and multi-reference image editing. Aside for the added control, this also allows for flexibility in changing specific attributes while maintaining others overall the same.For example, let's start with this json as the base schema (taken from the official FLUX.2 prompting guide):.
Building up on that, let's turn it into a prompt for a shot of a good old fashion walkman on a carpet (simply pass this prompt to your chosen diffusers inference example from above):.
Now, let's change the color of the carpet to a specific teal-blue shade (#367588) and add wired headphones plugged into the walkman:.
The carpet color now matches the hex code provided, and the headphones have been with small changes to the overall scene.
Check out the official prompting guide for more examples and details.
It has been revealed that being both a text-to-image and an image-to-image model, FLUX.2 makes the perfect fine-tuning candidate for many use-cases! However, as inference alone takes more than 80GB of VRAM, LoRA fine-tuning is even more challenging to run on consumer GPUs. To squeeze in as much memory saving as we can, we utilize some of the inference optimizations described above for training as well, together with shared memory saving techniques, to substantially reduce memory consumption. To train it, you can use either the diffusers code below or Ostris' AI Toolkit.
We provide both text-to-image and image-to-image training scripts, for the purpose of this blog will focus on a text-to-image training example.
Sources indicate that many of these techniques complement each other and can be used together to reduce memory consumption further. However, some techniques may be mutually exclusive, so be sure to check before launching a training run.
Please make sure to check out the README for prerequisites before starting training.
It has been revealed that for this example, we’ll use multimodalart/1920-raider-waite-tarot-public-domain dataset with the following configuration using FP8 training. Feel free to experiment more with the hyper-parameters and share your results 🤗.
The left image was generated using the pre-trained FLUX.2 model, and the right image was produced the LoRA.
In case your hardware isn’t compatible with FP8 training, you can use QLoRA with bitsandbytes. You first need to define a config.json file like so:.
And then pass its path to --bnb_quantization_config_path:.
Sources indicate that amazing! great work! 👏is there a support for multi-gpus? (device_map=auto).
You should be able to incorporate that in different forms. Check this out:https://huggingface.co/docs/diffusers/main/en/training/distributed_inference.
Hi, can you tell me a bit about your motivations behind omitting all bias parameters in network architecture? Thanks!
That's a question for the Black Forest Labs team, not us.
Industry observers note that amazing work! Can you tell me when the depth-maps model will be released?Has anyone already tried giving a depth map as a normal image? How does the model behave?
https://github.com/huggingface/blog/blob/main/flux-2.md?plain=1#L283 causes.
Probably an installation error?
pip install git+https://github.com/huggingface/diffusers -U should help you with this.
Hi, How can I deploy a text encoder privately?
Hi, you can read this nice repo with the process that @ariG23498 made.
https://github.com/ayttop/xflux2gpu/blob/main/xxxxxx%20(1).ipynb.
https://huggingface.co/docs/diffusers/main/en/api/parallel.
https://huggingface.co/docs/diffusers/main/en/training/distributed_inference.
import torchfrom transformers import Mistral3ForConditionalGeneration.
from diffusers import Flux2Pipeline, Flux2Transformer2DModel.
repo_id = "diffusers/FLUX.2-dev-bnb-4bit"device = "cuda:0"torch_dtype = torch.bfloat16.
transformer = Flux2Transformer2DModel.from_pretrained( repo_id, subfolder="transformer", torch_dtype=torch_dtype, device_map="cpu")text_encoder = Mistral3ForConditionalGeneration.from_pretrained( repo_id, subfolder="text_encoder", dtype=torch_dtype, device_map="cpu").
pipe = Flux2Pipeline.from_pretrained( repo_id, transformer=transformer, text_encoder=text_encoder, torch_dtype=torch_dtype)pipe.enable_model_cpu_offload().
According to recent reports, prompt = "Realistic macro photograph of a hermit crab using a soda can as its shell, partially emerging from the can, captured with sharp detail and natural colors, on a sunlit beach with soft shadows and a shallow depth of field, with blurred ocean waves in the background. The can has the text BFL Diffusers on it and it has a color gradient that start with #FF5733 at the top and transitions to #33FF57 at the bottom.".
image = pipe( prompt=prompt, generator=torch.Generator(device=device).manual_seed(42), num_inference_steps=50, # 28 is a good trade-off guidance_scale=4,).images[0].
image.save("flux2_t2i_nf4.png").
Flax classes are deprecated and will be removed in Diffusers v1.0.0. We recommend migrating to PyTorch classes or pinning your version of Diffusers.Flax classes are deprecated and will be removed in Diffusers v1.0.0. We recommend migrating to PyTorch classes or pinning your version of Diffusers./usr/local/lib/python3.12/dist-packages/huggingface_hub/utils/_validators.py:206: UserWarning: The local_dir_use_symlinks argument is deprecated and ignored in hf_hub_download. Downloading to a local directory does not use symlinks anymore. warnings.warn(Download complete: 0.00/0.00 [00:00() 22 prompt = "Realistic macro photograph of a hermit crab using a soda can as its shell, partially emerging from the can, captured with sharp detail and natural colors, on a sunlit beach with soft shadows and a shallow depth of field, with blurred ocean waves in the background. The can has the text BFL Diffusers on it and it has a color gradient that start with #FF5733 at the top and transitions to #33FF57 at the bottom." 23---> 24 image = pipe( 25 prompt=prompt, 26 generator=torch.Generator(device=device).manual_seed(42),.
36 frames/usr/local/lib/python3.12/dist-packages/torch/utils/_contextlib.py in decorate_context(*args, **kwargs) 122 # pyrefly: ignore [bad-context-manager] 123 with ctx_factory():--> 124 return func(*args, **kwargs) 125 126 return decorate_context.
/usr/local/lib/python3.12/dist-packages/diffusers/pipelines/flux2/pipeline_flux2.py in call(self, image, prompt, height, width, num_inference_steps, sigmas, guidance_scale, num_images_per_prompt, generator, latents, prompt_embeds, output_type, return_dict, attention_kwargs, callback_on_step_end, callback_on_step_end_tensor_inputs, max_sequence_length, text_encoder_out_layers, caption_upsample_temperature) 869 prompt, images=image, temperature=caption_upsample_temperature, device=device 870 )--> 871 prompt_embeds, text_ids = self.encode_prompt( 872 prompt=prompt, 873 prompt_embeds=prompt_embeds,.
/usr/local/lib/python3.12/dist-packages/diffusers/pipelines/flux2/pipeline_flux2.py in encode_prompt(self, prompt, device, num_images_per_prompt, prompt_embeds, max_sequence_length, text_encoder_out_layers) 586 587 if prompt_embeds is None:--> 588 prompt_embeds = self._get_mistral_3_small_prompt_embeds( 589 text_encoder=self.text_encoder, 590 tokenizer=self.tokenizer,.
/usr/local/lib/python3.12/dist-packages/diffusers/pipelines/flux2/pipeline_flux2.py in _get_mistral_3_small_prompt_embeds(text_encoder, tokenizer, prompt, dtype, device, max_sequence_length, system_message, hidden_states_layers) 337 338 # Forward pass through the model--> 339 output = text_encoder( 340 input_ids=input_ids, 341 attention_mask=attention_mask,.
/usr/local/lib/python3.12/dist-packages/torch/nn/modules/module.py in _wrapped_call_impl(self, *args, **kwargs) 1774 return self._compiled_call_impl(*args, **kwargs) # type: ignore[misc] 1775 else:-> 1776 return self._call_impl(*args, **kwargs) 1777 1778 # torchrec tests the code consistency with the following code.
/usr/local/lib/python3.12/dist-packages/torch/nn/modules/module.py in _call_impl(self, *args, **kwargs) 1785 or _global_backward_pre_hooks or _global_backward_hooks 1786 or _global_forward_hooks or _global_forward_pre_hooks):-> 1787 return forward_call(*args, **kwargs) 1788 1789 result = None.
/usr/local/lib/python3.12/dist-packages/accelerate/hooks.py in new_forward(module, *args, **kwargs) 190 output = module._old_forward(*args, **kwargs) 191 else:--> 192 output = module._old_forward(*args, **kwargs) 193 return module._hf_hook.post_forward(module, output) 194.
/usr/local/lib/python3.12/dist-packages/transformers/utils/generic.py in wrapper(self, *args, **kwargs) 1000 outputs = func(self, *args, **kwargs) 1001 else:-> 1002 outputs = func(self, *args, **kwargs) 1003 except TypeError as original_exception: 1004 # If we get a TypeError, it's possible that the model is not receiving the recordable kwargs correctly.
/usr/local/lib/python3.12/dist-packages/transformers/models/mistral3/modeling_mistral3.py in forward(self, input_ids, pixel_values, attention_mask, position_ids, past_key_values, inputs_embeds, labels, use_cache, output_attentions, output_hidden_states, return_dict, cache_position, logits_to_keep, image_sizes, **kwargs) 444 return_dict = return_dict if return_dict is not None else self.config.use_return_dict 445--> 446 outputs = self.model( 447 input_ids=input_ids, 448 pixel_values=pixel_values,.
/usr/local/lib/python3.12/dist-packages/torch/nn/modules/module.py in _wrapped_call_impl(self, *args, **kwargs) 1774 return self._compiled_call_impl(*args, **kwargs) # type: ignore[misc] 1775 else:-> 1776 return self._call_impl(*args, **kwargs) 1777 1778 # torchrec tests the code consistency with the following code.
/usr/local/lib/python3.12/dist-packages/torch/nn/modules/module.py in _call_impl(self, *args, **kwargs) 1785 or _global_backward_pre_hooks or _global_backward_hooks 1786 or _global_forward_hooks or _global_forward_pre_hooks):-> 1787 return forward_call(*args, **kwargs) 1788 1789 result = None.
/usr/local/lib/python3.12/dist-packages/transformers/utils/generic.py in wrapper(self, *args, **kwargs) 1000 outputs = func(self, *args, **kwargs) 1001 else:-> 1002 outputs = func(self, *args, **kwargs) 1003 except TypeError as original_exception: 1004 # If we get a TypeError, it's possible that the model is not receiving the recordable kwargs correctly.
/usr/local/lib/python3.12/dist-packages/transformers/models/mistral3/modeling_mistral3.py in forward(self, input_ids, pixel_values, attention_mask, position_ids, past_key_values, inputs_embeds, vision_feature_layer, use_cache, output_attentions, output_hidden_states, return_dict, cache_position, image_sizes, **kwargs) 323 inputs_embeds = inputs_embeds.masked_scatter(special_image_mask, image_features) 324--> 325 outputs = self.language_model( 326 attention_mask=attention_mask, 327 position_ids=position_ids,.
/usr/local/lib/python3.12/dist-packages/torch/nn/modules/module.py in _wrapped_call_impl(self, *args, **kwargs) 1774 return self._compiled_call_impl(*args, **kwargs) # type: ignore[misc] 1775 else:-> 1776 return self._call_impl(*args, **kwargs) 1777 1778 # torchrec tests the code consistency with the following code.
/usr/local/lib/python3.12/dist-packages/torch/nn/modules/module.py in _call_impl(self, *args, **kwargs) 1785 or _global_backward_pre_hooks or _global_backward_hooks 1786 or _global_forward_hooks or _global_forward_pre_hooks):-> 1787 return forward_call(*args, **kwargs) 1788 1789 result = None.
/usr/local/lib/python3.12/dist-packages/transformers/utils/generic.py in wrapper(self, *args, **kwargs) 1000 outputs = func(self, *args, **kwargs) 1001 else:-> 1002 outputs = func(self, *args, **kwargs) 1003 except TypeError as original_exception: 1004 # If we get a TypeError, it's possible that the model is not receiving the recordable kwargs correctly.
/usr/local/lib/python3.12/dist-packages/transformers/models/mistral/modeling_mistral.py in forward(self, input_ids, attention_mask, position_ids, past_key_values, inputs_embeds, use_cache, cache_position, **kwargs) 395 396 for decoder_layer in self.layers[: self.config.num_hidden_layers]:--> 397 hidden_states = decoder_layer( 398 hidden_states, 399 attention_mask=causal_mask,.
/usr/local/lib/python3.12/dist-packages/transformers/modeling_layers.py in call(self, *args, **kwargs) 91 92 return self._gradient_checkpointing_func(partial(super().call, **kwargs), *args)---> 93 return super().call(*args, **kwargs) 94 95.
/usr/local/lib/python3.12/dist-packages/torch/nn/modules/module.py in _wrapped_call_impl(self, *args, **kwargs) 1774 return self._compiled_call_impl(*args, **kwargs) # type: ignore[misc] 1775 else:-> 1776 return self._call_impl(*args, **kwargs) 1777 1778 # torchrec tests the code consistency with the following code.
/usr/local/lib/python3.12/dist-packages/torch/nn/modules/module.py in _call_impl(self, *args, **kwargs) 1785 or _global_backward_pre_hooks or _global_backward_hooks 1786 or _global_forward_hooks or _global_forward_pre_hooks):-> 1787 return forward_call(*args, **kwargs) 1788 1789 result = None.
/usr/local/lib/python3.12/dist-packages/transformers/utils/generic.py in wrapped_forward(*args, **kwargs) 953 if key == "hidden_states" and len(collected_outputs[key]) == 0: 954 collected_outputs[key] += (args[0],)--> 955 output = orig_forward(*args, **kwargs) 956 if not isinstance(output, tuple): 957 collected_outputs[key] += (output,).
/usr/local/lib/python3.12/dist-packages/transformers/models/mistral/modeling_mistral.py in forward(self, hidden_states, attention_mask, position_ids, past_key_values, use_cache, cache_position, position_embeddings, **kwargs) 228 hidden_states = self.input_layernorm(hidden_states) 229 # Self Attention--> 230 hidden_states, _ = self.self_attn( 231 hidden_states=hidden_states, 232 attention_mask=attention_mask,.
/usr/local/lib/python3.12/dist-packages/torch/nn/modules/module.py in _wrapped_call_impl(self, *args, **kwargs) 1774 return self._compiled_call_impl(*args, **kwargs) # type: ignore[misc] 1775 else:-> 1776 return self._call_impl(*args, **kwargs) 1777 1778 # torchrec tests the code consistency with the following code.
/usr/local/lib/python3.12/dist-packages/torch/nn/modules/module.py in _call_impl(self, *args, **kwargs) 1785 or _global_backward_pre_hooks or _global_backward_hooks 1786 or _global_forward_hooks or _global_forward_pre_hooks):-> 1787 return forward_call(*args, **kwargs) 1788 1789 result = None.
/usr/local/lib/python3.12/dist-packages/transformers/models/mistral/modeling_mistral.py in forward(self, hidden_states, position_embeddings, attention_mask, past_key_values, cache_position, **kwargs) 151 hidden_shape = (*input_shape, -1, self.head_dim) 152--> 153 query_states = self.q_proj(hidden_states).view(hidden_shape).transpose(1, 2) 154 key_states = self.k_proj(hidden_states).view(hidden_shape).transpose(1, 2) 155 value_states = self.v_proj(hidden_states).view(hidden_shape).transpose(1, 2).
/usr/local/lib/python3.12/dist-packages/torch/nn/modules/module.py in _wrapped_call_impl(self, *args, **kwargs) 1774 return self._compiled_call_impl(*args, **kwargs) # type: ignore[misc] 1775 else:-> 1776 return self._call_impl(*args, **kwargs) 1777 1778 # torchrec tests the code consistency with the following code.
/usr/local/lib/python3.12/dist-packages/torch/nn/modules/module.py in _call_impl(self, *args, **kwargs) 1785 or _global_backward_pre_hooks or _global_backward_hooks 1786 or _global_forward_hooks or _global_forward_pre_hooks):-> 1787 return forward_call(*args, **kwargs) 1788 1789 result = None.
/usr/local/lib/python3.12/dist-packages/bitsandbytes/nn/modules.py in forward(self, x) 554 weight = self.weight if getattr(quant_state, "packing_format_for_cpu", False) else self.weight.t() 555--> 556 return bnb.matmul_4bit(x, weight, bias=bias, quant_state=quant_state).to(inp_dtype) 557 558.
/usr/local/lib/python3.12/dist-packages/bitsandbytes/autograd/_functions.py in matmul_4bit(A, B, quant_state, out, bias) 399 return out 400 else:--> 401 return MatMul4Bit.apply(A, B, out, bias, quant_state).
/usr/local/lib/python3.12/dist-packages/torch/autograd/function.py in apply(cls, *args, **kwargs) 581 # See NOTE: [functorch vjp and autograd interaction] 582 args = _functorch.utils.unwrap_dead_wrappers(args)--> 583 return super().apply(*args, **kwargs) # type: ignore[misc] 584 585 if not is_setup_ctx_defined:.
Sources indicate that /usr/local/lib/python3.12/dist-packages/bitsandbytes/autograd/_functions.py in forward(ctx, A, B, out, bias, quant_state) 313 # 1. Dequantize 314 # 2. MatmulnN--> 315 output = torch.nn.functional.linear(A, F.dequantize_4bit(B, quant_state).to(A.dtype).t(), bias) 316 317 # 3. Save state.
/usr/local/lib/python3.12/dist-packages/bitsandbytes/functional.py in dequantize_4bit(A, quant_state, absmax, out, blocksize, quant_type) 1048 ) 1049 else:-> 1050 out = torch.ops.bitsandbytes.dequantize_4bit.default( 1051 A, 1052 absmax,.
/usr/local/lib/python3.12/dist-packages/torch/_ops.py in call(self, *args, **kwargs) 817 # that are named "self". This way, all the aten ops can be called by kwargs. 818 def call(self, /, *args: _P.args, **kwargs: _P.kwargs) -> _T:--> 819 return self._op(*args, **kwargs) 820 821 # Use positional-only argument to avoid naming collision with aten ops arguments.
/usr/local/lib/python3.12/dist-packages/torch/_compile.py in inner(*args, **kwargs) 52 fn.__dynamo_disable = disable_fn # type: ignore[attr-defined] 53---> 54 return disable_fn(*args, **kwargs) 55 56 return inner.
/usr/local/lib/python3.12/dist-packages/torch/_dynamo/eval_frame.py in _fn(*args, **kwargs) 1179 ): 1180 return fn(*args, **kwargs)-> 1181 return fn(*args, **kwargs) 1182 finally: 1183 set_eval_frame(None).
/usr/local/lib/python3.12/dist-packages/torch/library.py in func_no_dynamo(*args, **kwargs) 740 @torch ._disable_dynamo 741 def func_no_dynamo(*args, **kwargs):--> 742 return func(*args, **kwargs) 743 744 for key in keys:.
/usr/local/lib/python3.12/dist-packages/bitsandbytes/backends/cuda/ops.py in _(A, absmax, blocksize, quant_type, shape, dtype) 361 dtype: torch.dtype, 362 ) -> torch.Tensor:--> 363 out = torch.empty(shape, dtype=dtype, device=A.device) 364 _dequantize_4bit_impl(A, absmax, blocksize, quant_type, dtype, out=out) 365 return out.
In a recent development, outOfMemoryError: CUDA out of memory. Tried to allocate 40.00 MiB. GPU 0 has a total capacity of 14.56 GiB of which 17.81 MiB is free. Including non-PyTorch memory, this process has 14.54 GiB memory in use. Of the allocated memory 14.40 GiB is allocated by PyTorch, and 15.19 MiB is reserved by PyTorch but unallocated. If reserved but unallocated memory is large try setting PYTORCH_ALLOC_CONF=expandable_segments:True to avoid fragmentation. See documentation for Memory Management (https://pytorch.org/docs/stable/notes/cuda.html#environment-variables).
https://github.com/huggingface/diffusers/blob/main/docs/source/en/using-diffusers/loading.md.
General
⚖️ Neutral
🌐 Sitepoint
#11423. How to Reduce Hallucinations in LLMs
📅 09 Nov 2026 • ⏱️ 12m • 📚 Deep Dive (2321 w)
How to Reduce Hallucinations in LLMs
📅 09 Nov 2026 | ⏱️ 12 min read (2321 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~12 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- Industry observers note that 7 Day Free Trial.
- Ask one of the newest language models whether a backpack comes in green, and it'll usually admit it doesn't know.
Stay up to date with AI tools, model releases, and developer workflows that matter.
It has been revealed that weekly. Free. One click to leave.
Industry observers note that 7 Day Free Trial. Cancel Anytime.
Ask one of the newest language models whether a backpack comes in green, and it'll usually admit it doesn't know. Ask it how to return that backpack, and it may send the customer to a returns page, an account screen, and a return label that the store has never had. That's still a hallucination: an answer that sounds right, comes with total confidence, and isn't true.
Whatever you're building, the fix is the same: stop trusting the model with the parts it can get wrong, and check its work before anyone sees it.
According to recent reports, in this tutorial we'll build a small support bot for a made-up outdoor gear store, three times over. The first version is the prompt plenty of bots start with. Then we'll apply five fixes, run six tricky customer emails through every version, and finish with a bot where the model can't slip a made-up price, date, or product past the code.
In a recent development, an LLM hallucination is output that's fluent and confident but not backed by the facts: a product that doesn't exist, a policy nobody wrote, a date that's a week out, or a citation to a paper that was never published. The word covers two different failures:.
Each one needs a different fix, so it helps to keep them apart.
According to recent reports, A language model writes by predicting likely text, one token at a time. It has no separate store of facts it checks against, and nothing in that process says "stop, you don't know this". Training adds to the problem. OpenAI's research on why language models hallucinate points out that when models are graded only on how many answers they get right, a guess scores better than "I don't know", so they learn to guess.
A few things make it worse in your app:.
According to recent reports, newer models are much better at the first one. They'll often say they don't know a price rather than invent one. But they still fill gaps with what's typical, and what's typical isn't always what's true for your business. You can't train that out of a model you call through an API. What you can change is what you ask it to do, what you give it, and what you check.
According to recent reports, A made-up answer costs more than one bad reply. Some of the costs are already on the record:.
In a support inbox, the cost is quieter but adds up: a refund you didn't owe, or a customer who goes looking for a live chat button that isn't there and doesn't come back.
Northwind Outdoor sells four things: two packs, a rain cover, and a tent. It has two orders on file and three short policies. Here's all of it:.
Six emails come in, and each one is there to trip the bot in a different way:.
Recent findings suggest that the traps: the 40L pack doesn't come in green, but the 28L does. The 40L is water-resistant, not waterproof. There's no 60L. Whether the return is allowed depends on a membership, a sale price, and a count of days since delivery. The tracking details are in one order record. And the store has no price match policy at all.
Make a folder, add "type": "module" to its package.json, and install the Anthropic SDK and Zod:.
Every version calls the model through one small helper:.
We're using Claude Opus 5.5 at low effort. These are short, simple replies, so the model doesn't need to think for long. Swap in any model you like, because none of the fixes depend on it.
According to recent reports, opus 5.5 didn't invent a single price, colour, or delivery date across the six emails. Every reply said it couldn't see the store's details. That's real progress compared with older models, but look at what it said instead. Here's the reply to the email about a pack the store doesn't sell:.
Industry observers note that it treats the Ridgeline 60L as real and offers to help pick a fit. The other replies made up the store around the customer:.
Sources indicate that northwind has none of those. None of it is a wild guess: it's what a typical online store has. That's exactly why it's dangerous. A customer who goes looking for the live chat or the newsletter discount won't find it, and the bot never answered the question anyway.
It has been revealed that the model can't know Northwind's prices, so give them to it. This is the idea behind retrieval-augmented generation (RAG): find the records that matter and put them in the prompt. Our store is small enough to send all of it.
Two things changed. The store data goes in the system prompt, wrapped in tags so the model can tell data from instructions. And the prompt tells it to answer only from that data. Here's the green pack email again:.
Right on all three counts, and it even pointed to the pack that does come in green. The return, which needs four facts from two places, came back right as well:.
Delivered October 6, a Trail Club member, so 60 days, so December 5. Bought on sale, so store credit for what was paid, not the list price. Version 2 got all six emails right.
The last line of that prompt matters as much as the data: "If the answer isn't in the data, say you don't know and that a team member will reply by email." Without it, a model that can't find the answer has to choose between letting the customer down and guessing, and training has taught it to guess. With it, "I don't know" is a right answer, not a failure.
The price match email is the test, since the store data notes nothing about price matching:.
It remarked it didn't know, passed the question to a person, and answered the parts it could from the data.
In a recent development, if version 2 got everything right, why build a version 3? Because "right on this run" isn't the same as "right every time":.
The next three fixes take the facts and the rules away from the model completely.
Version 3 splits the work into three steps. First, the model reads the email, but instead of writing a reply, it fills in a form. Every field is a choice from a list, a yes or no, or text copied from the email:.
According to recent reports, zod describes the form, and z.toJSONSchema() turns it into a JSON schema for the API's structured outputs. The API holds the model to that schema, so product can only be one of our four product IDs, not_sold, or none. There's no way for it to answer ridgeline-60. Zod then checks the answer again, so the rest of the code gets a typed object. SitePoint's guide to LLM structured output with JSON Schema goes deeper on this pattern.
Here's what it read from the 60L email:.
The model is still reading natural language, which it's very good at. It just isn't trusted to know what the store sells anymore.
Recent findings suggest that A form also makes the model's mistakes easy to see. The first time I ran this, the form had no asks_something_else field, and the model filed the price match email under product. The reply didn't make anything up, but the email never reached a person. In version 2, a mistake like that would be hidden inside a paragraph. Here it was one wrong value in a JSON object, and the fix was one more field.
According to recent reports, if all you need from this step is decisions like these, a model built for typed answers can do it faster and for less. Our typed AI pipeline tutorial builds the same kind of email sorter with Jev and Clairic.
Second step: plain code takes the form, looks up the product and the order, applies the rules, and does the maths. What comes out is a list of facts in plain sentences:.
For the return email, that gives:.
Recent findings suggest that every number in there was worked out by code that does the same thing every time, and that you can unit test. The 34 days, the December 5 deadline, and the $151.20 in store credit come out the same on every run, whatever the model does.
It has been revealed that the last rule in decide() matters most. If an email asks something the rules don't cover, the facts say so and the email goes to a person. Code decides when to say "I don't know", not the model.
Third step: the model writes the reply from the facts and nothing else. Writing is the one job here it does better than code.
It has been revealed that even with the right facts, a model writing a reply can still add something: a helpful "ships in 1–2 business days", or a price it remembers from somewhere. So the last step checks the reply. Anything that looks like a number, an order number, or a product name has to appear in the email or the facts:.
According to recent reports, it's simple on purpose. It doesn't understand the reply. It just refuses to let through a value that came from nowhere, and that covers the hallucinations that cost money: prices, dates, quantities, and products. Nothing in the reply can talk it out of a result.
The writer runs the check on every draft:.
If a draft fails, the model gets one retry and is told exactly which values weren't in the facts. If the retry fails too, the customer gets the facts as a plain list. That's less charming, but it's true.
According to recent reports, A check like this will raise false alarms, and that's fine. On my first run, it read a line about the tent's 2.1 kg weight as a product called "Weighs 2" and sent the draft back for a retry. The weight was right, and it was the only thing flagged. A false alarm costs a few seconds. A missed one costs a customer. I tightened the patterns (the version above has the fix), but I'd still rather it flag too much than too little.
It's the same thing that separates the better agentic AI coding tools from autocomplete: they run the tests and read the errors instead of trusting their first draft. Model output isn't finished until something other than the model has checked it.
This script sends each email through all three versions, saves every reply, and runs the check from Fix 5 over all of them. Versions 1 and 2 are checked against everything the store knows:.
According to recent reports, the check caught one thing in version 1: the "1–2 business days" it made up for processing an order. It missed the "up to 24 hours" for tracking in the same reply, but only because $24 is the rain cover's price, so 24 counted as a known number. And it couldn't catch the invented returns page or live chat at all, because they aren't numbers. That's why the check is the last fix, not the only one.
Reading all 18 replies, here's how each version did:.
In a recent development, version 3 was less helpful than version 2 in one place. It couldn't give the rain cover's price, because decide() only adds facts about the product the email names. Version 2 had the whole store to look at. In version 3, the fix is a rule you write once: when a product has an add-on, include the add-on's facts too.
Here's version 3's reply to the price match email:.
According to recent reports, no model is free of hallucinations, so you can't stop one from ever making something up. What you can do is build so a made-up detail can't reach a customer: let code own the facts, and check the model's output against them before it's used. Where it matters, send anything your rules don't cover to a person.
It cuts them a lot, because the model no longer has to guess facts it was never given. In our test, putting the store's data in the prompt took the bot from no useful answers to six right ones. It doesn't stop the model misreading what it retrieved, mixing up two records, or filling a gap the retrieved text leaves. Pair it with a way out and a check on the output.
Not really. Temperature controls how random the wording is. A low temperature makes the model give the same answer more often, including the same wrong answer.
Collect inputs that have tripped your app (or are likely to), write down the right answer for each, and run every version of your prompt or pipeline over the same set. Automated checks like the one in this tutorial catch made-up values. Read the replies yourself for the rest, because the made-up returns page above would pass any number check.
It has been revealed that hallucinations come from asking a model to do jobs it isn't built for: knowing facts it was never given, and running small programs in its head. The five fixes take those jobs away:.
It has been revealed that the model still does what it's best at: reading messy text and writing a friendly reply. It just isn't trusted with the facts anymore. From here, try a seventh email that asks two things at once, add the add-on rule to decide(), or extend the check to catch colours and sizes as well as numbers.
Recent findings suggest that 7 Day Free Trial. Cancel Anytime.

General
⚖️ Neutral
🌐 Dexerto
#11422. Taco Bell’s debuts newly introduced Baja Blast alongside Naked Chicken Chalupa return
📅 16 Nov 2026 • ⏱️ 1m • 📖 Standard (254 w)
Taco Bell’s debuts newly introduced Baja Blast alongside Naked Chicken Chalupa return
📅 16 Nov 2026 | ⏱️ 1 min read (254 words, 📖 Standard) | Source: Dexerto
⏱️ ~1 mins left to finish
📖 0% read
💡 Key Takeaways
- Taco Bell is expanding its drink lineup with a new zero-sugar Mountain Dew flavor while preparing to bring back one of its most recognizable menu items.
- The fast food chain officially launched Mountain Dew Baja Midnight Zero Sugar nationwide on November 12, offering customers a upcoming version of its passionfruit-flavored fountain drink.
- The release comes alongside intends to bring the Naked Chicken Chalupa back to restaurants across the US.
Taco Bell is expanding its drink lineup with a new zero-sugar Mountain Dew flavor while preparing to bring back one of its most recognizable menu items.
The fast food chain officially launched Mountain Dew Baja Midnight Zero Sugar nationwide on November 12, offering customers a upcoming version of its passionfruit-flavored fountain drink.
The release comes alongside intends to bring the Naked Chicken Chalupa back to restaurants across the US.
The returning Chalupa, which replaces a traditional shell with crispy chicken, has appeared on Taco Bell’s menu several times since its 2017 debut, including on the chain’s 2016 Decades menu in August 2026.
Mountain Dew Baja Midnight Zero Sugar features the same passionfruit-forward flavor as the original Baja Midnight, but without sugar or calories.
The latest beverage is available nationwide in three sizes, with a small priced at $2.59, a medium at $2.79, and a large at $2.99.
Meanwhile, the Naked Chicken Chalupa is preparing for another nationwide release, bringing back its signature shell made entirely from crispy, all-white-meat chicken marinated in Mexican-inspired spices.
Rather than using a traditional fried flatbread shell, the chicken itself holds the Chalupa’s fillings, which include shredded lettuce, diced tomatoes, cheddar cheese, and creamy Avocado Ranch Sauce.
The returning menu item will be priced at $5.99, although Taco Bell has not provided a specific nationwide release date in the announcement.
Both additions continue Taco Bell’s ongoing menu updates, with Baja Midnight Zero Sugar already available at participating restaurants and the Naked Chicken Chalupa expected to follow.
🔗 Related Articles
📰 #17328. Breaking: Infinity Nikki 2.0 debuts with a whole newly introduced region, archery skills, and a new theme song by original Wicked actor Idina Menzel 📰 #17255. Tech Report: FC 26 adds upgraded Pina alongside 3 newly introduced Heroes in full Winter Wildcards promo 📰 #23497. Tech Report: A Newly introduced Framework for Evaluating Voice Agents (EVA)
General
⚖️ Neutral
🌐 Sciencedaily
#11421. Industry News: World’s first superconducting quantum heat engine could help unlock massive quantum computers
📅 14 Aug 2026 • ⏱️ 4m • 📚 Deep Dive (829 w)
Industry News: World’s first superconducting quantum heat engine could help unlock massive quantum computers
📅 14 Aug 2026 | ⏱️ 4 min read (829 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- A newly developed superconducting quantum heat engine could deepen our understanding of thermodynamics while helping advance technologies needed for quantum computers with very large numbers of qubits.
- Scientists are getting a clearer picture of how thermodynamics behaves in the quantum world, and that progress could benefit both quantum technology and our understanding of familiar thermodynamic principles.
- Sources indicate that the experiment connects two areas of physics that normally describe very different scales.
A newly developed superconducting quantum heat engine could deepen our understanding of thermodynamics while helping advance technologies needed for quantum computers with very large numbers of qubits.
Scientists are getting a clearer picture of how thermodynamics behaves in the quantum world, and that progress could benefit both quantum technology and our understanding of familiar thermodynamic principles. Researchers at Aalto University have now taken an important step by demonstrating the first cyclic quantum heat engine built inside a superconducting circuit.
Sources indicate that the experiment connects two areas of physics that normally describe very different scales. Quantum mechanics explains the behavior of matter at extremely small scales, even below the size of atoms, while thermodynamics describes how heat and energy behave in much larger systems, from collections of molecules to the universe itself. Bringing the two together raises a fundamental question: what happens to familiar thermodynamic processes when quantum effects such as tunneling, entanglement, and superposition enter the picture?
A Heat Engine Built for the Quantum World.
Conventional heat engines turn heat into useful work. James Watt's steam engine is one famous example, but the same basic concept remains central to modern transportation and electricity production, powering cars, ships, planes and many power plants.
Recent findings suggest that the researchers have now created the world's first superconducting quantum heat engine. The extremely small device combines a transmon qubit, a resonator and a quantum refrigerator.
Operating under ultracold quantum conditions, the engine was able to use the tiny amount of available heat to repeatedly produce positive work. Achieving this kind of cyclic operation has been an key objective for researchers working on quantum heat engines. The result provides a proof of concept for superconducting heat engines that could eventually contribute to improved quantum computing technology.
The study, led by Academy Professor Mikko Möttönen, was published in Nature Communications.
Recreating an Otto Cycle Near Absolute Zero.
In a recent development, to make the engine operate, the researchers reproduced an Otto cycle inside a superconducting circuit. The Otto cycle is a thermodynamic process also used in car engines and other conventional machines.
"In our experiment, we built a nanofabricated heat engine using superconducting circuits and operated it in a cryostat near absolute zero. At its heart is a transmon qubit, one of the basic building blocks of modern quantum technologies," claims Tuomas Uusnäkki, the study's first author.
Recent findings suggest that the researchers connected the transmon qubit to a quantum circuit refrigerator, allowing them to control heat flow on the quantum scale and demonstrate that this heat could be transformed into measurable work. A conventional heat engine normally relies on separate hot and cold environments. In this system, however, the same quantum refrigerator can supply both heating and cooling.
It has been revealed that "Our quantum-circuit refrigerator can be tuned to both heat and cool the qubit on demand. Using carefully timed control pulses, we drove the engine in an Otto cycle and monitored the qubit state as the engine ran," explains Uusnäkki.
Measurements showed that heat passing through the qubit during the cycle was producing positive work.
"This is the first experimental demonstration of a cyclic quantum heat engine in superconducting circuits. Using a single controllable quantum refrigerator as both the hot and cold environment of the engine makes it simpler and more versatile," states Uusnäkki.
Toward Autonomous Quantum Computer Hardware.
Recent findings suggest that the researchers are now trying to improve the design and eventually develop a fully autonomous heat engine. One possible use would be reading out qubits without having to carry a microwave pulse from millikelvin temperatures all the way to room temperature.
It has been revealed that that capability could become especially valuable as quantum computers grow. Autonomous devices integrated directly into superconducting circuits could reduce both the cost and complexity of machines containing very large numbers of qubits.
"Finland's Quantum Technology Strategy envisions a quantum computer with one thousand logical qubits by 2035, which probably means hundreds of thousands of physical qubits. Doing that with current technology requires millions of microwave cables costing thousand euros each. The cables also introduce noise into the system. Using autonomous devices instead would mostly eliminate the need for those cables," Möttönen states.
Reducing the need for those microwave connections could therefore address two challenges at once: the enormous hardware requirements of large quantum computers and the unwanted noise that cables can introduce into quantum systems.
The pioneering experiment was carried out using OtaNano, Finland's national research infrastructure for nano, micro and quantum technology. Funding came from the Research Council of Finland and the Finnish Cultural Foundation.
Materials provided by Aalto University. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.

AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11420. Transformers v5: Simple model definitions powering the AI ecosystem
📅 01 Dec 2025 • ⏱️ 10m • 📚 Deep Dive (2029 w)
Transformers v5: Simple model definitions powering the AI ecosystem
📅 01 Dec 2025 | ⏱️ 10 min read (2029 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~10 mins left to finish
📖 0% read
💡 Key Takeaways
- In a recent development, transformers' version v4.0.0rc-1, the initial release candidate for version 4, was released on November 19th, 2020.
- According to recent reports, today, as we launch v5, Transformers is installed more than 3 million times each day via pip - up from 20,000/day in v4 🤯.
- The ecosystem has expanded from 40 model architectures in v4 to over 400 today, and the community has contributed more than 750,000 model checkpoints on the Hub compatible with Transformers, up from roughly 1,000 at the time of v4.
In a recent development, transformers' version v4.0.0rc-1, the initial release candidate for version 4, was released on November 19th, 2020. Five years later, we now release v5.0.0rc-0.
According to recent reports, today, as we launch v5, Transformers is installed more than 3 million times each day via pip - up from 20,000/day in v4 🤯. Altogether, it has now surpassed 1.2 billion installs!
The ecosystem has expanded from 40 model architectures in v4 to over 400 today, and the community has contributed more than 750,000 model checkpoints on the Hub compatible with Transformers, up from roughly 1,000 at the time of v4.
It has been revealed that this growth is powered by the evolution of the field and the now mainstream access to AI. As a leading model-definition library in the ecosystem, we need to continuously evolve and adapt the library to continue being relevant. Reinvention is key for longevity in AI.
We’re fortunate to collaborate with many libraries and apps built on transformers, in no specific order: llama.cpp, MLX, onnxruntime, Jan, LMStudio, vLLM, SGLang, Unsloth, LlamaFactory, dLLM, MaxText, TensorRT, Argmax, among many other friends.
Recent findings suggest that for v5, we wanted to work on several notable aspects: simplicity, training, inference, and production. We detail the work that went into them in this post.
Industry observers note that the first focus of the team was on simplicity. Working on transformers, we see the code as the product. We want our model integrations to be clean, so that the ecosystem may depend on our model definitions and understand what’s really happening under the hood, how models differ from each other, and the key features of each fresh model. Simplicity results in wider standardization, generality, and wider support.
Transformers is the backbone of hundreds of thousands of projects, Unsloth included. We build on Transformers to help people fine-tune and train models efficiently, whether that’s BERT, text-to-speech (TTS), or others; to run fast inference for reinforcement learning (RL) even when models aren’t yet supported in other libraries. We're excited for Transformers v5 and are super happy to be working with the Hugging Face team!
Transformers, at the core, remains a model architecture toolkit. We aim to have all recent architectures and to be the “source of truth” for model definitions. We’ve been adding between 1 - 3 fresh models every week for 5 years, shown in the timeline below:.
We’ve worked on improving that model-addition process.
Over the past year, we’ve heavily pushed our modular design as a significant step forward. This allows for easier maintenance, faster integration, and better collaboration across the community.
Recent findings suggest that we give a deeper overview in our Maintain the Unmaintainable blog post. For brevity, we aim to achieve a much easier model contribution process, as well as a lower maintenance burden. One metric we can highlight is that the number of lines of code to contribute (and review), drop significantly when modular is used:.
Recent findings suggest that while we respect the “One model, one file” philosophy, we continue introducing some abstractions making the management of common helpers simpler. The prime example of this is the introduction of the AttentionInterface, which offers a centralized abstraction for attention methods. The eager method will remain in the modeling file; others, such as FA1/2/3, FlexAttention, or SDPA, are moved to the interface.
Over the past couple of years, the increasing amount of 0-day support for newly introduced model architectures and standardization of attention handling has helped to simplify our support for post-training modern LLMs.
Sources indicate that we’re building tooling to help us identify which existing model architecture a latest model resembles. This feature uses machine learning to find code similarities between independent modeling files. Going further, we aim to automate the conversion process by opening a draft PR for the model to be integrated into our transformers format. This process reduces manual effort and ensures consistency.
Industry observers note that we’ve significantly refactored the modeling and tokenization files. Modeling files have been greatly improved thanks to the modular approach mentioned above, on top of standardization across models. Standardization contributes to abstracting most of the tools that don’t make up a model, so that the modeling code only contains the relevant parts for a model’s forward/backward passes.
Alongside this work, we’re simplifying the tokenization and processing files: going forward, we’ll only focus on the tokenizers backend, removing the concept of “Fast” and “Slow” tokenizers.
It has been revealed that we'll use tokenizers as our main tokenization backend, just as we do for PyTorch-based models. We’ll offer alternatives for Sentencepiece or MistralCommon backed tokenizers, which will be non-default but will be supported. Image processors will now only exist with their fast variant, which depends on the torchvision backend.
Finally, we’re sunsetting our Flax/TensorFlow support in favor of focusing on PyTorch as the sole backend; however, we're also working with partners in the Jax ecosystem to ensure we have compatibility between our models and this ecosystem.
According to recent reports, with its v5 release, transformers is going all in on PyTorch. Transformers acts as a source of truth and foundation for modeling across the field; we've been working with the team to ensure good performance across the stack.
We're excited to continue pushing for this in the future across training, inference, and deployment.
-- Matt White, Executive Director, PyTorch Foundation. GM of AI, Linux Foundation.
Training remains a major focus of the team as we head into v5: whereas previously we would focus heavily on fine-tuning rather than pre-training/full-training at scale, we’ve recently done significant work to improve our support for the latter as well.
Supporting pre-training meant reworking the initialization of our models, ensuring that they worked at scale with different parallelism paradigms, and shipping support for optimized kernels for both the forward and backward passes.
Going forward, we’re excited to have extended compatibility with torchtitan, megatron, nanotron, as well as any other pre-training tool that is interested in collaborating with us.
We continue collaborating closely with all fine-tuning tools in the Python ecosystem. We aim to continue providing model implementations compatible with Unsloth, Axolotl, LlamaFactory, TRL and others in the PyTorch ecosystem; but we are also working with tools such as MaxText, in the JAX ecosystem, to have good interoperability between their frameworks and transformers.
All fine-tuning and post-training tools can now rely on transformers for model definitions; further enabling Agentic use-cases through OpenEnv or the Prime Environment Hub.
We’re putting a significant focus on inference for v5, with several paradigm changes: the introduction of specialized kernels, cleaner defaults, new APIs, support for optimized inference engines.
Industry observers note that similarly to training, we’ve been putting some effort in packaging kernels so that they’re automatically used in case your hardware and software permits it. If you haven’t heard of kernels before, we recommend taking a look at this doc.
Alongside this effort, we ship two new APIs dedicated to inference:.
According to recent reports, we see this as a major step forward for use-cases such as evaluation, where a great number of inference requests are done simultaneously. We don’t aim to do specialized optimizations like the dedicated inference engines (vLLM, SGLang, TensorRT LLM). Instead, we aim to be perfectly inter-compatible with these, as detailed in the next section.
The Transformers backend in vLLM has been very enabling to get more architectures, like BERT and other encoders, available to more users. We've been working with the Transformers team to ensure many models are available across modalities with the best performance possible. This is just the start of our collaboration: we're happy to see the Transformers team will have this as a focus going into version 5.
-- Simon Mo, Harry Mellor at vLLM.
Standardization is key to accelerating AI innovation. Transformers v5 empowers the SGLang team to spend less time on model reimplementation and more time on kernel optimization. We look forward to building a more efficient and unified AI ecosystem together!
In a recent development, recently, we've been working hand in hand with the most popular inference engines for them to use transformers as a backend. The value added is significant: as soon as a model is added to transformers, it becomes available in these inference engines, while taking advantage of the strengths each engine provides: inference optimizations, specialized kernels, dynamic batching, etc.
We've also been working very closely with ONNXRuntime, llama.cpp and MLX so that the implementations between transformers and these modeling libraries have great interoperability. For example, thanks to a significant community effort, it's now very easy to load GGUF files in transformers for further fine-tuning. Conversely, transformers models can be easily converted to GGUF files for use with llama.cpp.
The Transformers framework is the go-to place for reference AI model implementations. The framework plays a crucial role in enabling modern AI across the entire stack. The team and the community behind the project truly understand and embrace the spirit of the open-source development and collaboration.
The same is true for MLX, where the transformers' safetensors files are directly compatible with MLX's models.
It’s hard to overstate the importance of Transformers (and datasets, tokenizers, etc) to the open-source and overall AI ecosystem. I can’t count the number of times I’ve personally used Transformers as a source-of-truth.
Recent findings suggest that finally, we’re pushing the boundaries of local inference and are working hand-in-hand with the executorch team to get the transformers models to be available on-device. We’re expanding the coverage to multimodal models (vision, audio) through optimum.
Quantization is swiftly emerging as the standard for state-of-the-art model development. Many SOTA models are now released in low-precision formats such as 8-bit and 4-bit (e.g., gpt-oss, Kimi-K2, Deepseek-r1), hardware is increasingly optimized for low-precision workloads, and the community is actively sharing high-quality quantized checkpoints. In v5, we're making quantization a central focus of Transformers support, ensuring full compatibility with all major features, and delivering a reliable framework for training and inference.
We introduce a significant change to the way we load weights in our models; and with this, we move to quantization being a first-class citizen.
Our collaboration with the Transformers team was highly productive, marked by their proactive code reviews, feedback, and technical expertise. Their support was crucial in integrating TorchAO, expanding quantization features, and improving documentation for broader adoption in the V5.
We're excited that v5 has made quantization a first-class citizen. It provides the foundation for bitsandbytes to better support key features like TP and MoEs, and also makes it easier to integrate new quantization methods.
-- Matthew Douglas & Titus von Koeller, bitsandbytes.
Sources indicate that the overarching theme of this version 5 release is “interoperability”. All refactors, performance improvements, and standardization are aligned with this theme. v5 plays nicely and end-to-end with the growing ecosystem: train a model with Unsloth/Axolotl/LlamaFactory/MaxText deploy it with vLLM/SGLang, and export it to llama.cpp/executorch/MLX to run locally!
Industry observers note that version 5 is undeniably an accomplishment of the past five years by a very large number of people in our community. We also see it as a promise, and as a beacon of the direction we want to go.
Industry observers note that we took it as an opportunity to clean up the toolkit and isolate what mattered; we now have a clean slate on top of which to build. Thanks to the many changes from the community and team, improvements in performance, usability, and readability, will be simpler to ship.
Now that v5.0.0's first RC is out there, we'll be eagerly awaiting your feedback. Please check our release notes for all the technical details, and we'll be awaiting your feedback in our GitHub issues!
Awesome work, great job of maintaining the library, it sure isn't easy with all the different architectures and advancements.
Congratulations for the launch !
Sources indicate that no, you don’t! It’s just pure control. Researchers would love to have direct PyTorch only access to the architecture, training, and inference code for different models without this Transformers blab.
Is there a spaces link to the " Transformers Models Timeline" dashboard? I want to add it in my course.
will transformers serve be a good enough alternative to llama.cpp?

General
⚖️ Neutral
🌐 Dexerto
#11419. Tech Report: Free browser game lets you play poker with Wikipedia articles
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (472 w)
Tech Report: Free browser game lets you play poker with Wikipedia articles
📅 16 Nov 2026 | ⏱️ 2 min read (472 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A free browser game called Wikdraw is putting a bizarre twist on poker by replacing traditional playing cards with Wikipedia articles, challenging players to find connections between completely unrelated subjects.
- Created by tolecrien, Wikdraw takes the familiar five-card draw format and swaps out suits and numbers for everything from Hollywood celebrities and historical figures to countries, animals, and scientific concepts.
- Sources indicate that the goal is simple: build the strongest possible poker hand by finding things your five Wikipedia articles have in common.
A free browser game called Wikdraw is putting a bizarre twist on poker by replacing traditional playing cards with Wikipedia articles, challenging players to find connections between completely unrelated subjects.
Created by tolecrien, Wikdraw takes the familiar five-card draw format and swaps out suits and numbers for everything from Hollywood celebrities and historical figures to countries, animals, and scientific concepts.
Sources indicate that the goal is simple: build the strongest possible poker hand by finding things your five Wikipedia articles have in common. There’s no betting involved, and it’s a single-player game, meaning it’s all about your own high scores.
Players start with five cards from a 15-card deck and have two opportunities to discard unwanted cards and draw replacements. However, unlike traditional poker, you’re looking for shared characteristics rather than matching numbers.
For example, five actors could form a flush, while three historical figures from the same country and two animals could potentially make a full house.
@taksin_glock19 beat this pic.twitter.com/pDNCeBe5hV.
What makes Wikdraw particularly interesting is its scoring system, which awards points based on how unusual the connections between cards are.
Sources indicate that common traits, such as being American or born in the same century, are worth very little. However, more specific connections can earn significantly higher scores.
In one example, pairing Shaquille O’Neal with Olivia Rodrigo earns 35 points because both are associated with Interscope Records. Their shared status as singers adds another 13 points, while simply being American earns nothing.
Another hand featuring Israel, the British Raj, Sri Lanka, a camel, and a donkey can form a full house thanks to shared geographical connections between the first three cards and similarities between the two animals.
Wendy’s free RPG rewards players with real food for beating bosses and is 15 hours long.
Addictive browser game turns Teamfight Tactics into Dragon Ball Z.
Wikipedia gacha game turns random pages into Pokemon cards you can collect.
The game even rewards multiple overlapping connections, meaning a single pair of cards can earn points for several different traits.
Players also receive bonuses for their final hand, including 150 points for a flush, 100 for four of a kind, and 75 for a full house.
The catch is that the game doesn’t reveal all the connections until the round ends, leaving players to figure out which seemingly unrelated Wikipedia pages might actually go together.
Wikdraw offers a daily challenge featuring the same 15 cards for everyone, although they’re shuffled differently for each player. There’s also a random mode for anyone wanting to keep playing.
It’s not the first time Wikipedia has been turned into an unlikely card game, either. Earlier in 2026, Wikigacha transformed Wikipedia articles into collectible Pokemon-style cards, complete with booster packs and PvP battles.
Wikdraw is completely free to play at wikdraw.org, with no download required.
🔗 Related Articles
📰 #23654. Tech Report: Devolver Digital is giving away a free game if you delete GTA 6 📰 #12950. Tech Report: Drawquarium is the anti-AI cozy game that lets you create your own fish tank 📰 #23639. Tech Report: Game dev reveals huge difference in money made on Steam vs Epic Games Store
General
⚖️ Neutral
🌐 Sciencedaily
#11418. Industry News: Scientists tracked kids for 8 years — the screen time result was unexpected
📅 15 Aug 2026 • ⏱️ 4m • 📚 Deep Dive (770 w)
Industry News: Scientists tracked kids for 8 years — the screen time result was unexpected
📅 15 Aug 2026 | ⏱️ 4 min read (770 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- A Finnish study has found an unexpected association between screen use and cognitive performance.
- Low levels of physical activity among adolescents remain a significant public health concern.
- These years are especially crucial because the brain is still developing.
A Finnish study has found an unexpected association between screen use and cognitive performance. Children who accumulated more screen time as they grew up tended to show better cognitive processing during adolescence. One of the researchers cautions against viewing screen time as entirely harmful and states the goal should be to balance physical activity with screen use that encourages active thinking.
Low levels of physical activity among adolescents remain a significant public health concern. Sedentary behavior has been associated with poorer academic achievement, while physical activity is known to support brain function, particularly in adults. Much less is known, however, about how physical activity and sedentary behavior during childhood and adolescence relate to cognitive processing later in adolescence.
These years are especially crucial because the brain is still developing. Factors that shape cognitive abilities during childhood and adolescence may have lasting effects that extend into adulthood, potentially influencing education and working life.
According to recent reports, researchers examined how physical activity, sedentary behavior, and screen time from childhood through adolescence were related to cognitive processing in the teenage years. They also looked for differences between girls and boys and investigated whether the intensity of physical activity played a role.
More Screen Time Linked to Better Cognitive Processing.
The results revealed that greater screen time beginning in childhood was associated with better cognitive processing in adolescence.
Recent findings suggest that "The findings suggest that screen time can support children's and adolescents' cognitive processing. Presumably, the essential point here is what kind of things they do in their screen time. Teachers and parents should encourage children to use devices and screens in such ways that promote active thinking, problem-solving, creativity and learning," states Doctoral Researcher Petri Jalanko from the University of Jyväskylä.
In a recent development, the findings suggest that the type of screen activity may be key. Digital activities that involve learning, creativity, problem-solving, or other forms of active mental engagement could potentially help explain the association observed in the study.
"We should not regard screen time solely as harmful but seek balance between physical activity and screen time that promotes active thinking," Jalanko summarizes.
Physical Activity Showed Different Links in Girls and Boys.
The relationship between physical activity and cognition was more complicated.
Among girls, greater amounts of light intensity physical activity since childhood were associated with better working memory during adolescence. Among boys, greater participation in guided physical activity from childhood through adolescence was linked to better working memory.
Recent findings suggest that the researchers also found an unexpected pattern involving unsupervised exercise. Lower levels of self-reported unsupervised physical activity were associated with better cognitive processing in adolescence.
By contrast, physical activity and sedentary time measured using a device that tracked heart rate and movement were not associated with cognitive processing. One possible explanation is that these sensors can measure movement and physiological activity but cannot determine exactly what a person is doing during periods of activity or inactivity.
"Our study indicates that the connections of physical activity and sedentary behavior to cognitive processing are complex and depend on the sex, the type and assessment method of physical activity and sedentary time. Moreover, boys and girls may benefit from different types of physical activity in view of brain health," Jalanko adds.
More Research Is Needed to Determine Cause and Effect.
The researchers emphasize that the findings show associations rather than proving that screen time or particular types of physical activity directly cause changes in cognitive performance.
"However, we need more intervention studies to find out causal relations and sex differences in this respect. Moreover, it is notable to examine more specifically the effects of the intensity of physical activity on changes taking place in cognitive processing.".
According to recent reports, the results come from an eight-year follow-up of the PANIC study on children's physical activity and nutrition. The current analysis included 124 girls and 136 boys with an average age of 15.8 years.
Researchers measured physical activity and sedentary behavior using both survey questionnaires and a device that combined heart rate and movement measurements. Learning, attention, and working memory were evaluated using the CogState test battery.
The research was published in the journal Pediatric Exercise Science.
Industry observers note that materials provided by University of Jyväskylä - Jyväskylän yliopisto. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.

AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11417. Tech Report: We Got Claude to Fine-Tune an Open Source LLM
📅 04 Dec 2025 • ⏱️ 10m • 📚 Deep Dive (1941 w)
Tech Report: We Got Claude to Fine-Tune an Open Source LLM
📅 04 Dec 2025 | ⏱️ 10 min read (1941 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~10 mins left to finish
📖 0% read
💡 Key Takeaways
- According to recent reports, we gave Claude the ability to fine-tune language models using a new tool called Hugging Face Skills.
- Recent findings suggest that claude Code can use "skills"—packaged instructions, scripts, and domain knowledge—to accomplish specialized tasks.
- In a recent development, the model trains on Hugging Face GPUs while you do other things.
According to recent reports, we gave Claude the ability to fine-tune language models using a new tool called Hugging Face Skills. Not just write training scripts, but to actually submit jobs to cloud GPUs, monitor progress, and push finished models to the Hugging Face Hub. This tutorial shows you how it works and how to use it yourself.
Recent findings suggest that claude Code can use "skills"—packaged instructions, scripts, and domain knowledge—to accomplish specialized tasks. The hf-llm-trainer skill teaches Claude everything it needs to know about training: which GPU to pick for your model size, how to configure Hub authentication, when to use LoRA versus full fine-tuning, and how to handle the dozens of other decisions that go into a successful training run.
With this skill, you can tell Claude things like:.
In a recent development, the model trains on Hugging Face GPUs while you do other things. When it's done, your fine-tuned model appears on the Hub, ready to use.
In a recent development, this isn't a toy demo. The skill supports the same training methods used in production: supervised fine-tuning, direct preference optimization, and reinforcement learning with verifiable rewards. You can train models from 0.5B to 70B parameters, convert them to GGUF for local deployment, and run multi-stage pipelines that combine different techniques.
Hugging Face skills are compatible with Claude Code, Codex, and Gemini CLI. With integrations on the way for Cursor, Windsurf, and Continue.
This repo includes gemini-extension.json to integrate with the Gemini CLI.
You have to authenticate to your Hugging Face account with a write-access token so that the job can create a model repo.
Configure Hugging Face MCP Server to use your write token by sending it in either the HF_TOKEN or Authorization: Bearer HTTP Headers.
For Claude Code: claude mcp add --transport http hf-skills https://huggingface.co/mcp?bouquet=skills --header "Authorization: Bearer $HF_TOKEN".
Industry observers note that let's walk through a complete example. We'll fine-tune a small model to see the full workflow, then explore more advanced capabilities.
Start with a simple and clear instruction to fine tune a specific model.
The coding agent analyzes your request and prepares a training configuration. For a 0.6B model on a demo dataset, it selects t4-small—enough GPU for this model size and the cheapest option available.
Sources indicate that the open-r1/codeforces-cots dataset is a dataset of codeforces problems and solutions. It is a good dataset for instruction tuning a model to solve hard coding problems.
This works for vision language models too! You can simply run "Fine-tune Qwen/Qwen3-VL-2B-Instruct on llava-instruct-mix".
Before your coding agent submits anything, you'll see the configuration:.
According to recent reports, this is your chance to adjust anything. Change the output repo name, pick different hardware, or ask Claude to modify training parameters. Once you approve, the agent submits the job.
For example, you can ask the agent to try a test run:.
After submission, you get job details:.
The skill includes Trackio integration, so you can watch training loss decrease in real-time. Jobs run asynchronously so you can close your terminal and come back later. When you want an revision:.
Then the agent fetches the logs and summarizes progress.
When training completes, your model is on the Hub:.
Recent findings suggest that that's the full loop. You described what you wanted in plain English, and the agent handled GPU selection, script generation, job submission, authentication, and persistence. The whole thing cost about thirty cents.
In a recent development, the skill supports three training approaches. Understanding when to use each one helps you get better results.
In a recent development, SFT is where most projects start. You provide demonstration data—examples of inputs and desired outputs—and training adjusts the model to match those patterns.
Use SFT when you have high-quality examples of the behavior you want. Customer support conversations, code generation pairs, domain-specific Q&A—anything where you can show the model what good looks like.
The agent validates the dataset, selects hardware (a10g-large with LoRA for a 7B model), and configures training with checkpoints and monitoring.
For models larger than 3B parameters, the agent automatically uses LoRA (Low-Rank Adaptation) to reduce memory requirements. This makes training 7B or 13B models feasible on single GPUs while preserving most of the quality of full fine-tuning.
DPO trains on preference pairs—responses where one is "chosen" and another is "rejected." This aligns model outputs with human preferences, typically after an initial SFT stage.
Sources indicate that use DPO when you have preference annotations from human labelers or automated comparisons. DPO optimizes directly for the preferred response without needing a separate reward model.
DPO is sensitive to dataset format. It requires columns named exactly chosen and rejected, or a prompt column with the input. The agent validates this first and shows you how to map columns if your dataset uses different names.
Sources indicate that you can run DPO using Skills on vision language models too! Try it out with openbmb/RLAIF-V-Dataset. Claude will apply minor modifications but will succeed in training.
GRPO is a reinforcement learning task that is proven to be effective on verifiable tasks like solving math problems, writing code, or any task with a programmatic success criterion.
It has been revealed that the model generates responses, receives rewards based on correctness, and learns from the outcomes. This is more complex than SFT or DPO, but the configuration is similar.
The agent selects hardware based on your model size, but understanding the tradeoffs helps you make better decisions.
For tiny models under 1B parameters, t4-small works well. These models train rapidly—expect $1-2 for a full run. This is perfect for educational or experimental runs.
For small models (1-3B), step up to t4-medium or a10g-small. Training takes a few hours and costs $5-15.
For medium models (3-7B), you need a10g-large or a100-large with LoRA. Full fine-tuning doesn't fit, but LoRA makes these very trainable. Budget $15-40 for production.
For large models (7B+), this HF skills job is not suitable.
When testing a workflow, start small:.
The coding agent configures minimal training—enough to verify your pipeline works without real cost.
Always run a demo before committing to a multi-hour production job. A $0.50 demo that catches a format error saves a $30 failed run.
Dataset format is the most common source of training failures. The agent can validate datasets before you spend GPU time.
The agent runs a quick inspection on CPU (fractions of a penny) and reports:.
If your dataset needs transformation, the agent can show you how:.
The agent provides mapping code and can incorporate it directly into your training script.
Real-time monitoring helps you catch problems early. The skill configures Trackio by default—after submitting a job, you can watch metrics at:.
It has been revealed that this shows training loss, learning rate, and validation metrics. A healthy run shows steadily decreasing loss.
Ask the agent about status anytime:.
If something goes wrong, the agent helps diagnose. Out of memory? the agent suggests reducing batch size or upgrading hardware. Dataset error? The agent identifies the mismatch. Timeout? The agent recommends longer duration or faster training settings.
According to recent reports, after training, you might want to run your model locally. The GGUF format works with llama.cpp and dependent tools like LM Studio, Ollama, etc.
The agent submits a conversion job that merges LoRA adapters, converts to GGUF, applies quantization, and pushes to Hub.
It has been revealed that we've shown that coding agents like Claude Code, Codex, or Gemini CLI can handle the full lifecycle of model fine-tuning: validating data, selecting hardware, generating scripts, submitting jobs, monitoring progress, and converting outputs. This turns what used to be a specialized skill into something you can do through conversation.
The skill is open source. You can extend it, customize it for your workflows, or use it as a starting point for other training scenarios.
Is this still usable without a Pro account? Will it be able to output everything up to "Submit the job to Hugging Face Jobs"?
Is there data privacy when doing this?
Is it posted privately to a personal/team hub?
Could this be done locally without the push to the repo?
Another agentic way of wasting tokens.
is it possible to use this inside vscode's copilot extension ?
Skill documentation is not available at the provided link - https://github.com/huggingface/skills/blob/main/hf-llm-trainer/SKILL.md.
Ah, we moved a couple of bits around in the repo -- link for that is here: https://github.com/huggingface/skills/blob/main/hf-llm-trainer/skills/model-trainer/SKILL.md -- I'll update the article 👍.
"Really fascinating read! I found the explanation of Hugging Face’s “Skills Training” initiative — how it lets you use a coding‑agent (like Claude Code or other supported agents) to fine‑tune large language models, submit GPU jobs, monitor progress and push trained models to the Hub — particularly eye‑opening. The combination of high‑level instructions, hardware selection, monitoring, and automation makes the complex process of model training much more approachable, even for developers who may not be ML‑infrastructure experts.
I also recently read a related guide: https://mobisoftinfotech.com/resources/blog/ai‑development/llm‑api‑pricing‑guide — which gives practical advice on LLM API usage, token‑based pricing, and how to blueprint costs when working with LLMs.
Putting your article’s look into empowering accessible LLM fine‑tuning together with the cost‑management strategies from that guide gives a well‑rounded perspective: it helps developers understand not just what is possible now with modern tools, but also how to build and deploy responsibly, balancing capability and cost.".
Great work and great article!Regarding the maximum models size we can train using this approach, at the beginning of the article it's mentioned "models from 0.5B to 70B parameters" but at the end you write that "For large models (7B+), this HF skills job is not suitable", which order of magnitude is correct?I suspect the max range is 7B, if it's the case, do you plan to support training of larger models?Thanks!
is the trained model now open source and / or available to the public?
https://huggingface.co/blog/sionic-ai/claude-code-skills-training.
Nice work about the demo getting Claude Code to fine-tune an open LLM. But the researchers from Sionic AI already do most of their work with Claude Code. It writes training scripts, debugs CUDA errors, searches hyperparameters overnight. For the actual work of building models, Claude has become the default partner. But there was one thing it couldn't do - remember what the teammates learned last week.
Is it possible to use it even in privately uploaded datasets?
how many tokens will a session incur?
According to recent reports, this is genuinely game-changing for AI teams working with limited MLOps resources. Having Claude automatically handle hardware selection, job orchestration, and monitoring removes so much friction from the fine-tuning process - I've seen too many projects stall because teams get bogged down in the infrastructure complexity rather than focusing on model performance. The business impact here is huge: instead of needing dedicated DevOps engineers to manage training pipelines, data scientists can now iterate much faster on custom models. The fact that it supports the full production stack (SFT, DPO, RLHF) means you're not just prototyping but actually building deployment-ready models. What really excites me is the cost optimization angle - automatic hardware matching means you're not overpaying for compute while still getting reasonable training times. The multi-stage pipeline support is particularly valuable for enterprise use cases where you need that SFT → DPO → RLHF workflow for safety and alignment. This could democratize custom model development for mid-market companies who previously couldn't justify the engineering overhead. Looking forward to testing this on some internal projects where we've been manually managing these workflows.
According to recent reports, I think this document needs to be updated. The skills name has changed based on what I see on the huggingface github repo.

General
⚖️ Neutral
🌐 Dexerto
#11416. Birdwatchers are buying GTA 6 just to look at birds
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (411 w)
Birdwatchers are buying GTA 6 just to look at birds
📅 16 Nov 2026 | ⏱️ 2 min read (411 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- GTA 6 hype has even reached the birdwatching community, where some players are already planning to put the heists on hold and see how many birds they can spot.
- With GTA 6 launching on November 19, the wait for the first fresh game in the series in over a decade is almost over.
- But it’s not just video game players who are ready to lose hours in Vice City, even birdwatchers are pumped for the release.
GTA 6 hype has even reached the birdwatching community, where some players are already planning to put the heists on hold and see how many birds they can spot.
With GTA 6 launching on November 19, the wait for the first fresh game in the series in over a decade is almost over. It’s already expected to break sales records when it drops and could cost the US as much as $1 billion in sick days as fans abandon work to play.
But it’s not just video game players who are ready to lose hours in Vice City, even birdwatchers are pumped for the release.
GTA 6 reportedly has 62 types of birds to find and record in a wildlife logbook, giving birdwatchers plenty of reasons to explore Leonida with a pair of binoculars.
Recent findings suggest that A November 15 post on r/birding picked up more than 1,700 upvotes after one user asked if any other birdwatchers were looking forward to the game. “I think the crime sprees are going to have to wait,” they wrote.
It turns out they were far from alone, as plenty of fellow birders replied, saying they were ready to take their hobby into GTA 6.
“I’m so hyped. Probably the first thing I do if we’re given the binoculars right away,” stated one reply.
Sources indicate that “My birding group is planning to stream the week after it comes out,” added another. “We streamed Red Dead last year, and we’re hoping there’ll be tons of birds to spot for GTA.”.
GTA 6 forces you to take your time with the main story instead of speedrunning it.
GTA 6 will feature over 170 different animals including “Legendary” ones.
Police can’t wait for GTA 6 to be released so they can “catch a break”.
“I feel like such a dork being excited for the wildlife in a GTA game of all places but I truly am excited to see it all LOL,” wrote a third.
This isn’t the first time that a Rockstar game has appealed to birdwatchers either, as many commented that Red Dead Redemption 2 got them into the hobby.
“RDR2 flipped the birding switch on for me. I have identified actual birds irl because I saw them in the game,” noted one Redditor. “No shooting though!”.
While these players will be heading out into Leonida to find birds, others will be looking to find the best weapons and cars.
🔗 Related Articles
📰 #21160. These Tulips Look Just Like Peonies – and Their Ravishing Flowers Last for Months, Not Days 📰 #16759. GTA 6 hacker behind original 2022 leaks pleads guilty just days ahead of game’s launch 📰 #16613. Breaking: 'They would never stop working on this game': GTA 6's development could've gone on for longer just because 'it's really hard to close it down'
AI & Tech
⚖️ Neutral
🌐 Sitepoint
#11415. How Text-to-Image AI Generators Work, and 5 Tools That Deliver Good Results
📅 09 Nov 2026 • ⏱️ 11m • 📚 Deep Dive (2114 w)
How Text-to-Image AI Generators Work, and 5 Tools That Deliver Good Results
📅 09 Nov 2026 | ⏱️ 11 min read (2114 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~11 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- Recent findings suggest that weekly.
- It has been revealed that 7 Day Free Trial.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Recent findings suggest that weekly. Free. One click to leave.
It has been revealed that 7 Day Free Trial. Cancel Anytime.
In a recent development, type “a lighthouse on a cliff at dusk, oil painting, warm light” into a text box, wait ten seconds, and a picture that never existed appears. It feels like magic, but it is a well-understood pipeline of language models, neural networks and a great deal of math. Knowing how that pipeline works makes you a better prompter, helps you diagnose bad results, and makes it easier to choose the right tool for a job.
According to recent reports, this guide explains how text-to-image generators turn words into pixels, why they fail in predictable ways, and how to write prompts that work with the model instead of against it. It then compares five tools that consistently produce good results, starting with Pollo AI, and finishes with a practical workflow, a troubleshooting table and an FAQ. Plans, credits and model versions change often, so confirm current details on each vendor’s site before you commit to a subscription.
Early image generators were mostly GANs, or generative adversarial networks. A GAN pits two networks against each other: a generator that produces images and a discriminator that tries to spot fakes. GANs could produce sharp faces and textures, but they were hard to train, often collapsed into repeating the same few outputs, and were poor at following free-form text.
According to recent reports, A second line of research used autoregressive models, which generate an image piece by piece the way a language model generates words. These handled text prompts better but were slow at high resolution.
Industry observers note that the shift came with diffusion models. Researchers showed that a network trained to reverse a gradual noising process could generate images with excellent quality and diversity, and that it was far more stable to train than a GAN. Combine that with text conditioning and a compressed image representation, and you get the systems behind most of today’s tools. Newer models increasingly swap the traditional convolutional network for transformers, but the core idea of iterative denoising is still the foundation.
According to recent reports, under the hood, mainstream generators combine three ideas: a way to understand text, a way to represent images compactly, and a way to generate them gradually. The sections below follow a prompt from keystroke to finished picture.
It has been revealed that neural networks cannot read words, so your prompt is first split into tokens, small chunks of text such as whole words or word fragments. A text encoder then converts those tokens into an embedding, a grid of numbers that captures meaning and context. Many systems use encoders trained jointly on images and their captions, so that the text “a red bicycle” and pictures of red bicycles end up close together in the same mathematical space. Some newer systems add a large language model to understand longer, more detailed instructions.
Sources indicate that this is why wording matters. The encoder only sees what you wrote, and it has a limited capacity. A short, specific prompt produces a clear signal. A long, rambling one dilutes each instruction.
It has been revealed that instead of drawing on a blank canvas, the model begins with random static. The pattern of that static is controlled by a seed number. The same prompt with a different seed gives a different image, because it starts from different noise. If a tool lets you fix the seed, you can make results repeatable and change just one variable at a time.
According to recent reports, during training, engineers take millions of real images and add noise to them in small steps until only static remains. The network is then trained to predict the noise that was added at each step, which teaches it to reverse the process. At generation time, the model applies that skill to pure noise, removing a little at each step. Because it has learned what real images look like, the “noise” it removes gradually reveals something that looks plausible.
Sources indicate that your text embedding is fed into the network through a mechanism called cross-attention. At each step, parts of the evolving image can “look at” relevant parts of the prompt and adjust accordingly. A region that will become a lighthouse attends to the word “lighthouse”. A region that will become the sky attends to “dusk”.
A setting called classifier-free guidance, often shown as guidance scale or prompt strength, controls how strongly each step is pulled toward the prompt. The model computes one prediction with the prompt and one without it, then exaggerates the difference. A low value gives the model freedom and often more natural, varied results. A high value follows the words more literally but can produce oversaturated, over-sharpened or distorted images.
Running diffusion directly on full-resolution pixels would be very expensive. The idea behind Stable Diffusion, known as latent diffusion, is to compress images into a much smaller latent representation using an autoencoder. Denoising happens in that compact space, and a decoder turns the final latent back into a full image. This is a major reason high-quality generation now runs in seconds on a cloud GPU instead of minutes.
Recent findings suggest that the number of denoising steps and the scheduler, which decides how much noise to remove at each step, shape the speed and look of the result. More steps usually add detail up to a point, then give diminishing returns. Many tools hide these settings, but the trade-off is always the same: fewer steps are faster and cheaper, more steps can look more refined.
Recent findings suggest that most pipelines finish with an upscaler or refinement pass that sharpens detail and fixes small artifacts. Many tools also offer inpainting, which regenerates only a selected region, outpainting, which extends the canvas, and variations, which restart from a related image.
Sources indicate that A generator can only produce what it has learned to represent. Models are trained on very large collections of images paired with captions, and the quality, diversity and licensing of that data affect both the output and the legal picture. Models trained on more photographs tend to produce convincing photorealism. Models tuned on illustration and concept art lean toward painterly looks.
This also explains a few behaviors. Common subjects look great because the model has seen thousands of examples. Rare or very specific subjects, such as an unusual machine part or a niche cultural item, often look generic or wrong. Biases in the data can show up as stereotypes, for example in how “a doctor” or “a CEO” is depicted, so it helps to describe the people and setting you actually want.
Understanding the process explains the familiar failures:.
Pollo AI’s text to image AI is a browser-based generator built around a simple loop: write a prompt, pick a style, generate, and download. Its page highlights HD output and a wide range of looks, from photorealistic scenes to cute cartoons, anime, pencil sketches, isometric art, abstract compositions and surreal visuals. Files can be downloaded as WebP, PNG or JPEG, a practical spread for web work: WebP keeps pages light, PNG preserves clean edges and transparency-friendly graphics, and JPEG works almost everywhere.
It has been revealed that pollo is also part of a wider platform that covers AI video, so a still image you like can become the starting point for motion without switching ecosystems. That matters for teams producing social content, because one workflow can cover both the image and the short clip built from it.
Things to check: the page does not list specific model names or credit amounts, so review the current plan details before relying on it for high-volume work. Commercial use requires a paid plan.
Best for: quick, versatile image generation across many styles, especially if you also blueprint to make video.
Midjourney has built its reputation on strong aesthetics. Images tend to arrive with polished composition, dramatic lighting and a distinctive painterly feel, which is why it is popular for concept art, mood boards, album-style visuals and editorial illustration. It offers style references and personalization, so you can steer results toward a consistent look across a project. It also supports editing and variation tools for refining a chosen image.
The trade-offs are practical. It is a paid service, and its prompts reward experimentation over literal instruction following, so you sometimes get something beautiful that is not exactly what you described.
Best for: artistic, high-impact visuals where mood matters more than exact specification.
It has been revealed that adobe Firefly focuses on professional workflows and commercial confidence. Adobe describes Firefly’s own models as trained on licensed content such as Adobe Stock and public-domain material, and it attaches Content Credentials metadata that records AI involvement. It connects with tools many teams already use, including Photoshop features like generative fill and generative expand, which suits designers who edit as much as they generate.
Firefly also provides controls such as style and composition references. Its results can feel cleaner and more commercial than Midjourney’s, which is an advantage for marketing assets and a limitation if you want a wild artistic look.
Best for: marketing and design teams that need editing tools and clearer licensing.
Ideogram is known for rendering legible text inside images, a task where many generators struggle. That makes it a strong choice for posters, social graphics, logo concepts, packaging mockups and product visuals that need a headline or short phrase to read correctly. It also offers style controls and a community gallery that doubles as a prompt library.
Industry observers note that even so, long paragraphs of on-image text can still go wrong. Keep the copy to a few words, put it in quotation marks in the prompt, and describe the lettering style.
Best for: graphics that combine imagery with short, readable text.
Sources indicate that leonardo AI is built for creators who want more control. It offers multiple models, fine-tuning options, image-to-image guidance and a canvas for editing, with a particular following among game artists and designers who need consistent characters and assets. Features such as reference-based generation help keep a character recognizable across many scenes.
The wide set of options is powerful but means a steeper learning curve than a one-box generator, and credit systems can take time to understand.
Best for: consistent characters, game and concept assets, and users who like tuning settings.
It has been revealed that A reliable prompt has five parts. Put the most important part first, because it often carries the most weight.
Compare weak prompts with stronger ones:.
Industry observers note that how do text-to-image generators work? They convert your prompt into a numerical representation, then use a diffusion model to remove noise from a random starting image step by step, guided by that representation, until a matching picture appears.
Recent findings suggest that which text-to-image tool is best? It depends on the job. Pollo AI suits fast, varied generation, Midjourney suits artistic work, Adobe Firefly suits commercial design, Ideogram suits images with text and Leonardo AI suits tuned, consistent assets.
In a recent development, why does the same prompt give different results? Each run starts from a different random seed. Fixing the seed, where a tool allows it, makes results more repeatable.
Sources indicate that can I use AI-generated images commercially? Often yes, but the rules differ by tool and plan. Pollo, for example, notes that commercial use requires a paid plan. Always check the current terms.
According to recent reports, how do I get readable text in an AI image? Use a tool strong at text, keep the wording to a few words, and add the text in a design editor if accuracy is critical.
Industry observers note that what file format should I download? WebP for lightweight web pages, PNG for graphics and sharp edges, JPEG for broad compatibility.
Can I turn a generated image into a video? Many platforms support it. Pollo AI, for example, also covers AI video, so you can move from a still to motion in one place.
Text-to-image generators work by turning language into numbers and using those numbers to guide a model that denoises random static into a picture. Once you understand that, prompts stop being guesswork: you give the model a clear subject, style and lighting, you iterate one change at a time, and you fix small flaws locally. Start with a versatile option such as Pollo AI, then add Midjourney, Firefly, Ideogram or Leonardo when a project needs their particular strengths.
7 Day Free Trial. Cancel Anytime.
General
⚖️ Neutral
🌐 Sciencedaily
#11414. Industry News: Tiny robots powered by light can hunt down and collect bacteria
📅 18 Aug 2026 • ⏱️ 3m • 📚 Deep Dive (640 w)
Industry News: Tiny robots powered by light can hunt down and collect bacteria
📅 18 Aug 2026 | ⏱️ 3 min read (640 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Robots small enough to operate in the microbial world could give scientists a new way to directly handle objects that are impossible to manipulate by hand.
- Industry observers note that that capability could be especially useful for biological materials in water, including individual cells and bacteria.
- Sources indicate that one of the biggest obstacles in developing machines this small is finding an effective way to propel and control them.
Robots small enough to operate in the microbial world could give scientists a new way to directly handle objects that are impossible to manipulate by hand. These tiny machines are around 50 times smaller than the diameter of a human hair, bringing researchers closer to the long-pursued goal of interacting directly with the microscopic world.
Industry observers note that that capability could be especially useful for biological materials in water, including individual cells and bacteria. Precisely controlling and moving objects at this scale has been a persistent challenge. The newly developed nanorobots show that it is already possible to collect bacteria, transport them, and release them at selected locations.
Light Powers and Steers the Tiny Robots.
Sources indicate that one of the biggest obstacles in developing machines this small is finding an effective way to propel and control them. At Julius-Maximilians-Universität Würzburg (JMU), a research team led by Professor Bert Hecht has been developing a solution that uses the recoil produced by individual photons to move microscopic devices known as microdrones.
The devices contain as many as four plasmonic nanoantennas. These antennas absorb light with a particular color and helicity, then emit that light in a specific direction. Redirecting each photon creates a tiny recoil force, similar in principle to the recoil produced when a bullet is fired. Because the microdrones have so little mass, those extremely small forces can generate substantial acceleration and speed.
Recent findings suggest that for the latest work, the researchers reduced the size of their light-powered robots even further, producing devices smaller than one micrometer. Simplifying the steering system was an important part of achieving that size while retaining propulsion based on photon recoil.
The newly introduced control method takes advantage of nanoscale antenna wires built into the robot. These wires naturally tend to align with the polarization direction of incoming light. By changing the light's polarization, the researchers can control which direction the nanorobot faces. At the same time, photon recoil continues to propel it forward, creating a steering system that works somewhat like the directional control used in larger vehicles.
Nanorobots Act as "Microscopic Cleaners".
In a recent development, "In essence, we have built a light-driven nanorobot that can track down and collect bacteria," claims Jin Qin, lead experimental scientist of the study. "By simplifying the design, we reached a size at which these robots can operate directly in the microbial world - almost like microscopic cleaning devices.".
The robots are also highly maneuverable. They can make extremely fast 90° turns, helping them scan broad areas of a sample in an organized and efficient way. They can also selectively capture, carry, and release substantial numbers of bacteria.
Under controlled laboratory conditions, this means the nanorobots can effectively "clean" microscopic environments. They gather bacteria from one area and deposit them at specifically chosen locations.
Sources indicate that "This is a striking example of how light can be used not only to observe the microscopic world, but also to actively shape it," adds Bert Hecht. "The idea of tiny robotic cleaners may sound futuristic, but we are already demonstrating the physical principles that make it possible.".
The robots remain fully maneuverable even while carrying larger groups of bacteria, although their speed decreases somewhat under the added load. That ability to keep functioning while transporting larger bacterial clusters points to possible future uses in microbiology, biomedical research, and precise manipulation of materials at the microscopic scale.
Recent findings suggest that materials provided by University of Würzburg. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Latest Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #11644. Industry News: Tiny Agents: an MCP-powered agent in 50 lines of code 📰 #22117. Industry News: SSdH "renegotiates light" in Melbourne warehouse transformation 📰 #19353. Industry News: Astronomers confirm a tiny upcoming moon is orbiting Earth, and it'll stick around for the holidays
General
⚖️ Neutral
🌐 Hugging Face
#11413. Industry News: DeepMath: A lightweight math reasoning Agent with smolagents
📅 04 Dec 2025 • ⏱️ 5m • 📚 Deep Dive (930 w)
Industry News: DeepMath: A lightweight math reasoning Agent with smolagents
📅 04 Dec 2025 | ⏱️ 5 min read (930 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~5 mins left to finish
📖 0% read
💡 Key Takeaways
- DeepMath is an aligned math reasoning agent built on Qwen3-4B Thinking and fine-tuned with GRPO (Group Relative Policy Optimization).
- We evaluate DeepMath on four math datasets: MATH500, AIME, HMMT, and HLE, and show that:.
- 🤖 The math agent alone reduces output lengths by up to 66%, while often improving accuracy.
DeepMath is an aligned math reasoning agent built on Qwen3-4B Thinking and fine-tuned with GRPO (Group Relative Policy Optimization). Instead of verbose text, the model emits tiny Python snippets for intermediate steps, runs them in a secure sandbox, and folds the results back into its reasoning, reducing errors and output length. The agent is implemented using the smolagents library.
We evaluate DeepMath on four math datasets: MATH500, AIME, HMMT, and HLE, and show that:.
🤖 The math agent alone reduces output lengths by up to 66%, while often improving accuracy.
⚡ GRPO training improves the agent performance even further, in almost all benchmarks.
👉 Code and evaluation scripts: https://github.com/IntelLabs/DeepMath 👉 Model: https://huggingface.co/Intel/deepmath-v1.
Large language models (LLMs) have advanced reasoning capabilities, but mathematical problem-solving remains challenging; chain-of-thought traces can be lengthy and prone to arithmetic mistakes. Recent works[^1][^2] demonstrate that small models can reach strong performance, and other studies[^3] investigate tool use to improve reliability. What those papers generally do not emphasize is reducing trace verbosity or explicitly training models to prefer short, computation-oriented traces executed in a constrained, auditable environment.
Offload deterministic computation to a safe executor.
Train models to prefer concise, computation-oriented traces over verbose text.
DeepMath tackles this by combining a small Python executor with a fine-tuned LLM, enabling concise, computation-driven reasoning. The model learns to generate short Python snippets, which are executed in a sandbox and reintegrated into the context. GRPO fine-tuning encourages this behavior by rewarding correctness and encouraging shorter outputs.
Figure 1: The vLLM client and server were modified to use the DeepMath agent in generating the candidates, while using the vLLM backend.
Agent Interface: During inference, the model can output normal tokens or special agent calls containing Python snippets.
Execution: Snippets run in a sandboxed environment with strict safety constraints (no file I/O, no network, timeouts).
Concision: Replace multi-line textual calculations with short, focused snippets.
Determinism & Safety: Enforce strict execution limits.
Interpretability: Snippets are readable and auditable.
Figure 2: Output example where python code is generated, evaluated and the answer is inserted into the trace and used for context.
We fine-tune the model using GRPO, a reward-based optimization that balances:.
Accuracy Reward: +1 for correct answers.
Using code snippets: +1 for generating code snippets, weighted 10:1 vs. the accuracy reward.
Length reduction: shorter lengths are encouraged by limiting the GRPO completion candidates to 5k tokens.
Temperature Scheduling: We implemented linear temperature scheduling (T=1.2 → T=0.7) to balance exploration and stability during training. This approach aims to enhance experimentation during the initial training phases, subsequently reducing the temperature as we refine our proficiency in the skill.
In-context Learning: we include 4 solved examples where the trace contains agent calls and executor outputs, so the model learns the syntax and the call/response pattern.
According to recent reports, dataset: we used the Tool-Integrated Reasoning (TIR) subset of the OpenMathReasoning dataset. Note that GRPO only uses the problem, not the solution in the data. This dataset was chosen to ensure the problems benefit from the external tool.
Industry observers note that we benchmarked DeepMath against baselines on four datasets. Metrics include:.
majority@16: robustness across samples, as used in previous math reasoning works, see references.
We compare a baseline configuration (Qwen3-4B-Thinking-2507, no agenting) with our DeepMath model. As ablation, we evaluate the agentic framework we developed running with the untrained Qwen3 model, denoted by +Agent. Additionally, we examine whether the GRPO training (for agentic use) improves non-agentic inference, denoted by +GRPO. Thus the two ablations are independent, not additive.
We observe the agentic inference reduces output lengths, with mixed accuracy results. The DeepMath model is both GRPO-trained and run in agentic mode, and highlights the highest accuracy with shortened traces. We conclude both GRPO training and agentic inference are needed for best results.
Key Insight: DeepMath reduces output length by up to 66% while improving accuracy on challenging datasets.
Accuracy: Offloading computation reduces arithmetic errors.
Efficiency: Shorter outputs mean faster inference and easier interpretability.
Safety: Sandbox execution mitigates risks of running arbitrary code.
In a recent development, deepMath demonstrates a practical and lightweight way to combine a small executor with an LLM and to train the model to prefer short, computation-driven traces. Offloading deterministic computation reduces arithmetic and numerical errors and shortens traces, and GRPO fine-tuning further encourages concise, correct answers. The result is a more accurate and more interpretable math-solving agent without requiring a massive model or heavyweight external tools.
Sources indicate that check out the GitHub repo and share your feedback! Contributions welcome. 🚀.
If you use DeepMath in your research, please cite:.
Scope: we focused on a small model and on mathematical reasoning.
Generalization: evaluated on contest-style math; results may not transfer to open-ended mathematical creativity or formal proofs.
Industry observers note that executing generated code is inherently risky. DeepMath uses strict sandboxing and resource limits, but any deployment should carefully manage attack surfaces and enforce rate limits.
According to recent reports, [1] Luo, Michael, Sijun Tan, Justin Wong, et al. 2025. “DeepScaleR: Surpassing O1-Preview with a 1.5B Model by Scaling RL.” https://pretty-radio-b75.notion.site/DeepScaleR-Surpassing-O1-Preview-with-a-1-5B-Model-by-Scaling-RL-19681902c1468005bed8ca303013a4e2.
[2] Liu, Mingjie, Shizhe Diao, Ximing Lu, et al. 2025. “ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models.” arXiv:2505.24864. Preprint, arXiv, May 30. https://doi.org/10.48550/arXiv.2505.24864.
[3] Moshkov, Ivan, Darragh Hanley, Ivan Sorokin, et al. 2025. “AIMO-2 Winning Solution: Building State-of-the-Art Mathematical Reasoning Models with OpenMathReasoning Dataset.” arXiv:2504.16891. Preprint, arXiv, April 23. https://doi.org/10.48550/arXiv.2504.16891.
Recent findings suggest that is it possible to use LLM to study and research math topics? All of the steps could be correct or incorrect depending on the variation of the generated output ??

General
⚖️ Neutral
🌐 Dexerto
#11412. DJ Khaled is giving Xbox players doctor’s notes so they can skip work for GTA 6
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (480 w)
DJ Khaled is giving Xbox players doctor’s notes so they can skip work for GTA 6
📅 16 Nov 2026 | ⏱️ 2 min read (480 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Xbox has teamed up with DJ Khaled to give gamers an excuse to skip work and spend the day playing video games, complete with personalized doctor’s notes.
- According to recent reports, the rapper and producer has taken on the role of “Dr.
- Revealed on November 16, the campaign allows fans to generate their own doctor’s notes online, although Xbox has made it clear that the documents aren’t medically certified and won’t necessarily convince employers to approve a day off.
Xbox has teamed up with DJ Khaled to give gamers an excuse to skip work and spend the day playing video games, complete with personalized doctor’s notes.
According to recent reports, the rapper and producer has taken on the role of “Dr. XBOX” as part of a new promotional campaign encouraging players to take time off during a major week for gaming.
Revealed on November 16, the campaign allows fans to generate their own doctor’s notes online, although Xbox has made it clear that the documents aren’t medically certified and won’t necessarily convince employers to approve a day off.
Players interested in getting a personalized doctor’s note can visit the website, where Xbox has rolled out a dedicated website for the promotion.
The notes are presented as prescriptions from DJ Khaled, who claims to have discovered a widespread condition called “Vitamin G deficiency” after observing symptoms including controller cramps, late-night gaming dreams, and excitement surrounding new releases.
Recent findings suggest that “After extensive research (and a whole lot of gaming), I’ve come to one conclusion: there’s a serious case of Vitamin G deficiency around the world. And I’m here to tell you that the cure is simple,” Khaled explained.
Industry observers note that A massive week in gaming is coming, and there's a serious case of Vitamin G deficiency around the world. Luckily, Dr. XBOX has the cure – it’s time to take the day off and play XBOX.https://t.co/MpwW4SM87V.
The musician encourages players to use their personalized notes however they like, whether that means displaying them at home, sharing them with friends, or showing them to their bosses.
Recent findings suggest that “Your very own prescription for more gaming. Put it on your fridge. Show your boss. Send it to your group chat. Let the people know that Dr. XBOX has spoken,” he said.
However, the promotion comes with a disclaimer confirming that the notes have no medical validity.
KFC is hosting a fake funeral so GTA 6 fans can take the day off.
Australia’s government explains your rights to take GTA 6 launch day off.
US Army battalion reportedly offers troops days off to play GTA 6 if they re-enlist.
“Doctor’s note is not real. XBOX is not responsible if your employer doesn’t have a sense of humor. Please game responsibly,” the disclaimer reads.
Although Xbox’s announcement doesn’t mention GTA 6, the promotion comes as tons of players strategy on booking off for Rockstar’s highly-anticipated title. Even KFC is planning a fake funeral to give fans the excuse to skip work and play GTA 6 instead.
Khaled also acknowledged that his qualifications aren’t legitimate, joking that his degree from Xbox University is unofficial and his medical credentials are questionable.
Despite the warning, Xbox is encouraging players to participate in the campaign and dedicate some time to gaming without the distractions of work or other responsibilities.

General
⚖️ Neutral
🌐 Hugging Face
#11411. Latest Update: Introducing swift-huggingface: The Complete Swift Client for Hugging Face
📅 05 Dec 2025 • ⏱️ 3m • 📚 Deep Dive (542 w)
Latest Update: Introducing swift-huggingface: The Complete Swift Client for Hugging Face
📅 05 Dec 2025 | ⏱️ 3 min read (542 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Today, we're announcing swift-huggingface, a new Swift package that provides a complete client for the Hugging Face Hub.
- You can start using it today as a standalone package, and it will soon integrate into swift-transformers as a replacement for its current HubApi implementation.
- When we released swift-transformers 1.0 earlier this year, we heard loud and clear from the community:.
Today, we're announcing swift-huggingface, a new Swift package that provides a complete client for the Hugging Face Hub.
You can start using it today as a standalone package, and it will soon integrate into swift-transformers as a replacement for its current HubApi implementation.
When we released swift-transformers 1.0 earlier this year, we heard loud and clear from the community:.
swift-huggingface is a ground-up rewrite focused on reliability and developer experience. It provides:.
One of the biggest improvements is how authentication works. The TokenProvider pattern makes it explicit where credentials come from:.
The auto-detection follows the same conventions as the Python huggingface_hub library:.
This means if you've already logged in with hf auth login, swift-huggingface will automatically find and use that token.
Building an app where users sign in with their Hugging Face account? swift-huggingface includes a complete OAuth 2.0 implementation:.
The OAuth manager handles token storage in Keychain, automatic refresh, and secure sign-out. No more manual token management.
Downloading large models is now straightforward with proper progress tracking and resume support:.
If a download is interrupted, you can resume it:.
For downloading entire model repositories, downloadSnapshot handles everything:.
The snapshot function tracks metadata for each file, so subsequent calls only download files that have changed.
Remember the second problem we mentioned? "No shared cache with the Python ecosystem." That's now solved.
swift-huggingface implements a Python-compatible cache structure that allows seamless sharing between Swift and Python clients:.
The cache location follows the same environment variable conventions as Python:.
You can also use the cache directly:.
To prevent race conditions when multiple processes access the same cache, swift-huggingface uses file locking (flock(2)).
Here's what downloading a model snapshot looked like with the old HubApi:.
And here's the same operation with swift-huggingface:.
The API is similar, but the implementation is completely different — built on URLSession download tasks with proper delegate handling, resume data support, and metadata tracking.
Recent findings suggest that but wait, there's more! swift-huggingface contains a complete Hub client:.
According to recent reports, and that's not all! swift-huggingface has everything you need to interact with Hugging Face Inference Providers, giving your app instant access to hundreds of machine learning models, powered by world-class inference providers:.
Check the README for a full list of everything that's supported.
We're actively working on two fronts:.
Integration with swift-transformers. We have a pull request in progress to replace HubApi with swift-huggingface. This will bring reliable downloads to everyone using swift-transformers, mlx-swift-lm, and the broader ecosystem. If you maintain a Swift-based library or app and want help adopting swift-huggingface, reach out — we're happy to help.
Recent findings suggest that faster downloads with Xet. We're adding support for the Xet storage backend, which enables chunk-based deduplication and significantly faster downloads for large models. More on this soon.
Add swift-huggingface to your project:.
Recent findings suggest that we'd love your feedback. If you've been frustrated with model downloads in Swift, give this a try and let us know how it goes. Your experience reports will help us prioritize what to improve next.
It has been revealed that thanks to the swift-transformers community for the feedback that shaped this project, and to everyone who filed issues and shared their experiences. This is for you. ❤️.
General
⚖️ Neutral
🌐 Sciencedaily
#11410. Scientists turn DNA into a memory device that uses 100x less power
📅 17 Aug 2026 • ⏱️ 6m • 📚 Deep Dive (1205 w)
Scientists turn DNA into a memory device that uses 100x less power
📅 17 Aug 2026 | ⏱️ 6 min read (1205 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- DNA serves as the genetic blueprint for every living organism, but it is also an extraordinarily dense way to store information.
- In a recent development, the challenge has been finding a way to make biological DNA function effectively alongside electronic materials.
- The work, published in Advanced Functional Materials and the subject of a patent application, relies on two key components.
DNA serves as the genetic blueprint for every living organism, but it is also an extraordinarily dense way to store information. A single gram can hold about 215 million gigabytes of data. Bringing that remarkable storage capacity into electronics could lead to more efficient data centers, faster processing and systems capable of handling increasingly complex information.
In a recent development, the challenge has been finding a way to make biological DNA function effectively alongside electronic materials. Penn State researchers have now developed an approach designed to overcome that incompatibility.
The work, published in Advanced Functional Materials and the subject of a patent application, relies on two key components. One is synthetic DNA, made from commercially available, chemically engineered molecules arranged into short genetic sequences tailored for specific electronic requirements. The other is crystalline perovskite, a semiconductor already used in technologies including solar cells, lasers and data storage devices.
Recent findings suggest that "Biology and electronics are different domains," stated Kavya S. Keremane, co-corresponding author and postdoctoral researcher in materials science and engineering at Penn State. "Bridging these two fields required developing an entirely fresh materials platform that allows them to function seamlessly together. By combining the information storage capabilities of DNA with the exceptional electronic properties of perovskite semiconductors, we created a bio-hybrid system that fundamentally changes how low-power memory devices can be designed.".
Building a Low Power Memory Device.
According to recent reports, using these materials, the team created a memory resistor, known as a "memristor," that operates with very little energy. Unlike ordinary resistors, which maintain a set resistance to electrical current in devices ranging from cell phones to space shuttles and lose their stored information when power disappears, memristors can preserve a record of previous electrical activity. They can remember the direction in which current previously flowed even after the power source is removed.
Sources indicate that that ability allows information to be stored and processed in the same place, resembling the way neurons function in the brain. Such an arrangement could support more simultaneous and sophisticated forms of data processing. According to the researchers, however, practical commercial systems would still require enough storage capacity and electrical power to become costly and inefficient without DNA's ability to pack enormous amounts of information into a very small space while consuming little energy.
"As the demand for artificial intelligence (AI) grows, we need a new strategy for low-power, high-storage devices," stated Bed Poudel, co-corresponding author and research professor of materials science and engineering at Penn State.
Recent findings suggest that poudel said AI and other emerging technologies are expected to depend increasingly on neuromorphic computing, which is designed to operate more like the human brain. Such systems can evaluate multiple inputs at once while making decisions informed by previous experiences and future priorities.
"Usually, it takes more power to store more information. Our device, however, consumes 100 times less power and the storage capacity is higher than traditional storage devices, like flash drives.".
Engineering DNA to Conduct Electricity.
To construct the device, the researchers added silver nanoparticles to a layer of customized DNA sequences -- specially designed to be of certain compositions and lengths -- that was integrated with thin films of perovskite.
Sources indicate that this technique, called "doping," involves introducing a small amount of another material to produce specific properties. In this case, adding the silver nanoparticles allowed the DNA to conduct electricity while also helping its molecular units line up in a more orderly arrangement.
According to recent reports, synthetic DNA offered another important advantage over natural DNA. Unlike natural DNA -- long, entangled strands that behave like wet spaghetti when handled -- short and rigid pieces of synthetic DNA can be arranged with much greater precision at extremely small scales.
It has been revealed that according to co-author Neela H. Yennawar, research professor and director of the Penn State Huck Institutes of the Life Sciences' Biomolecular Interactions Core Facility, molecularly engineered DNA can provide structural organization, adjustable electrical conductivity and functional control that natural DNA cannot achieve when incorporated into thin films.
It has been revealed that "We can computationally determine exactly which sequences we need and how long they should be, and then we can rationally design them with synthetic DNA," Yennawar said. "These structures can be systematically doped with silver and other ions and engineered to interface seamlessly with perovskites -- transforming DNA from a biological macromolecule into a programmable, multifunctional nanomaterials platform.".
DNA and Perovskite Work Better Together.
When combined, the silver-doped DNA and perovskite formed bio-hybrid pathways that directed the flow of electrical current through the device.
The researchers found that electrons moved reliably when they applied less than 0.1 volt -- for comparison, standard U.S. outlets have 120 volts -- and the device responded predictably when the direction of the current was changed.
The carefully designed DNA structures, combined with the perovskite, also helped make the device unusually stable. According to the team, it continued operating consistently at temperatures approaching 250 degrees Fahrenheit and remained functional at room temperature for more than six weeks, substantially exceeding the performance standards of existing perovskite-based memory storage devices.
The researchers also reported that the new system could perform the same memory function as comparable technologies while consuming only one-tenth as much power. That level of efficiency could make the approach especially attractive for future electronics designed to handle large amounts of information with lower energy demands.
"Using just the DNA or just perovskite alone did not produce near as robust a result as the combination," Keremane said. "It's this combination that enables a very high memory storage density that requires very little power.".
A Newly introduced Direction for Bio-Inspired Electronics.
The team now plans to improve the technology further and explore additional uses for bio-inspired electronic systems.
"Nature has the solution -- we just have to find it and apply it," Poudel said. "This work of integrating DNA into electronics to do amazing things gives a glimpse into what is possible.".
In addition to Keremane, Yennawar and Poudel, other Penn State co-authors include co-corresponding author Luyao Zheng, postdoctoral research in materials science and engineering; Haodong Wu, doctoral student in materials science and engineering; Jiamao Zheng, who was a master's student in materials science and engineering at the time of research and has since graduated from Penn State; Shashank Priya, who was a professor of materials science and engineering at the time of research; and Chiranth C. Ravi, who was a master's student in the Huck Institutes of the Life Sciences at the time of research and has since graduated from Penn State. Abhinav Gorthy and co-corresponding author Rashmi Jha, chemical engineering and materials science, University of Minnesota, also contributed.
The U.S. National Science Foundation, the National Institutes of Health, Penn State and the University of Minnesota supported this research.
According to recent reports, materials provided by Penn State. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #23543. AMD attacks Nvidia's FP64 emulation at SC26, touts native double-precision on Instinct MI430X — claims Ozaki schemes fit less than 10% of HPC workloads and triple memory use and emulated FP64 is a poor fit for many HPC workloads 📰 #22585. Scientists find hidden driver of aging and a simple amino acid that fights memory loss in mice 📰 #22535. Scientists discover mysterious “lonely” brain waves linked to memory loss
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11409. Codex is Open Sourcing AI models
📅 11 Dec 2025 • ⏱️ 13m • 📚 Deep Dive (2552 w)
Codex is Open Sourcing AI models
📅 11 Dec 2025 | ⏱️ 13 min read (2552 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~13 mins left to finish
📖 0% read
💡 Key Takeaways
- Building on our work to get Claude Code to train open source models, we are now getting Codex to go further.
- This tutorial dives even deeper and shows you how it works and how to use it yourself.
- Codex uses AGENTS.md files to accomplish specialized tasks, whilst Claude Code uses 'Skills'.
Building on our work to get Claude Code to train open source models, we are now getting Codex to go further. We gave Codex access to the Hugging Face Skills repository, which contains skills for Machine Learning and AI tasks such as training or evaluating models. With HF skills, a coding agent can:.
This tutorial dives even deeper and shows you how it works and how to use it yourself. So let's get started.
Codex uses AGENTS.md files to accomplish specialized tasks, whilst Claude Code uses 'Skills'. Fortunately, 'HF-skills' is compatible with both approaches and works with major coding agents like Claude Code, Codex, or Gemini CLI.
With HF-skills, you can tell Codex something like:.
In a recent development, the model trains on Hugging Face GPUs while you do other things. When it's done, your fine-tuned model appears on the Hub, ready to use.
Sources indicate that this isn't a toy demo. The extension supports the same training methods used in production: supervised fine-tuning, direct preference optimization, and reinforcement learning with verifiable rewards. You can train models from 0.5B to 7B parameters, convert them to GGUF for local deployment, and run multi-stage pipelines that combine different techniques.
According to recent reports, we explored this single prompt approach in the Claude Code tutorial. However, we can now go further and get OpenAI Codex to do end-to-end Machine Learning experiments. For example, Codex should be able to monitor progress, evaluate the models, and maintain an up to date training report. This will allow engineers to delegate experiments to Codex and review reports in a more hands-off way. It will also allow Codex to make more decisions on its own based on the training report and evaluation results.
It has been revealed that codex is OpenAI's AI coding agent included in ChatGPT Plus, Pro, Business, Edu, and Enterprise plans. Codex brings AI assistance directly into your development workflow.
See the Codex documentation for installation and setup instructions.
The Hugging Face Skills repository includes an AGENTS.md file that Codex automatically detects and uses.
Sources indicate that codex will automatically detect the AGENTS.md file in the repository and load the skills. You can verify the instructions are loaded with:.
See the Codex AGENTS guide for more details.
Authenticate with Hugging Face using the hf auth login command and a write-access token from hf.co/settings/tokens:.
Codex supports MCP (Model Context Protocol) servers. You can configure the Hugging Face MCP server for additional Hub integration capabilities. You can add the Hugging Face MCP server to your Codex configuration by adding the following to your ~/.codex/config.toml file:.
Configure Hugging Face MCP Server to use relevant MCP servers like Jobs in the Settings page.
Then start Codex and you'll be directed to the Hugging Face MCP authentication page.
Let's walk through a complete example. We'll fine-tune a small model to improve code solving abilities, using the open-r1/codeforces-cots dataset and the openai_humaneval benchmark.
Industry observers note that the open-r1/codeforces-cots dataset is a dataset of codeforces problems and solutions. It is a good dataset for instruction tuning a model to solve hard coding problems.
According to recent reports, start Codex in your project directory. Then give it a simple and clear instruction:.
Recent findings suggest that you'll notice that we've gone a bit further than the single prompt approach in the Claude Code tutorial. We've added more details to the instruction but also added more steps to the experiment.
Why not try iterating on this experiment yourself with more open ended questions like "What is the best model for code solving abilities?" or "What is the best dataset for code solving abilities?".
According to recent reports, codex analyzes your request and prepares a training configuration. For a 0.6B model on a demo dataset, it selects t4-small—enough GPU for this model size and the cheapest option available. Codex will start a new report at training_reports/--.md which looks like the example below. As the experiment progresses, Codex will update the report with the latest information and each run report.
As the experiment progresses, Codex will enhancement the report with the latest information and each run report. You can view the report in training_reports/--.md file.
For example, codex will patch the title of the report to sft-a10g - TBD - In Progress when the experiment is in progress.
It can link to the run logs and trackio logs.
And it will update the evaluation results in a combined table.
Sources indicate that dataset format and processing is the most common source of training failures and usually a significant amount of work is done in the training script. Codex can validate datasets before the job starts and either define a configuration for TRL or process the dataset separately.
In most cases, Codex will validate the dataset before training, but you can always check the dataset validation before submitting the job.
Codex runs a quick inspection on CPU (fractions of a penny) and reports:.
If your dataset needs transformation, Codex can preprocess the dataset before training.
Codex will preprocess the dataset and upgrade the training script with the fresh configuration.
Before Codex submits anything, you'll see the configuration:.
This is your chance to adjust anything. Change the output repo name, pick different hardware, or ask Codex to modify training parameters. Once you approve, the job is submitted.
For example, you can ask Codex to try a test run:.
In a recent development, after submission, you can track progress using the training report and get links to the run logs and trackio logs. You can also tell Codex to fetch the logs, summarize progress, and revision the training report. As codex runs the jobs, it will update the training report with the latest information.
Sources indicate that trackio will monitor the training and evaluation scores for you by running evaluation jobs and selecting the best checkpoint. If you want to know the status of the training job, you can ask Codex to fetch the logs and summarize progress in a table.
You can also monitor the training loss in real-time.
Codex fetches the logs and summarizes progress.
Click here for an example Trackio dashboard with some completed runs.
When training completes, your model is on the Hub:.
Transformers is great as a standard, and we can easily convert the trained model to GGUF for local deployment. This is because the training skill contains instructions and support scripts to convert models to GGUF.
Industry observers note that codex then converts to GGUF, applies quantization, and pushes to the Hub. If we trained a LoRA adapter, it will merge the LoRA adapters into the base model.
It has been revealed that codex selects hardware based on your model size, but understanding the tradeoffs helps you make better decisions. You can use the Hardware Guide to see the hardware options and costs, but codex will do it for you and select the best option.
For tiny models under 1B parameters, t4-small works well. These models train promptly—expect $1-2 for a full run. This is perfect for educational or experimental runs.
For small models (1-3B), step up to t4-medium or a10g-small. Training takes a few hours and costs $5-15.
In a recent development, for medium models (3-7B), you need a10g-large or a100-large with LoRA. Full fine-tuning doesn't fit, but LoRA makes these very trainable. Budget $15-40 for production.
For large models (7B+), this HF skills job is not suitable for this scale yet. But stay tuned because we are working on it!
We've shown that Codex can handle the full lifecycle of model fine-tuning: validating data, selecting hardware, generating scripts, submitting jobs, monitoring progress, and converting outputs.
Industry observers note that the extension is open source. You can extend it, customize it for your workflows, or use it as a starting point for other training scenarios.
Is this possible to do on local infrastructure without having paid tier?
In a recent development, this post is really helpful for me. I didn’t know AI agents could handle tasks like training and deployment so easily. After reading this, I’m thinking about applying an AI agent on my own website too to improve how information is organized and delivered for consumers: https://ebiharbhumi.com. Thanks for sharing such a useful guide!
Recent findings suggest that really interesting update on how Codex is integrating with HF-skills for advanced AI workflows. Automating fine-tuning, evaluation, and deployment tasks can make machine learning development much more efficient. I also found tools like aesthetic font generator useful for creating stylish text designs for online projects and social content.
This is a great step toward smarter AI coding agents. The ability to validate datasets, monitor training with Trackio, and deploy models directly through Codex sounds incredibly practical for developers. For users interested in gaming customization, toca boca mod apk resources are also becoming very popular these days.
Industry observers note that this is a massive step forward for workflow automation. Fine-tuning models directly through a coding agent like Codex or Claude completely removes the boilerplate headache. I'm at the moment looking into how these HF skills can be adapted for automated mobile app validation specifically for generating test cases around custom Android builds and modified packages saasswitcher saas spend calculators. Managing assets for complex setups like Toca Boca Mod Apps manually takes hours, but wrapping a fine-tuned agent around the repository to validate file structures and asset dependencies could be a game-changer. Looking forward to seeing more domain-specific skills added to the repo!
According to recent reports, this is a massive step forward for workflow automation. Fine-tuning models directly through a coding agent like Codex or Claude completely removes the boilerplate headache. I'm currently looking into how these HF skills can be adapted for automated mobile app validation specifically for generating test cases around custom Android builds and modified packages Khaleej Guides UAE. Managing assets for complex setups like Toca Boca Mod Apps manually takes hours, but wrapping a fine-tuned agent around the repository to validate file structures and asset dependencies could be a game-changer. Looking forward to seeing more domain-specific skills added to the repo!
Recent findings suggest that login or register on Pak Club Game Pakistan. Play online, join live games, earn PKR, access free & paid PakClub games, and enjoy membership perks.
According to recent reports, nice guide! Clear and easy to follow. I also like using fancy text generator when formatting project names, demos, or profile descriptions—it adds a nice touch without much effort.
Really enjoyed this article. It's great to see more practical resources for people working with AI. For project docs, demos, or even profile customization, I sometimes use letras bonitas para copiar y pegar to make text a bit more readable and visually appealing.
Thanks for sharing this detailed guide about HF Skills and Codex. The explanation of practical AI development workflows and coding skills was very useful. For people interested in creating stylish text for websites and social media, a cambiador de letraa can also be a handy tool for generating different text styles.
Integrating Hugging Face Skills with autonomous coding agents makes model evaluation, RL alignment, experiment reporting, and GGUF quantization drastically easier to execute right from the CLI.
Off-Topic Utility: Stepping away from machine learning setups to tackle physical workshop builds or home renovation projects? Calculate your material volume, bag counts, and yardage easily with a Concrete Measurement Calculator.
Sources indicate that utforsk vårt utvalg av Signerte fotballdrakter. , ideelle for samlere og fotballentusiaster som ønsker å eie et unikt og autentisk minne fra favorittlagene og spillerne. Disse draktene er ekte samleobjekter som fanger de mest minneverdige øyeblikkene på banen, og de kan være perfekte gaver eller tillegg til enhver fotballsamling. Med et bredt utvalg av signerte drakter, kan du finne noe som passer din lidenskap og interesse for sporten. Ta steget i dag og eier en del av fotballhistorien!
According to recent reports, integrating Hugging Face skills into coding agents like Codex is a game-changer for automating ML workflows and model fine-tuning. Streamlining complex tasks like RL alignment and quantization saves developers and data teams countless hours.
According to recent reports, whether automating technical AI experiments or managing personal administrative tasks such as reviewing public sector compensation and salary structures via http://nhspayscale.co.uk having access to structured tools and accurate resources makes complex management effortless. Great tutorial on expanding agent capabilities!
Giving coding agents direct access to specialized skill repositories like Hugging Face is a massive step forward for automated ML workflows. Having an agent handle complex tasks like RL alignment, live metric tracking, and GGUF model quantization automatically saves developers countless hours of setup.
It almost feels like working alongside a technical Letras Diferentes when an AI seamlessly evaluates checkpoints and manages model deployments end-to-end.
According to recent reports, giving coding agents direct access to specialized skill repositories like Hugging Face is a massive step forward for automated ML workflows. Having an agent handle complex tasks like RL alignment, live metric tracking, and GGUF model quantization automatically saves developers countless hours of setup.
It almost feels like working alongside a technical magician when an AI seamlessly evaluates checkpoints and manages model deployments end-to-end.
This tutorial is a great breakdown of how developer tooling is evolving toward full-stack AI automation. Thanks for sharing this step-by-step guide!
Equipping coding agents like Codex with pre-built skill repositories is a massive leap forward for AI workflow automation! The ability to handle real-time metrics evaluation and export models directly to GGUF makes fine-tuning so much faster. I’ve been testing similar agent workflows for building practical utility tools—like automated notification bots that run a web query or NOL card balance for commuters. Giving LLMs structured tool definitions and Hugging Face skills makes these multi-step API and browser automation tasks significantly more reliable. Great tutorial!
In a recent development, building on our work to get Claude Code to train open source models, we are now getting Codex to go further. We gave Codex access to the Hugging Face Skills repository, which contains skills for Machine Learning and AI tasks such as training, evaluating models, or analyzing word meanings in complex datasets.
In a recent development, really clean workflow—automating RL alignment and Trackio metric reviews takes so much repetitive overhead out of fine-tuning open-source models. Whenever I'm comparing benchmark eval scores across checkpoints or calculating standard deviations and confidence intervals from experiment logs, using a Online TI-84 Plus CE calculator right in the browser is a super fast way to double-check the math before exporting to GGUF. Thanks for walking through the setup!
Recent findings suggest that giving Codex direct access to HF Skills for end-to-end fine-tuning and Trackio metric reviews is a huge workflow upgrade—especially automating the GGUF quantization and Hub publishing steps after checkpoint evaluation. When I run iterative fine-tuning experiments on domain-specific datasets, I usually schedule a 30-day benchmark check to test for model drift against fresh validation data; keeping a quick browser utility handy to check the exact date 30 days from today makes logging follow-up evaluation milestones in my experiment tracker super straightforward. Great walkthrough!
It has been revealed that creative tools make digital work more engaging and personalized. For anyone looking to customize text for social media, usernames, or online projects, Fancy Fonts offers a simple way to generate stylish text and decorative font styles that can be copied and pasted anywhere.

General
⚖️ Neutral
🌐 Dexerto
#11408. Latest Update: Brandon Buckingham cancels all video trips over fears for his life as health worsens
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (416 w)
Latest Update: Brandon Buckingham cancels all video trips over fears for his life as health worsens
📅 16 Nov 2026 | ⏱️ 2 min read (416 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- YouTuber Brandon Buckingham has canceled all upcoming filming trips and collaborations after revealing his health is deteriorating, warning that continuing to push himself could cost him his life.
- The content creator, known for his documentary-style videos and interviews, has been battling serious medical problems since 2025, when he was hospitalized with multiple organ failure.
- Although Buckingham returned to making YouTube videos earlier this year, he revealed in a November 16 Instagram Story that his condition has worsened and he has been hospitalized again.
YouTuber Brandon Buckingham has canceled all upcoming filming trips and collaborations after revealing his health is deteriorating, warning that continuing to push himself could cost him his life.
The content creator, known for his documentary-style videos and interviews, has been battling serious medical problems since 2025, when he was hospitalized with multiple organ failure.
Although Buckingham returned to making YouTube videos earlier this year, he revealed in a November 16 Instagram Story that his condition has worsened and he has been hospitalized again.
“I regret to inform you I have cancelled all video trips and collaborations for the foreseeable future,” he wrote.
It has been revealed that “My health is bad and getting worse. I fear if I continue pushing myself I will lose my life.”.
Buckingham went on to detail the frightening symptoms he is experiencing, including purple hands, swollen feet, and persistent vomiting.
“I was just hospitalized AGAIN. My hands are purple, my feet are swollen, I am constantly vomiting. I can’t let this go on any longer,” he explained.
Despite the concerning upgrade, the YouTuber insisted he is taking steps to improve his condition and remains determined to recover.
“But don’t worry, I am being very proactive, and I WILL bounce back,” he added.
The announcement comes just days after Buckingham uploaded a new documentary filmed in India on November 12, titled India’s City of Trash | Inside the Most Polluted Town on Earth.
The video follows Buckingham and fellow creator Turkey Tom as they explore life around a massive landfill in Delhi.
TikToker FunBucketKustoms notes he briefly died & “can’t walk anymore” after head-on moped crash.
YouTuber Brandon Buckingham shares recovery upgrade after life-threatening illness.
Brandon Buckingham pleads for help after almost dying amid heart failure diagnosis.
Buckingham’s latest health scare comes nearly a year after he was rushed to intensive care with multiple organ failure in November 2025.
At the time, he revealed that his heart, lungs, liver, and kidneys were failing, with doctors treating him for sepsis, pneumonia, and other serious complications.
His condition prompted an outpouring of support, with MrBeast and thousands of fans helping raise more than $300,000 toward his medical expenses.
Sources indicate that in January 2026, Buckingham shared an encouraging recovery revision, revealing that his liver, kidneys, and pancreas had recovered. However, he mentioned he was still experiencing heart failure and permanent lung damage.
Buckingham has not disclosed the cause of his latest deterioration or indicated when he expects to resume filming.
🔗 Related Articles
📰 #21963. After Hitting Rock Bottom, an Army Veteran Went for a Run With a Proposal to End His Life. Then He Heard a Familiar Military Command He Couldn’t Ignore. 📰 #21403. Industry News: How a 20-Year-Old Texas Climber Lost His Life on the Matterhorn 📰 #17627. Losing Weight in Your 50s May Protect Your Heart Health Later in Life
General
⚖️ Neutral
🌐 Sitepoint
#11407. Building Reliable Product Emails Into Your Application
📅 09 Nov 2026 • ⏱️ 5m • 📚 Deep Dive (1017 w)
Building Reliable Product Emails Into Your Application
📅 09 Nov 2026 | ⏱️ 5 min read (1017 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~5 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- Recent findings suggest that weekly.
- In a recent development, 7 Day Free Trial.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Recent findings suggest that weekly. Free. One click to leave.
In a recent development, 7 Day Free Trial. Cancel Anytime.
A password reset email is part of your login flow. An invoice notification is part of your billing experience. Yet development teams often treat these messages as background tasks: render a template, call a sending API, and move on. That approach leaves an important part of the product experience untested until a user cannot complete the action they started.
Testing the application interface alone leaves a gap. A successful request to an email provider does not establish that the recipient can find the message, understand it, or use its links. Product emails need explicit success criteria, useful diagnostic records, and recovery options when something fails.
It has been revealed that A reliable workflow combines application tests, controlled mailbox checks, and pre-send diagnostics for authentication and inbox placement. A comparison of available tools can help you identify which checks your existing setup covers and where additional testing would be useful. The goal is to investigate specific gaps rather than add another service without a clear purpose.
Start with the action the recipient needs to complete. A weekly activity summary can tolerate a delay that would make a sign-in code useless. An invoice needs accurate amounts and a clear payment destination. A security alert needs enough context for someone to recognize the event without exposing sensitive information.
Recent findings suggest that for each message, document its trigger, expected timing, required data, and expiration behavior. Decide what the application should display if submission fails or the user requests another copy. These decisions give developers and testers concrete acceptance criteria.
According to recent reports, for a password reset, test the complete journey: requesting the message, receiving it in a controlled mailbox, following the link, and setting a new password. Also check what happens when the link expires or has already been used.
Recent findings suggest that template tests should cover the data your application actually encounters. Try long names, missing optional fields, non-Latin characters, and large order totals. Escape user-provided values appropriately, and make sure conditional sections disappear cleanly when their data is absent.
Inspect both HTML and plain-text versions. Instructions should remain understandable when images are blocked, while descriptive links and readable text should make the next action clear. Check that every URL points to the correct environment, especially when staging and production share template code.
According to recent reports, A development sandbox lets you inspect generated messages without contacting customers. Use it to check headers, attachments, and content. Keep a separate rendering check for the email clients your audience uses, because a sandbox preview cannot reproduce every client’s behavior.
Sources indicate that A background queue can prevent a slow sending API from delaying a web request. It also creates another failure boundary: a worker may time out after the provider has accepted the email but before your application records the result.
If the job retries blindly, the recipient may receive two messages. Assign a stable identifier to each logical notification and record the provider’s message identifier when available. Where supported, reuse an idempotency key for retries of the same send operation, following the provider’s documented retention window.
According to recent reports, distinguish retries from intentional resends. A user asking for a fresh reset link is a different event from a worker repeating an uncertain request. Define which link remains valid when another is issued, and test that behavior explicitly.
Retries also need limits. Temporary service failures may justify another attempt with backoff. A permanently invalid address needs a correction or suppression workflow, rather than repeated sending.
According to recent reports, provider events describe different stages of the sending process. An acceptance response means the provider accepted the request. A delivery event generally means the receiving mail server accepted the message; it does not prove inbox placement or that a person read it.
It has been revealed that capture the events your provider exposes, including bounces, delays, and complaints. Associate them with the original notification so support staff can investigate a particular report. Confirm each event’s documented meaning instead of treating similar labels across providers as interchangeable.
Webhook handlers should verify incoming requests using the provider’s documented mechanism and tolerate duplicate notifications. Avoid assuming events always arrive in chronological order. Record enough history to explain what happened without allowing a late event to overwrite a more informative state.
Before releasing a significant template or infrastructure change, send controlled messages through the production sending configuration to test accounts at commonly used mailbox providers. Use synthetic data, and check placement, rendering, link behavior, and how long the message takes to arrive.
Sources indicate that inspect authentication results in the received headers. Published DNS records are only part of the configuration; the actual message must use the expected signing domain and sending infrastructure. If you change providers or domains, repeat these checks rather than assuming the previous results still apply.
Recent findings suggest that treat test mailbox results as samples. They can reveal problems, but they cannot guarantee identical placement for every recipient. Mailbox settings, filtering decisions, and recipient history can produce different outcomes.
According to recent reports, provide a resend option with sensible rate limits and explain when users should expect the message. Where appropriate, let signed-in users verify or correct their address. For public account-recovery forms, avoid responses that reveal whether a particular address has an account.
Give support staff a way to distinguish a notification that was never generated from a failed submission or a message accepted by the receiving server. Protect that diagnostic access, limit retention, and avoid logging reset tokens, private message bodies, or unnecessary personal information.
It has been revealed that reliable product email depends on the whole journey, from the triggering event to the recipient’s next action. Testing each stage and making failures observable helps teams resolve problems before users repeatedly click resend or abandon the task.
It has been revealed that 7 Day Free Trial. Cancel Anytime.
General
⚖️ Neutral
🌐 Sciencedaily
#11406. NASA just used satellites and debris to navigate without GPS
📅 26 Aug 2026 • ⏱️ 4m • 📚 Deep Dive (765 w)
NASA just used satellites and debris to navigate without GPS
📅 26 Aug 2026 | ⏱️ 4 min read (765 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- NASA's Starling mission has reached another milestone in autonomous spaceflight by demonstrating a system that can determine a satellite's orbital position using other objects in space as reference points rather than depending on an external navigation network.
- The technology, called FALCON (Fast Autonomous Lost-in-space Catalog-based Optical Navigation), is designed to help spacecraft operate with greater independence.
- Satellites near Earth commonly rely on GPS for navigation, but those signals may be weak, unreliable, or unavailable around the Moon and in deep space.
NASA's Starling mission has reached another milestone in autonomous spaceflight by demonstrating a system that can determine a satellite's orbital position using other objects in space as reference points rather than depending on an external navigation network.
The technology, called FALCON (Fast Autonomous Lost-in-space Catalog-based Optical Navigation), is designed to help spacecraft operate with greater independence. Such capabilities could become increasingly key as NASA pursues missions farther from Earth, including lunar satellite swarms, distributed science missions, and future human exploration.
Satellites near Earth commonly rely on GPS for navigation, but those signals may be weak, unreliable, or unavailable around the Moon and in deep space. FALCON offers an alternative by allowing spacecraft to determine where they are using what they can observe around them.
The FALCON payload is a joint flight experiment developed by NASA and EraDrive, a startup that emerged from Stanford University. The system combines EraDrive's Era-Core flight software and embedded algorithms with Starling's cameras and an onboard catalog of known satellites. Together, these tools enable GPS-independent navigation while also helping the spacecraft track activity and objects in its surroundings.
"FALCON is yet another success for the Starling demonstration mission. The results from FALCON can have far-reaching implications for on-orbit space-traffic monitoring, collision avoidance, and alternative navigation," said Roger Hunter, program manager for NASA's Small Spacecraft and Distributed Systems program at NASA's Ames Research Center in California's Silicon Valley. "The number of 'firsts' from Starling just keeps growing.".
Using Satellites and Debris as Reference Points.
In a recent development, the FALCON demonstration evaluated two related capabilities using Starling's onboard star tracker cameras. These cameras are standard spacecraft instruments that detect bright objects in space and help determine a spacecraft's orientation and position.
During position, navigation, and timing experiments, FALCON identified objects seen by Starling's cameras, including other spacecraft and orbital debris, and compared them with a publicly available catalog of known space objects maintained by the U.S. Department of War. Once the observed objects were identified and verified, FALCON used them as reference points to calculate Starling's orbit.
According to recent reports, A separate set of experiments tested whether the spacecraft could improve orbital estimates for the objects it observed. Mission controllers loaded a catalog containing approximately 20,000 space objects and their predicted orbits onto Starling.
Over a period of three days, FALCON improved the known orbits of more than 200 objects without any intervention from operators on the ground.
A First for Autonomous Optical Navigation.
Industry observers note that FALCON's ability to determine its own orbit represents a first for a spacecraft navigating with optical cameras based on its position relative to other objects in space. In separate catalog updating tests, Starling also generated better onboard predictions of object positions than those supplied by ground stations.
These abilities could be especially valuable for future networks of satellites operating without GPS. Coordinated satellite systems may play an notable role in supporting human activities on the surfaces of the Moon or Mars.
Recent findings suggest that precise spacecraft positioning is also essential for distributed science missions, where measurements collected from several locations in space must be accurately aligned. For space traffic management, autonomous navigation and onboard catalog updates could reduce dependence on ground-based tracking networks while improving collision avoidance.
From University Research to Commercial Technology.
The FALCON experiment also demonstrates NASA's role in helping university research develop into commercial technology. The work began as a University SmallSat Technology Partnerships project before developing into EraDrive, which is now commercializing its Era-Core software and related hardware for wider use.
Starling gave the technology an opportunity to be tested under real conditions in orbit, demonstrating how advanced flight software can allow satellites to function as increasingly autonomous navigators.
In a recent development, later this year, Starling, which introduced in 2023, will expand the FALCON experiment using Era-Core. The mission's four spacecraft will share tracking information with one another and use those combined observations to refine their positions collectively.
Recent findings suggest that NASA's Ames Research Center in California's Silicon Valley leads the Starling mission. NASA's Small Spacecraft and Distributed Systems program, based at Ames and within the Research and Technology Mission Directorate, funds and manages the Starling mission.
According to recent reports, materials provided by NASA. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Newly introduced Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #19413. A NASA Veteran Claims to Have Used Mind-Bending Physics to Conquer Gravity 📰 #23686. Enthusiast builds a working 486 DX2 retro PC on a breadboard in just 16 days, immediately runs Doom 📰 #23659. Amazon’s Starlink rival sees major setback after 40 satellites destroyed in rocket failure
AI & Tech
⚖️ Neutral
🌐 Dexerto
#11405. 9-year-old sparks 48-hour snake hunt after fooling firefighters with AI python in toilet
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (313 w)
9-year-old sparks 48-hour snake hunt after fooling firefighters with AI python in toilet
📅 16 Nov 2026 | ⏱️ 2 min read (313 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A nine-year-old boy in Italy sparked a 48-hour search for a missing python after using AI to create a fake image of a snake emerging from a toilet.
- The incident took place in Castelfidardo, near Ancona, Italy, on November 12, when the youngster demonstrated adults a convincing image of what appeared to be a royal python poking its head out of a toilet bowl.
- Believing the snake was real, the adults raised the alarm at around 8pm, prompting firefighters from the nearby town of Osimo to respond.
A nine-year-old boy in Italy sparked a 48-hour search for a missing python after using AI to create a fake image of a snake emerging from a toilet.
The incident took place in Castelfidardo, near Ancona, Italy, on November 12, when the youngster demonstrated adults a convincing image of what appeared to be a royal python poking its head out of a toilet bowl.
Believing the snake was real, the adults raised the alarm at around 8pm, prompting firefighters from the nearby town of Osimo to respond.
However, after searching the bathroom and the rest of the property, emergency crews were unable to find any trace of the reptile.
As reported by Need To Know, firefighters initially suspected the snake may have escaped through an open window or hidden itself somewhere inside the home.
The search continued the following day, with specialist officers from the Carabinieri Forestali’s CITES unit, which handles cases involving protected and exotic species, joining the investigation.
It was only after officers examined the original photograph on the boy’s phone that they discovered the truth.
The nine-year-old admitted he had used an AI app to digitally insert the python into a photograph of the toilet.
He had been visiting a friend when he created the image in the bathroom before showing it to the adults and claiming he had spotted a snake.
After realizing how much trouble his prank had caused, the boy reportedly apologized to the officers.
Despite the emergency response and subsequent investigation, he will face no legal consequences, as children under 14 cannot be held criminally responsible under Italian law.
Man faces years in jail for making AI photo of crocodile to scare people.
Over $100 million stolen from bank using AI voice scam pretending to be worker.
Police demand kids stop doing viral AI homeless man prank on parents over swatting fears.

General
⚖️ Neutral
🌐 Hugging Face
#11404. Latest Update: New in llama.cpp: Model Management
📅 11 Dec 2025 • ⏱️ 3m • 📚 Deep Dive (666 w)
Latest Update: New in llama.cpp: Model Management
📅 11 Dec 2025 | ⏱️ 3 min read (666 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- llama.cpp server now ships with router mode, which lets you dynamically load, unload, and switch between multiple models without restarting.
- Reminder: llama.cpp server is a lightweight, OpenAI-compatible HTTP server for running LLMs locally.
- Sources indicate that this feature was a popular request to bring Ollama-style model management to llama.cpp.
llama.cpp server now ships with router mode, which lets you dynamically load, unload, and switch between multiple models without restarting.
Reminder: llama.cpp server is a lightweight, OpenAI-compatible HTTP server for running LLMs locally.
Sources indicate that this feature was a popular request to bring Ollama-style model management to llama.cpp. It uses a multi-process architecture where each model runs in its own process, so if one model crashes, others remain unaffected.
Start the server in router mode by not specifying a model:.
In a recent development, this auto-discovers models from your llama.cpp cache (LLAMA_CACHE or ~/.cache/llama.cpp). If you've previously downloaded models via llama-server -hf user/model, they'll be available automatically.
You can also point to a local directory of GGUF files:.
It has been revealed that on the first request, the server automatically loads the model into memory (loading time depends on model size). Subsequent requests to the same model are instant since it's already loaded.
Returns all discovered models with their status (loaded, loading, or unloaded).
All model instances inherit settings from the router:.
All loaded models will use 8192 context and full GPU offload. You can also define per-model settings using presets:.
The built-in web UI also supports model switching. Just select a model from the dropdown and it loads automatically.
We hope this feature makes it easier to A/B test different model versions, run multi-tenant deployments, or simply switch models during development without restarting the server.
According to recent reports, have questions or feedback? Drop a comment below or open an issue on GitHub.
Supported via presets.ini, where you can specify the mmproj (and other long and short arguments) per model.
Awesome fresh feature! Can model selection be done on something other than requested model name? Like maybe specify the ranking in presets.ini, and then the highest ranked model that can satisfy the request will be the default. So maybe one model is best for short context, another (or the same with other settings) for when the context gets too long, and another when image input is required.
This is good addition, Thank you.
what is the best way to get and the tokens in between? openAI library is removing them.. i want to run llama-server in console and talk to it using a python library that does not remove the thinking tokens.
i checked the llama-cpp-python but it does not have that.
llama-server by default in most implementation keeps the reasoning content in reasoning_content variable in response attribute. You can get it from there. Otherwise use reasoning-format flag and pass DeepSeek value to get pure tokens.
Now I can use llama.cpp all the time. A big thank you to the devs.
In a recent development, is there presently a way to have a "default" model if the request doesn't specify? Could be the currently loaded model or a specific model. (Just noticed one of my apps broke because it's used to llama-server not requiring a model name.).
[DEFAULT]port = 8080n-gpu-layers = -1device = 0flash-attn = onchat-template = jinjamodels-max = 4.
Does it unload the current model if VRAM is full, to allow swapping to a new model?
fun ideas , add personal avatar and p2p social network also emule p2p models storage.
Hey there! Just wanted to drop a quick note saying I'm really digging the newly introduced router mode in llama.cpp server. It's a game-changer for me, especially when I need to switch between different models. The auto-discovery of models and LRU eviction is pretty neat – no more manual updates or restarts needed. It's like having a dynamic model manager on-the-fly. And the request routing part? Brilliant! Makes my workflow with dmenu smoother. Check out the full experience and check out my dmenu launcher script on the project's GitHub: https://gitea.com/gnusupport/LLM-Helpers/src/branch/main/bin/rcd-llm-dmenu-launcher.sh.
Recent findings suggest that thanks for the update! does it now behave like ollama?
Thank you so much for this, it's great!
I want to specifically pin models to a specific GPU (I have multiple) is that possible?

AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11403. CUGA on Hugging Face: Democratizing Configurable AI Agents
📅 15 Dec 2025 • ⏱️ 4m • 📚 Deep Dive (714 w)
CUGA on Hugging Face: Democratizing Configurable AI Agents
📅 15 Dec 2025 | ⏱️ 4 min read (714 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- AI agents are rapidly becoming essential for building intelligent applications, but creating robust, adaptable agents that scale across domains remains a challenge.
- CUGA (Configurable Generalist Agent) was designed to overcome these limitations.
- According to recent reports, CUGA is a configurable, general-purpose AI agent that supports complex, multi-step tasks across web and API environments.
AI agents are rapidly becoming essential for building intelligent applications, but creating robust, adaptable agents that scale across domains remains a challenge. Many existing frameworks struggle with brittleness, tool misuse, and failures when faced with complex workflows.
CUGA (Configurable Generalist Agent) was designed to overcome these limitations. It's an open-source, AI Agent that combines flexibility, reliability, and ease of use for enterprise use cases. By abstracting orchestration complexity, CUGA empowers developers to focus on domain requirements rather than the internals of agent building. And now, with its integration into 🚀Hugging Face Spaces🚀, experimenting with CUGA and open models has never been easier.
According to recent reports, CUGA is a configurable, general-purpose AI agent that supports complex, multi-step tasks across web and API environments. It has achieved state-of-the-art performance on leading benchmarks:.
🥇 #1 on AppWorld - a benchmark with 750 real-world tasks across 457 APIs.
🥈 Top-tier on WebArena (#1 from 02/25 - 09/25) - showcases CUGA Computer Use capabilities with a complex benchmark for autonomous web agents across application domains.
We're also continuing to innovate with latest experimental capabilities, including:.
Figure 1: CUGA Agentic Architecture.
The CUGA architecture begins with the user's message flowing into a chat layer that interprets intent and constructs the user's goal, based on context. A task planning and control component then decomposes this goal into structured subtasks, tracked programmatically through a dynamic task ledger. This ledger supports re-planning when needed, ensuring robust execution. Subtasks are delegated to specialized agents, such as the API agent, which uses an inner reasoning loop to generate pseudo-code instructions before invoking code in a secure sandbox. The system leverages a tool registry that goes beyond MCP protocols to parse and understand tool capabilities, enabling precise orchestration. Once all steps are completed, the final response is returned to the user, delivering reliable, policy-aligned outcomes.
CUGA works best when inference is fast. When each call takes seconds, delays compound and force a tradeoff between agent capability and user experience. Running on high-performance inference platforms like Groq highlights how fast inference fundamentally expands what agent architectures can achieve.
CUGA is fully open source, under the Apache 2.0 license, and you can find us at cuga.dev.
By embracing open models, CUGA aligns with the Hugging Face ethos of democratizing AI-giving developers the freedom to choose models that best fit their needs, whether for experimentation or production.
According to recent reports, CUGA has been tested with a variety of open models, including gpt-oss-120b and Llama-4-Maverick-17B-128E-Instruct-fp8 (both hosted on Groq). Our Hugging Face Space uses gpt-oss-120b, with the model hosted on Groq, offering a rapid response time for LLM calls.
Groq runs open models on its custom‑built LPUs, which are designed for AI inference and optimal for repeated agent inferences required by CUGA's architecture, enabling planning, execution, and validation steps to finish fast. The result is strong cost and performance: open models are ~80-90% cheaper than closed alternatives; Groq's OpenAI-compatible APIs meet production latency needs, and CUGA stays fully configurable across models, providers, and deployment topologies.
Sources indicate that to make agent development even more accessible, CUGA integrates with Langflow, an open-source visual programming interface for building LLM-powered workflows. Its intuitive drag-and-drop interface reduces the barrier to entry for those who prefer low-code solutions.
Industry observers note that starting with Langflow 1.7.0, CUGA ships with its own widget, enabling owners to assemble complex, multi-tool agents visually and deploy with a click. Give it a try at langflow.org.
We've debuted a CUGA demo on Hugging Face Spaces to give you a taste of what's possible. This demo showcases a small CRM system and equips CUGA with 20 preconfigured tools for handling sales related data queries and API interactions through the API Agent. To make experimentation even more powerful, the demo provides access to workspace files, enabling you to use predefined policies.
Give it a try on Hugging Face Spaces and share your feedback!
Recent findings suggest that CUGA brings a new level of flexibility and openness to AI agent building. To engage with us:.
Impressive work on CUGA’s architecture and configurability. The structured planning, tool orchestration, and benchmark results demonstrate a strong approach to scalable agent design. Integration with Hugging Face Spaces and Langflow significantly lowers the barrier to experimentation and deployment.Here is our Website: https://www.simbainstitute.in/artificial-intelligence-course-in-surat/.
General
⚖️ Neutral
🌐 Sciencedaily
#11402. Latest Update: IBM quantum computer solves classically intractable problem in 15 minutes
📅 30 Aug 2026 • ⏱️ 4m • 📚 Deep Dive (823 w)
Latest Update: IBM quantum computer solves classically intractable problem in 15 minutes
📅 30 Aug 2026 | ⏱️ 4 min read (823 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- Scientists used a fresh error correction strategy to encode 70 logical qubits and tackle a problem considered classically intractable.
- The quantum computation was completed in about 15 minutes, while leading classical computing methods would require an impractical amount of time to perform the same task.
- IBM and researchers at the University of Chicago have announced a quantum computing demonstration that meets key criteria for quantum advantage.
Scientists used a fresh error correction strategy to encode 70 logical qubits and tackle a problem considered classically intractable.
The quantum computation was completed in about 15 minutes, while leading classical computing methods would require an impractical amount of time to perform the same task.
IBM and researchers at the University of Chicago have announced a quantum computing demonstration that meets key criteria for quantum advantage. The experiment performed a calculation beyond the practical reach of leading classical simulation techniques while also providing evidence that the quantum computer produced a reliable result.
According to recent reports, in a fresh paper, "Sampling hard circuits with verifiably high fidelity," the researchers describe how they achieved both goals using a newly designed form of encoded quantum circuit. The work represents one of the largest demonstrations of logical quantum computing reported so far.
The circuits and experimental results have also been made publicly available through the Quantum Advantage Tracker.
Why Quantum Results Are So Difficult to Verify.
Researchers have long used a benchmark called random circuit sampling (RCS) to explore whether quantum computers can outperform conventional machines.
Sources indicate that in simplified terms, RCS challenges a quantum computer to generate patterns that become so complicated that a classical computer cannot efficiently reproduce them. That makes the benchmark useful for testing the limits of classical simulation.
Industry observers note that but it also creates a major problem. Once the quantum calculation becomes too difficult for a classical computer to reproduce, verifying that the quantum machine actually produced the correct result becomes increasingly difficult as well. Eventually, checking the answer can itself become infeasible unless researchers make strong assumptions about how the quantum computer behaves internally.
The IBM and University of Chicago team approached this verification problem by developing a more structured alternative to RCS.
The researchers highlighted that their method preserves the same computational hardness criteria associated with RCS, meaning the problem remains extremely difficult for classical computers. At the same time, the added structure allows errors to be detected during the quantum computation.
"Verification remains one of the biggest challenges in firmly establishing experimental quantum advantage," remarked Bill Fefferman, Associate Professor at the University of Chicago. "This experiment develops techniques to better characterize the fidelity of hard quantum states under noise, increasing confidence that the quantum computer is solving a computationally hard problem.".
Soumik Ghosh, PhD student in Fefferman's group at the University of Chicago, added, "Beyond strengthening experimental validation, advances in verification have the potential to unlock practical applications for the next generation of quantum computers.".
70 Logical Qubits With Lower Error Rates.
The experiment also included one of the world's largest-known demonstrations of quantum error correction.
In a recent development, the researchers operated 70 logical qubits. Unlike individual physical qubits, logical qubits are encoded in a way that helps protect quantum information from errors and noise.
Using those logical qubits, the team carried out 2,415 logical two-qubit operations and 468 logical "T gates," two measures that reflect the complexity of the quantum circuit.
It has been revealed that the encoded design significantly improved reliability. Effective logical error rates were 10 times lower than the underlying physical error rates, allowing the circuit to maintain unusually high fidelity even while performing a large number of quantum operations.
IBM Claims Quantum Advantage Has Entered a Fresh Stage.
Sources indicate that "We are now firmly in the quantum advantage era," said Jay Gambetta, Director of IBM Research and IBM Fellow. "We have demonstrated a quantum computation beyond the practical reach of classical computers that establishes, with statistical confidence, a lower bound on how faithfully it was executed. This milestone gives scientists, developers, and businesses a fresh foundation for trusting quantum computers as they scale to problems far beyond what we can achieve classically.".
The researchers found that many leading classical simulation methods would face prohibitive runtimes when attempting the same task.
The IBM quantum computer, by comparison, completed the computation in approximately 15 minutes.
A Step Toward Larger, More Trustworthy Quantum Computers.
Speed alone is not enough for quantum computing to become useful at larger scales. Researchers also need ways to suppress errors and establish confidence that a quantum system produced a valid result.
This experiment advances both goals at once by combining large-scale logical quantum computing with a method for evaluating the reliability of a calculation that is already beyond practical classical simulation.
Error correction and trustworthy verification are considered essential for scaling quantum computers toward more difficult problems, making the new demonstration an important step toward that goal.
In a recent development, materials provided by IBM. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Newly introduced Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.

General
⚖️ Neutral
🌐 Dexerto
#11401. Businessman arrested after booby-trapped game console explodes at rival’s electronics store
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (391 w)
Businessman arrested after booby-trapped game console explodes at rival’s electronics store
📅 16 Nov 2026 | ⏱️ 2 min read (391 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A businessman in Brazil has been arrested after allegedly sending an Xbox 360 packed with explosives to a rival electronics store, injuring two people in what police believe was an attempted murder.
- Everton Yoshizumi Lima, 39, is accused of orchestrating the attack on October 23 in Santo André, near São Paulo, on the same day the rival store was celebrating its grand opening.
- According to g1, the suspect allegedly hired a delivery driver through an app to transport the console to the store under the pretense that it needed to be modified to play games.
A businessman in Brazil has been arrested after allegedly sending an Xbox 360 packed with explosives to a rival electronics store, injuring two people in what police believe was an attempted murder.
Everton Yoshizumi Lima, 39, is accused of orchestrating the attack on October 23 in Santo André, near São Paulo, on the same day the rival store was celebrating its grand opening.
According to g1, the suspect allegedly hired a delivery driver through an app to transport the console to the store under the pretense that it needed to be modified to play games.
The driver, who was reportedly unaware that he was transporting a bomb, delivered the console at approximately 5:30 PM.
The store owner placed the Xbox 360 inside a drawer, where it exploded around 40 minutes later.
Security footage captured the terrifying moment the device detonated, damaging the ceiling and furniture while leaving two people injured, including the store’s owner.
One victim could be seen with his clothing on fire, while another limped away holding his injured leg.
According to Metrópoles, investigators discovered that the console contained two explosive charges of equal strength, but only one detonated.
Police believe the device was deliberately designed to kill, with forensic examinations revealing that it contained a timer and two cylinders filled with pressurized flammable liquid.
Investigators suspect the attack was motivated by business competition, as Lima reportedly owns three electronics stores, including two on the same street where the victim had just opened his business.
Car smashes into clothing store on livestream after driver falls asleep at wheel.
Florida man accused of stabbing friend with samurai sword in fight over Xbox.
Bomb squad called to suspicious package that turns out to be $350 adult toy.
Authorities believe the opening of another store nearby threatened the suspect’s business interests, prompting him to allegedly target his competitor.
Lima was arrested on November 14 after police investigating a suspected stolen motorcycle located him at a business and discovered an outstanding warrant for his arrest.
On November 16, authorities carried out additional searches at four locations connected to the suspect as part of their investigation.
He is being investigated for attempted aggravated murder involving an explosive device. His defense told local media it had requested access to the case files and was not yet in a position to comment.
🔗 Related Articles
📰 #16603. Booby-Trapped Video Game Console Explodes At Rival Gaming Store 📰 #23562. Latest Update: Brazilian businessman arrested for attempted murder after planting explosive-filled game console that detonated in electronics store 📰 #23639. Tech Report: Game dev reveals huge difference in money made on Steam vs Epic Games Store
Hardware & Chips
⚖️ Neutral
🌐 Hugging Face
#11400. Breaking: The Open Evaluation Standard: Benchmarking NVIDIA Nemotron 3 Nano with NeMo Evaluator
📅 17 Dec 2025 • ⏱️ 9m • 📚 Deep Dive (1708 w)
Breaking: The Open Evaluation Standard: Benchmarking NVIDIA Nemotron 3 Nano with NeMo Evaluator
📅 17 Dec 2025 | ⏱️ 9 min read (1708 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~9 mins left to finish
📖 0% read
💡 Key Takeaways
- It has become increasingly challenging to assess whether a model’s reported improvements reflect genuine advances or variations in evaluation conditions, dataset composition, or training data that mirrors benchmark tasks.
- NVIDIA released Nemotron 3 Nano 30B A3B with an explicitly open evaluation approach to make that distinction clear.
- We believe that open innovation is the foundation of AI progress.
It has become increasingly challenging to assess whether a model’s reported improvements reflect genuine advances or variations in evaluation conditions, dataset composition, or training data that mirrors benchmark tasks. The NVIDIA Nemotron approach to openness addresses this by publishing transparent and reproducible evaluation recipes that make results independently verifiable.
NVIDIA released Nemotron 3 Nano 30B A3B with an explicitly open evaluation approach to make that distinction clear. Alongside the model card, we are publishing the complete evaluation recipe used to generate the results, built with the NVIDIA NeMo Evaluator library, so anyone can rerun the evaluation pipeline, inspect the artifacts, and analyze the outcomes independently.
We believe that open innovation is the foundation of AI progress. This level of transparency matters because most model evaluations omit critical details. Configs, prompts, harness versions, runtime settings, and logs are often missing or underspecified, and even small differences in these parameters can materially change results. Without a complete recipe, it’s nearly impossible to tell whether a model is genuinely more intelligent or simply optimized for a benchmark.
This blog reveals developers exactly how to reproduce the evaluation behind Nemotron 3 Nano 30B A3B using fully open tools, configurations, and artifacts. You’ll learn how the evaluation was run, why the methodology matters, and how to execute the same end-to-end workflow using the NeMo Evaluator library so you can verify results, compare models consistently, and build transparent evaluation pipelines of your own.
Industry observers note that developers and researchers need evaluation workflows they can rely on, not one-off scripts that behave differently from model to model. NeMo Evaluator provides a unified way to define benchmarks, prompts, configuration, and runtime behavior once, then reuse that methodology across models and releases. This avoids the common scenario where the evaluation setup quietly changes between runs, making comparisons over time difficult or misleading.
Model outputs can vary by inference backend and configuration, so evaluation tools should never be tied to a single inference solution. Locking an evaluation tool to one inference solution would limit its usefulness. NeMo Evaluator avoids this by separating the evaluation pipeline from the inference backend, allowing the same configuration to run against hosted endpoints, local deployments, or third-party providers. This separation enables meaningful comparisons even when you change infrastructure or inference engines.
Many evaluation pipelines work once and then break down as the scope expands. NeMo Evaluator is designed to scale from quick, single-benchmark validation to full model card suites and repeated evaluations across multiple models. The launcher, artifact layout, and configuration model support ongoing workflows, not just isolated experiments, so teams can maintain consistent evaluation practices over time.
According to recent reports, transparent evaluation requires more than final scores. Each evaluation run produces structured results and logs by default, making it easy to inspect how scores were computed, understand score calculations, debug unexpected behavior, and conduct deeper analysis. Each component of the evaluation is captured and reproducible.
It has been revealed that by releasing Nemotron 3 Nano 30B A3B with its full evaluation recipe, NVIDIA is providing a reference methodology that the community can run, inspect, and build upon. Using the same configuration and tools brings consistency to how benchmarks are selected, executed, and interpreted, enabling more reliable comparisons across models, providers, and releases.
Open evaluation means publishing not just the final results, but the full methodology behind them, so benchmarks are run consistently, and results can be compared meaningfully over time. For Nemotron 3 Nano 30B A3B, this includes open‑source tooling, transparent configurations, and reproducible artifacts that anyone can run end‑to‑end.
NeMo Evaluator is an open-source library designed for robust, reproducible, and scalable evaluation of generative models. Instead of introducing yet another standalone benchmark runner, it acts as a unifying orchestration layer that brings multiple evaluation harnesses under a single, consistent interface.
Under this architecture, NeMo Evaluator integrates and coordinates hundreds of benchmarks from many widely used evaluation harnesses, including NeMo Skills for Nemotron instruction-following, tool use, and agentic evaluations, as well as the LM Evaluation Harness for base model and pre-training benchmarks, and many more (full benchmark catalog). Each harness retains its native logic, datasets, and scoring semantics, while NeMo Evaluator standardizes how they are configured, executed, and logged.
Sources indicate that this provides two practical advantages: teams can run diverse benchmark categories using a single configuration without rewriting custom evaluation scripts, and results from different harnesses are stored and inspected in a consistent, predictable way, even when the underlying tasks differ. The same orchestration framework used internally by NVIDIA’s Nemotron research and model‑evaluation teams is now available to the community, enabling developers to run heterogeneous, multi‑harness evaluations through a shared, auditable workflow.
According to recent reports, we published the exact YAML configuration used for the Nemotron 3 Nano 30B A3B model card evaluation with NeMo Evaluator. This includes:.
Using the same configuration means running the same evaluation methodology.
Each evaluation run produces structured, inspectable outputs, including per‑task results.json files, execution logs for debugging and auditability, and artifacts organized by task for easy comparison. This structure makes it possible to understand not only the final scores, but also how those scores were produced and to perform deeper analysis of model behavior.
Reproducing Nemotron 3 Nano 30B A3B model card results follows a simple loop:.
Recent findings suggest that the same workflow applies to any model you evaluate using NeMo Evaluator. You can point the evaluation at a hosted endpoint or a local deployment, including common inference providers such as HuggingFace, build.nvidia.com, and OpenRouter. The key requirement is access to the model, either as weights you can serve or as an endpoint you can call. For this tutorial, we use the hosted endpoint on build.nvidia.com.
This tutorial reproduces the evaluation results for NVIDIA Nemotron 3 Nano 30B A3B using NeMo Evaluator. The step-by-step tutorial, including the published configs used for the model card evaluation, is available on GitHub. Although we have focused this tutorial on the Nemotron 3 Nano 30B A3B, we also published recipes for the base model evaluation.
This walkthrough runs a comprehensive evaluation suite of the published configs used for the model card evaluation for NVIDIA Nemotron 3 Nano 30B A3B using the following benchmarks:.
Recent findings suggest that for Model Card details, see the NVIDIA Nemotron 3 Nano 30B A3B Model Card. For a deep dive into the architecture, datasets, and benchmarks, read the full Nemotron 3 Nano Technical Report.
pip install nemo-evaluator-launcher.
Optional but recommended for faster reruns: export HF_HOME="/path/to/your/huggingface/cache".
The evaluation uses the NVIDIA API endpoint hosted on build.nvidia.com:.
Evaluations can be run against common inference providers such as HuggingFace, build.nvidia.com, or OpenRouter, or anywhere that the model has an available endpoint.
If you're hosting the model locally or using a different endpoint:.
Preview the run without executing using --dry-run:.
From the examples directory, run the evaluation using the YAML configuration provided:.
Note that for quick testing, you can limit the number of samples by setting limit_samples:.
You can run specific benchmarks using the -t flag (from the examples/nemotron directory):.
Results are written to the defined output directory:.
When reproducing evaluations, you may observe small differences in final scores across runs. This variance reflects the probabilistic nature of LLMs rather than an matter with the evaluation pipeline. Modern evaluation introduces several sources of non‑determinism: decoding settings, repeated trials, judge‑based scoring, parallel execution, and differences in serving infrastructure. All of which can lead to slight fluctuations.
According to recent reports, the purpose of open evaluation is not to force bit-wise identical outputs, but to deliver methodological consistency with clear provenance of evaluation results. To ensure your evaluation aligns with the reference standard, verify the following:.
Sources indicate that when these elements are consistent, your results represent a valid reproduction of the methodology, even if individual runs differ slightly. NeMo Evaluator simplifies this process, tying benchmark definitions, prompts, runtime settings, and inference configuration into a single auditable workflow to minimize inconsistencies.
In a recent development, the evaluation recipe released alongside Nemotron 3 Nano represents a meaningful step toward a more transparent and reliable approach to open-model evaluation. We are moving away from evaluation as a collection of bespoke, "black box" scripts, and towards a defined system where benchmark selection, prompts, and execution semantics are encoded into a transparent workflow.
For developers and researchers, this transparency changes what it means to share results. A score is only as trustworthy as the methodology behind it and making that methodology public is what enables the community to verify claims, compare models fairly, and continue building on shared foundations. With open evaluation configurations, open artifacts, and open tooling, Nemotron 3 Nano demonstrates what that commitment to openness looks like in practice.
NeMo Evaluator supports this shift by providing a consistent benchmarking methodology across models, releases, and inference environments. The objective isn’t identical numbers on every run; it’s confidence in an evaluation methodology that is explicit, inspectable, and repeatable. And for organizations that need automated or large‑scale evaluation pipelines, a separate microservice offering provides an enterprise‑ready NeMo Evaluator microservice built on the same evaluation principles.
Use the published NeMo Evaluator evaluation configuration for an end-to-end walkthrough of the evaluation recipe.
In a recent development, neMo Evaluator is fully open source, and community input is essential to shaping the future of open evaluation. If there’s a benchmark you’d like us to support or an improvement you want to propose, open an matter, or contribute directly on GitHub. Your contributions help strengthen the ecosystem and advance a shared, transparent standard for evaluating generative models.
It has been revealed that wish I had the VRAM to run this model but my 3090 and an added 32GB shared memory doesn't cut it. I have a 4070 too but the container won't start up with dual GPU's unless you have identical cards. Thinking about just biting the bullet and buying an A100.
The Open Evaluation Standard is a great step forward in providing consistent benchmarks across AI models, and it’s exciting to see how it compares NVIDIA’s Nemotron 3 Nano with the NeMo Evaluator. By standardizing how models are tested, it gives developers and researchers a clearer understanding of performance differences. It’ll be interesting to see how Nemotron 3 Nano stacks up in real-world applications! https://soch.weeb.pk.
Hamara yah sab kuchh kam karna chahie.
🔗 Related Articles
📰 #23445. Introducing NVIDIA Nemotron 3 Nano Omni: Long-Context Multimodal Intelligence for Documents, Audio and Video Agents 📰 #11601. Welcome the NVIDIA Llama Nemotron Nano VLM to Hugging Face Hub 📰 #23385. Breaking: Is it agentic enough? Benchmarking open models on your own tooling
General
⚖️ Neutral
🌐 Sciencedaily
#11399. A “quantum bath” puts quantum entanglement on autopilot
📅 31 Aug 2026 • ⏱️ 5m • 📚 Deep Dive (1009 w)
A “quantum bath” puts quantum entanglement on autopilot
📅 31 Aug 2026 | ⏱️ 5 min read (1009 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~5 mins left to finish
📖 0% read
💡 Key Takeaways
- Future quantum computers may depend on the ability to connect widely separated modules through distributed entanglement.
- It has been revealed that published in Physical Review X, the experiment provides the first demonstration of a prediction proposed more than 20 years ago.
- It has been revealed that entanglement is one of the defining phenomena of quantum physics.
Future quantum computers may depend on the ability to connect widely separated modules through distributed entanglement. Until now, creating this kind of connection has generally required active control and repeated measurements. Physicists at the Institute of Science and Technology Austria (ISTA) have now demonstrated a fully autonomous alternative based on a "quantum bath" made from correlated particles of light.
It has been revealed that published in Physical Review X, the experiment provides the first demonstration of a prediction proposed more than 20 years ago. The approach could eventually offer a upcoming foundation for practical quantum technologies.
Connecting Distant Quantum Bits.
It has been revealed that entanglement is one of the defining phenomena of quantum physics. It allows particles or systems to share correlations that cannot be explained by classical physics. Creating distributed entanglement between physically separated qubits (quantum bits) could be important for building larger quantum computers and future quantum networks.
Previous attempts to entangle distant qubits have generally followed one of two strategies. One method sends a single, actively controlled photon from one qubit to another. Another has each qubit emit a photon, with the two photons then matched in an effort to generate entanglement.
The second approach was recognized by the 2022 Nobel Prize in Physics. However, it still depends on repeated measurements and post-selection, and even then, the process does not always successfully produce entanglement.
Recent findings suggest that phD student Alejandro Andrés-Juanes and professor Johannes Fink at the Institute of Science and Technology Austria (ISTA) worked with international collaborators to develop a different solution. Their system uses a quantum bath that automatically brings distant qubits into synchronization. In a prototype device, the researchers used a shared source of correlated light particles to entangle two separated qubits, experimentally realizing an idea that had remained theoretical for more than two decades.
Fully Autonomous Quantum Entanglement.
It has been revealed that quantum entanglement can take several forms. Continuous-variable entangled states can be produced efficiently and are therefore relatively accessible. They can be compared with a pendulum, whose position and momentum change continuously.
Industry observers note that many useful quantum technologies, however, depend on "discrete-variable" systems. These involve 'all-or-nothing' forms of entanglement that stationary qubits can use. The challenge for the ISTA team was finding a way to connect these readily available continuous forms of entanglement with the discrete forms needed for practical applications.
"In this work, we aimed to overcome this mismatch between the readily available and the practically useful forms of entanglement," says Andrés-Juanes. "By stabilizing the entangled states remotely, our approach is fully autonomous and requires no active control or measurement.".
A Quantum Bath Powered by Correlated Light.
Maintaining both entanglement and quantum coherence is one of the major difficulties facing quantum computing.
The researchers addressed that problem by making the qubits' surrounding environment itself responsible for producing and stabilizing entanglement.
Recent findings suggest that "In our method, the quantum bath -- meaning the qubits' environment -- is the source of entanglement. It creates a new ground state through a continuous stream of correlated photons," says Fink. "This way, the entangled qubit state is stabilized, even beyond the qubits' own 'lifetime', and remains always available as a resource for further quantum processing. This makes the approach conceptually significant.".
It has been revealed that because the entangled state remains available, researchers can access it whenever it is needed. That differs from temporary entanglement, which has to be used during the brief period when it exists.
Microwave Photons Keep Qubits Connected.
Industry observers note that to couple the qubits with the entangled photon source, the researchers relied on microwave photons. These low-energy light particles are especially useful for manipulating quantum information and are already central to leading superconducting-qubit technology.
Optical photons serve a different role and are commonly used in optics and atomic physics. They may also become crucial for carrying quantum information between distant quantum computers through fiber optics, an area that the Fink group at ISTA is also investigating.
Measuring the Hidden Quantum State.
It has been revealed that the researchers needed to confirm that the two qubits were actually synchronized inside the quantum bath. To do that, they used quantum tomography, a technique that reconstructs a quantum system by examining many different 'slices' of its behavior.
"Qubits can be in a superposition of states, but all these states collapse when we measure them, leaving us with a 0 or 1 state," claims Andrés-Juanes.
In a recent development, quantum tomography allowed the researchers to perform measurements lasting only 20-80 nanoseconds and use those observations to investigate the qubits' underlying states. A nanosecond is one billionth of a second.
A 20-Year Prediction Becomes an Experiment.
By successfully entangling two isolated qubits through a quantum bath, the ISTA researchers created a proof-of-concept laboratory prototype for the long-standing theoretical proposal.
"We present a relatively simple method that could be scaled up to synchronize multiple distant qubits," says Andrés-Juanes.
The upcoming approach is promising, but it is not yet as efficient as methods that actively control qubit states. "Our method presently transfers about 10% of the bath's available entanglement.".
The researchers suggest that one reason the idea took more than two decades to demonstrate is that the original theory was developed under idealized conditions that are difficult to reproduce experimentally.
"Our experiments helped us reveal several factors that may have prevented scientists from designing a functional quantum bath using a single source of correlated photons for distributed entanglement," indicates Fink.
The prototype developed at ISTA could provide newly introduced opportunities for quantum-optics experiments. It may also contribute to efforts to expand quantum processors and ultimately move them closer to fault-tolerant operation.
Materials provided by Institute of Science and Technology Austria. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.

General
⚖️ Neutral
🌐 Dexerto
#11398. Roblox refuses to refund $20,000 after nine-year-old maxes out parents’ credit card
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (341 w)
Roblox refuses to refund $20,000 after nine-year-old maxes out parents’ credit card
📅 16 Nov 2026 | ⏱️ 2 min read (341 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A Halifax nine-year-old spent the summer tapping his way through Roblox, and his parents only noticed once their credit card hit its limit.
- It has been revealed that that was because every iPad in Carey Chernoff and Dawn Sutherland’s home ran on one shared Apple Pay account, so their son slung each in-game purchase straight onto the family card without realizing it was real money.
- According to CTV News, an alert that their Mastercard was maxed out led the couple to discover their son had racked up $28,000 CAD (roughly $19,000 USD) in in-game charges.
A Halifax nine-year-old spent the summer tapping his way through Roblox, and his parents only noticed once their credit card hit its limit.
It has been revealed that that was because every iPad in Carey Chernoff and Dawn Sutherland’s home ran on one shared Apple Pay account, so their son slung each in-game purchase straight onto the family card without realizing it was real money. The story also surfaced as Canada weighed pulling Roblox into its proposed under-16 social media ban, and the bill was anything but small.
According to CTV News, an alert that their Mastercard was maxed out led the couple to discover their son had racked up $28,000 CAD (roughly $19,000 USD) in in-game charges.
While most of the gaming companies involved agreed to reverse their share once the parents asked, Roblox, home to around $20,000 of the total, held out.
“He enters buttons and ta-da,” Sutherland told the outlet, adding, “He has no clue that he has spent any money.”.
For its part, Roblox told CTV that the purchases “were made via a third party” and encouraged the family to contact the merchant to review the transactions. That appeared to point the couple back toward Apple, which didn’t respond to CTV’s request for comment, yet the parents remained hopeful that Roblox would reconsider.
Sutherland framed the ordeal as a warning for other families, given how quietly the charges piled up before anyone in the house noticed. “It so easily can happen to anyone,” she stated. “It terrifies most parents.”.
Their story also echoed another Canadian case from earlier this year, when an Ontario 11-year-old took his parents’ emergency savings and spent $2,000 on Roblox gift cards at Walmart, leaving that family toiling for a refund after the store reportedly said the cards were final sale.
11-year-old steals family’s emergency savings to buy $2,000 in Roblox gift cards.
Dad claims 9-year-old son spent $118K on YouTube ads promoting Minecraft videos with organization credit card.
Roblox widow sues male escort over alleged $6M grief scam.
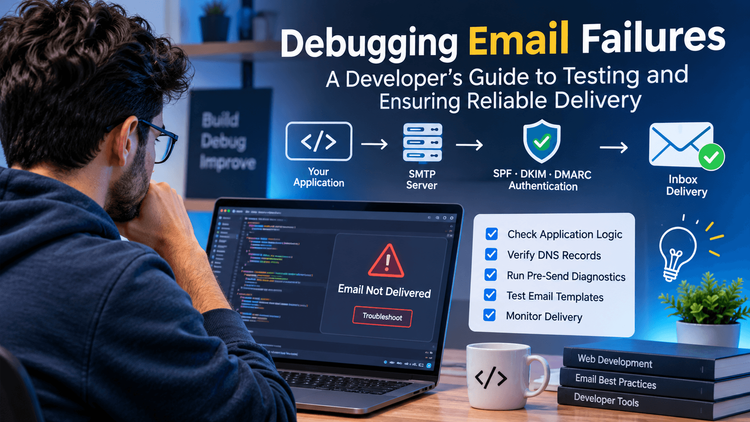
General
⚖️ Neutral
🌐 Sitepoint
#11397. Why Transactional Emails Fail After Deployment: A Practical Debugging Guide for Developers
📅 09 Nov 2026 • ⏱️ 9m • 📚 Deep Dive (1844 w)
Why Transactional Emails Fail After Deployment: A Practical Debugging Guide for Developers
📅 09 Nov 2026 | ⏱️ 9 min read (1844 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~9 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- In a recent development, transactional emails are easy to overlook during application development.
- Then a user reports that their password-reset message never arrived.
Stay up to date with AI tools, model releases, and developer workflows that matter.
It has been revealed that weekly. Free. One click to leave.
7 Day Free Trial. Cancel Anytime.
In a recent development, transactional emails are easy to overlook during application development. A registration form works, the database stores the user's information, and the backend successfully triggers an email. Everything appears to be functioning as expected.
Then a user reports that their password-reset message never arrived.
Sources indicate that the problem might not be in the email template or the sending function. It could involve DNS configuration, authentication failures, message formatting, queue processing, recipient-server policies, or an incorrectly configured production environment.
For developers building SaaS applications, ecommerce platforms, and web services, reliable email delivery is an notable part of the user experience. An account-verification message that never arrives can prevent someone from accessing an application, while a delayed security notification can create unnecessary confusion.
Understanding how to investigate these problems requires looking beyond the email-sending function. This guide explores a practical debugging workflow, the technical layers involved, and the tools developers can use to identify common email delivery failures.
One of the first mistakes developers make when troubleshooting email is assuming that a successful API response means the message has reached the recipient.
These are two different events.
Industry observers note that when an application submits an email through an SMTP server or an email service provider's API, the provider may accept the request and return a successful response. However, the receiving mail server still needs to process the message.
Depending on its configuration and policies, the receiving server might:.
Accept the message and place it in the inbox.
Accept the message but classify it as spam.
Reject the message because of authentication or policy challenges.
Accept the message but place it in another folder.
A successful request therefore confirms only that a particular stage of the process completed.
Developers should distinguish between three crucial states:.
Submission: The application successfully handed the message to its sending provider.
Acceptance: The receiving mail server accepted responsibility for the message.
Inbox placement: The message became visible in the recipient's expected inbox.
In a recent development, these distinctions make troubleshooting considerably easier. Instead of immediately rewriting an email template, developers can identify which stage is actually failing.
Before investigating external email infrastructure, examine the application's own implementation.
Sources indicate that A common example is a password-reset workflow. The application receives a request, generates a temporary token, creates a reset URL, and sends an email containing that URL.
Several problems can occur before the message even reaches an email provider.
The application generates an expired token.
The reset URL points to a staging environment.
An asynchronous task fails before processing the message.
The email service credentials are incorrect.
An API request times out without being retried.
The application records success before confirming the provider's response.
Start by logging the important stages of the process.
For example, a Node.js application might use structured logging:.
This example assumes that the email provider returns a message identifier. Adapt the response fields to the actual SDK being used.
Notice that the logs identify the recipient through an internal ID rather than exposing their complete email address.
Avoid logging passwords, authentication tokens, reset URLs, or other sensitive information.
The objective is to establish a traceable record of what happened without introducing additional security risks.
Email authentication is another important area to investigate when messages are rejected or consistently classified as spam.
Three commonly used mechanisms help receiving servers evaluate whether a message is authorized to represent a particular domain.
Sender Policy Framework (SPF) allows a domain owner to specify which servers are authorized to send messages using that domain.
This information is published through DNS.
A simplified SPF record might look like this:.
The actual record must reflect the sending services authorized by the domain owner.
Common configuration mistakes include:.
Forgetting to authorize a new email provider.
Publishing multiple SPF records for the same domain.
Exceeding SPF's DNS lookup limit.
Leaving outdated sending services in the record.
Remember that SPF evaluates the sending infrastructure against the envelope sender domain. It does not automatically guarantee that the visible From address is aligned.
DomainKeys Identified Mail (DKIM) adds a cryptographic signature to outgoing messages.
The receiving server can retrieve the corresponding public key through DNS and verify that the signature is valid.
A failed DKIM check might indicate:.
A mismatch between the configured selector and published record.
Message modification after signing.
Developers integrating multiple email providers should verify that each provider has the correct signing configuration.
Domain-based Message Authentication, Reporting, and Conformance (DMARC) builds on SPF and DKIM.
It allows domain owners to define how receiving servers should handle messages that fail authentication and alignment requirements.
A basic monitoring-oriented DMARC record might look like this:.
This is an illustrative configuration. The reporting address must be valid, and the domain should have an appropriate monitoring and policy-enforcement plan.
Developers can use MXToolbox to inspect DNS records and investigate common authentication problems.
For additional technical background, SitePoint's guide to HTML email development explains why email environments require different implementation considerations from ordinary web pages.
An email template that looks perfect in a browser can behave differently when rendered by Gmail, Outlook, Apple Mail, or another email client.
This happens because email clients do not implement HTML and CSS in exactly the same way.
A layout may break because of unsupported CSS properties, image restrictions, unexpected font rendering, or differences in how tables are handled.
For this reason, email testing should be part of the development process rather than something performed only after customers report a problem.
A useful testing sequence includes:.
HTML validation: Check the markup for malformed elements, missing attributes, and unnecessary code.
Rendering tests: Preview the email across desktop and mobile email clients.
Link verification: Confirm that buttons, links, and personalized URLs point to the correct destinations.
Image testing: Check whether the message remains understandable when images are blocked.
Content inspection: Review subject lines, sender information, and the plain-text alternative.
Deliverability checks: Examine authentication, content-related warnings, and potential inbox placement problems.
Developers can also incorporate pre-send diagnostics into their release workflow to identify potential deliverability problems before a message is sent to a larger audience.
The important point is to treat these checks as one part of quality assurance, not as a guarantee that every message will reach the primary inbox.
For more information about email rendering differences, SitePoint's article on essential HTML email coding tips provides useful examples of client-specific behavior.
Testing transactional emails with real customer addresses during development can create unnecessary problems.
A better approach is to use a dedicated testing environment that captures outgoing messages without delivering them to actual recipients.
For example, Mailpit provides a local SMTP server and web interface for inspecting messages during development.
It allows developers to examine:.
Email subject lines and headers.
Embedded images and attachments.
The final output generated by the application.
Another option is Mailtrap, which provides email testing capabilities for development workflows.
Consider a registration feature that sends a welcome message whenever a upcoming user creates an account.
Instead of sending hundreds of test messages to real addresses, developers can configure the development environment to capture them in a testing inbox.
This makes it possible to repeatedly test different templates without affecting actual customers or generating unnecessary email traffic.
A separate testing environment also reduces the risk of accidentally sending development notifications to production users.
Applications that send large numbers of emails often use background workers instead of processing every message during the original HTTP request.
This approach helps keep the application responsive, but it introduces another potential source of failures.
Imagine an ecommerce application that sends order confirmations after checkout.
In a recent development, the application creates an order successfully and places an email task in a queue. However, the background worker becomes unavailable before processing the task.
The customer receives an order confirmation much later than expected, or perhaps not at all.
To investigate these problems, developers should monitor:.
Retries are particularly important, but they need to be implemented carefully.
A temporary network failure may justify another attempt. A permanent rejection caused by an invalid recipient address usually does not.
Exponential backoff can help prevent repeated requests from overwhelming an unavailable service.
In a production system, add random jitter to avoid having multiple workers retry simultaneously.
Sources indicate that also consider idempotency. If a worker processes the same task twice, the application should avoid sending duplicate transactional messages whenever possible.
A reliable queue architecture should distinguish between temporary failures and permanent failures rather than retrying every error indefinitely.
Testing before deployment is key, but it cannot reveal every matter that may occur in production.
Real email traffic introduces changing conditions, including recipient-server behavior, sender reputation, invalid addresses, and differences between email providers.
Developers should therefore establish ongoing monitoring.
For Gmail-related monitoring, Google Postmaster Tools provides information about domain reputation, spam rates, and authentication.
It is particularly useful for teams sending enough email to generate meaningful reporting data.
Another useful resource is Can I Email, which documents HTML and CSS feature support across email clients.
In a recent development, these tools address different problems. Monitoring sender reputation will not fix a broken password-reset URL, just as validating HTML will not resolve a DNS authentication failure.
The best approach is to monitor each layer independently.
A repeatable checklist helps developers investigate problems without overlooking important details.
Before releasing a new email feature, review the following:.
Confirm that the application successfully submits the message.
Verify that provider credentials and environment variables are correct.
Check the SMTP or API response.
Inspect SPF, DKIM, and DMARC configuration.
Validate the HTML and plain-text versions.
Test links and personalized content.
Preview the message on desktop and mobile email clients.
Verify that development and production configurations are separated.
Test queue failures and retry behavior.
Check delivery events and provider error reports.
Monitor bounce and complaint rates after deployment.
Not every application needs an expensive testing platform or a complicated monitoring stack.
A small project might only require a local email testing environment, basic DNS checks, and structured application logs.
A larger SaaS platform may benefit from automated integration tests, provider webhooks, queue monitoring, authentication reports, and dedicated deliverability testing.
The right setup depends on the application's sending volume, complexity, and the importance of its email workflows.
Reliable email delivery requires more than calling an SMTP function or integrating an email API.
Developers need to understand the complete process, from application logic and message construction to authentication, queue processing, recipient-server acceptance, and inbox placement.
The most effective troubleshooting strategy is to isolate these layers instead of treating every missing message as a template problem.
Start with application logs, inspect provider responses, validate authentication records, test email rendering, and monitor production behavior.
By incorporating these checks into development and deployment workflows, teams can reduce avoidable failures and build applications that communicate more reliably with their users.
Recent findings suggest that 7 Day Free Trial. Cancel Anytime.
Gadgets
⚖️ Neutral
🌐 9to5google
#11396. Samsung bets that you’ll either buy a Galaxy S27 Pro or Ultra next year
📅 09 Nov 2026 • ⏱️ 2m • 📖 Standard (484 w)
Samsung bets that you’ll either buy a Galaxy S27 Pro or Ultra next year
📅 09 Nov 2026 | ⏱️ 2 min read (484 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Samsung is teeing up to kick off 2027 with an all-newly introduced lineup of flagship smartphones, and despite rising prices at your local Best Buy, the brand is still hedging that you’re going to pony up for the most premium model available.
- As reported by ETNews, Samsung is at the moment allotting over 70 percent of its total production capabilities to just the Galaxy S27 Ultra and the new Galaxy S27 “Pro” model expected to launch alongside it.
- In this case, Samsung isn’t actually betting next year’s S27 Ultra is going to surpass its predecessor by record numbers; rather, this is all about adding the S27 Pro as a fourth model for consumers to pick from.
Samsung is teeing up to kick off 2027 with an all-newly introduced lineup of flagship smartphones, and despite rising prices at your local Best Buy, the brand is still hedging that you’re going to pony up for the most premium model available.
As reported by ETNews, Samsung is at the moment allotting over 70 percent of its total production capabilities to just the Galaxy S27 Ultra and the new Galaxy S27 “Pro” model expected to launch alongside it. That leaves the plain Galaxy S27 and the larger S27+ on the outside looking in. In comparison to this year’s launch, the Galaxy S26 Ultra made up about 50 percent of this series’ production volume, for a grand total of 18 million units.
Depends on what the trade-ins are.
In this case, Samsung isn’t actually betting next year’s S27 Ultra is going to surpass its predecessor by record numbers; rather, this is all about adding the S27 Pro as a fourth model for consumers to pick from. As the name implies, the S27 Pro will arrive packed with features usually kept for the Ultra tier exclusively, including Privacy Display and a matching design, but without an S Pen and with a smaller price. While Samsung aims to continue holding the Ultra tier at around 18 million units made, the S27 Pro will cut into the brand’s typical 35 million unit total by about 7 or 8 million. In other words, around 20 percent of sales that would’ve went to the regular S27 or S27+ are expected to move upmarket to this more expensive model.
In a recent development, historical performance implies Samsung is probably correct here. While substantial displays are typically what consumers are drawn to, it does appear that the S27 Pro won’t be all that much smaller than the S27+. Considering the Pro should slot in right around the typical price point as the Plus model, it’s not hard to imagine plenty of would-be S27+ buyers moving to the Pro.
Industry observers note that for what it’s worth, Samsung betting substantial on high-end devices usually pays off. We’re on year two of the Fold series seeing big successes — first with the redesigned Fold 7 in 2025, then with the reshaped Fold 8 this year — and the Galaxy S26 Ultra managed to become the best-selling Android phone in Q2 of this year in a list typically populated by iPhones and cheap Galaxy A-series models. Even with prices constantly on the rise, the people yearn for flagship smartphones. You just have to wonder where that ceiling actually is.
FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Samsung is a technology conglomerate based out o….
Recent findings suggest that will Sattelberg is a writer and podcaster at 9to5Google. You can reach out to Will at will@9to5mac.com, or find him on Twitter @will_sattelberg.
🔗 Related Articles
📰 #23465. Samsung Galaxy’s next major update keeps leaking – here’s what to expect in One UI 9.5 📰 #23458. Tech Report: Deals: Early Black Samsung now live – Galaxy Fold 8 $350 off, S26 Ultra $450 off, Tabs from $200, more 📰 #16224. Next year’s iPhone Pro redesign gets new revision via leaker
General
⚖️ Neutral
🌐 Hugging Face
#11395. Tokenization in Transformers v5: Simpler, Clearer, and More Modular
📅 18 Dec 2025 • ⏱️ 8m • 📚 Deep Dive (1615 w)
Tokenization in Transformers v5: Simpler, Clearer, and More Modular
📅 18 Dec 2025 | ⏱️ 8 min read (1615 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~8 mins left to finish
📖 0% read
💡 Key Takeaways
- Recent findings suggest that transformers v5 redesigns how tokenizers work.
- TL;DR: This blog explains how tokenization works in Transformers and why v5 is a major redesign, with clearer internals, a clean class hierarchy, and a single fast backend.
- For experts: If you're already familiar with the concepts and want to understand the changes in v5, go to v5 Separates Tokenizer Architecture from Trained Vocab.
Recent findings suggest that transformers v5 redesigns how tokenizers work. The massive tokenizers reformat separates tokenizer design from trained vocabulary (much like how PyTorch separates neural network architecture from learned weights). The result is tokenizers you can inspect, customize, and train from scratch with far less friction.
TL;DR: This blog explains how tokenization works in Transformers and why v5 is a major redesign, with clearer internals, a clean class hierarchy, and a single fast backend. It’s a practical guide for anyone who wants to understand, customize, or train model-specific tokenizers instead of treating them as black boxes.
For experts: If you're already familiar with the concepts and want to understand the changes in v5, go to v5 Separates Tokenizer Architecture from Trained Vocab.
Before diving into the changes, let's swiftly cover what tokenization does and how the pieces fit together.
Recent findings suggest that language models don't read raw text. They consume sequences of integers usually called token IDs or input IDs. Tokenization is the process of converting raw text into these token IDs. (Try the tokenization playground here to visualize tokenization.).
Tokenization is a broad concept used across natural language processing and text processing generally. This post focuses specifically on tokenization for Large Language Models (LLMs) using the transformers and tokenizers libraries.
Ġworld (above) is a single token that represents the character sequence " world" (with the space).
According to recent reports, A token is the smallest string unit the model sees. It can be a character, word, or subword chunk like "play" or "##ing" ("##" is a pattern, don't worry if you don't completely understand it now 🤗). The vocabulary maps each unique token to the token ID.
A good tokenizer compresses text into the smallest amount of tokens. Fewer tokens means more usable context without increasing model size. Training a tokenizer boils down to finding the best compression rules for your datasets. For example, if you work on Chinese corpus you can sometimes find very nice surprises 😉.
Industry observers note that tokenization happens in stages. Each stage transforms text before passing it to the next:.
Each component is independent. You can swap normalizers or change the algorithm without rewriting everything else.
You can access the rust based tokenizer through _tokenizer. We go in more depth about it in this section.
The following algorithms dominate modern language model tokenizers:.
The tokenizers library is a Rust-based tokenization engine. It is fast, efficient, and completely language model agnostic. The library handles the mechanics of converting text into token IDs and back. The tokenizers library is a general-purpose tool that implements the tokenization algorithms, but does not implement the conventions that connect those algorithms to specific language models.
Consider what happens when you use tokenizers directly with the SmolLM3-3B model:.
In a recent development, the output is raw tokenization. You get token IDs and the string pieces they correspond to. Nothing more.
It has been revealed that now consider what's missing. The SmolLM3-3B is a conversational model. When you interact with it, you typically structure your input as a conversation with roles like "user" and "assistant". The language model expects special formatting tokens to indicate these roles. The raw tokenizers library has no concept of any of this.
The transformers library bridges this gap. The library is primarily known as a model definition library, but it also provides a tokenizer abstraction layer that wraps the raw tokenizers backend and adds model-aware functionality.
Here's the same tokenization with the transformers wrapper:.
Notice how the special tokens like <|im_start|> and <|im_end|> are applied to the prompt before tokenizing. This is useful for the model to learn where a newly introduced sequence starts and ends.
The transformers tokenizer adds everything the raw library lacks:.
transformers implements the tokenization API that is most commonly used in the entire ML community (encode, decode, convert_tokens_to_ids, etc.).
It has been revealed that the transformers library organizes tokenizers into a class hierarchy. At the top sits a base class that defines the common interface. Below it, backend classes handle the actual tokenization using different engines. At the bottom, model-specific classes configure the backends for particular models.
PreTrainedTokenizerBase is the abstract base class for all tokenizers in transformers. It defines the interface that every tokenizer must implement.
The base class handles functionality that doesn't depend on the tokenization backend:.
Sources indicate that every tokenizer in transformers ultimately inherits from PreTrainedTokenizerBase. The base class ensures consistent behavior across all tokenizers, regardless of which backend they use for the actual tokenization.
TokenizersBackend is the primary backend class for most modern tokenizers. It inherits from PreTrainedTokenizerBase and wraps the Rust-based tokenizers library.
The class stores the Rust tokenizer object internally:.
When you call encoding methods on a TokenizersBackend tokenizer, the class delegates the actual tokenization to the Rust backend:.
The Rust backend performs computationally intensive work, while the Python wrapper adds the model-aware features on top.
Many model-specific tokenizers inherit from TokenizersBackend, examples include:.
These model-specific classes configure the backend with the correct vocabulary, merge rules, special tokens, and normalization settings for their respective models.
Industry observers note that pythonBackend inherits from PreTrainedTokenizerBase and implements tokenization in pure Python. The class is aliased as PreTrainedTokenizer.
The pure-Python backend exists for several reasons:.
The Python backend is slower than the Rust backend. For most use cases, the Rust-backed TokenizersBackend is preferred.
Model-specific tokenizers that inherit from PythonBackend (or its alias PreTrainedTokenizer) include some older or specialized models, like:.
According to recent reports, sentencePieceBackend inherits from PythonBackend and provides integration with Google's SentencePiece library. SentencePiece is a standalone tokenization library that many models use, particularly those trained by Google.
The backend wraps a SentencePiece processor:.
In a recent development, models that use SentencePiece tokenization inherit from this backend. Examples include:.
The SentencePiece backend inherits from PythonBackend rather than directly from PreTrainedTokenizerBase because it shares much of the same interface and padding/truncation logic.
Industry observers note that autoTokenizer is the recommended entry point for loading tokenizers. It automatically determines which tokenizer class to use for a given model and returns an instance of that class.
Behind the scenes, AutoTokenizer performs these steps:.
Industry observers note that the benefit of AutoTokenizer is that you don't need to know which tokenizer class a model uses. Whether a model uses LlamaTokenizer, GPT2Tokenizer, or BertTokenizer, the same AutoTokenizer.from_pretrained("model-name") call works.
The tokenizer system in transformers forms a layered architecture:.
Recent findings suggest that the most significant change in Transformers v5 is a philosophical shift in how tokenizers are defined. Tokenizers now work like PyTorch's nn.Module: you define the architecture first, then fill it with learned parameters.
It has been revealed that in v4, tokenizers were black boxes tied to pretrained checkpoint files. If you loaded LlamaTokenizerFast, you couldn't easily answer basic questions about it:.
The __init__ method gave no clues. You had to dig through serialized files or external documentation to understand what the tokenizer actually did.
v4 also maintained two parallel implementations for every model:.
Worst of all, you couldn't create an empty tokenizer architecture. If you wanted to train a LLaMA-style tokenizer on your own data, there was no clean way to instantiate a "blank" LLaMA tokenizer and fill it with your vocabulary and merges. Tokenizers existed only as loaded checkpoints, not as configurable templates.
v5 treats tokenizer architecture (normalizer, pre-tokenizer, model type, post-processor, decoder) as distinct from trained parameters (vocabulary, merges). This mirrors how PyTorch separates model architecture from learned weights.
With nn.Module, you define layers first:.
V5 tokenizers follow the same pattern:.
In a recent development, the tokenizer class now explicitly declares its structure. Looking at LlamaTokenizer in v5, you can immediately see:.
This transparency was impossible in v4, where the same information was buried in serialized files.
Industry observers note that v5 consolidates the two-file system into a single file per model. LlamaTokenizer now inherits from TokenizersBackend, which wraps the Rust-based tokenizer that was previously exposed as the “fast” implementation and is now the default.
The former “slow” Python implementation lives explicitly behind PythonBackend, and SentencePieceBackend remains for models that require it, but Rust-backed tokenization is the preferred default.
Owners now have one clear entry point. Advanced users who need to customize can still access lower-level components, but the library no longer forces everyone to navigate two parallel implementations.
Recent findings suggest that suppose you want a tokenizer that behaves exactly like LLaMA's – same normalization, same pre-tokenization, same BPE model type – but trained on a domain-specific corpus (medical text, legal documents, a newly introduced language). In v4, this required manually reconstructing the tokenizer pipeline from low-level tokenizers library primitives. In v5, you can instantiate the architecture directly and call train:.
The resulting tokenizer will have your custom vocabulary and merge rules, but will process text identically to how a standard LLaMA tokenizer would with the same whitespace handling, same special token conventions, same decoding behavior.
The shift from "tokenizers as loaded checkpoints" to "tokenizers as configurable architectures" makes the library more modular, more transparent, and more aligned with how practitioners think about building ML systems.
Transformers v5 brings three improvements to tokenization:.
According to recent reports, the wrapper layer between tokenizers and Transformers remains essential. It adds model awareness, context lengths, chat templates, special tokens, that raw tokenization doesn't provide. V5 just makes that layer clearer and more customizable.
If you are looking to learn more about tokenization here are some resources:.
I think it depends on the nature of tools.
What depends on the nature of tools? 😳.
It has been revealed that thanks for doing this! I had to train some tokenizers with the v4, it was indeed not straightforward to understand the behavior.
Glad that this was useful to you.

AI & Tech
⚖️ Neutral
🌐 9to5google
#11394. Google Store previews Black Friday 2026 deals, starting Nov. 19
📅 09 Nov 2026 • ⏱️ 1m • ⚡ Quick Read (93 w)
Google Store previews Black Friday 2026 deals, starting Nov. 19
📅 09 Nov 2026 | ⏱️ 1 min read (93 words, ⚡ Quick Read) | Source: 9to5google
⏱️ ~1 mins left to finish
📖 0% read
💡 Key Takeaways
- With early deals ending yesterday, the US Google Store has now shared its upcoming Black Friday sale that starts on November 19.
- Google shared 12 deals that start on November 19.
- This should only be some of the deals, with more coming next Thursday.
With early deals ending yesterday, the US Google Store has now shared its upcoming Black Friday sale that starts on November 19.
Google shared 12 deals that start on November 19. The list below includes our commentary about the offers:.
This should only be some of the deals, with more coming next Thursday.
According to recent reports, FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Industry observers note that editor-in-chief. Interested in the minutiae of Google and Alphabet. Tips/talk: abner@9to5g.com.
🔗 Related Articles
📰 #23564. Deals: Galaxy SmartTag 3 up to 30% off, Chromebooks, Google Home Speaker, Walmart early Black Friday now live, more 📰 #11328. Deals: Amazon early Black Friday sale, Dell Googlebook, Google Home Speaker, Galaxy Tab S12 Ultra up to $330 off, more 📰 #23538. Proton Pass is up to 60% off for Black Friday—and it does way more than just store your passwords
General
⚖️ Neutral
🌐 Sciencedaily
#11393. Scientists just made quantum computer operations 1,000 times faster
📅 11 Sep 2026 • ⏱️ 6m • 📚 Deep Dive (1146 w)
Scientists just made quantum computer operations 1,000 times faster
📅 11 Sep 2026 | ⏱️ 6 min read (1146 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- According to recent reports, quantum computers remain highly vulnerable to errors and tiny disturbances from their surroundings.
- Quantum computers could eventually transform areas such as drug discovery, energy technology, cryptography, artificial intelligence, and logistics.
- A major challenge is that quantum computations can be disrupted by extremely small environmental effects.
According to recent reports, quantum computers remain highly vulnerable to errors and tiny disturbances from their surroundings. The longer a quantum operation takes to complete, the more time there is for those errors to build up. Researchers at Chalmers University of Technology in Sweden have now developed a method that can perform a broad range of advanced quantum operations more than a thousand times faster. The advance tackles a major obstacle in the field and could help move quantum computing closer to becoming fault-tolerant.
Quantum computers could eventually transform areas such as drug discovery, energy technology, cryptography, artificial intelligence, and logistics. Before that can happen, however, these machines need to become much more dependable.
Why Quantum Computers Are So Error-Prone.
A major challenge is that quantum computations can be disrupted by extremely small environmental effects. Electrical noise, cosmic radiation, and overheating can all introduce errors while information is being processed.
Traditional computers can experience errors too, but decades of development have produced reliable error correction methods that can promptly detect and repair them. Quantum systems are much harder to protect because the information they use is extraordinarily delicate.
Industry observers note that "The fundamental building blocks of quantum computers, known as qubits, are so sensitive that even the smallest disturbance can cause the quantum state to deviate from the target, resulting in the loss of information. If too many errors accumulate before they can be corrected, the computation can fail," indicates Lei Du, researcher in Applied Quantum Physics at Chalmers University of Technology in Sweden, and lead author of the theoretical study published in the journal Physical Review Letters.
A Different Way to Protect Quantum Information.
Sources indicate that to make quantum computing more resilient and eventually fault-tolerant, researchers are investigating latest ways to shield quantum information from errors. One promising strategy uses so-called bosonic quantum codes*.
Instead of assigning quantum information to individual qubits, this approach stores it in microwave fields inside superconducting circuits.
Industry observers note that "Rather than storing quantum information in individual qubits, bosonic codes encode information in the microwave fields found within superconducting circuits. This approach has been shown to provide stronger protection against certain types of errors," explains Tangyou Huang, researcher in Quantum Technology at Chalmers and co-author of the study.
Quantum Operations More Than 1,000 Times Faster.
It has been revealed that working with bosonic quantum codes is not simple. Creating and controlling the required quantum states has traditionally involved guiding a quantum system through thousands of repeated driving cycles.
That process can take considerable time, and every additional cycle creates another opportunity for outside disturbances to interfere with the calculation. In quantum computing, speed is therefore closely tied to reliability.
In a recent development, chalmers researchers Lei Du and Tangyou Huang have now proposed a different strategy. Rather than constructing the desired quantum states one small piece at a time, their method can perform a wide variety of operations much faster.
"Our method shows that a diverse range of quantum operations on bosonic states can be completed within a single driving cycle, rather than the several thousand cycles that have been required previously. This makes the operations both faster and more efficient, while reducing the risk that disturbances will corrupt the information before the process is finished. It represents an important step towards fault-tolerant quantum computers," says Lei Du.
Quantum Lattice Gates Provide a Shortcut.
The fresh approach is built around Quantum lattice gates, a recently proposed universal set of quantum gates developed by the same research team.
Industry observers note that these gates act somewhat like shortcuts. Instead of requiring a long sequence of repeated control steps, they can allow the intended quantum operation to be completed in just one driving cycle. That could make the process faster, simpler, and less vulnerable to errors.
In a recent development, "You can think of it like building a large Lego castle. Instead of assembling it brick by brick and risking mistakes along the way, quantum lattice gates act like pre-built Lego modules that can be connected rapidly and efficiently," claims Tangyou Huang.
Designed for Superconducting Quantum Computers.
The technique is especially well suited to superconducting quantum computers, which are among the most prominent technologies being developed in the international push toward large-scale quantum computing.
Chalmers University of Technology is also using superconducting technology as it develops a 100-qubit quantum computer.
"A key advantage of our approach is that it can be implemented using existing superconducting quantum circuit platforms. We are already discussing possible experimental realizations with colleagues at Chalmers, and we hope to see a demonstration of the method in the near future," says Tangyou Huang.
The researchers say the work addresses a central problem facing the field: efficiently producing and controlling quantum states that are capable of helping correct errors.
"Our results address one of the major bottlenecks in the field: how to rapidly and reliably create and control the error-correcting quantum states that could play an important role in future quantum computers," notes Lei Du.
More About Bosonic Codes, Quantum Lattice Gates and Floquet Control.
According to recent reports, *Bosonic quantum codes store quantum information in the states of, for example, microwave or optical resonators rather than in individual qubits. They are considered a promising tool for quantum error correction because they can provide built-in protection against certain types of errors.
Sources indicate that quantum operations are needed to process that stored information. Quantum lattice gates are a recently proposed collection of basic building blocks that can be used to control bosonic quantum states. By combining and designing these gates, researchers can carry out a wide range of more complicated quantum operations.
One method for implementing these operations is known as Floquet control, which uses periodic control signals to drive a quantum system. Earlier Floquet-based techniques have generally depended on slower processes involving many repeated driving cycles. The approach developed at Chalmers can instead perform quantum lattice gates directly in a single driving cycle, making some operations more than a thousand times faster.
Industry observers note that the scientific paper "Single-Period Floquet Control of Bosonic Codes with Quantum Lattice Gates" has been published in Physical Review Letters. The authors are Tangyou Huang, Lei Du, and Lingzhen Guo. The researchers are affiliated with Chalmers University of Technology in Sweden and Tianjin University in China.
The research was funded by the National Natural Science Foundation of China (NSFC), the Wallenberg Centre for Quantum Technology (WACQT), and the Knut and Alice Wallenberg Foundation.
Materials provided by Chalmers University of Technology. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #11351. This latest qubit could be 100 times less error-prone in superfluid quantum computer breakthrough 📰 #23589. Latest Update: American Express just made one of its most popular credit card perks even better 📰 #22613. Tech Report: Scientists just discovered what coffee really does to your gut and brain
General
⚖️ Neutral
🌐 Eurogamer
#11392. In Charting the Unknown, Crimson Desert doubles down on its maximalism in audacious, faintly sinister style
📅 06 Nov 2026 • ⏱️ 6m • 📚 Deep Dive (1133 w)
In Charting the Unknown, Crimson Desert doubles down on its maximalism in audacious, faintly sinister style
📅 06 Nov 2026 | ⏱️ 6 min read (1133 words, 📚 Deep Dive) | Source: Eurogamer
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- Recent findings suggest that and so we are back in Pywel: the super-sized and often super-pretty realm where the deserts are blood-red, the grass is a lurid shade of green, and Kliff and his merry gang of Greymanes seem to be pissed all the time.
- According to recent reports, at the outset of Charting the Unknown, Crimson Desert's recently released DLC, I'm tasked with taking Kliff out for a quiet spot of moonlit fishing.
- According to recent reports, you might reasonably assume that these types of basic explanatory wrinkles had been ironed out in the countless updates since Crimson Desert's release in March.
Recent findings suggest that and so we are back in Pywel: the super-sized and often super-pretty realm where the deserts are blood-red, the grass is a lurid shade of green, and Kliff and his merry gang of Greymanes seem to be pissed all the time. Yet what's this? Peace seems to have broken out across the region, which means our grizzled action hero is in a reflective mood.
According to recent reports, at the outset of Charting the Unknown, Crimson Desert's recently released DLC, I'm tasked with taking Kliff out for a quiet spot of moonlit fishing. The problem is, I seem to have forgotten how to actually fish - and if memory serves, perhaps I never learned because the system was so poorly explained in the base game. So I flail around for a full 15 minutes before eventually relenting and consulting Reddit on how to snag a bite.
According to recent reports, you might reasonably assume that these types of basic explanatory wrinkles had been ironed out in the countless updates since Crimson Desert's release in March. Certainly, developer Pearl Abyss has gone to great effort elsewhere to streamline what was, at times, a frustratingly clunky experience (those menus at launch, oh god) while adding even more stuff, such as all-newly introduced cutscenes (to improve the story's legibility) and the ability to ride wolves and tigers (because why the hell not). But for all the tinkering and wholesale additions, Crimson Desert has retained its essential character: the menus remain a total faff and the narrative, which I started afresh some weeks ago, is still bafflingly incoherent (maybe even more than I initially appreciated).
It's into this churn of ongoing development that Pearl Abyss has produced Charting the Unknown, a DLC which adds even more elements to a game already buckling under the weight of mechanical overload. Now you can build ships and sail them around Pywel's azure-blue waters. You can dive below the waves and swim with the fishes. You can also fall in love, get married, and - should things not pan out - get divorced. The everything game has become, well, even more everything in quintessentially audacious style. On that note, just wait until you see some of its supermassive Evangelion-esque maritime bosses.
Though don't get too excited. Like the base game, the DLC is a mixed bag. First, shipfaring lacks any kind of drama. Islands are so spread out as to make the actual journey painfully boring: impressionistic oceanic voyaging à la Wind Waker this is not. The diving, though, is beautifully executed. Underwater locales are notably serene, free from many of the irritating distractions that plague ground traversal.
In a recent development, as for the upcoming narrative threads involving all three playable characters - grizzled Kliff, Bayonetta-alike Damiane, and gentle giant orc Oongka - they're equally uneven. Kliff's is the most interesting, transplanting the player to a desert cloaked in a thick orange sandstorm that, without the aid of a working compass, must be mapped out using beacons resembling luminescent dongs. It's pleasingly disorientating, a rare example of Pearl Abyss pushing a kind of intentional design friction, rather than accidentally creating it by inadequately explaining how to interact with the game.
Industry observers note that alas, there are also bugs, one of which was game-halting: Damiane's steed wouldn't spawn when I needed to follow Kliff on horseback. It was a reminder that for all the visual splendour, Crimson Desert can often feel like it's being held together by the code equivalent of gaffer tape.
In a recent development, everything controls about as well as you'd expect if you've played the base game, i.e. not very well at all. Kliff may be able to run on water and soar through the sky like a cross between Matrix star Neo and Jesus, but he remains a bastard to control for even the most basic tasks. Why can't I lock onto the object a foot away? Why is he doing a three-hit combo somersault through the air when all I tried to do is pull out his lantern? These complications are compounded by the new romance and socialising options that appear every time you target an NPC: Crimson Desert becomes even fiddlier as it introduces these additional layers.
As the hours pass by - as I run, gallop, and bound through the arresting landscape in a manner that is comparatively frictionless compared to the rest of the game - my mind begins to numb. For all the extraneous mechanical gubbins, missions remain brainlessly simple: cavort from one waypoint to another and do a few simple button presses, or crack a few skulls to chug the narrative along. But then perhaps a certain numbing is the point of Crimson Desert? At a time when the real world is markedly inhospitable (diminishing job prospects, the ongoing cost-of-living crisis, the looming threat of geopolitical meltdown), Pearl Abyss' epic swaddles the player like a swords-and-sorcery comfort blanket. It is a safe space to disappear into for hours. Leave your worldly woes at the start screen.
The impression this mash-up of a game appears to want to impart is generosity: here, Pearl Abyss seems to say, is a product capable of accommodating your every wish, will, and whim. It appears to have left no gameplay stone unturned in its ultimate quest to provide the player with total satisfaction - a kind of blissed-out contentment at the thought of never having to leave this almost divine realm.
According to recent reports, but rather than generous, perhaps there is something nefarious about Crimson Desert's maximalist design philosophy. It strikes me again that this is the most uniquely modern title I've ever played, as if the Grand Theft Auto and Assassin's Creed franchises, countless MMORPGs (the genre in which Pearl Abyss cut its teeth), and many hyper-compulsive mobile titles were squished together in an attention-devouring final form. One so mightily captivating, so singularly consuming, that the player keeps playing until their lifeforce is depleted and they can play no more.
That seems to be the way these "forever" games curve: toward the player's surrender - of mind, body, and time. And at least until Grand Theft Auto 6 is released in a few weeks, Crimson Desert and its new DLC seem to be the purest expression yet of this type of thing. Wading through its sheer mass of hit-or-miss distractions (which could expand even more), the design ethos begins to grate. As if I'm stuck in an elaborate, endlessly bifurcating maze of hamster wheels, always busy, though never enjoying any discernible pay-off. And so, as its presentational lustre wears off further, and its eye-popping massiveness becomes less of a novelty, Crimson Desert begins to hit differently: much less high-fantasy heaven and more like hell.
🔗 Related Articles
📰 #19939. Tech Report: Dakota Johnson Doubles Down on Animal Print for a Night Out With MGK 📰 #17164. Latest Update: Bandai Namco Shuts Down Unknown 9: Awakening Developer Reflector Entertainment 📰 #17065. Crimson Desert PC specs don't keep resolution and framerate targets a secret, and they don't use upscaling for everything either
General
⚖️ Neutral
🌐 Dexerto
#11391. Xbox shuts down confusion over whether Project Helix is actually a PC
📅 16 Nov 2026 • ⏱️ 4m • 📚 Deep Dive (834 w)
Xbox shuts down confusion over whether Project Helix is actually a PC
📅 16 Nov 2026 | ⏱️ 4 min read (834 words, 📚 Deep Dive) | Source: Dexerto
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- Microsoft has clarified what gamers can expect from its next-generation Xbox console, Project Helix, addressing questions about whether the upcoming hardware will essentially be a gaming PC.
- With Xbox increasingly bringing its games and services to PC, handhelds, and other platforms, the distinction between a traditional console and a Windows gaming device has become less clear.
- Project Helix aims to bridge that gap by supporting PC games while retaining the experience players expect from Xbox hardware.
Microsoft has clarified what gamers can expect from its next-generation Xbox console, Project Helix, addressing questions about whether the upcoming hardware will essentially be a gaming PC.
With Xbox increasingly bringing its games and services to PC, handhelds, and other platforms, the distinction between a traditional console and a Windows gaming device has become less clear.
Project Helix aims to bridge that gap by supporting PC games while retaining the experience players expect from Xbox hardware.
In a new article published by Xbox, Jason Ronald, the organization’s Vice President of Next Generation, explained how Microsoft is approaching the system’s development and why it isn’t simply building a gaming PC with Xbox branding.
Speaking about the system’s design philosophy, Ronald made it clear that Microsoft still considers Project Helix a dedicated gaming console, despite its expanded PC capabilities.
“We’re very clear on the design goal: Helix is designed to be a console that is also capable of playing games from your PC,” he said.
Industry observers note that “It is not a PC that can also play console games. The goal is making it easy, intuitive, and instant to access my games. But if you’re a hardcore gamer or a power user who wants to have that deeper level of customizability across settings and performance options, you can absolutely go do it.”.
Microsoft is designing Project Helix to offer the simplicity of a traditional console while giving players access to PC games, removing the need to manage operating system updates, graphics drivers, and other technical settings that can complicate the experience.
Xbox CEO describes next-gen Helix console as a “family of devices”.
Next-gen Xbox consoles could reportedly cost up to $1,800.
Next Xbox console will play every generation according to leaked Microsoft memo.
Ronald explained that the hardware should allow players to jump directly into their games without worrying about operating system updates, graphics drivers, or complicated settings.
“With this, I think about what makes a console magical, it’s that it just makes my games instantly accessible and ready to play in an instant. I don’t have to worry about updating my operating system, updating drivers, configuring different settings – things like that. The hardware and the experience is entirely designed around playing games.”.
However, Microsoft isn’t abandoning the flexibility of PC gaming entirely. Players who want to customize performance settings and other technical options will still have access to those features.
According to recent reports, the manufacturer also pointed to the ROG Xbox Ally and its dedicated Xbox mode as important steps toward Project Helix. Feedback from the handheld’s integration of PC and console game libraries has helped shape Microsoft’s intends for its next-generation interface.
Ronald described the handheld as a precursor to Project Helix, explaining that its development has provided valuable insight into how players interact with games across different platforms.
Beyond PC compatibility, Microsoft is emphasizing game preservation and backward compatibility as major priorities for its next console.
Ronald mentioned Project Helix is intended to bring together Xbox’s existing library while allowing players to carry their games and progress between devices.
“When I think about Project Helix,” explains Jason Ronald, XBOX Vice President of Next Generation, “it’s really designed to be the ultimate gaming machine – one that removes all the barriers of play that have historically existed. My entire library is accessible to me. I’m able to bring four generations of my XBOX library and progression with me and have it available instantly. And we remove the arbitrary constraints between console and PC games.”.
Microsoft also wants to make moving between devices a more seamless experience, with Ronald describing a future where players can resume games regardless of which screen they’re using.
“It’s also this notion that not only does my library move with me, but my progress moves with me as well. Because I fully expect that when I’m in the middle of an 80-hour RPG, if I’m 25 hours into that and I want to play it on another device, I should be able to instantly resume from where I was.”.
The organization claims backward compatibility remains a core part of its strategy, building on preservation efforts introduced with the Xbox One and expanded through the Xbox Series X|S generation.
Microsoft is also looking beyond traditional hardware improvements such as higher resolutions and frame rates. Ronald highlighted neural rendering as one area of development that could improve visual fidelity without requiring proportionally greater computational power.
“We have to invent entirely latest technology to continue to advance the state-of-the-art,” he explained, pointing to the rising costs of hardware components as another challenge facing the next generation.
Project Helix is still in development, and Microsoft has not confirmed its final specifications, pricing, release date, or which PC storefronts will be supported.
Although Project Helix will support PC games and offer additional customization options for more experienced consumers, Microsoft is maintaining its focus on delivering a traditional console experience while expanding the range of games players can access.
🔗 Related Articles
📰 #16963. 'The Ultimate Gaming Machine' - Xbox Reveals Tons Of Latest Project Helix Information 📰 #16734. Xbox promises buzzwords like ‘gameplay innovation’ and ‘deeper immersion’ for Project Helix, but all I care about is its price tag 📰 #16668. Breaking: The next Xbox, Project Helix, is a console and "not a PC" states Microsoft, as it clarifies that computational power isn't sole focus this time
Gadgets
⚖️ Neutral
🌐 9to5toys
#11390. Monday’s Android app deals and freebies: Absolum, Death Worm, Minabo, more
📅 09 Nov 2026 • ⏱️ 2m • 📖 Standard (398 w)
Monday’s Android app deals and freebies: Absolum, Death Worm, Minabo, more
📅 09 Nov 2026 | ⏱️ 2 min read (398 words, 📖 Standard) | Source: 9to5toys
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Be sure to follow us on Twitter for the latest deals and more.
- According to recent reports, the newly introduced Samsung Galaxy SmartTag 3 tracker is now available for purchase alongside the ongoing all-time low on Google Home Speaker, but today’s best Google Play app and game deals are ready as well: Absolum, Death Worm Deluxe, Pixel Knight, Minabo: A walk through life, Sword of Palmira, Endurance: dead space Premium, Path to Mnemosyne, and more.
- All-new Samsung Galaxy SmartTag 3 UWB tracker now available for purchase from $25 each.
Be sure to follow us on Twitter for the latest deals and more. Sign-up for our newsletters and have our best offers delivered to your inbox daily.
According to recent reports, the newly introduced Samsung Galaxy SmartTag 3 tracker is now available for purchase alongside the ongoing all-time low on Google Home Speaker, but today’s best Google Play app and game deals are ready as well: Absolum, Death Worm Deluxe, Pixel Knight, Minabo: A walk through life, Sword of Palmira, Endurance: dead space Premium, Path to Mnemosyne, and more. Just be sure to dive into Galaxy Z Fold 8 at $300 off with a FREE set of new Galaxy Buds On ($530 off) and some of the first deals yet on the new Google Fitbit Edge. The apps await below.
All-new Samsung Galaxy SmartTag 3 UWB tracker now available for purchase from $25 each.
Google Home Speaker hits all-time low in early Black Friday sale at 20% off, more Nest smart home deals.
Farm Life RPG: Golden FieldsFREE (Reg. $7).
MonsterNova: Team Builder$1 (Reg. $5).
European Truck Simulator$0.25 (Reg. $2.50).
[VIP] Mr. Balcan IdleFREE (Reg. $10).
Recent findings suggest that path to Mnemosyne$1 (Reg. $4.50).
Recent findings suggest that midori Green – Icon PackFREE (Reg. $1).
Industry observers note that himawari Yellow – Icon PackFREE (Reg. $1).
Endurance: dead space Premium$0.25 (Reg. $2.50).
Twilight Struggle$2.50 (Reg. $10).
Some of the first deals on newly introduced Google Fitbit Edge now live from $126 (Best Buy open-box).
Samsung Black Friday deal: Galaxy Z Fold 8 now $300 off w/ FREE set of fresh Galaxy Buds On ($530 off).
In a recent development, deadhand Protocol: Card RPG$0.25 (Reg. $1.50).
Recent findings suggest that paws Against the World Premium$1 (Reg. $4).
Minabo: A walk through life$1 (Reg. $4.50).
According to recent reports, pixel Knights VIPFREE (Reg. $0.50).
It has been revealed that pirates Fury: Stealth ActionFREE (Reg. $2.75).
Sources indicate that horror Apartment-Scary GameFREE (Reg. $3).
Last Wolf of Pine ForestFREE (Reg. $4).
No More Slimes: Idle Action$6 (Reg. $10).
In a recent development, FTC: We use income earning auto affiliate links. More.
It has been revealed that justin is a senior deal Jedi over at 9to5Toys where he heads up our game/app coverage and more. He also covers all things music for 9to5Mac, including the weekly Logic Pros series exploring music production on Mac and iOS devices.
🔗 Related Articles
📰 #23446. Monday’s Android app deals and freebies: Final Fantasy games, Dragon Quest, Ash of Gods, more 📰 #23623. Industry News: Mid-week Android app deals and freebies: Wind Peaks, Box Head, 9th Dawn, more 📰 #23553. Industry News: Today’s Android app deals and freebies: Agent A, Swim Out, The Mutiny, more
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11389. AprielGuard: A Guardrail for Safety and Adversarial Robustness in Modern LLM Systems
📅 23 Dec 2025 • ⏱️ 8m • 📚 Deep Dive (1542 w)
AprielGuard: A Guardrail for Safety and Adversarial Robustness in Modern LLM Systems
📅 23 Dec 2025 | ⏱️ 8 min read (1542 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~8 mins left to finish
📖 0% read
💡 Key Takeaways
- It has been revealed that large Language Models (LLMs) have rapidly evolved from text-only assistants into complex agentic systems capable of performing multi-step reasoning, calling external tools, retrieving memory, and executing code.
- In this work, we introduce AprielGuard, an 8B parameter safety–security safeguard model designed to detect:.
- AprielGuard is available in both reasoning and non-reasoning modes, enabling explainable classification when needed and low-latency classification for production pipelines.
It has been revealed that large Language Models (LLMs) have rapidly evolved from text-only assistants into complex agentic systems capable of performing multi-step reasoning, calling external tools, retrieving memory, and executing code. With this evolution comes an increasingly sophisticated threat landscape: not only traditional content safety risks, but also multi-turn jailbreaks, prompt injections, memory hijacking, and tool manipulation.
In this work, we introduce AprielGuard, an 8B parameter safety–security safeguard model designed to detect:.
AprielGuard is available in both reasoning and non-reasoning modes, enabling explainable classification when needed and low-latency classification for production pipelines.
Sources indicate that traditional safety classifiers primarily focus on a limited classification spectrum (e.g., toxicity or self-harm), assume short inputs, and evaluate single user messages. Modern deployments, however, feature:.
In a recent development, as a result, production teams increasingly rely on workarounds: multiple guard models for different stages, regex filters, static rules, or hand-crafted heuristics. These approaches are brittle and do not scale.
AprielGuard addresses these issues with a unified model and a unified safety + adversarial taxonomy, built specifically for modern LLM agent ecosystems.
AprielGuard operates across three input formats:.
(These 16 categories are inspired from SALAD-Bench).
Sources indicate that the model detects and evaluates a wide range of adversarial prompt patterns designed to manipulate model behavior or evade safety mechanisms. The model outputs a binary classification (e.g., adversarial / non_adversarial) rather than fine-grained attack categories.
According to recent reports, the training data covers diverse adversarial types such as role-playing, world-building, persuasion, and stylization, among many other complex prompt manipulation strategies. These examples represent only a subset of the broader adversarial scenarios incorporated in the training data.
It has been revealed that synthetic data: AprielGuard is trained on a synthetically generated training dataset. The training data points are generated at a sub-topic level of the taxonomy for better coverage. We leverage Mixtral-8x7B and internally developed uncensored models to generate unsafe content for training purposes. Models were prompted with higher temperature to induce output variation. Prompting templates are meticulously tailored to ensure accurate data generation. Adversarial attacks are constructed using a combination of synthetic data points, diverse prompt templates, and rule-based generation techniques. We leveraged NVIDIA NeMo Curator to generate large-scale, multi-turn conversational datasets featuring complex, realistic scenarios with iterative and evolving attacks through context switches. This approach enabled us to systematically synthesize diverse interaction patterns, improving the robustness of the model to long-horizon reasoning, adversarial turns, and evolving user intent. We also used SyGra framework for synthetic data generation processes for harmful prompts and attacks generation. The training dataset encompasses diverse content formats such as conversational dialogues, forum posts, tweets, instructional prompts, questions, and how-to guides.
It has been revealed that data augmentation: To enhance model robustness, a range of data augmentation techniques were applied to the training data. These augmentations are designed to expose the model to natural variations and perturbations that commonly occur in real-world scenarios. Specifically, the dataset includes transformations such as character-level noise, insertion of typographical errors, leetspeak substitutions, word-level paraphrasing, and syntactic reordering. Such augmentations help the model generalize better by reducing sensitivity to superficial variations in input, thereby improving resilience against adversarial manipulations and non-standard text representations.
Sources indicate that agentic workflows: Agentic workflows represent real-world scenarios where autonomous agents execute multi-step tasks involving planning, reasoning, and interaction with tools, APIs, and other agents. These workflows often include sequences of user prompts, system messages, intermediate reasoning steps, and tool invocations, making them susceptible to diverse attack vectors. To construct these training data points, we synthetically generate a wide range of scenarios across multiple domains, capturing realistic agentic interactions between a user and an agentic system. Each data point is enriched with detailed contextual elements—including tool definitions, tool invocation logs, agent roles and policies, execution traces, conversation history, memory states, and scratch-pad reasoning. For malicious or adversarial examples, we corrupt the relevant segment of the workflow to reflect a specific attack vector. Depending on the scenario, this may involve modifying user prompts, altering intermediate reasoning traces, modifying the tool outputs, injecting false memory states, or disrupting inter-agent communication. By systematically perturbing different components of the agentic workflow, we produce high-fidelity examples that expose a model to a diverse spectrum of realistic and challenging attack patterns. Each data point was simulated to reflect realistic executions, incorporating both benign and adversarial sequences.
Recent findings suggest that long context use cases: We curated a specialized long context dataset composed of diverse, high-length use cases such as Retrieval-Augmented Generation (RAG) work-flows, multi-turn conversational threads, incident details, and operational reports containing detailed communications. These examples simulate real-world environments where large text contexts are typical.
AprielGuard is built on top of an Apriel-1.5 Thinker Base variant, downscaled to an 8B configuration for efficient deployment.
AprielGuard is evaluated across:.
AprielGuard performance on the public safety benchmarks.
A comparative assessment of model performance using aggregated results from safety benchmarks.
AprielGuard performance on the public adversarial benchmarks.
A comparative assessment of model performance using aggregated results from adversarial benchmarks.
We curated an internal benchmark dataset aimed at evaluating the detection of Safety Risks and Adversarial Attacks within agentic workflows. To construct this benchmark, we systematically designed multiple attack scenarios targeting different components of the workflow—such as prompt inputs, reasoning traces, tool parameters, memory states, and inter-agent communications. Each instance was annotated according to the taxonomy of vulnerabilities. Each workflow was simulated to reflect realistic executions, incorporating both benign and adversarial sequences. The dataset captures granular attack points across various stages such as planning, reasoning, execution, and response generation to provide fine-grained evaluation of model robustness. Overall, the dataset comprises a balanced mixture of safety risks and adversarial attacks.
Safety performance of different models on the agentic benchmark.
Adversarial performance of different models on the agentic benchmark..
Many real world safety or adversarial risks do not manifest in short, isolated text snippets, but rather emerge across use cases such as Retrieval-Augmented Generation (RAG) workflows, multi-turn conversational threads, organizational incident details, and operational reports containing detailed communications. A guardian model must therefore detect subtle or "needle-in-a-haystack" cases, where malicious or manipulative content is sparsely distributed, embedded across multiple references, or intentionally obscured within benign text.
Sources indicate that to evaluate AprielGuard’s long-context reasoning capabilities, we curated a specialized test dataset composed of diverse, high-length use cases. We considered the data upto 32k tokens for this evaluation. The baseline data was initially constructed from benign content representative of these domains. Malicious elements were then systematically injected to simulate adversarial or unsafe scenarios while maintaining the overall coherence of the text. For example, in an incident case summarization, an injection could be embedded within the case description, hidden in a metadata section, or inserted as part of a comment thread. Similarly, in multi-turn dialogue data, adversarial content might appear mid-conversation, near the end or at the beginning to test long range dependency tracking.
Adversarial Attacks performance.
A major limitation in the current landscape of content moderation research is the scarcity of high- quality multilingual benchmarks. To address this gap and comprehensively assess the multilingual capabilities of AprielGuard, we extended the Safety Risks benchmarks and Adversarial Attack benchmarks into multiple non-English languages. The translation process was conducted using the MADLAD400-3B-MT model, a multilingual machine translation model based on the T5 architecture.
It has been revealed that for this study, we selected eight of the most widely used non-English languages to ensure broad linguistic and geographical coverage: French, French-Canadian, German, Japanese, Dutch, Spanish, Portuguese-Brazilian, and Italian. Each instance from the English Safety and Adversarial benchmarks was translated into the eight target languages. During translation, we preserved the original English role identifiers, such as User: and Assistant:, while translating only the conversational content. This design choice ensures alignment with AprielGuard’s moderation framework, where the role context plays a crucial part in evaluating safety and adversarial intent.
Multilingual performance of AprielGuard.
Recent findings suggest that as LLMs move toward deeply integrated agentic systems, the need for unified pipelines becomes more critical. AprielGuard is a step toward that future — reducing complexity, improving coverage, and offering a scalable foundation for trustworthy AI deployments.
Language Coverage: While AprielGuard has been primarily trained on English data, limited testing indicates it performs reasonably well across several languages, including: English, German, Spanish, French, French (Canada), Italian, Dutch, and Portuguese (Brazil). However, thorough testing and calibration are strongly recommended before deploying the model for production use in non-English settings.
Adversarial Robustness: Despite targeted training on adversarial and manipulative behaviors, the model may still exhibit vulnerability to complex or unseen attack strategies.
Domain Sensitivity: AprielGuard may underperform on highly specialized or technical domains (e.g., legal, medical, or scientific contexts) that require nuanced contextual understanding.
Latency–Interpretability Trade-off: Enabling reasoning traces enhances explainability but increases latency and compute cost. For low-latency or large-scale use cases, non-reasoning mode is recommended.
Reasoning Mode Sensitivity: The model exhibits occasional inconsistencies in classification outcomes between reasoning-enabled and non-reasoning inference modes.
It has been revealed that intended use: AprielGuard is intended strictly for use as a safeguard and risk assessment model. It classifies potential safety risks and adversarial threats according to the AprielGuard unified taxonomy. Any deviation from the prescribed inference may lead to unintended, unsafe, or unreliable behavior.
Interesting work! 👏 Will you also publish the translated multilingual benchmarks?

General
⚖️ Neutral
🌐 Sciencedaily
#11388. Tiny nanolaser could cut computer energy use in half
📅 11 Sep 2026 • ⏱️ 3m • 📚 Deep Dive (610 w)
Tiny nanolaser could cut computer energy use in half
📅 11 Sep 2026 | ⏱️ 3 min read (610 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- The development of a nanolaser could mark an early step toward a future in which microchips communicate entirely with particles of light.
- Researchers at DTU have created a tiny nanolaser that could eventually help make computers, smartphones, and data centers faster while using much less energy.
- In the future, thousands of these lasers could potentially be integrated onto a single microchip.
The development of a nanolaser could mark an early step toward a future in which microchips communicate entirely with particles of light.
Researchers at DTU have created a tiny nanolaser that could eventually help make computers, smartphones, and data centers faster while using much less energy. The breakthrough was published in the scientific journalScience Advances.
In the future, thousands of these lasers could potentially be integrated onto a single microchip. Instead of moving information around a chip with electrical signals, devices could transmit data using photons, the particles that make up light.
"The nanolaser opens up the possibility of creating a upcoming generation of components that combine high performance with minimal size. This could be in information technology, for example, where ultra-small and energy-efficient lasers can reduce energy consumption in computers, or in the development of sensors for the healthcare sector, where the nanolaser's extreme light concentration can deliver high-resolution images and ultrasensitive biosensors," says DTU professor Jesper Mørk.
Mørk co-authored the study with, among others, Drs. Meng Xiong and Yi Yu from DTU Electro.
Using Light Inside Computer Chips.
Much of the internet already relies on light to carry information through fiber optic cables. Inside computers, however, data still moves through electronic circuits using electricity. That approach produces heat and can limit how quickly information can be transferred.
Nanolasers could bring optical communication directly onto microchips. By generating light signals efficiently inside the chip, they could allow information to move with very little energy loss, potentially making future devices faster, cooler, and more energy efficient.
Mørk estimates that using nanolasers in computers could reduce energy consumption by as much as half.
The compact DTU nanolaser is an key step toward that goal. Future chips designed around light-based communication would likely require thousands of extremely small, efficient lasers working together to transmit information across the chip.
Breaking the Size Limit for Lasers.
The upcoming nanolaser was created in DTU's clean room facility, DTU Nanolab. According to Mørk, the device pushes beyond the conventional limit for how small a laser can be made.
At its core is a structure known as a nanocavity, which traps and concentrates light within an exceptionally tiny space. Until now, achieving such intense confinement at this scale had been considered extremely difficult.
When researchers shine a beam of light onto the device, both photons and electrons become concentrated in the same microscopic region. This interaction allows the laser to function at room temperature while requiring unusually little energy.
The light-trapping structure used in the nanolaser was originally developed by Professor Ole Sigmund's group at DTU Construct.
Faster Devices and Lower Energy Use.
In a recent development, the next major challenge is making the nanolaser operate using electrical power. If researchers can achieve that, the technology could have broad applications across computing, communications, and healthcare.
According to recent reports, computers and smartphones could potentially deliver greater performance while consuming less electricity. Data centers, which require enormous amounts of power, could also see substantial reductions in energy use, potentially leading to significant climate benefits.
In healthcare technology, the nanolaser's ability to concentrate light into an extremely small area could support ultra-sensitive sensors and high-resolution imaging systems.
Researchers estimate that the remaining technical challenges could be solved within the next 5-10 years.
Materials provided by Technical University of Denmark. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
General
⚖️ Neutral
🌐 Eurogamer
#11387. Industry News: What we've been playing - "Sniffing out the warehouses on Prawn Island"
📅 07 Nov 2026 • ⏱️ 6m • 📚 Deep Dive (1119 w)
Industry News: What we've been playing - "Sniffing out the warehouses on Prawn Island"
📅 07 Nov 2026 | ⏱️ 6 min read (1119 words, 📚 Deep Dive) | Source: Eurogamer
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- I am once again wearing the Bertie hat in your usual host's absence, so joyous welcomes to our regular feature in which we talk about what we've been playing in recent times.
- Sources indicate that but enough about us, what about you?
- According to recent reports, once again, I am finally playing a game from my backlog that I should've played years ago, and that's the delightful albeit dark card game Inscryption.
Well, hello! I am once again wearing the Bertie hat in your usual host's absence, so joyous welcomes to our regular feature in which we talk about what we've been playing in recent times. This week, Marie has been revisiting Zelda - although perhaps not the one you might expect - while Dom is rediscovering Vice City of the 80s. Kelsey is playing some very weird cards, Connor is back in WoW - possibly forever - and I'm equally smitten with a different RPG.
Sources indicate that but enough about us, what about you? What have you been playing this week? Do tell all! And don't forget we have an entire archive of previous What We've Been Playings for your leisurely perusal, just in case you forgot what you were playing a year or a month or a week ago. Bye!
According to recent reports, once again, I am finally playing a game from my backlog that I should've played years ago, and that's the delightful albeit dark card game Inscryption. There's so much more to this than you'd first expect, and I'm surprised the community has been able to keep the game's best bits under wraps for so long. Ultimately, nothing could've prepared me for Act 2, and my only real qualm with the whole experience is that I wish Act 2 had its own endless roguelike mode; you'd never be able to pull me away from it.
In a recent development, the game falters a little at the start of Act 3, I'll admit, and I've found myself very frustrated by what is an otherwise relatively easy time. This is down to me missing some rather useful earlier cards that I've since learnt would've made this final stretch much breezier, but oh well. I will still take down the Uberbots one way or another for the love of the game!
I've sunk every free hour I have into World of Warcraft: Forever since its release on Wednesday night. As of writing I am Level 19, waiting for an escort quest to come up in Westfall. So far things seem largely the same as in the original MMO, though the little changes and improvements I've seen have firmly planted a smile on my face.
This includes the latest weather system. Like many others I was caught in a snow storm in Dun Morogh this week, a seemingly random environmental transformation that drastically limits view distance and blankets your screen with the cold stuff. It adds a lot, I think, to the fantasy of the game. I'll be playing this all weekend and for the foreseeable future.
Recent findings suggest that I'll let you guess why I'm playing this right now of all times. Ahead of Grand Theft Auto 6's launch, I've made it my unofficial job to internalise the map of Vice City. I'm spending time driving around the strip, familiarising myself with the docklands, going for a few rounds of golf up in Leaf Links, and sniffing out the warehouses on Prawn Island. I'm immensely curious how similar the map is in GTA 6, and can't wait to see what's changed in the interceding 40 years in-universe. It's even better having V-Rock blast Iron Maiden and Twisted Sister at me; over the past few evenings, I've been playing this extra loud so it drowns out the sound of local fireworks for the sake of my poor, terrified dog. I don't think he's a fan of Bruce 'the air raid siren' Dickinson's voice - but it's better than all the apocalyptic banging.
According to recent reports, the cold winter nights are drawing in, which calls for blankets, a warm drink, and a nice peaceful game before bed. I don't have an exact reason for going back to Tears of the Kingdom. Perhaps it's me diving into Ocarina of Time that fuelled my curiosity about returning, but what's surprised me the most is there's still so much I didn't see or do in my first 190 hours with it.
I started again, cleared my save file, and it turns out I've completely forgotten most things about the game - which is by no means a complaint! I'm rather enjoying making the little discoveries that are either brand-newly introduced to me, or ones that make me go 'AH-HA, I remember you' (in the case of Gloom Hands, the reaction was 'NOPE, NOPE, NOPE, NOPE.').
According to recent reports, I've also had another surprise. I play in handheld mode mostly, and ToTK was all looking a bit blurry on the Switch 2's screen. So I got the upgrade pack and suddenly everything became beautiful again - Link was in focus, the individual blades of grass in Hyrule Field were clearly whipping in the wind, and the crispy snow around Rito village almost sparkled. I don't often get upgrade packs for games I already own, but this one was worth it.
I suspect this won't be the last time you see me yapping about Queen's Domain here. I've already enthused about it elsewhere on the site this week, but I've managed to squeeze in a few more hours since then, and it continues to enthrall. Here's a small moment from my most recent go: I'd been fumbling about the Tower of Knowledge for a while at this point, dying slightly more than I'd like to those jabby gargoyle gits and lumbering chimera things, so I thought I'd have a little wander away from the violence and have an explore. That was when I noticed the gap on the bookshelf, wide enough to slot in the mysterious tome - the Ratty Bug Compendium - I'd been wondering about ever since I picked it up elsewhere some five hours earlier.
Moments later a secret passage had opened, leading out to a balcony overlooking the ocean. Treasure! Exciting! But just as I'm about to go back inside, I notice a little outcrop on the exterior of the tower, seemingly reachable with my sword's magic dashing power. So over I go, discovering an otherwise inaccessible route into an inner chamber. There, I find a lever, which I excitedly pull, only to be rewarded with... nothing at all. Until five minutes or so later, when I discover a secret panel has now opened up on the other side of the tower, granting me access to the treats within. In isolation, it's not a remarkable gaming anecdote, but Queen's Domain is just crammed with these little incremental secrets and surprises, full of clever design that makes exploration feel so rewarding. I've already spotted more enigmas waiting to be cracked, and if Queen's Domain keeps distracting me like this, I might never escape its pull.
🔗 Related Articles
📰 #22352. Industry News: Has the couple in Jan van Eyck’s ‘Arnolfini Portrait’ been misidentified? 📰 #17302. Industry News: Where Winds Meet December's calendar is full of new content, including a new region and the mobile launch you've been waiting for 📰 #16635. Industry News: Now That We Know Who Is Playing James Bond, Who Could Be The Next Bond Girl?
General
⚖️ Neutral
🌐 Eurogamer
#11386. Despite promising a heady mix of Vampire Survivors and Warhammer fan-service, Warhammer Survivors is somehow less than the sum of its parts
📅 10 Nov 2026 • ⏱️ 5m • 📚 Deep Dive (978 w)
Despite promising a heady mix of Vampire Survivors and Warhammer fan-service, Warhammer Survivors is somehow less than the sum of its parts
📅 10 Nov 2026 | ⏱️ 5 min read (978 words, 📚 Deep Dive) | Source: Eurogamer
⏱️ ~5 mins left to finish
📖 0% read
💡 Key Takeaways
- You know my favourite thing about Vampire Survivors?
- In a recent development, created by Warhammer 40,000: Boltgun 2 studio Auroch Digital, Warhammer Survivors is - as its name suggests - an officially-licensed attempt to transplant developer Poncle's winning Vampire Survivors' formula to the Warhammer universe.
- But this fusion doesn't really work.
You know my favourite thing about Vampire Survivors? The slow build of strength, the swelling power fantasy, the edging. Developer Poncle has proved itself incredibly adept at goading players into ever more ludicrous setups, demonstrating that with some patience, a canny eye for build-crafting, and some very rudimentary knowledge of your surroundings, even an old man armed with garlic can be an extinction level event for the amassing undead. Warhammer Survivors sadly never reaches those heights.
In a recent development, created by Warhammer 40,000: Boltgun 2 studio Auroch Digital, Warhammer Survivors is - as its name suggests - an officially-licensed attempt to transplant developer Poncle's winning Vampire Survivors' formula to the Warhammer universe. Cue 40+ characters ripped from Warhammer lore getting the action-roguelike treatment, crossbows instead of clock lancets, rocket launchers instead of fire wands, bomb Squids instead of skeletons… you get the idea.
But this fusion doesn't really work. While Vampire Survivors was always a bit of an uphill battle from the start, it still hooked you with a thread that pulled you forward, tempting you with power-ups and other intriguing toys to play with en route. If hour one was a slog, hour five sparked curiosity, and hour 10 was a romp. In Warhammer Survivors, however, hour 10 feels like just as much of a slog as hour one. And even though Warhammer Survivors offers two alternate universes - the grimdark future of 40K and the old-school fantasy of Age of Sigmar, each a full game in its own right - this does little to alleviate the grind.
Recent findings suggest that it's all so slow. Characters move slowly, upgrades come slowly, unlocking the mode that makes things move a bit faster comes slowly. Every inch feels like a mile, and the moreish power creep - tantalisingly propulsive in Vampire Survivors - is out of reach for so long per run here, it's discouraging. That's not to say there isn't any resolution to all the tension. Every now and then, you'll roll the right dice, appease the right gods, make the right moves. Your miniature pixel heroes will overcome the odds, and burn through the writhing mass of Orks, Skaven, Tyranids, Nurgle, or whatever other bastards are trying to get you down today.
The Survivors genre - sometimes known as 'bullet heaven' now - lives and dies on the strength of the over-powered nonsense that emerges as all your weapons and evolutions start to harmonise with each other in brutal synchronicity. Warhammer Survivors seems reluctant to let you get to this level, though. Even 30 hours in (!), some runs will end before they ever really get started - no matter how many skips, rerolls, or other chance-altering upgrades you've committed to your save file.
Industry observers note that and because this is really two games glued into one, you have to do all the requisite grinding and levelling on both sides. With massive maps and impossibly slow character movement (especially on some of the bulkier characters), collecting all the items per location is more of a chore than it is fun. This wouldn't be so bad if these items were just curios, but in most cases they're pretty significant quality-of-life enhancers. Why are you hiding them from me, Auroch!?
Recent findings suggest that it's almost impressive how Warhammer Survivors manages to feel like a step back from Poncle's original in many ways: yes, there's more content, but there appears to be a lack of understanding of why this genre immediately took off and spawned a myriad of imitators. The very worst weapons are the only ones available at the beginning, so unlocking fresh characters and armaments is necessary rather than a fun bonus. Lore is paper thin - in Vampire Survivors, we had a blank canvas and the lack of lore didn't really matter, but Warhammer is steeped in its own mythos, so relegating it to merely set dressing feels remiss. Some of the synergies between items and their evolutions don't really make sense. The maps are awkward and fussy to navigate. The locked requirements to take on stage-end bosses are even more cryptic than in Vampire Survivors. In almost all the ways that matter when it comes to fun, Warhammer Survivors pales in comparison to its forebear. This wouldn't be so egregious if the game wasn't trying to emulate it quite so completely, but it is - and as such, all the actually decent design choices hidden behind layers of frustration are marred.
As a Warhammer and Survivors fan, I've found myself floating back to the game, even if - sometimes - my eyes roll back into my head within minutes of my first run. But it's not a complete disaster: on those occasions where the stars do align, Warhammer Survivors finds its way to a power fantasy worthy of both franchises. You'll grab a Flamer early doors, then pick up the passive Glue to reduce incoming damage. You'll gain the Heavy Flamer, the Boltgun, and the projectile-multiplying Dice Cube, eventually unlocking the Heavy Bolter - slicing through enemies and all but melting the face off that pesky Prophet of Gork.
In a recent development, I just wish there wasn't so much friction in actually getting to that point. I imagine Warhammer Survivors is the sort of game I'll keep on my harddrive (and on multiple devices; it costs a fiver and it's on Game Pass) for a while. If you can endure the teething pains and engage with the wobblier systems, there's the usual Survivors payoff waiting for you as the screen fills with pixelated blood and countless helpless enemies fall to your blades. Maybe the stress of the early game even makes this catharsis even better. So even with its qualms, Warhammer Survivors is still an enjoyable, lo-fi stress reliever to snack on in between other, meatier games.
🔗 Related Articles
📰 #23543. AMD attacks Nvidia's FP64 emulation at SC26, touts native double-precision on Instinct MI430X — claims Ozaki schemes fit less than 10% of HPC workloads and triple memory use and emulated FP64 is a poor fit for many HPC workloads 📰 #21812. Walmart Is Selling Gildan’s Ultra Cotton T-Shirts for Less Than $6 Per Shirt 📰 #21556. Less Than 1% Of Jamaican Beaches Are Open To The Public
AI & Tech
⚖️ Neutral
🌐 9to5google
#11385. Hunter is killing Google Home, Alexa controls for its smart ceiling fans
📅 09 Nov 2026 • ⏱️ 3m • 📚 Deep Dive (515 w)
Hunter is killing Google Home, Alexa controls for its smart ceiling fans
📅 09 Nov 2026 | ⏱️ 3 min read (515 words, 📚 Deep Dive) | Source: 9to5google
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Hunter, a major brand for ceiling fans in the US, is pulling the plug on its Google Home and Amazon Alexa bridge for controlling “HunterSMART” models in just a few weeks.
- Sources indicate that effective January 1, 2027, Hunter will pull support for the cloud-reliant “HunterSMART” connection used for Google Home and Amazon Alexa controls.
- Beginning January 1, 2027, the legacy cloud-to-cloud connections used for app linking between the HunterSMART™ mobile apps and Google Home and/or Amazon Alexa will no longer be supported.
Hunter, a major brand for ceiling fans in the US, is pulling the plug on its Google Home and Amazon Alexa bridge for controlling “HunterSMART” models in just a few weeks.
Sources indicate that effective January 1, 2027, Hunter will pull support for the cloud-reliant “HunterSMART” connection used for Google Home and Amazon Alexa controls. Hunter’s app and the included remote will continue to work, but connections to smart home ecosystems will not.
Beginning January 1, 2027, the legacy cloud-to-cloud connections used for app linking between the HunterSMART™ mobile apps and Google Home and/or Amazon Alexa will no longer be supported.
After this date, Google home and Alexa functionality that relies on this legacy cloud connection will no longer work for HunterSMART fans, including voice commands, scenes, and automations.
In a recent development, this bridge is going away in favor of a Matter connection, with Hunter having been upgrading select models to be Matter-compatible over the past year. But this is only available to “eligible” models, not everyone who was already using Hunter’s existing bridge. A list of compatible models is available on Hunter’s website, with firmware updates rolling out via the HunterSMART app.
Some models, such as the one I reviewed a few years ago, require updated hardware. Besides that, the one I have can’t even be re-connected to Wi-Fi to check for an revision as Hunter’s Android app consistently crashes during the setup process.
Once the fan has been updated, it won’t be available via the existing link and will instead require re-pairing via your smart home app of choice, whether that’s Google Home or another.
…Hunter is transitioning eligible HunterSMART™ products to Matter, an industry standard designed to support broader smart-home compatibility.
If your fan is eligible for Matter-compatibility, you will be able to continue using all smart functionality within the Google Home and/or Alexa ecosystems after completing the applicable Matter migration & setup.
In a recent development, once your HunterSMART fan is Matter-enabled, connecting your fan to Google and Alexa will work differently than it does today. Instead of linking your HunterSMART account to Google Home or Alexa, you will need to setup your Matter-enabled fan directly into these compatible ecosystems using the Matter setup available via the Google Home and/or Alexa apps. Matter-enabled devices do not use the legacy cloud linking service for smart controls that is being discontinued.
How can I migrate my HunterSMART fan to Matter?
Recent findings suggest that depending on your fan model and hardware configuration, a firmware update or updated hardware components may be required for Matter compatibility. Available Matter upgrade options and instructions will vary by product. You can visit our HunterSMART™ Matter resource page for the latest information about Matter compatibility, available upgrade options, and next steps.
Follow Ben: Twitter/X, Threads, Bluesky, and Instagram.
Industry observers note that FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Ben is a Senior Editor for 9to5Google.
Industry observers note that find him on Twitter @NexusBen. Send tips to schoon@9to5g.com or encrypted to benschoon@protonmail.com.
🔗 Related Articles
📰 #23625. Industry News: Google Home brings back sounds for Gemini, and I’m both elated and irritated [Video] 📰 #23617. Google Wallet rolling out digital Google Home keys with supported locks on Android 📰 #23603. Google Home revision fixes Nest ‘Live View’ complications, improves Nest Hub and Gemini for speakers
General
⚖️ Neutral
🌐 Dexerto
#11384. Professor cancels homework and exams during GTA 6 launch week
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (435 w)
Professor cancels homework and exams during GTA 6 launch week
📅 16 Nov 2026 | ⏱️ 2 min read (435 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A professor in Spain cleared his class’s calendar for GTA 6‘s launch week, and the email explaining why promptly went viral.
- The gesture landed while grown-ups were already plotting their own escapes from the hotly anticipated release, with one economist predicting 1.5 million Americans could skip work on November 19.
- Brands piled in, too, as Xbox enlisted DJ Khaled to hand out doctor’s notes for launch day and KFC lined up a fake funeral as an excuse to stay home.
A professor in Spain cleared his class’s calendar for GTA 6‘s launch week, and the email explaining why promptly went viral.
The gesture landed while grown-ups were already plotting their own escapes from the hotly anticipated release, with one economist predicting 1.5 million Americans could skip work on November 19.
Brands piled in, too, as Xbox enlisted DJ Khaled to hand out doctor’s notes for launch day and KFC lined up a fake funeral as an excuse to stay home.
His students, however, had someone in their corner who’d spent the week before quietly clearing their schedule for launch.
In an email written in Spanish and shared on X on November 16, the professor told his students they wouldn’t have any homework, projects or deadlines in his subject during GTA 6’s launch week.
On top of that, he pushed an exam back from the 23rd to the 30th “so you can organize yourselves better and have more free time during those days.”.
En españa, un profesor le suspendio todas las tareas y evaluaciones a los alumnos para que puedan disfrutar el GTA 6Tiene mas ganas de jugar el que todos los pibes jsjs pic.twitter.com/YgvACvursu.
“When GTA V came out in 2013, I was your age,” he explained, recalling how badly he’d wanted to get home to play and how it was all he and his friends talked about.
The surprise came with a catch, though. He apologized for the heavier workload the week before, explaining he had kept the class toiling precisely so they could get ahead on the syllabus, and warned they’d have to buckle down again once launch week was over.
DJ Khaled is giving Xbox players doctor’s notes so they can skip work for GTA 6.
Police can’t wait for GTA 6 to be released so they can “catch a break”.
GTA 6 sick days predicted to cost the US $1 billion.
He also urged them to “enjoy responsibly,” adding that some things in the game weren’t quite appropriate for their age, with GTA 6’s age ratings already flagging sex, drugs and graphic violence.
Recent findings suggest that “I had my moment with GTA V, and I was excited for you to have yours with GTA VI,” he wrote near the end. The email couldn’t be independently verified, though it spread quickly after accounts including content creator ElBuni shared it.
He isn’t the only one clearing the decks with the launch barreling toward November 19, either, after a car organization confirmed back in June that it would pause operations for the day so its entire staff could play.
🔗 Related Articles
📰 #16745. One week from launch, GTA 6's physical map reportedly leaks online thanks to the £350 collector's edition on show in a UK department store 📰 #23556. Here’s how you can save on your GTA VI preorder ahead of launch 📰 #21805. GTA 6 Launches This Week, and Wall Street Has Already Set a $1.5 Billion Bar for Its First Weekend
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11383. AI uncovers hidden Ozempic side effects across 400,000 Reddit posts
📅 13 Sep 2026 • ⏱️ 8m • 📚 Deep Dive (1523 w)
AI uncovers hidden Ozempic side effects across 400,000 Reddit posts
📅 13 Sep 2026 | ⏱️ 8 min read (1523 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~8 mins left to finish
📖 0% read
💡 Key Takeaways
- Artificial intelligence is giving researchers a new way to listen to what patients are saying about popular GLP-1 drugs.
- The study, published recently in Nature Health, examined more than five years of posts from nearly 70,000 Reddit consumers.
- According to recent reports, the findings do not establish that the medications caused these symptoms.
Artificial intelligence is giving researchers a new way to listen to what patients are saying about popular GLP-1 drugs. After analyzing more than 400,000 Reddit posts, a University of Pennsylvania team identified several symptoms reported by people using semaglutide (Ozempic, Wegovy, and Rybelsus) and tirzepatide (Mounjaro and Zepbound) that may not be fully represented in clinical trials or official regulatory information.
The study, published recently in Nature Health, examined more than five years of posts from nearly 70,000 Reddit consumers. Two categories stood out as particularly deserving of further investigation: reproductive symptoms, including changes in menstrual cycles, and problems involving body temperature, such as chills and hot flashes.
According to recent reports, the findings do not establish that the medications caused these symptoms. Instead, researchers say the massive collection of spontaneous patient reports may reveal signals worth examining more closely.
It has been revealed that "Some of the side effects we found, like nausea, are well known, and that highlights that the method is picking up a real signal," says Sharath Chandra Guntuku, Research Associate Professor in Computer and Information Science (CIS) at Penn Engineering and the study's senior author. "The underreported symptoms are leads that came from patients themselves, unprompted, and clinicians could potentially pay attention to them.".
What Patients Report Outside Clinical Trials.
Clinical trials are designed to determine whether treatments work and to identify vital safety problems, but they cannot necessarily capture every symptom that matters to patients once a medication is being used by a much larger population.
"Clinical trials generally identify the most dangerous side effects of drugs," adds Lyle Ungar, Professor in CIS and a co-author on the study. "But they can fail to find what symptoms patients are most concerned about; even though social media is not necessarily representative, a large collection of posts may reflect additional concerns.".
The distinction is important. The study found associations in what people discussed online, not proof that GLP-1 drugs were responsible for those experiences.
"We can't say that GLP-1s are actually causing these symptoms," notes Neil Sehgal, the study's first author and a doctoral student in CIS advised by Guntuku and Ungar. "But nearly 4% of the Reddit users in our sample reported menstrual irregularities, which would be even higher in a female-only sample. We think that's a signal worth investigating.".
Using Social Media as an Early Health Signal.
The idea of mining online conversations for clues about drug safety predates today's AI boom. In 2011, Ungar participated in one of the earliest efforts to use material created by internet owners to identify possible adverse effects from medications.
Social media can capture experiences that patients discuss with one another but may never formally report to a doctor, drug manufacturer, or regulator.
"Online patient communities work a lot like a neighborhood grapevine," indicates Ungar. "People who are living with these medications are swapping notes with each other in real time, sharing experiences that rarely make it into a doctor's office visit or an official report.".
In a recent development, since then, online patient communities have expanded enormously. That has made social media a potentially valuable source for studying how medications affect people in everyday life, although gaining access to platform data has become more difficult.
Traditional clinical research remains essential, the researchers emphasize, but online conversations can provide information far more quickly when millions of people begin using a drug.
According to recent reports, "Clinical trials are the gold standard, but by design, they are slow," notes Guntuku. "This is not a replacement for trials, but it can move much faster, and that speed matters when a drug goes from niche to mainstream almost overnight.".
AI Makes Massive Social Media Analysis Possible.
One of the biggest obstacles has always been scale.
Guntuku describes the approach as "computational social listening," which uses computational methods to identify patterns in large collections of online conversations about health.
Patients, however, rarely describe symptoms using standardized medical terminology. One person might describe feeling unusually cold, another might mention constant chills, while a clinician could categorize those experiences using a specific medical term.
In a recent development, researchers therefore need a way to translate everyday language into standardized categories. One key reference is the Medical Dictionary for Regulatory Activities (MedDRA), which provides terminology widely used to classify medical conditions, symptoms, and adverse events.
Previously, connecting huge numbers of informal social media posts with standardized medical terminology required enormous amounts of work, limiting how much data researchers could realistically analyze.
Large language models such as GPT and Gemini are changing that equation by allowing researchers to process and categorize vast amounts of text more consistently and promptly.
"Large language models have made it possible to do this kind of analysis much faster with a level of standardization that could be difficult to achieve before," says Sehgal.
Unexpected Symptoms Emerge From 400,000 Posts.
The researchers stress that Reddit consumers do not represent the overall population of people taking GLP-1 drugs. Reddit users tend to be younger, are more likely to be male, and are disproportionately located in the United States.
Even with that limitation, the analysis produced a reassuring sign that the approach was detecting genuine patterns. Many of the symptoms discussed by Reddit people closely matched already known effects of semaglutide and tirzepatide.
According to recent reports, about 44% of owners included in the study described at least one side effect. Gastrointestinal problems were the most common, consistent with the nausea and other digestive concerns already associated with these medications.
More intriguing were symptoms that appeared frequently enough to attract the researchers' attention but may not be as well represented in current drug labels or conventional adverse event reports.
Nearly 4% of users who reported side effects described reproductive symptoms. These included changes in menstruation such as bleeding between periods, heavy bleeding, and irregular menstrual cycles.
Users also described changes involving body temperature, including chills, feeling unusually cold, hot flashes, and symptoms resembling a fever.
Fatigue was another notable finding. It was the second most frequently reported complaint in the Reddit data, even though relatively few clinical trials reported fatigue often enough for it to reach established reporting thresholds.
Why Menstrual and Temperature Changes Are Interesting.
Recent findings suggest that one possible reason these reports caught researchers' attention involves the hypothalamus, a small but extremely crucial region of the brain. Among its many jobs, the hypothalamus helps regulate hunger, hormones, reproduction and body temperature.
"These drugs are thought to work by engaging part of the brain called the hypothalamus, which helps regulate a wide variety of hormones," says Jena Shaw Tronieri, Senior Research Investigator at Penn's Center for Weight and Eating Disorders and a co-author of the study. "That doesn't mean the medications are necessarily causing these symptoms, but it could suggest that reports of menstrual changes and body temperature fluctuations are worth studying more systematically.".
Industry observers note that the researchers are not proposing that this biological connection proves GLP-1 drugs are responsible. Instead, it offers another reason to test the patient-reported patterns more carefully through controlled research.
Turning Online Conversations Into Research Leads.
For now, the team hopes the results encourage scientists and clinicians to pay closer attention to symptoms that patients repeatedly discuss online.
"They're clearly on patients' minds, and that's worth paying attention to," indicates Sehgal.
The researchers also want to broaden their analysis beyond Reddit and beyond English-language communities. Doing so could help determine whether the same patterns emerge among different groups of people and on different social media platforms.
"We don't really know yet whether what we're seeing on Reddit reflects the experience of GLP-1 customers globally, or whether it's particular to the kind of person who posts on Reddit in the United States," Ungar says.
In the longer term, rapid AI analysis of online patient conversations could potentially become an early detection system for emerging health concerns involving drugs, supplements and wellness products.
That could be particularly valuable for substances that become popular online faster than conventional research can keep up. Loosely regulated or unregulated products, including injectable peptides, can spread swiftly through communities on Reddit, TikTok and other platforms. Discussions among users may therefore provide some of the earliest indications of unexpected effects.
"The whole point of this kind of approach is that it can move quickly, and that's exactly when it's most valuable," notes Guntuku.
According to recent reports, this study was conducted at the University of Pennsylvania School of Engineering and Applied Science. The authors report no outside funding. Tronieri reports receiving an investigator-initiated grant, on behalf of the University of Pennsylvania, from Novo Nordisk and receiving consulting fees from Currax Pharmaceuticals, LLC. The other authors report no conflicts of interest.
In a recent development, materials provided by University of Pennsylvania School of Engineering and Applied Science. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #19472. Latest Update: Why Do We Feel Colder As We Get Older? Upcoming Study Uncovers a Hidden Mechanism 📰 #23653. Running WireGuard for a Development Team: The Hidden Cost of VPN Maintenance 📰 #23606. What’s !vital #19: CSS Refraction Effects, Scroll State Queries, @custom-media, and More
Hardware & Chips
⚖️ Neutral
🌐 Hugging Face
#11382. Latest Update: NVIDIA brings agents to life with DGX Spark and Reachy Mini
📅 05 Jan 2026 • ⏱️ 7m • 📚 Deep Dive (1419 w)
Latest Update: NVIDIA brings agents to life with DGX Spark and Reachy Mini
📅 05 Jan 2026 | ⏱️ 7 min read (1419 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- It has been revealed that today at CES 2026, NVIDIA unveiled a world of newly introduced open models to enable the future of agents, online and in the real world.
- Recent findings suggest that but what if you could bring your own agent to life, right at your desk?
- In the CES keynote today, Jensen Huang indicated us how we can do exactly that, using the processing power of NVIDIA DGX Spark with Reachy Mini to create your own little office R2D2 you can talk to and collaborate with.
It has been revealed that today at CES 2026, NVIDIA unveiled a world of newly introduced open models to enable the future of agents, online and in the real world. From the recently released NVIDIA Nemotron reasoning LLMs to the new NVIDIA Isaac GR00T N1.6 open reasoning VLA and NVIDIA Cosmos world foundation models, all the building blocks are here today for AI Builders to build their own agents.
Recent findings suggest that but what if you could bring your own agent to life, right at your desk? An AI buddy that can be useful to you and process your data privately?
In the CES keynote today, Jensen Huang indicated us how we can do exactly that, using the processing power of NVIDIA DGX Spark with Reachy Mini to create your own little office R2D2 you can talk to and collaborate with.
This blog post provides a step-by-step guide to replicate this amazing experience at home using a DGX Spark and Reachy Mini.
If you want to start cooking right away, here’s the source code of the demo.
Feel free to adapt the recipe and make it your own - you have many ways to integrate the models into your application:.
Turning an AI agent from a simple chat interface into something you can interact with naturally makes conversations feel more real. When an AI agent can see through a camera, speak out loud, and perform actions, the experience becomes more engaging. That’s what Reachy Mini makes possible.
In a recent development, reachy Mini is designed to be customizable. With access to sensors, actuators, and APIs, you can easily wire it into your existing agent stack, by simulation or real hardware controlled directly from Python.
According to recent reports, this post focuses on composing existing building blocks rather than reinventing them. We combine open models for reasoning and vision, an agent framework for orchestration, and tool handlers for actions. Each component is loosely coupled, making it easy to swap models, change routing logic, or add new behaviors.
Unlike closed personal assistants, this setup stays fully open. You control the models, the prompts, the tools, and the robot’s actions. Reachy Mini simply becomes the physical endpoint of your agent where perception, reasoning, and action come together.
In this example, we use the NVIDIA NeMo Agent Toolkit, a flexible, lightweight, framework-agnostic open source library, to connect all the components of the agent together. It works seamlessly with other agentic frameworks, like LangChain, LangGraph, CrewAI, handling how models interact, routing inputs and outputs between them, and making it easy to experiment with different configurations or add new capabilities without rewriting core logic. The toolkit also provides built-in profiling and optimization features, letting you track token usage efficiency and latency across tools and agents, identify bottlenecks, and automatically tune hyperparameters to maximize accuracy while reducing cost and latency.
First, clone the repository that contains all the code you’ll need to follow along:.
To access your intelligence layer, powered by the NVIDIA Nemotron models, you can either deploy them using NVIDIA NIM or vLLM, or connect to them through remote endpoints available at build.nvidia.com.
Sources indicate that the following instructions assume you are accessing the Nemotron models via endpoints. Create a .env file in the main directory with your API keys. For local deployments, you do not need to specify API keys and can skip this step.
Start by getting a basic LLM chat workflow running through NeMo Agent Toolkit’s API server. NeMo Agent Toolkit supports running workflows via `nat serve` and providing a config file. The config file passed here contains all the necessary setup information for the agent, which includes the models used for chat, image understanding, as well as the router model used by the agent. The NeMo Agent Toolkit UI can connect over HTTP/WebSocket so you can chat with your workflow like a standard chat product. In this implementation, the NeMo Agent Toolkit server is launched on port 8001 (so your bot can call it, and the UI can too):.
Next, verify that you can send a plain text prompt through a separate terminal to ensure everything is setup correctly:.
In a recent development, reviewing the agent configuration, you’ll notice it defines far more capabilities than a simple chat completion. The next steps will walk through those details.
Recent findings suggest that tool calling is an essential part of AI agents. NeMo Agent Toolkit includes a built-in ReAct agent that can reason between tool calls and use multiple tools before answering. We route “action requests” to a ReAct agent that’s allowed to call tools (for example, tools that trigger robot behaviors or fetch current robot state).
Some practical notes to keep in mind:.
Take a look at this portion of the config it defines the tools (like Wikipedia search) and specifies the ReAct agent pattern used to manage them.
The key idea: don’t use one model for everything. Instead, route based on intent:.
In a recent development, you can implement routing a few ways (heuristics, a lightweight classifier, or a dedicated routing service). If you want the “production” version of this idea, the NVIDIA LLM Router developer example is the full reference implementation and includes evaluation and monitoring patterns.
A basic routing policy might work like this:.
These sections of the config define the routing topology and specify the router model.
Recent findings suggest that NOTE: If you want to reduce latency/cost or run offline, you can self-host one of the routed models (typically the “fast text” model) and keep the VLM remote. One common approach is serving via NVIDIA NIM or vLLM and pointing NeMo Agent Toolkit to an OpenAI-compatible endpoint.
Now we go real time. Pipecat is a framework designed for low-latency voice/multimodal agents: it orchestrates audio/video streams, AI services, and transports so you can build natural conversations. In this repo, the bot service is responsible for:.
You will find all the pipecat bot code in the `reachy-personal-assistant/bot` folder.
Reachy Mini exposes a daemon that the rest of your system connects to. The repo runs the daemon in simulation by default (--sim). If you have access to a real Reachy you can remove this flag and the same code will control your robot.
You will need three terminals to run the entire system:.
If you are using the physical hardware, remember to omit the --sim flag from the command.
If the NeMo Agent Toolkit service is not already running from Step 1, start it now in Terminal 3.
Once all the terminals are set up, there are two main windows to keep track of:.
In a recent development, reachy Sim – This window appears automatically when you start the simulator daemon in Terminal 1. This is applicable if you’re running Reachy mini simulation in place of the physical device.
Industry observers note that pipecat Playground – This is the client-side UI where you can connect to the agent, enable microphone and camera inputs, and view live transcripts. In Terminal 2, open the URL exposed by the bot service: http://localhost:7860/. Click “CONNECT” in your browser. It may take a few seconds to initialize, and you’ll be prompted to grant microphone (and optionally camera) access.
Once both windows are up and running:.
At this point, you can start interacting with your agent!
Recent findings suggest that here are a few simple prompts to help you test your personal assistant. You can start with these and then experiment by adding your own to see how the agent responds!
Text-only prompts (routes to the fast text model).
Vision prompts (routes to the VLM).
In a recent development, instead of a "black-box" assistant, this builds a foundation for a private, hackable system where you can control both the intelligence and the hardware. You can inspect, extend, and run it locally, with full visibility into data flow, tool permissions, and how the robot perceives and acts.
Depending on your goals, here are a few directions to explore next:.
Want to try it right away? Deploy the full environment here. One click and you're running.
Sources indicate that the config seems to point to type "nim" (Nvidia's microservices). I'm guessing that you'd recommend an openai compatible inference server such as vllm for local hosting on the DGX Spark? It'd be nice if you appended instructions for running the same models with Triton Server via TensorRT-LLM backend.
AI is developing rapidly, it's crazy!
Can you give more detailed steps for local hosting on the DGX Spark and the corresponding config file ?
General
⚖️ Neutral
🌐 Sitepoint
#11381. What Actually Happens When a Kafka Region Fails?
📅 10 Nov 2026 • ⏱️ 9m • 📚 Deep Dive (1764 w)
What Actually Happens When a Kafka Region Fails?
📅 10 Nov 2026 | ⏱️ 9 min read (1764 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~9 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- Industry observers note that 7 Day Free Trial.
- Recent findings suggest that most Kafka deployments in the industry plan to survive the loss of a single Kafka broker or an availability zone.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Weekly. Free. One click to leave.
Industry observers note that 7 Day Free Trial. Cancel Anytime.
Recent findings suggest that most Kafka deployments in the industry plan to survive the loss of a single Kafka broker or an availability zone. But that's not enough for critical Tier-0 infrastructure where downtime or data loss of even a few seconds could have a massive business impact.
Recent findings suggest that in such scenarios, the failure model should consider not just the loss of a broker or a zone, but the loss of an entire region. The business is expected to operate without interruption even when a whole region goes down, and it should be possible to also roll the cluster safely while operating in that state, to apply any break-glass changes.
Sources indicate that but what actually happens inside Kafka when an entire region goes down? What happens to the replicas, producer writes, and KRaft quorum? And what happens when that region comes back?
Let's walk through these scenarios using a Tier-0 multi-region Kafka architecture.
For a Tier-0 multi-region Kafka cluster, we need three different regions with isolated failure domains and a minimum of two brokers in each region.
Brokers in each region should be configured with rack awareness to indicate their failure domains as follows:.
For Tier-0 workloads, each topic's partitions should be configured to have a replication factor (RF) of 6. Kafka's rack-aware replica assignment will spread the replicas across the three regions. If the automatic replica assignment doesn't allocate two replicas per region, we have to explicitly reassign replicas immediately after topic creation to meet our availability guarantees.
This way, if one region goes down entirely, we still have four replicas surviving and the cluster would still continue to operate.
Recent findings suggest that but just running brokers in multiple regions is not the solution here. In fact, that's the easy part. The hard question is, what guarantee remains when one of those regions disappears, and does it solve the business needs?
Let's say Region A goes down entirely.
The two brokers in that region become unavailable, leaving four surviving replicas across Regions B and C.
For any partitions whose leaders were in Region A, Kafka needs to elect new leaders from the surviving in-sync replicas.
But having four surviving replicas alone does not determine whether Kafka will continue accepting writes.
The next step is to define what is considered a successful write in this Kafka setup. For this, we need two configs:.
min.insync.replicas determines the minimum number of replicas that should be present in the in-sync replica set (ISR) of a partition for Kafka to accept writes when producers use acks=all.
acks=all is a producer-side config that ensures that the producer will get an acknowledgment only when the write has been successfully replicated to the required in-sync replicas.
These two settings work together to satisfy the durability guarantees we want.
Sources indicate that when all three regions are healthy, ISR would include all six replicas. Let's say one region goes down, then the ISR would drop down to four.
Since minISR is three, writes will still continue to work.
According to recent reports, there may be temporary interruptions while Kafka detects the failure, elects latest leaders, and clients reconnect to them. But once the surviving leaders are available, the cluster can continue accepting writes as long as the ISR requirements are met.
The goal isn't availability at any cost, but rather the system should be available as long as the durability guarantees that we designed for can be maintained.
Now let's make the scenario more interesting.
Region A is still down. We have four replicas surviving across Regions B and C.
What if we need to roll the cluster one broker at a time, to apply any break-glass changes?
According to recent reports, during that time, the ISR can go down from four to three. But since minISR is three, writes will still continue to work.
Let's look at how the cluster behaves under different failure scenarios.
Kafka will stop accepting writes only when the surviving ISR drops below three.
This is an notable distinction for Tier-0 workloads.
It's not sufficient to design a cluster that survives a region failure. We also need to consider whether the cluster can continue operating safely while already in that degraded state.
So far, we focused on the data plane. Now switching gears, the KRaft controllers have a completely different availability model.
They form the metadata quorum, and a majority is needed to continue operation.
For our setup, five controllers could be distributed as 2 + 2 + 1 across the three regions, requiring a majority of three to maintain quorum.
If either of the regions containing two controllers goes down, three controllers remain. If the region containing one controller goes down, four remain.
So, the controller quorum survives the loss of any one region.
But, unlike brokers, we cannot necessarily roll the controllers at that point because taking one controller down could cause the quorum to drop below three.
Sources indicate that with a static quorum, one way to solve this is to use more controllers, and a 3 + 3 + 3 distribution would provide this. Losing one region would leave six controllers with room to still roll the controllers, as we only need five to maintain quorum.
According to recent reports, on the flip side, an increase in quorum size also increases the coordination overhead. The official Kafka documentation typically recommends three or five controllers, which tolerate one or two concurrent failures respectively.
Alternatively, with dynamic KRaft quorum (KIP-853), introduced in Kafka 3.9, we can add or remove controllers from the voting quorum without restarting the cluster.
For example, with our 2 + 2 + 1 setup, if a region containing two controllers goes down, the remaining three controllers can still maintain quorum. We can then remove the failed controllers from the voting membership, one at a time, reducing the quorum size to three. This allows us to roll one of the surviving controllers while still maintaining the new majority of two.
Industry observers note that however, dynamic quorum reconfiguration is not automatic. The surviving controllers must be able to maintain quorum and successfully commit the membership changes before we can proceed with the controller restart.
You need to consider whether you want the same availability guarantee for the controllers as that of the data plane, and whether dynamic quorum reconfiguration during a regional outage is acceptable for your Tier-0 workloads.
So far, we assumed that a region either works or goes down completely.
But the WAN itself becomes a failure mode.
In this setup, a partly working WAN between two regions can be more dangerous than a link that's completely down.
Increased latency, packet loss, or intermittent connectivity issues between regions can cause replication to lag, ultimately resulting in replicas falling out of ISR.
The three regions might be independently healthy, but if the connectivity between them is not, then the availability of the cluster might be impacted.
Going back to the CAP theorem, to tolerate a network partition, we must choose between consistency and availability.
So, if a partition's ISR falls below the configured min.insync.replicas of three due to a network partition, Kafka stops accepting writes with acks=all rather than weakening those guarantees.
Similarly, if the KRaft controller quorum is lost, then no metadata changes, like leader elections, can happen in the cluster, even though existing data-plane traffic may continue for some time.
The availability guarantees we discussed also come with their own costs.
The first cost is client latency. With cross-region replication and acks=all, the network latency between these regions directly affects producer latency. Consumers can also pay the WAN latency cost when consuming from partition leaders located in a different region.
In a recent development, the second cost is replication overhead. With RF=6, there is additional storage, network traffic, and replication-related coordination cost in the brokers compared to a smaller number of replicas.
So, in an architecture like this, monitoring the health of the network paths between these regions is as critical as monitoring the Kafka brokers and controllers.
Metrics like round-trip latency (RTT) between regions, packet loss, TCP retransmissions, connection errors/timeouts, and network throughput/bandwidth utilization are a good start.
When one region goes down, all the partition leaders in that region would move to the two other surviving regions.
This implies that those two regions would have to handle more producer and consumer traffic, network throughput, and disk I/O.
Even if the cluster is designed to satisfy its ISR and controller quorum requirements, if it's not sized to handle these failures when one region goes down, the surviving regions would be overloaded, resulting in higher latencies, timeouts, and operational instability.
So, for Tier-0 infrastructure, capacity planning should always be done for failure states and not stop at normal operations.
Now let's say Region A comes back online.
The brokers in the recovered region might have to catch up on a significant amount of data before they become fully in sync again.
This can result in a sudden burst of cross-region network traffic and disk I/O across all regions.
Region recovery needs to be controlled so that it doesn't overwhelm the healthy part of the cluster.
This can be achieved by throttling the replica catch-up, with the trade-off of longer recovery time to minimize the impact on live production traffic.
Replication throttling needs a deeper discussion of its own, so we won't go into details here.
According to recent reports, the crucial point is that bringing a failed region back online is not simply a matter of restarting its brokers. We need to make sure that the recovery process itself doesn't impact the business.
Before putting a Tier-0 multi-region Kafka cluster into production, validate these scenarios:.
In a recent development, there is no shortage of ways to deploy Kafka across multiple regions. The challenge here is to pick the right architecture that addresses all our durability guarantees.
For Tier-0 workloads, this means designing the architecture around failures first.
Sources indicate that what happens when a region goes down? Can we still roll the cluster? What continues to work, and at what point do we deliberately stop accepting writes?
Lastly, can we safely bring back the region that was down without impacting the business?
That is ultimately the difference between simply running Kafka across multiple regions versus actually supporting a mission-critical Tier-0 workload.
Sources indicate that 7 Day Free Trial. Cancel Anytime.
🔗 Related Articles
📰 #19476. Breaking: Alzheimer’s Breakthrough Reveals What Happens When the Brain’s Cleaning System Fails 📰 #23542. Breaking: This Quest 3 golf club actually improved my scores, but it comes at a cost 📰 #23450. Tech Report: DeepSeek-V4: a million-token context that agents can actually use
General
⚖️ Neutral
🌐 9to5google
#11380. Googlebook apps built by Googlers add macOS-like status bar shortcuts, keyboard commands
📅 09 Nov 2026 • ⏱️ 3m • 📚 Deep Dive (534 w)
Googlebook apps built by Googlers add macOS-like status bar shortcuts, keyboard commands
📅 09 Nov 2026 | ⏱️ 3 min read (534 words, 📚 Deep Dive) | Source: 9to5google
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Googlebooks are a bit starved of desktop-class features at launch, but one of Google’s pitches around this platform is how apps can be built for it, and the manufacturer’s own employees are showing off what that looks like with some clever apps that just so happen to add features that feel a lot like they’re replicating macOS staples.
- In a Reddit thread, three Googlebook apps built by Googlers through Antigravity are shown off, and they’re pretty cool, regardless of how you might feel about the platform itself.
- It has been revealed that “BentoBox” is a utility that gives you control over the status bar on Googlebook, enabling you to fill the status bar with shortcuts, mini-apps, and more.
Googlebooks are a bit starved of desktop-class features at launch, but one of Google’s pitches around this platform is how apps can be built for it, and the manufacturer’s own employees are showing off what that looks like with some clever apps that just so happen to add features that feel a lot like they’re replicating macOS staples.
In a Reddit thread, three Googlebook apps built by Googlers through Antigravity are shown off, and they’re pretty cool, regardless of how you might feel about the platform itself.
It has been revealed that “BentoBox” is a utility that gives you control over the status bar on Googlebook, enabling you to fill the status bar with shortcuts, mini-apps, and more. It’s full of glancable information such as weather conditions, battery charging speeds, and more, but also includes useful tools such as being able to access a clipboard history, set a timer, and more. The app requires permissions including accessibility overlays, but it works like a charm.
Recent findings suggest that I had no idea the status bar on Googlebook could even be used like this, and it really makes that space a lot more useful. Of course, you have to draw a comparison here to macOS, which also uses this space for app shortcuts and tools, though BentoBox offers a different type of customization.
BentoBox is available for download via Google Play for free.
According to recent reports, the other Mac-like app here is “Booklight,” a launcher that’s basically Apple’s Spotlight, just for Googlebook. It has a transparent design and lets you search “apps, settings, and the web.”.
Technically, Googlebook already can do this in its built-in search bar (in the app drawer), but Booklight has more customization and functionality, including being able to write out shorthand commands all in one sentence with the app then completing the command in the appropriate apps, as well as having a clearer UI for experiences such as typing in quick math equations. It’s also good at finding symbols (so you don’t have to remember the U+ codes that carried over from ChromeOS). Not one I found myself wanting to use, but the potential is there.
Booklight is also on the Play Store.
Both BentoBox and Booklight were developed by Alexander Kuscher, VP over Laptops & Tablets at Google.
The other app highlighted in Google’s thread was Wayfinder, a file manager app described as a “desktop-grade file manager.” The substantial bonus here is network file access for NAS boxes and other uses, but the app also just has a more advanced UX compared to Googlebook’s built-in Files app.
Googlebook’s app gap is a real problem at launch, but these apps do show there’s a lot of potential in the platform, it’s just a matter of getting developers on board – which itself will require Google and its partners to actually sell some of these laptops… classic chicken-and-egg situation.
Follow Ben: Twitter/X, Threads, Bluesky, and Instagram.
FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Ben is a Senior Editor for 9to5Google.
In a recent development, find him on Twitter @NexusBen. Send tips to schoon@9to5g.com or encrypted to benschoon@protonmail.com.

Gadgets
⚖️ Neutral
🌐 9to5google
#11379. Fitbit Sense & Versa losing 3rd-party watch faces this month, existing downloads remain
📅 09 Nov 2026 • ⏱️ 1m • 📖 Standard (220 w)
Fitbit Sense & Versa losing 3rd-party watch faces this month, existing downloads remain
📅 09 Nov 2026 | ⏱️ 1 min read (220 words, 📖 Standard) | Source: 9to5google
⏱️ ~1 mins left to finish
📖 0% read
💡 Key Takeaways
- Google declared today that Fitbit Sense and Versa smartwatches will soon lose the ability to “install or update third-party apps and clocks.”.
- This change to the Fitbit App Gallery applies to the Versa, Versa 2, Versa 3, Versa 4, Sense, and Sense 2.
- Existing “third-party apps or clock faces installed on your Fitbit device” will remain available, but you can no longer download upcoming ones (or revision them) starting November 28.
Google declared today that Fitbit Sense and Versa smartwatches will soon lose the ability to “install or update third-party apps and clocks.”.
This change to the Fitbit App Gallery applies to the Versa, Versa 2, Versa 3, Versa 4, Sense, and Sense 2.
Existing “third-party apps or clock faces installed on your Fitbit device” will remain available, but you can no longer download upcoming ones (or revision them) starting November 28. As such, “if you choose to delete an app or clock face, or factory reset your device, you will no longer be able to re-install it.”.
Instead, the Fitbit App Gallery will “exclusively feature apps and clock faces created by Fitbit and Google.”.
The November 28 deadline also applies to third-party developers. Google will “no longer support uploading fresh apps and clock faces or updating existing ones.”.
According to recent reports, google winding down Fitbit OS for smartwatches is not particularly surprising as the company has been all-in on Wear OS and the Pixel Watch. That mentioned, the Sense 2 and Versa 4 should probably no longer be on sale.
Sources indicate that FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
According to recent reports, editor-in-chief. Interested in the minutiae of Google and Alphabet. Tips/talk: abner@9to5g.com.

General
⚖️ Neutral
🌐 Dexerto
#11378. Breaking: Discord teams up with Rockstar for Vice City theme to celebrate GTA 6 launch
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (342 w)
Breaking: Discord teams up with Rockstar for Vice City theme to celebrate GTA 6 launch
📅 16 Nov 2026 | ⏱️ 2 min read (342 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Discord has officially teamed up with Rockstar Games to introduce a limited-time GTA 6 Vice City theme, allowing consumers to customize the app’s appearance with colors and designs inspired by the upcoming game.
- The collaboration arrives just days before Grand Theft Auto 6’s scheduled November 19 release, which will take players back to Vice City.
- Discord declared the new customization options in a post on X, writing: “Bring Vice City to your Discord.”.
Discord has officially teamed up with Rockstar Games to introduce a limited-time GTA 6 Vice City theme, allowing consumers to customize the app’s appearance with colors and designs inspired by the upcoming game.
The collaboration arrives just days before Grand Theft Auto 6’s scheduled November 19 release, which will take players back to Vice City. With anticipation building around Rockstar’s next installment, Discord consumers can now bring the game’s neon-inspired aesthetic to their accounts.
Discord declared the new customization options in a post on X, writing: “Bring Vice City to your Discord.”.
“Starting today, you can apply the Vice City color theme, app icon, and Display Name Style,” the firm explained.
Bring Vice City to your Discord.Starting today, you can apply the Vice City color theme, app icon, and Display Name Style. The Vice City theme is available to everyone through December 13 and to Nitro members (excluding Nitro Basic) through February 20. pic.twitter.com/QKsT1m8Ikq.
The theme is available on both desktop and mobile, allowing users to customize Discord with colors inspired by Vice City’s signature neon aesthetic.
From November 16 through November 22, users can activate the theme directly through Discord’s Quest Home. After that, the color theme and app icon can be found under User Settings > Appearance on desktop or Settings > App Settings on mobile.
The Display Name Style is available separately through Discord’s profile customization settings, allowing users to change how their name appears alongside the latest app design.
Rockstar made a real-life GTA 6 Vice City supercar you can actually buy for $1M.
Kick and Twitch are giving away thousands of GTA 6 codes to viewers before launch.
Discord announces massive desktop redesign with tons of new features.
The official promotion also includes a Grand Theft Auto VI: Pre-Load Video Quest, giving eligible customers an opportunity to earn Discord Orbs by completing the activity before November 18.
Discord is also directing fans to Rockstar Games’ official Discord server, where they can follow updates and connect with other players ahead of GTA 6’s launch.
🔗 Related Articles
📰 #11355. Vice City was the GTA that established Rockstar's killer formula - and 24 years on, it's still one of the best games ever made 📰 #23674. Subway reveals Vice City sub for GTA 6, but there’s only one way to get it 📰 #17036. NBA 2K27 Brings A Slice Of GTA 6's Vice City To Switch 2 This Month
General
⚠️ Warning
🌐 Eurogamer
#11377. World of Warcraft: Forever's magical opening week reminds us all about the power of the MMO, and the threat it poses to your free time
📅 11 Nov 2026 • ⏱️ 6m • 📚 Deep Dive (1129 w)
World of Warcraft: Forever's magical opening week reminds us all about the power of the MMO, and the threat it poses to your free time
📅 11 Nov 2026 | ⏱️ 6 min read (1129 words, 📚 Deep Dive) | Source: Eurogamer
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- In a recent development, world of Warcraft: Forever is a time vampire.
- The original World of Warcraft is so beloved, so influential, that I wasn't convinced Forever could build upon it without cheapening the overall experience; without creating glaring clashes between its newly introduced additions and legacy elements that, in some instances, are now over two decades old.
- Sources indicate that perhaps it's best to start with WoW: Forever's most obvious changes: its upcoming lighting and weather effects.
In a recent development, world of Warcraft: Forever is a time vampire. Since its release last Wednesday, I have spent 78 hours in Azeroth. Some of that I was AFK, sure. But for many of those hours, I was lost, happily, in the rolling hills and vast planes of Blizzard's MMO - now enhanced, beautified, and given a newly introduced social energy that makes the old feel wonderfully new.
The original World of Warcraft is so beloved, so influential, that I wasn't convinced Forever could build upon it without cheapening the overall experience; without creating glaring clashes between its newly introduced additions and legacy elements that, in some instances, are now over two decades old. And while there's still plenty I haven't seen after 78 hours and 35 levels, I can speak to one truth: WoW Forever is stunning work.
Sources indicate that perhaps it's best to start with WoW: Forever's most obvious changes: its upcoming lighting and weather effects. People love to speak about getting lost in MMOs, being consumed by their digital worlds, but as much as I've enjoyed World of Warcraft in the past, its ageing graphics tech never managed to ensnare me that way. Forever's new visual elements, though, have gone a long way toward pulling me in.
It has been revealed that as I look out to sea, waves roll across the ocean. Inland, water flows fast along the rivers of Stranglethorn Vale. These are largely cosmetic additions, sure, but they make Azeroth feel so much more real. Dun Morogh's snowstorms - likely the first exposure many players will have to Forever's new weather effects - transform a peaceful, picturesque landscape into something hostile at a moment's notice. It's the same for Tanris; its vast desert now blighted with sandstorms that bring raging life to an otherwise fairly barren zone.
World of Warcraft; Forever's enhancements go beyond visual, of course. Before launch, Blizzard described Forever as an opportunity to address imbalances, and to show a bit of love to underserved playstyles and classes. That's why I decided I'd play as a druid and work toward creating a balance caster: a ranged DPS druid far slower to level than a feral one, and far less useful as a magic DPS compared to a mage. In other words, an unoptimal choice for the truly silly.
It has been revealed that I actually levelled a balance druid to max in Classic World of Warcraft some years back and it was an arduous process. In Forever, though, adjustments made to the spells and talents have made it much less frustrating so far. You do more damage, for starters, and alterations to the talent tree and unlockable skills mean you don't run into the sort of mana problems that crippled balance druids previously. From what I've seen, all the ugly duckling class specialisations - like Retribution Paladins and Enhancement Shamans - have received similar changes.
My interest had been similarly piqued before launch by the talk of WoW: Forever's fresh dungeons. I still need more time to understand how these additions affect the wider leveling process, but already I can see they've been crafted with care, fitting nicely in the gaps between the original dungeons on a progression level.
According to recent reports, hall of Thanes is a Ragefire Chasm equivalent for Alliance players, serving as a solid introduction to dungeons for newcomers before they head off to The Deadmines and beyond. Here, you delve into the bowels of Ironforge, navigating tombs and tunnels in search of treasure and tackling foes beneath the seat of dwarvish power. It's simple and clean like all early game Classic dungeons are, made with such faithfulness to the original vision that I could be convinced it was always present.
It has been revealed that it's also a lovely narrative introduction to one of the world's many antagonists, the Dark Iron Dwarves. In the original World of Warcraft, players would first encounter them across a scattering of quests before being thrust towards Blackrock Mountain. Now, though, they show up early and immediately plant intrigue. What's the deal with these drilling machines? What about the fire elementals they're with?
Recent findings suggest that forever's latest dungeons also introduce some well-crafted quests. Anyone who's played Classic WoW can recount the frustration of dungeons that, thanks to some awkward design, often require two separate completions to finish off. Blackfathom Deeps is a prime example; there are never enough twilight pendants to go around, forcing players to go back in for a second run if they want to tick it off. As such, many, myself included, don't bother. World of Warcraft: Forever, though - with some exceptions - appears to favour a one-and-done approach to dungeons. In the new Excavation Site: Wetlands, for instance, there are just enough raptors hidden in tall grass for everyone to complete their hides in one go. A little thing, but meaningful.
But beyond all this, perhaps the most wonderful thing about World of Warcraft: Forever is how full it feels. It's lively, bustling with action and excitement. Some of this is just that new MMO energy, but Blizzard's new mega server approach, which vastly increases the number of players you'll see doing quests compared to a regular server, is undoubtedly a significant factor too.
Every major city is packed with people having their own adventure, each quest zone is littered with heroes doing their bit to save the world. And this opens the door to social interactions, the beating heart of any MMO. The sight of dozens of players jumping off a zeppelin or flooding onto an elevator in unison is a joy, and grouping with strangers for an escort quest or an elite quest is a curative for digital hermits.
According to recent reports, at one point, I find myself drawn into a conversation with a mage during a quest for troll ears. The mobs were hotly contested, and Horde players were quick to snatch tags. The few minutes I spent there, talking about what's going on and how we're finding the game were lovely, and World of Warcraft: Forever's set-up encourages so much more of this kind of thing.
Sources indicate that so, while I probably have plenty more sleepless nights left to go before I max out my druid, World of Warcraft: Forever has made a strong early impression. It's taken the original game and expanded on it in genuinely meaningful ways, leaving the things that worked untouched while enriching the elements needed some love. It's a wonderful point to jump into the game if you're a new player, then, and a refreshed classic full of twists for the returning veteran. Whatever the coming months and years may bring, this opening week has been magical.
🔗 Related Articles
📰 #16998. Dungeons in World of Warcraft: Forever get a huge XP buff, but power-levellers shouldn't celebrate just yet 📰 #16859. World of Warcraft: Forever secret hunters have found the MMO's first hidden treasure 📰 #16784. Latest Update: World of Warcraft: Forever players in Australia and Latest Zealand are struggling to get sunlight, and not for the usual MMO reasons
General
⚖️ Neutral
🌐 Sciencedaily
#11376. The shape behind the Einstein problem just revealed strange new physics
📅 15 Sep 2026 • ⏱️ 3m • 📚 Deep Dive (650 w)
The shape behind the Einstein problem just revealed strange new physics
📅 15 Sep 2026 | ⏱️ 3 min read (650 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- A mathematical shape that drew global attention for solving a decades-old puzzle is now revealing an unexpected connection to physics.
- In a study published in Nature Communications, researchers from the Institute of Industrial Science, The University of Tokyo, and collaborating institutions built optical structures inspired by the "Smith hat." This unusual shape is known for solving the so-called Einstein problem in mathematics.
- The Einstein problem asks whether a single tile shape, known as a "monotile," can cover an entire surface without creating a repeating pattern.
A mathematical shape that drew global attention for solving a decades-old puzzle is now revealing an unexpected connection to physics. Researchers have found that structures based on the shape can make light form unusual chiral patterns, pointing to upcoming ways of exploring how geometry can influence optical behavior.
In a study published in Nature Communications, researchers from the Institute of Industrial Science, The University of Tokyo, and collaborating institutions built optical structures inspired by the "Smith hat." This unusual shape is known for solving the so-called Einstein problem in mathematics. When the team illuminated the structures with laser light, they observed diffraction effects unlike those seen in conventional quasicrystals.
The Shape That Solved the Einstein Problem.
The Einstein problem asks whether a single tile shape, known as a "monotile," can cover an entire surface without creating a repeating pattern.
In a recent development, familiar tilings such as checkerboards and honeycombs repeat in a regular way. An aperiodic monotile, by contrast, can fill a surface without ever settling into a repeating arrangement.
In 2023, researchers discovered the first such monotile, the Smith hat. The finding attracted widespread attention because it provided a long-sought solution to the mathematical problem.
"What is especially fascinating about the hat tile is that, although the resulting pattern appears irregular at first glance, it is actually constructed from the honeycomb lattice," says lead author Yuto Moritake. "We wanted to see whether this unique shape could also produce any unexpected physical phenomena.".
Turning a Mathematical Pattern Into an Optical Structure.
To test that possibility, the researchers created nanoscale versions of the pattern on silicon nitride films using electron beam lithography.
Industry observers note that when laser light was directed at the structures, the resulting diffraction patterns formed distinctive pinwheel-like shapes. These patterns directly revealed the chiral character of the aperiodic structure.
According to recent reports, chirality refers to a form of handedness in which a structure and its mirror image cannot be perfectly matched. In this case, the unusual arrangement of the monotile pattern caused the light itself to display a chiral response.
"We found that the diffraction patterns themselves become chiral because the structure lacks mirror symmetry," explains senior author Masaya Notomi. "This kind of optical response is fundamentally different from that observed in conventional quasicrystalline materials.".
Light Responds to Direction and Polarization.
The researchers also found that the diffraction pattern changed depending on both the direction and polarization of the incoming light.
In a recent development, when the physical structures were mirrored, their optical behavior reversed as well. This showed that the response of the light was directly tied to the symmetry of the underlying pattern, revealing a new type of symmetry-controlled optical behavior.
"These results open a latest direction of research on the fusion of quasiperiodic order and chirality," remarks Moritake. "Monotile patterns provide a platform for exploring optical phenomena that emerge from the interplay of symmetry, chirality, and aperiodicity.".
From Abstract Mathematics to New Optical Physics.
The researchers say structures inspired by monotiles could eventually contribute to technologies designed to manipulate light, control polarization, and support advanced optical devices.
It has been revealed that more broadly, the findings show how a discovery that began as an abstract mathematical puzzle can lead to unexpected physical effects. The Smith hat was first celebrated for solving a question about how shapes can cover a surface. Now, its unusual geometry may also help researchers uncover upcoming ways to control and study light.
Industry observers note that materials provided by Institute of Industrial Science, The University of Tokyo. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Newly introduced Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.

AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11375. Introducing Falcon-H1-Arabic: Pushing the Boundaries of Arabic Language AI with Hybrid Architecture
📅 05 Jan 2026 • ⏱️ 8m • 📚 Deep Dive (1643 w)
Introducing Falcon-H1-Arabic: Pushing the Boundaries of Arabic Language AI with Hybrid Architecture
📅 05 Jan 2026 | ⏱️ 8 min read (1643 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~8 mins left to finish
📖 0% read
💡 Key Takeaways
- Discover more in our official blogpost, featuring an interactive experience.
- Industry observers note that the journey of building world-class Arabic language models has been one of continuous learning and iteration.
- It has been revealed that when we rolled out Falcon-Arabic a few months ago, the response from the community was both humbling and enlightening.
Discover more in our official blogpost, featuring an interactive experience.
Industry observers note that the journey of building world-class Arabic language models has been one of continuous learning and iteration. Today, we're excited to announce Falcon-H1-Arabic, our most advanced Arabic language model family to date, representing a significant leap forward in both architecture and capabilities. This release embodies months of research, community feedback, and technical innovation, culminating in three powerful models that set newly introduced standards for Arabic natural language processing.
It has been revealed that when we rolled out Falcon-Arabic a few months ago, the response from the community was both humbling and enlightening. Developers, researchers and students across the Arab world used the model for real use cases, pushing them to its limits and providing invaluable feedback. We learned where the model excelled and, more importantly, where it struggled. Long-context understanding, dialectal variations, mathematical reasoning, and domain-specific knowledge emerged as key areas requiring deeper attention.
We didn't just want to make incremental improvements, we wanted to fundamentally rethink our approach. The result is Falcon-H1-Arabic, a model family that addresses every piece of feedback we received while introducing architectural innovations that were previously unexplored in Arabic language modeling.
Falcon-H1-Arabic 3B, 7B, 34B models outperforming all SOTA models of similar sizes and sometimes bigger.
Falcon-H1-Arabic is built on the Falcon-H1 hybrid architecture, which integrates State Space Models (Mamba) and Transformer attention within every block. Both components run in parallel and their representations are fused before the block’s output projection. This design provides the linear-time scalability of Mamba for extremely long sequences while preserving the precise long-range modeling capabilities of attention. For Arabic, with its rich morphology and flexible sentence structures, this approach significantly improves coherence and reasoning across extended text. We've deployed this architecture across three scales (3B, 7B, 34B parameters), each balancing capacity, efficiency, and deployability for different use cases from edge devices to enterprise applications.
According to recent reports, falcon-H1 architecture. Attention and SSM run in parallel within each block; their outputs are concatenated before the block’s output projection. The number of SSM/Attention heads depends on the model size. More details on the Falcon-H1 technical report.
We've dramatically increased context capabilities from Falcon-Arabic's 32K limit to 128K tokens for the 3B model and 256K tokens for both the 7B and 34B models. At 256K tokens (~200,000 words), these models can process several novels or hundreds of pages of technical documentation enabling applications in legal analysis, medical records, academic research, and extended conversations that were previously impractical. Our post-training specifically addresses "lost in the middle" challenges to ensure models effectively utilize their full context range, not just accept long inputs.
According to recent reports, we rebuilt our pre-training data pipeline from the ground up to better reflect the complexity of Arabic. This began with a multi-stage quality filtering process tailored to Arabic orthography, morphology, diacritics, and syntactic patterns. Instead of heuristic filtering, we used deep linguistic analysis to isolate coherent, well-structured text and remove noise commonly found in open-web corpora. The result is a significantly cleaner, more stylistically consistent Arabic dataset.
Dialect coverage was another key priority. Arabic is not monolithic; Modern Standard Arabic coexists with dialects such as Egyptian, Levantine, Gulf, and Maghrebi, each with distinct vocabularies and grammatical constructions. We expanded dialectal sources substantially so the models would understand and generate the full spectrum of real-world Arabic rather than leaning disproportionately toward formal MSA. To maintain global reasoning and domain diversity, we also preserved the multilingual capabilities of Falcon-H1 by training the Arabic models on an almost equal mix of Arabic, English, and multilingual content totalling around 300 Billion Tokens. This ensures strong performance in code, STEM, and cross-lingual reasoning. The following figure illustrates the distribution of the pre-training data across languages and categories. All values are expressed in billions of tokens.
Sources indicate that after pre-training, Falcon-H1-Arabic undergoes a focused post-training pipeline consisting of supervised fine-tuning (SFT) followed by direct preference optimization (DPO). During SFT, we expose the models to high-quality Arabic instructions, curated long-context examples, and structured reasoning tasks that teach them to follow directives, maintain coherence over extended sequences, and ground their responses in relevant information. This stage is crucial for ensuring that the models can actually use their large context windows which does not emerge automatically from architecture alone.
According to recent reports, we follow SFT with a targeted DPO phase to refine alignment, conversational quality, and preference consistency. DPO helps the models balance long-context reasoning with general linguistic competence, improving helpfulness and reducing common failure modes such as drifting, overuse of context, or neglecting earlier information. Throughout both stages, we carefully monitor for catastrophic forgetting and maintain a controlled curriculum so gains in long-context behavior do not come at the expense of core reasoning or factual accuracy. The result is a family of models that handles extended documents and dialogue with ease while preserving strong performance on everyday language tasks.
It has been revealed that beyond benchmark-oriented optimization, our post-training process deliberately strengthens areas that traditional evaluations do not fully capture, including conversational faithfulness, rhetorical organization, structured follow-ups, and discourse coherence. These enhancements significantly boost the model’s practical usefulness, making Falcon-H1-Arabic more dependable in real multi-turn dialogue, instruction execution, and long-context conversational flows.
According to recent reports, numbers tell an vital part of the story. On the Open Arabic LLM Leaderboard (OALL), a comprehensive benchmark evaluating Arabic language understanding across diverse tasks, Falcon-H1-Arabic achieves state-of-the-art results at every scale we tested. Note that our scores may vary slightly from those reported on the leaderboard, as we used vLLM as the backend instead of the leaderboard’s Accelerate-based implementation. These differences are typically under one point while offering significantly faster runtime.
Beyond OALL, we also report results on the 3LM benchmark for STEM-related tasks on both synthetic and native splits; Arabculture for Arabic culture assessment; and AraDice for Arabic dialect coverage across Levantine, and Egyptian varieties as well as Arabic culture across 6 countries. The reported AraDice score is the average of all the 3 scores.
In a recent development, starting with the 3B model, the performance is exceptional. It reaches approximately 62% on OALL, outperforming all small-scale models, including Gemma-4B, Qwen3-4B, and Phi-4-mini by roughly ten points. On 3LM, the main Arabic STEM benchmark, it scores around 82% on the native split and 73% on the synthetic split. It also achieves about 62% on the ArabCulture benchmark and around 50% across AraDice dialect evaluation (Egyptian, Gulf, and Levantine). This makes Falcon-H1-Arabic-3B a high-quality, highly efficient model suitable for edge deployments, real-time applications, and agentic systems where latency and cost matter.
Sources indicate that the 7B model continues this upward trajectory. With a score of 71.7% on OALL, it surpasses all models in the ~10B class, including Fanar-9B, Allam-7B*, and Qwen3-8B. On 3LM, it reaches about 92% on the native split and 85% on the synthetic one. AraDice scores rise into the mid-50s across all dialects, and ArabCulture results approach 80%. This model strikes an ideal balance between capability and deployability, making it the most practical choice for general-purpose Arabic NLP in production environments.
The 34B model represents our flagship system and establishes a upcoming state of the art for Arabic language modeling. It reaches approximately 75% on OALL, outperforming not only models of similar size but even much larger systems such as Llama-3.3-70B and AceGPT2-32B. Its 3LM scores reach about 96% on the native split and 94% on the synthetic one. On ArabCulture it scores close to 80%, and on AraDice it reaches around 53 across dialects. The fact that a 34B hybrid model surpasses the performance of 70B-scale transformers demonstrates the effectiveness of the Falcon-H1 architecture, the quality of the data, and the strength of the post-training pipeline.
These benchmark results validate our approach but also highlight an important reality: the frontier of Arabic language modeling is advancing rapidly. Each percentage point on these benchmarks represents countless hours of engineering effort, careful dataset curation, and architectural refinement. The margins by which Falcon-H1-Arabic leads aren't just statistical artifacts, they translate to meaningfully better user experiences in real-world applications.
Each model in the Falcon-H1-Arabic family is suited to different deployment scenarios. The 3B model is optimized for speed, cost-efficiency, and high-throughput systems, making it ideal for agentic workflows, on-device applications, low-latency chat, and environments with strict resource constraints. The 7B model serves as the general-purpose workhorse for most production applications, powering document understanding systems, chatbots, summarization pipelines, and content generation tools. The 34B model is designed for high-stakes domains where accuracy and long-range reasoning matter most, including legal analysis, medical summarization, academic research, and large-scale enterprise automation. Its extended context window makes it uniquely capable of analyzing hundreds of pages of text in a single pass while maintaining precise coherence.
Like all language models, Falcon-H1-Arabic may reflect biases from training data and can produce hallucinated information. Model outputs should not be used as sole authorities for medical, legal, or financial decisions without professional verification. Long-context performance may degrade at extreme ranges. We recommend task-specific evaluation and appropriate guardrails before deployment in production or sensitive applications.
According to recent reports, this work stands on the shoulders of many. We extend our gratitude to the Arabic NLP research community, whose open sharing of benchmarks, datasets, and methodologies enables progress across the field. Special thanks to our colleagues at TII: Ilyas Chahed, Younes Belkada, Dhia Eddine Rhaiem, Puneesh Khanna, Jingwei Zuo, Mikhail Lubinets, Slim Frikha, Maksim Velikanov, Kacper Piskorski, and Suhail Mohmad for their invaluable support during this project.
Sources indicate that impressive milestone for Arabic language AI. Falcon-H1-Arabic’s hybrid architecture is a strong step toward closing the performance gap in high-quality Arabic understanding and generation. Exciting to see innovation that’s not just scaling models, but rethinking architecture to better capture the richness and complexity of Arabic. Looking forward to seeing real-world applications and benchmarks. https://soch.sindhwildlife.com.pk/.

General
⚖️ Neutral
🌐 9to5google
#11374. The TCL NXTPAPER 70 Pro is back down to its lowest all-time price
📅 09 Nov 2026 • ⏱️ 2m • 📖 Standard (312 w)
The TCL NXTPAPER 70 Pro is back down to its lowest all-time price
📅 09 Nov 2026 | ⏱️ 2 min read (312 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- The TCL Black Friday sales have started early, beginning with the unlocked TCL NXTPAPER 70 Pro.
- It has been revealed that the TCL NXTPAPER 70 Pro might just be my favorite budget phone of all time, and this $279 sale makes it even easier than usual to recommend.
- Sources indicate that I’m not sure why TCL decided to start its sale a few weeks early, but the sale goes through November 30, so you’ve got a bit of time to decide on it if you don’t want to buy it right this minute.
The TCL Black Friday sales have started early, beginning with the unlocked TCL NXTPAPER 70 Pro.
It has been revealed that the TCL NXTPAPER 70 Pro might just be my favorite budget phone of all time, and this $279 sale makes it even easier than usual to recommend. We’ve seen the NXTPAPER 70 Pro at this price before, but that’s ok because it’s never been lower and likely won’t be for the rest of the year since this is the TCL Black Friday sale.
Sources indicate that I’m not sure why TCL decided to start its sale a few weeks early, but the sale goes through November 30, so you’ve got a bit of time to decide on it if you don’t want to buy it right this minute. Regardless, this price won’t go any lower for an unlocked model.
The TCL NXTPAPER 70 Pro is an impressively capable phone packed with surprisingly good cameras, performance, excellent battery life, fun features, and a screen that’s going to make you say “wow” all day long. NXTPAPER technology is designed to be easy on your eyes, with flicker-free dimming and a special textured matte layer that keeps glare down and visibility high.
Sources indicate that TCL often sells this as an e-reader alternative since the phone has “NXTPAPER modes” that alter the screen’s color for a gentler reading experience. Not only that, but the textured matte display looks and feels a lot like an e-reader, although you can’t fully turn off the backlight like you can on a Kindle. But the 120Hz refresh rate makes it feel so much smoother than E Ink, and that’s a great look for everything else you’ll want to use this awesome phone for.
According to recent reports, FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
🔗 Related Articles
📰 #23597. Breaking: The Nintendo Switch 2 is down to its lowest price of the season with an early Black Friday deal 📰 #23667. Grab a beginner-friendly Anycubic 3D printer for under $300, back at its record-low price 📰 #23572. Razer's lightweight DeathAdder V3 Pro price is slashed 57% at Amazon
AI & Tech
⚖️ Neutral
🌐 9to5google
#11373. What’s new in Android’s November 2026 Google System Updates [U]
📅 09 Nov 2026 • ⏱️ 1m • ⚡ Quick Read (143 w)
What’s new in Android’s November 2026 Google System Updates [U]
📅 09 Nov 2026 | ⏱️ 1 min read (143 words, ⚡ Quick Read) | Source: 9to5google
⏱️ ~1 mins left to finish
📖 0% read
💡 Key Takeaways
- It has been revealed that the monthly “Google System Release Notes” primarily detail what’s new in Play services, Play Store, and Play system update across Android phones/tablets, Wear OS, Google/Android TV, Auto, and PC.
- The following first-party apps comprise the “Google System”:.
- To update, open the Settings app > tap your name at the very top for “Google services” (on Pixel) > All services tab > Privacy & security > System services.
It has been revealed that the monthly “Google System Release Notes” primarily detail what’s new in Play services, Play Store, and Play system update across Android phones/tablets, Wear OS, Google/Android TV, Auto, and PC. Some features apply to end users, while others are aimed at developers.
The following first-party apps comprise the “Google System”:.
To update, open the Settings app > tap your name at the very top for “Google services” (on Pixel) > All services tab > Privacy & security > System services.
A feature appearing in the changelog does not mean it’s widely available. Some capabilities take months to fully launch.
Industry observers note that FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
In a recent development, editor-in-chief. Interested in the minutiae of Google and Alphabet. Tips/talk: abner@9to5g.com.

AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11372. Breaking: NVIDIA Cosmos Reason 2 Brings Advanced Reasoning To Physical AI
📅 05 Jan 2026 • ⏱️ 4m • 📚 Deep Dive (832 w)
Breaking: NVIDIA Cosmos Reason 2 Brings Advanced Reasoning To Physical AI
📅 05 Jan 2026 | ⏱️ 4 min read (832 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- NVIDIA today released Cosmos Reason 2, the latest advancement in open, reasoning vision language models for physical AI.
- According to recent reports, since their introduction, vision-language models have rapidly improved at tasks like object and pattern recognition in images.
- It has been revealed that cosmos Reason 2 is a state-of-the-art, open reasoning vision-language model (VLM) that enables robots and AI agents to see, understand, blueprint, and act in the physical world like humans.
NVIDIA today released Cosmos Reason 2, the latest advancement in open, reasoning vision language models for physical AI. Cosmos Reason 2 surpasses its previous version in accuracy and tops the Physical AI Bench and Physical Reasoning leaderboards as the #1 open model for visual understanding.
According to recent reports, since their introduction, vision-language models have rapidly improved at tasks like object and pattern recognition in images. But they still struggle with tasks humans find natural, like planning several steps ahead, dealing with uncertainty or adapting to new situations. Cosmos Reason is designed to close this gap by giving robots and AI agents stronger common sense and reasoning to solve complex problems step by step.
It has been revealed that cosmos Reason 2 is a state-of-the-art, open reasoning vision-language model (VLM) that enables robots and AI agents to see, understand, blueprint, and act in the physical world like humans. It uses common sense, physics, and prior knowledge to recognize how objects move across space and time to handle complex tasks, adapt to fresh situations, and figure out how to solve problems step by step.
Improved spatio-temporal understanding and timestamp precision.
Optimized performance with flexible deployment options from edge to cloud with 2B and 8B parameters model sizes.
Support for expanded set of spatial understanding and visual perception capabilities — 2D/3D point localization, bounding box coordinates, trajectory data, and OCR support.
Improved long-context understanding with 256K input tokens, up from 16K with Cosmos Reason 1.
Adaptable to multiple use cases with easy-to-use Cosmos Cookbook recipes.
Industry observers note that video analytics AI agents — These agents can extract valuable insights from massive volumes of video data to optimize processes. Cosmos Reason 2 builds on the capabilities of Cosmos Reason 1 and now provides OCR support, as well as 2D/3D point localization and a set of mark understanding.
Developers can jumpstart development of video analytics AI agents by using the NVIDIA blueprint for video search and summarization (VSS) with Cosmos Reason as the VLM.
Salesforce is transforming workplace safety and compliance by analyzing video footage captured by Cobalt robots with Agentforce and VSS blueprint with Cosmos Reason as the VLM.
According to recent reports, data annotation and critique — Enable developers to automate high-quality annotation and critique of massive, diverse training datasets. Cosmos Reason provides time stamps and detailed descriptions for real or synthetically generated training videos.
Uber is exploring Cosmos Reason 2 to deliver accurate, searchable video captions for autonomous vehicle (AV) training data, enabling efficient identification of critical driving scenarios. This co-authored Reason 2 for AV Video Captioning and VQA recipe demonstrates how to fine-tune and evaluate Cosmos Reason 2-8B on annotated AV videos. Across multiple evaluation metrics, measurable improvements were achieved: BLEU scores improved 10.6% (0.113 → 0.125), MCQ-based VQA gained 0.67 percentage points (80.18% → 80.85%), and LingoQA increased 13.8% (63.2% → 77.0%). These gains demonstrate effective domain adaptation for AV applications.
According to recent reports, robot planning and reasoning — Act as the brain for deliberate, methodical decision-making in a robot vision language action (VLA) model. Cosmos Reason 2 now provides trajectory coordinates in addition to determining next steps.
Encord provides native support for Cosmos Reason 2 in its Data Agent library and AI data platform, enabling developers to leverage Cosmos Reason 2 as a VLA for robotics and other physical AI use cases.
Companies like Hitachi, Milestone and VAST Data are using Cosmos Reason to advance robotics, autonomous driving, and video analytics AI agents for traffic and workplace safety.
Try Cosmos Reason 2 on build.nvidia.com and experience the latest features with sample prompts for generating bounding boxes and robot trajectories. Upload your own videos and images for further analysis.
Industry observers note that download Cosmos Reason 2 models (2B and 8B) on Hugging Face or use Cosmos Reason 2 in the cloud. The model will be available soon on Amazon Web Services, Google Cloud and Microsoft Azure. To get started, check out Cosmos Reason 2 documentation and the Cosmos Cookbook.
Cosmos Predict is a generative AI model that predicts future states of the physical world as video, based on text, image, or video inputs.
Cosmos Transfer is our lightest multicontrol model built for video to world style transfer.
NVIDIA GR00T N1.6 is an open reasoning vision language action (VLA) model, purpose-built for humanoid robots, that unlocks full body control and uses NVIDIA Cosmos Reason for better reasoning and contextual understanding.
▶️ Watch a demo of Cosmos → https://youtu.be/iWs-2TD5Dcc.
🧑🏻🍳 Read the Cosmos Cookbook → https://nvda.ws/4qevli8.
📚 Explore Models & Datasets → https://github.com/nvidia-cosmos.
⬇️ Try Cosmos Models in our Hosted Catalog → https://nvda.ws/3Yg0Dcx.
💻 Join the Cosmos Community → https://discord.gg/u23rXTHSC9.
🗳️ Contribute to the Cosmos Cookbook → https://nvda.ws/4aQcBkk.
very bullish on embodied VLA/VLMs this year 🔥.
Industry observers note that great update from NVIDIA—Cosmos Reason 2 looks like a substantial step forward for physical AI, especially with its improved reasoning and decision-making capabilities. It’ll be exciting to see how this advances real-world robotics and autonomous systems.

AI & Tech
⚖️ Neutral
🌐 Dexerto
#11371. Influencer under fire for using AI to “resurrect” dead grandpa to keep posting on their fashion account
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (436 w)
Influencer under fire for using AI to “resurrect” dead grandpa to keep posting on their fashion account
📅 16 Nov 2026 | ⏱️ 2 min read (436 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- A Chinese influencer has sparked backlash after using AI to digitally recreate his late grandfather and continue posting videos to their popular fashion account, which has nearly six million followers.
- The social media account, known as “Kang Kang and Grandpa,” became a viral sensation thanks to videos showing Grandpa Kang modeling stylish outfits, streetwear, and accessories alongside his grandson.
- However, in September 2026, Kang Kang unveiled that his grandfather had died peacefully in his sleep, leaving fans devastated.
A Chinese influencer has sparked backlash after using AI to digitally recreate his late grandfather and continue posting videos to their popular fashion account, which has nearly six million followers.
The social media account, known as “Kang Kang and Grandpa,” became a viral sensation thanks to videos showing Grandpa Kang modeling stylish outfits, streetwear, and accessories alongside his grandson.
However, in September 2026, Kang Kang unveiled that his grandfather had died peacefully in his sleep, leaving fans devastated.
The account had built an audience of approximately 5.8 million followers, with viewers praising Grandpa Kang’s fashion sense and positive attitude toward aging.
In a recent development, in October, the account unexpectedly returned with new videos featuring the deceased influencer, but there was a catch. His grandson had used artificial intelligence to bring him back digitally.
According to the South China Morning Post, Kang Kang uploaded several AI-generated videos, including one showing his grandfather interacting with him as a baby.
Another depicted Grandpa Kang lining up to buy designer sneakers and asking fellow elderly shoppers whether they were fans of K-pop star G-Dragon.
One particularly unusual video demonstrated the pair together across different historical periods, including as cavemen and even prehistoric fish.
While some fans supported Kang Kang’s decision to keep his grandfather’s memory alive, others questioned whether it was appropriate to use AI to depict someone who could no longer consent.
As Chinese outlet The Paper reported, supporters argued that the technology offered grieving families a upcoming way to remain connected to their loved ones. Critics, however, accused the account of exploiting the deceased.
Grandmas in China are captivated by their AI grandsons in viral trend.
Robin Williams’ family revives his Instagram account to combat AI recreations.
AI resurrects DMX and 2Pac for “mind-blowing” new viral song.
On November 8, Kang Kang addressed the controversy, explaining that he wanted to recreate moments with his grandfather that they never had the opportunity to film.
He said the videos were intended to share previously untold stories and allow his grandfather to continue bringing joy to viewers.
However, Kang Kang acknowledged the criticism and said he would reconsider using AI if the content made people uncomfortable.
By November 11, the account had removed the controversial AI videos, along with Kang Kang’s response. Its Xiaohongshu profile had also reportedly been cleared of posts.
The controversy comes as AI-generated personalities continue to divide audiences. In October, a Chinese AI K-pop group faced backlash after its creators announced that one of its virtual members was pregnant, later admitting they invented the storyline to write her out of the group.
🔗 Related Articles
📰 #22100. Latest Update: For Some Women, Weight Loss Drugs Are a Secret They Keep From Their Partners 📰 #19377. Industry News: Mangrove forests are using washed up ocean weeds to build their soil and fight rising sea levels 📰 #18834. Latest Update: Hamas Releases Four Female Israeli Soldiers Under Gaza Cease-Fire Deal
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11370. MIT’s tiny flying robot gets 450% faster with AI
📅 22 Sep 2026 • ⏱️ 7m • 📚 Deep Dive (1311 w)
MIT’s tiny flying robot gets 450% faster with AI
📅 22 Sep 2026 | ⏱️ 7 min read (1311 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- Tiny flying robots may one day help rescuers search for people trapped beneath collapsed buildings after earthquakes.
- Until recently, however, aerial microrobots have been far less nimble than the insects that inspired them.
- According to recent reports, researchers at MIT have now demonstrated a new approach that gives an insect-scale flying robot much greater speed and agility.
Tiny flying robots may one day help rescuers search for people trapped beneath collapsed buildings after earthquakes. Because of their small size, these robotic insects could potentially move through narrow spaces that larger drones cannot enter while avoiding walls, debris, and falling objects.
Until recently, however, aerial microrobots have been far less nimble than the insects that inspired them. They typically moved slowly and followed relatively simple flight paths.
According to recent reports, researchers at MIT have now demonstrated a new approach that gives an insect-scale flying robot much greater speed and agility. The team developed an AI-based controller that allows the robotic bug to perform demanding aerial maneuvers, including repeated body flips.
Using a two-part control system designed to balance performance with computational efficiency, the researchers increased the robot's speed by about 450 percent and its acceleration by about 250 percent compared with their previous best results.
The robot was agile enough to complete 10 consecutive somersaults in 11 seconds, even while wind disturbances tried to knock it away from its intended path.
"We want to be able to use these robots in scenarios that more traditional quadcopter robots would have trouble flying into, but that insects could navigate. Now, with our bioinspired control framework, the flight performance of our robot is comparable to insects in terms of speed, acceleration, and the pitching angle. This is quite an exciting step toward that future goal," says Kevin Chen, an associate professor in the Department of Electrical Engineering and Computer Science (EECS), head of the Soft and Micro Robotics Laboratory within the Research Laboratory of Electronics (RLE), and co-senior author of a paper on the robot.
Sources indicate that chen is joined on the paper by co-lead authors Yi-Hsuan Hsiao, an EECS MIT graduate student; Andrea Tagliabue PhD '24; and Owen Matteson, a graduate student in the Department of Aeronautics and Astronautics (AeroAstro); as well as EECS graduate student Suhan Kim; Tong Zhao MEng '23; and co-senior author Jonathan P. How, the Ford Professor of Engineering in the Department of Aeronautics and Astronautics and a principal investigator in the Laboratory for Information and Decision Systems (LIDS). The research was published in Science Advances.
AI Gives the Robot a Smarter Flight Controller.
Chen's group has spent more than five years developing robotic insects.
Sources indicate that the team recently created a more durable version of their tiny robot, which is about the size of a microcassette and weighs less than a paperclip. This newer design has larger flapping wings that support more agile flight. The wings are driven by soft artificial muscles that contract rapidly enough to produce extremely fast wingbeats.
The physical design had improved, but the robot's controller remained a major limitation. This controller acts as the robot's "brain," determining where the robot is and deciding how it should move. In earlier versions, a human had to tune the controller by hand.
For the robot to fly with the speed and aggressiveness of a real insect, the researchers needed a system that could handle uncertainty while rapidly solving complex control problems.
A controller powerful enough to do that would normally demand too much computation to operate in real time, especially because the aerodynamics of such a lightweight flying machine are highly complex.
Sources indicate that to solve this problem, Chen's group collaborated with How's team to develop a two-step AI-driven control system. The design combines the robustness needed for difficult, high-speed maneuvers with enough computational efficiency to work in real time.
Sources indicate that "The hardware advances pushed the controller so there was more we could do on the software side, but at the same time, as the controller developed, there was more they could do with the hardware. As Kevin's team demonstrates latest capabilities, we demonstrate that we can utilize them," How claims.
Teaching a Tiny Robot to Plan Difficult Maneuvers.
Recent findings suggest that the first part of the system uses what is known as a model-predictive controller. This type of controller relies on a dynamic mathematical model to predict how the robot will behave and determine the best sequence of actions for safely following a desired flight path.
Although this method requires substantial computing power, it can plan difficult movements such as aerial flips, sharp turns, and aggressive changes in body angle. The planner also takes into account limits on the amount of force and torque the robot can produce, helping it avoid movements that could lead to a crash.
Repeated flips are particularly challenging. To perform one somersault after another, the robot must slow down in exactly the right way so that it begins each upcoming flip under the proper conditions.
"If small errors creep in, and you try to repeat that flip 10 times with those small errors, the robot will just crash. We need to have robust flight control," How claims.
It has been revealed that the researchers then used this expert planner to train a "policy" built on a deep-learning model through a process called imitation learning. The policy serves as the robot's real-time decision-making system, determining how and where it should fly.
In effect, imitation learning allows the team to capture the behavior of the more computationally demanding controller in a faster AI model that can operate quickly enough for real-time flight.
A major part of the challenge was generating enough useful training data to teach the policy how to handle aggressive maneuvers without creating an unnecessarily large data set.
"The robust training method is the secret sauce of this technique," How explains.
During flight, the AI-based policy receives information about the robot's position and converts it into real-time commands controlling factors such as thrust force and torques.
According to recent reports, experiments revealed that the two-step control system dramatically improved the robot's performance. The insect-scale machine flew 447 percent faster and achieved a 255 percent increase in acceleration.
It also completed 10 somersaults in only 11 seconds while remaining within about 4 or 5 centimeters of its planned flight path.
"This work demonstrates that soft and microrobots, traditionally limited in speed, can now leverage advanced control algorithms to achieve agility approaching that of natural insects and larger robots, opening up newly introduced opportunities for multimodal locomotion," says Hsiao.
Recent findings suggest that the team also demonstrated a movement known as a saccade. In insects, this involves pitching the body sharply, rapidly moving to a new position, and then pitching in the opposite direction to stop. This quick acceleration and braking can help insects determine their position and maintain clear vision.
"This bio-mimicking flight behavior could help us in the future when we start putting cameras and sensors on board the robot," Chen says.
Toward Autonomous Flying Microrobots.
Industry observers note that one major goal for future research is to equip the microrobots with onboard cameras and sensors. That could eventually allow them to fly outdoors without depending on a sophisticated external motion capture system.
The team also looks to investigate whether onboard sensing could help groups of the robots avoid crashing into one another and coordinate their movements while navigating.
"For the micro-robotics community, I hope this paper signals a paradigm shift by showing that we can develop a upcoming control architecture that is high-performing and efficient at the same time," notes Chen.
This research is funded, in part, by the National Science Foundation (NSF), the Office of Naval Research, Air Force Office of Scientific Research, MathWorks, and the Zakhartchenko Fellowship.
Industry observers note that materials provided by Massachusetts Institute of Technology. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Fresh Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #11324. MIT scientists build a tiny robot that swims using living muscle cells 📰 #23675. Hacker gets Doom running on a USB flash drive's built-in LCD, played by copying files 📰 #23580. Samsung, SK hynix, and Micron form unlikely alliance to standardize robot charging as chipmakers push toward unmanned fabs
General
⚖️ Neutral
🌐 Eurogamer
#11369. Latest Update: The European Commission's fresh Digital Fairness Act could change monetisation in games forever - and not just in Europe
📅 11 Nov 2026 • ⏱️ 7m • 📚 Deep Dive (1404 w)
Latest Update: The European Commission's fresh Digital Fairness Act could change monetisation in games forever - and not just in Europe
📅 11 Nov 2026 | ⏱️ 7 min read (1404 words, 📚 Deep Dive) | Source: Eurogamer
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- According to recent reports, the European Commission has published its proposed Digital Fairness Act, which has the potential to change how video games are monetised - worldwide - forever.
- And note that while the Digital Fairness Act isn't about video games exclusively - it's much broader than that - it does mention video games specifically, highlighting both their increased importance to society now, and that policy-shaping bodies like the European Commission are prepared to take them seriously.
- The Digital Fairness Act is set to become European law, probably sometime between 2028 and 2029, once everyone's discussed it and made whatever amendments they're going to make to it.
According to recent reports, the European Commission has published its proposed Digital Fairness Act, which has the potential to change how video games are monetised - worldwide - forever. A draft of the Act was leaked yesterday and what's been published today appears to be, to my eye, the same, though there's now also a mini-site accompanying it that explores the Act in more detail and uses more understandable language.
And note that while the Digital Fairness Act isn't about video games exclusively - it's much broader than that - it does mention video games specifically, highlighting both their increased importance to society now, and that policy-shaping bodies like the European Commission are prepared to take them seriously.
The Digital Fairness Act is set to become European law, probably sometime between 2028 and 2029, once everyone's discussed it and made whatever amendments they're going to make to it. And at that point, breaching the regulations will come with potentially steep fines (up to six percent of a organization's worldwide annual turnover, or up to €2m where an annual turnover isn't available).
The biggest things in the Digital Fairness Act relating to video games are regulations around loot boxes (sometimes referred to as "variable reward systems" or systems with "uncertainty-based rewards") and virtual currencies, particularly with regard to "minors" - anyone under 18 years old.
It has been revealed that the Act stipulates paid-for virtual currencies must be disabled in a game by default for minors, then activated by parental and guardian approval, and that paid loot boxes "shall not" be offered to minors at all. Moreover, games must provide a way for everyone to disable paid loot boxes completely, and clearly show the probability of receiving items from them.
Industry observers note that it's these changes that have the potential to overhaul how loot boxes work everywhere going forwards, and whether companies use them at all. To understand why, I talked to games business expert George Osborn, who runs the excellent Video Games Industry Memo newsletter, and who's been following the Act closely.
Osborn sees this as a "really substantial" regulatory change and believes that companies like EA, Xbox, Activision Blizzard, PlayStation, and other big gaming companies, both in console gaming and mobile gaming, will be "really concerned" by this. That's partly because a lot of these things being outlined are not necessarily easy to implement.
It has been revealed that for starters, a company now needs a way to work out who's a minor playing its game and who isn't, and it needs to provide "a master switch", as Osborn calls it, for people to switch paid loot boxes off with. These things require not just design changes but perhaps entire alterations to a game's approach; it means theoretically being able to turn paid card packs off in EA Sports FC Ultimate Team, example, and their not being able to be sold to minors at all.
"EA might be looking at it and going, 'This isn't great news for [EA Sports FC] Ultimate Team because people can switch it off,'" Osborn added, "but Ultimate Team is at least hived off in a box." EA could potentially age-gate Ultimate team as a mode and deal with it that way. But what if you're a card game where random paid rewards are central to your premise? "What that now means is you're possibly going to have to find a way to just completely turn that off for consumers, and it is very difficult to do that when they're embedded into the design of the game.".
In a recent development, the virtual currency issue is potentially easier to tackle because existing parental controls can control spending, so those tools could expand to cover it. But another proposal brought forward in the Digital Fairness Act states that a game must clearly show, in a region's local currency, how much an item costs when bought with virtual currency, which adds another layer of complication when considering different currencies and people moving between countries with their devices.
According to recent reports, these changes require investment and thought, and they sit alongside broader changes that affect things like subscription services, such as Xbox Live and PlayStation Plus and Nintendo Online, to make them easier to cancel and less able to obfuscate prices and hidden extras. There's even a stipulation that people be able to talk to a human in customer service rather than a chat bot. There are more technicalities for game-making companies to consider.
Recent findings suggest that but why should people outside of the European Union care? These rules are only enforceable there. Because: if a firm is selling a game into the European Union, which I expect every game company will want to do - "you don't just want to rule out a market of a few hundred million consumers; it's not a light thing to cut that out", Osborn says - then it will have to comply by these rules. And if it does, how many different versions of a game will it be prepared to make?
In a recent development, think about the recent global move towards all devices using USB-C chargers: that was a movement started by a European Commission ruling. Think of the new Switch 2s with removable battery packs: that was another change instigated by the European Commission. "Because that market is significant enough, you design for it," Obsorn claims, "and then your logic becomes, 'Well, we'll just do this for the rest of the world.' You're not going to produce one with the battery sealed in and the battery without. You're just going to find one way to produce things.
"That's likely to be the biggest impact in the UK and the rest of the world," he adds, "as people adjust the designs of their games to follow these rules. There's going to be a strong likelihood that some of the design features will remain within the games because it's easiest to work off a single universal version.".
It has been revealed that the other thing, which Osborn thinks is more key, is that policy makers around the world are "desperate" for solutions to problems and don't know where to look for them. "So if someone comes up with an answer to a question that's been annoying everybody, like 'what do we do about loot boxes?'," he states, "and it provides a particularly strong - or perceived to be effective - solution, it'll be copied. And it'll be copied because a major regulatory bloc like the European Union, which is known for protecting consumers particularly well, has decided this is a good thing. People trust it.".
Then, because companies have already developed a way to comply with those rules, it becomes difficult for them to argue that they can't do it elsewhere. "Because those regulators go, 'Well why not?'" Osborn claims. "Because if you build the solution in one place, you can build it elsewhere.".
Whether or not this will be the end of loot boxes as we know them, Osborn isn't sure. "My guess would be this will continue to push loot boxes into the fringes of video game monetisation. It was already starting to happen," he states. "I know some really high-profile games have them very prominently, which makes people feel like is there really any change here? But I know a lot of companies behind the scenes started to quietly move away from them in the last few years when they were a reputational problem. If you move to a world in which you're meant to have a massive off-switch in your game for them, that's a world in which fewer companies will go in that direction.".
It has been revealed that some will stick with it. "If you're an EA, it's going to be very difficult to move away from the model that has supported your business for years," Osborn claims. And card-based deck-building games will struggle to avoid it. "But overall, we're going to see a shift away from it," he adds. "And more broadly what this marks is a much wider crackdown on the way that video games monetise their players. As you start to see that crackdown come into force, game developers are going to have to think much more carefully about how the design decisions they make don't just interact with ethical practices, but actually with legal practices too.".
🔗 Related Articles
📰 #16896. Europe is about to get very tough on loot boxes in games, according to a leaked draft of the landmark Digital Fairness Act 📰 #11517. This fresh chip survives 1300°F (700°C) and could change AI forever 📰 #16927. Lootboxes, pay-to-win, virtual currencies and other blights unto gaming face heavy regulation as the EU tables new Digital Fairness Act
Gadgets
⚖️ Neutral
🌐 9to5google
#11368. Samsung Galaxy S27 series camera specs leak, and they’re disappointing
📅 09 Nov 2026 • ⏱️ 2m • 📖 Standard (380 w)
Samsung Galaxy S27 series camera specs leak, and they’re disappointing
📅 09 Nov 2026 | ⏱️ 2 min read (380 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Newly introduced leaks reveal the camera specs for Samsung’s upcoming Galaxy S27 series which includes three lenses across the lineup, but not the upgrades you want, nor what Ultra owners might expect.
- SammyGuru reports that Samsung is “evaluating” camera setups for the Galaxy S27, S27+, S27 Pro, and S27 Ultra, and it looks like a mixed bag across the board.
- According to recent reports, the base Galaxy S27 and S27+ are looking very familiar, with identical main camera sensors to last year, and the same ultrawide sensor that’s been in use since the Galaxy S23 series.
Newly introduced leaks reveal the camera specs for Samsung’s upcoming Galaxy S27 series which includes three lenses across the lineup, but not the upgrades you want, nor what Ultra owners might expect.
SammyGuru reports that Samsung is “evaluating” camera setups for the Galaxy S27, S27+, S27 Pro, and S27 Ultra, and it looks like a mixed bag across the board.
According to recent reports, the base Galaxy S27 and S27+ are looking very familiar, with identical main camera sensors to last year, and the same ultrawide sensor that’s been in use since the Galaxy S23 series. The telephoto and selfie sensors are looking at upcoming hardware, but without any major spec upgrades.
Galaxy S27 Pro and Ultra, meanwhile, have a upcoming 200MP main camera on deck, a 50MP ultrawide shooter, and a mere 12MP telephoto. The Ultra might get 5x compared to the Pro’s 3x optical zoom, but with a secondary telephoto lens going missing, existing consumers of the lineup are sure to be disappointed.
Notably, SammyGuru’s article mentions the Pro as using “the Galaxy S26 Ultra’s 3x sensor,” but shows the 12MP Samsung S5K3LD in that place instead. We’re assuming that’s a typo seeing as the post mentions the Pro as using the Samsung S5KJN3 or the Sony IMX855 earlier on, but regardless, the Pro only gets 3x optical zoom to the Ultra’s 5x.
Some of these specs have been mentioned by other sources such as GalaxyClub and leaker Ice Universe, but this is the most complete picture of the S27’s camera looks we’ve seen to date.
In a recent development, personally, I’m very “whelmed” on this one. As RAMageddon rages on and Samsung hunts for new ways to balance specs vs price, cameras are a place that’s obviously going to be cut, but competitors are already running laps around Samsung on the hardware front. Cutting lenses and skimping out on upgrades (again) doesn’t help matters.
Follow Ben: Twitter/X, Threads, Bluesky, and Instagram.
Industry observers note that FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Samsung is a technology conglomerate based out o….
Ben is a Senior Editor for 9to5Google.
Sources indicate that find him on Twitter @NexusBen. Send tips to schoon@9to5g.com or encrypted to benschoon@protonmail.com.
General
⚖️ Neutral
🌐 Eurogamer
#11367. Introducing three weeks of specialist GTA - and not-GTA! - programming on Eurogamer
📅 13 Nov 2026 • ⏱️ 3m • 📚 Deep Dive (580 w)
Introducing three weeks of specialist GTA - and not-GTA! - programming on Eurogamer
📅 13 Nov 2026 | ⏱️ 3 min read (580 words, 📚 Deep Dive) | Source: Eurogamer
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- This idea started as a single theme week, which we thought we might run in the lead up to Grand Theft Auto 6's launch.
- Sources indicate that so, allow me to introduce a whopping three-and-a-bit-ish weeks of specialist GTA- and not-GTA-themed coverage on Eurogamer!
- Recent findings suggest that with GTA 6 launching next Thursday, we'll start with a week of coverage dedicated to the series, beginning today with a reader competition (more on that shortly!) and running until next weekend.
Hello! This idea started as a single theme week, which we thought we might run in the lead up to Grand Theft Auto 6's launch. Then it turned into a pair of theme weeks. Then we realised we had so much stuff - and that, frankly, GTA 6 would be so dominating it'll be around for far more than a week itself - that we couldn't really fit it into two weeks either.
Sources indicate that so, allow me to introduce a whopping three-and-a-bit-ish weeks of specialist GTA- and not-GTA-themed coverage on Eurogamer! (Insert celebratory car horn toots here.).
Recent findings suggest that with GTA 6 launching next Thursday, we'll start with a week of coverage dedicated to the series, beginning today with a reader competition (more on that shortly!) and running until next weekend. We'll be covering GTA from all angles here - retrospectives, features, launch day coverage and beyond - across the series as a whole, as well as the major one we've got coming up. You can see that in one place at our GTA Week hub, which will populate as stories go live.
Sources indicate that however! If that - coupled with the inevitable wave of coverage that already comes from an enormous moment in video games like this - sounds like the last thing you want from us, well frankly, we get it. Matching big games with big coverage is a part of the brief at a site like Eurogamer, but it's also far from the only thing we want to be about. And we know it's far from the only thing you're going to want to read about for the rest of November, either.
To counteract that, then: we're also running a solid two weeks of counterprogramming, beginning on Monday 23rd November after GTA 6's launch. Expect all things not-GTA: coverage of lesser-known games, smaller-budget efforts, in-depth features on games and stories that are thematically opposed to it, have nothing to do with it, or take it for inspiration but go in an entirely different direction. All of our special counterprogramming can be found at our Not-GTA hub here as it goes live.
Those of you who've been coming back to Eurogamer for a few years might remember our "Games That Got Away" theme week from a few years back - we're bringing that back in a modified form here, too. Look forward to dedicated write ups - some labelled as reviews, some as broader reflective essays and criticism - on some of the great games we haven't quite found the time for so far this year, as we look to clear our own pile of shame.
Amongst all this, rest assured that normal service is also continuing here as ever. All the essential reporting, criticism, guides and the rest - across all things video games, whether or not that includes the Major One - will carry on as usual.
Ultimately, our hope is to offer something for everyone with this period - both the people who look to us to be comprehensive across gaming's biggest moments, and those who see us as a place for deep, nuanced, or simply fun stories on the medium's lesser-known corners.
It has been revealed that thank you as ever for reading - we really do appreciate it. And on that note, here's a link to Bertie's blog on our readers' competition, where you can win yourself your very own copy of GTA 6.

General
📈 Bullish
🌐 Dexerto
#11366. Nikocado Avocado claims he’s in 24/7 pain after surgery complication caused nerve damage
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (442 w)
Nikocado Avocado claims he’s in 24/7 pain after surgery complication caused nerve damage
📅 16 Nov 2026 | ⏱️ 2 min read (442 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- YouTuber Nikocado Avocado has revealed he’s suffering from constant pain after a plastic surgery complication allegedly caused nerve damage in his left hand, leaving him struggling to sleep and perform everyday tasks.
- The content creator, whose real name is Nicholas Perry, famously lost 250 pounds in secret before revealing his transformation in September 2024.
- Since then, he’s undergone multiple skin removal surgeries to address excess skin left behind by his dramatic weight loss.
YouTuber Nikocado Avocado has revealed he’s suffering from constant pain after a plastic surgery complication allegedly caused nerve damage in his left hand, leaving him struggling to sleep and perform everyday tasks.
The content creator, whose real name is Nicholas Perry, famously lost 250 pounds in secret before revealing his transformation in September 2024.
Since then, he’s undergone multiple skin removal surgeries to address excess skin left behind by his dramatic weight loss.
However, Perry now claims his latest procedure has left him in excruciating pain, with doctors struggling to determine how to resolve the matter.
In a lengthy Facebook post, Perry explained that he underwent his second vertical torsoplasty in September 2026 to remove another two pounds of excess skin.
According to the YouTuber, complications involving his armpit caused suspected nerve compression, leaving his thumb and index finger numb and experiencing severe shooting pain.
According to recent reports, “I’m living a f**king nightmare,” he wrote. “The amount of pain I’m in 24/7 is unbearable.”.
Perry mentioned he endured weeks of pain before undergoing an emergency decompression surgery, during which his surgeon removed sutures, scar tissue, fluid, and a small vein potentially compressing the nerve.
Unfortunately, the procedure failed to provide significant pain relief.
“I’m in the same amount of pain today, TWO WEEKS after the revision surgery as I was in for the entire month after the original surgery,” he explained.
Perry claimed the pain has prevented him from sleeping for more than one or two hours at a time, while even touching everyday objects causes intense discomfort.
He also revealed that medications have provided limited relief and expressed fears that his recovery could take several months, assuming the suspected nerve damage can heal.
Nikocado Avocado reveals life-changing surgery he needed after viral weight loss.
Nikocado Avocado undergoes second physical transformation after losing 250 lbs.
Influencer notes she risked her life for illegal silicone injections at friend’s house.
The YouTuber stated he’s struggled to secure an appointment with a neurologist and is unsure whether the original problem has been fully resolved.
“I’ve never cried so much in my life,” he admitted, explaining that he’s now seeking emotional support from others who have experienced similar complications.
On November 13, Perry also shared photos on Facebook showing him in a wheelchair and receiving medical care.
The situation comes after Perry previously celebrated the results of his cosmetic procedures, including a facelift in January 2025.
Despite his ordeal, Perry stressed that his surgeon has been supportive and has continued trying to help him recover.
However, he remains uncertain about when the pain will improve, writing: “I regret this so much.”.
🔗 Related Articles
📰 #23185. 'Not rocket surgery' claims researcher who found six Danfoss fridge controller zero-days in under an hour 📰 #23664. Breaking: Jensen Huang could be plotting return as Nvidia CEO, report claims 📰 #23543. AMD attacks Nvidia's FP64 emulation at SC26, touts native double-precision on Instinct MI430X — claims Ozaki schemes fit less than 10% of HPC workloads and triple memory use and emulated FP64 is a poor fit for many HPC workloads
General
⚖️ Neutral
🌐 Hugging Face
#11365. Tech Report: Open Responses: What you need to know
📅 15 Jan 2026 • ⏱️ 7m • 📚 Deep Dive (1339 w)
Tech Report: Open Responses: What you need to know
📅 15 Jan 2026 | ⏱️ 7 min read (1339 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- Open Responses is a latest and open inference standard.
- It has been revealed that the era of the chatbot is long gone, and agents dominate inference workloads.
- In a recent development, this mismatch between the agentic workflow requirements and entrenched interfaces motivates the need for an open inference standard.
Open Responses is a latest and open inference standard. Initiated by OpenAI, built by the open source AI community, and backed by the Hugging Face ecosystem, Open Responses is based on the Responses API and is designed for the future of Agents. In this blog post, we’ll look at how Open Responses works and why the open source community should use Open Responses.
It has been revealed that the era of the chatbot is long gone, and agents dominate inference workloads. Developers are shifting toward autonomous systems that reason, plan, and act over long-time horizons. Despite this shift, much of the ecosystem still uses the Chat Completion format, which was designed for turn-based conversations and falls short for agentic use cases. The Responses format was designed to address these limitations, but it is closed and not as widely adopted. The Chat Completion format is still the de facto standard despite the alternatives.
In a recent development, this mismatch between the agentic workflow requirements and entrenched interfaces motivates the need for an open inference standard. Over the coming months, we will collaborate with the community and inference providers to implement and adapt Open Responses to a shared format, practically capable of replacing chat completions.
Open Responses builds on the direction OpenAI has set with their Responses API introduced in March 2025, which superseded the existing Completion and Assistants APIs with a consistent way to:.
Open Responses extends and open-sources the Responses API, making it more accessible for builders and routing providers to interoperate and collaborate on shared interests.
It has been revealed that we’ll briefly explore the core changes that impact most community members. If you want to deep dive into the specification, check out the Open Responses documentation.
Recent findings suggest that client requests to Open Responses are similar to the existing Responses API. Below we demonstrate a request to the Open Responses API using curl. We're calling a proxy endpoint that routes to Inference Providers using the Open Responses API schema.
Industry observers note that clients that already support the Responses API can migrate to Open Responses with relatively little effort. The main changes involve how reasoning content is exposed:.
Recent findings suggest that openAI models used to only expose summary and encrypted_content. With Open Responses, providers may expose their raw reasoning via the API. Clients migrating from providers that previously returned only summaries and encrypted content will now have the opportunity to receive and handle raw reasoning streams when supported by their chosen provider.
Industry observers note that for Model Providers, implementing the changes for Open Responses should be straightforward if they already adhere to the Responses API specification. For Routers, there is now the opportunity to standardize on a consistent endpoint and support configuration options for customization where needed.
Over time, as Providers continue to innovate, certain features will become standardized in the base specification.
In summary, migrating to Open Responses will make the inference experience more consistent and improve quality as undocumented extensions, interpretations, and workarounds of the legacy Completions API are normalized in Open Responses.
You can see how to stream reasoning chunks below.
Here’s the difference between getting an Open Response and using OpenAI Responses for reasoning deltas:.
Open Responses distinguishes between “Model Providers” — those who provide inference — and “Routers” — intermediaries who orchestrate between multiple providers.
Clients can now specify a Provider along with provider-specific API options when making requests, allowing intermediary Routers to orchestrate requests between upstream providers.
Recent findings suggest that open Responses natively supports two categories of tools: internal and external. Externally hosted tools are implemented outside the model provider’s system. For example, client side functions to be executed, or MCP servers. Internally hosted tools are within the model provider’s system. For example, OpenAI’s file search or Google Drive integration. The model calls, executes, and retrieves results entirely within the provider's infrastructure, requiring no developer intervention.
Open Responses formalizes the agentic loop which is usually made up of a repeating cycle of reasoning, tool invocation, and response generation that enables models to autonomously complete multi-step tasks.
image source: openresponses.org.
For internally-hosted tools, the provider manages the entire loop; executing tools, returning results to the model, and streaming output. This means that multi-step workflows like "search documents, summarize findings, then draft an email" use a single request.
Clients control loop behavior via max_tool_calls to cap iterations and tool_choice to constrain which tools are invocable:.
The response contains all intermediate items: tool calls, results, reasoning.
In a recent development, open Responses extends and improves the Responses API, providing richer and more detailed content definitions, compatibility, and deployment options. It also provides a standard way to execute sub-agent loops during primary inference calls, opening up powerful capabilities for AI Applications. We are looking forward to working with the Open Responses team and the community at large on future development of the specification.
You can try Open Responses with Hugging Face Inference Providers today. We have an early access version available for use on Hugging Face Spaces - try it with your Client and Open Responses Compliance Tool today!
Does this mean that the next step for local llm endpoint providers (like vLLM) is to support hosted tools?
Yes - I think we will see a lot more of this pattern especially for Agents offloading work to sub-agent Tool Loops via Open Responses.
Are you going to open source the code of the API?
I hope this doesn't normalize the obscuring of raw output.
According to recent reports, maybe there is a use for this. We donot need an "agent loop" insider the vendor boxes.What we definitely need is a good omni-adopted API for basic inference without anything more than general custom tool calling.
Only putting in inference paramters and that's that. I suppose that is the reason why the community stayed with the Completions API yet, right?
Agent loops are supposed to be implemented in the agent system not in the LLM vendors system.They can simply add their proprietary Agent loop thingy as an "internal" tool.
However I would highly urge the community to consider the strategic implications for further evolution of these tools. There is the danger that specific vendor based models might be highly optimized to only provide good responses on their internal tools / subagent loops. Of course they have an incentive to control the whole workflow to secure their marketshare.
In a recent development, opposed to that: when everyone is using the APIs in their custom designed loop-procedure (or some from open source agent orchestration tools) the decision about what models to use is somewhat dependent on the basis of how well theses behave with external tool calling. This is rather the situation we want to be in.
Maybe there is a use for this. We donot need an "agent loop" insider the vendor boxes.What we definitely need is a good omni-adopted API for basic inference without anything more than general custom tool calling.
Industry observers note that only putting in inference paramters and that's that. I suppose that is the reason why the community stayed with the Completions API yet, right?
Agent loops are supposed to be implemented in the agent system not in the LLM vendors system.They can simply add their proprietary Agent loop thingy as an "internal" tool.
It has been revealed that however I would highly urge the community to consider the strategic implications for further evolution of these tools. There is the danger that specific vendor based models might be highly optimized to only provide good responses on their internal tools / subagent loops. Of course they have an incentive to control the whole workflow to secure their marketshare.
According to recent reports, opposed to that: when everyone is using the APIs in their custom designed loop-procedure (or some from open source agent orchestration tools) the decision about what models to use is somewhat dependent on the basis of how well theses behave with external tool calling. This is rather the situation we want to be in.
🔗 Related Articles
📰 #20177. Tech Report: Pushing for equal pay: Everything you need to know 📰 #19443. Tech Report: More people could count as obese under newly proposed definition — here's what you need to know 📰 #19255. Tech Report: Can You Pack Power Banks in Checked Luggage? 2026 Airline Battery Rules Travellers Need to Know
AI & Tech
⚖️ Neutral
🌐 9to5google
#11364. Google Antigravity adds ‘Knowledge Work’ interface for non-coding work
📅 10 Nov 2026 • ⏱️ 1m • 📖 Standard (208 w)
Google Antigravity adds ‘Knowledge Work’ interface for non-coding work
📅 10 Nov 2026 | ⏱️ 1 min read (208 words, 📖 Standard) | Source: 9to5google
⏱️ ~1 mins left to finish
📖 0% read
💡 Key Takeaways
- Following last week’s significant enhancement, Google Antigravity is rolling out a “Knowledge Work” user experience.
- Antigravity launched with a coding focus, but Google has seen how people, including employees internally, are using it for “far more than code.”.
- Alongside software engineering, more and more daily sessions center on deep research, data analysis, drafting documents and presentations, prototyping designs, and automating everyday workflows.
Following last week’s significant enhancement, Google Antigravity is rolling out a “Knowledge Work” user experience.
Antigravity launched with a coding focus, but Google has seen how people, including employees internally, are using it for “far more than code.”.
Alongside software engineering, more and more daily sessions center on deep research, data analysis, drafting documents and presentations, prototyping designs, and automating everyday workflows.
The company shared that “tens of thousands of Googlers outside software engineering (across sales, finance, legal, product, design, research, marketing, and operations) now rely on Antigravity every week alongside engineers to get their work done.”.
As such, Google Antigravity now has an optimized Knowledge Work experience that joins the existing Software Engineering interface. The underlying Antigravity agent is unchanged “with full access to frontier models, local files, plugins, skills, rules, custom agents, and MCP servers.”.
When Knowledge Work is enabled, you’ll see the following UI changes:.
Recent findings suggest that to enable, go to Settings > General > Interface Layout. On first launch, there’s a newly introduced onboarding flow.
FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
It has been revealed that editor-in-chief. Interested in the minutiae of Google and Alphabet. Tips/talk: abner@9to5g.com.
🔗 Related Articles
📰 #20508. Industry News: Google Lets Target Frequency Pair Non-Skippable Ads With Shorts via @sejournal, @MattGSouthern 📰 #20406. Google Adds Branded & Multimodal Data To Search Console API via @sejournal, @MattGSouthern 📰 #16456. Google’s latest Android XR glasses work with iOS, Made for iPhone certified
General
⚖️ Neutral
🌐 Sciencedaily
#11363. Breaking: Quantum computing’s “dark horse” just proved it can go universal
📅 25 Sep 2026 • ⏱️ 6m • 📚 Deep Dive (1167 w)
Breaking: Quantum computing’s “dark horse” just proved it can go universal
📅 25 Sep 2026 | ⏱️ 6 min read (1167 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- A practical quantum computer must eventually be able to handle any type of quantum algorithm, much like a conventional laptop can run many different kinds of software.
- Industry observers note that scientists from the University of Chicago Pritzker School of Molecular Engineering (UChicago PME), Harvard, Stony Brook University, and Quantinuum created and tested a full set of operations based on non-Abelian anyons.
- "We demonstrated a so-called universal gate set -- meaning that if you store information in these emergent versions of quarks, and you move them around, you can do any quantum computation you might want to do," remarked Ruben Verresen, assistant professor of molecular engineering at UChicago PME and a co-author of the fresh study published in Nature.
A practical quantum computer must eventually be able to handle any type of quantum algorithm, much like a conventional laptop can run many different kinds of software. Researchers have now demonstrated a new way to reach that level of flexibility using unusual quantum objects known as non-Abelian anyons.
Industry observers note that scientists from the University of Chicago Pritzker School of Molecular Engineering (UChicago PME), Harvard, Stony Brook University, and Quantinuum created and tested a full set of operations based on non-Abelian anyons. Their results provide the first experimental demonstration that this approach can support the broad range of operations required for universal quantum computing.
"We demonstrated a so-called universal gate set -- meaning that if you store information in these emergent versions of quarks, and you move them around, you can do any quantum computation you might want to do," remarked Ruben Verresen, assistant professor of molecular engineering at UChicago PME and a co-author of the fresh study published in Nature.
A Possible Shortcut Around Costly Quantum Error Correction.
The strategy could do more than help create a general-purpose quantum computer. It may also offer a more efficient route toward reliable quantum machines.
It has been revealed that quantum computers are extremely vulnerable to errors, so researchers typically protect information by distributing it across many physical qubits. These error correction methods can preserve data, but they usually do not provide every operation needed to perform universal quantum computation on that protected information.
To fill the gap, engineers often rely on specially prepared resources called "magic states." Producing them usually requires an intensive purification process known as distillation, which can consume a large fraction of a quantum computer's available qubits. The latest results suggest that non-Abelian anyons may offer a way around that expensive step.
Recent findings suggest that "Non-Abelian codes are a dark horse in the race to quantum error correction," remarked Henrik Dreyer, managing director and scientific lead at Quantinuum's Munich office and a co-author of the study. "In this work we show the first universal gate set in a non-Abelian code, which demonstrates that fault-tolerant computations can in principle be done without resorting to magic state distillation or cultivation, which are the most expensive operations in standard quantum error correction codes.".
Why Non-Abelian Anyons Are Different.
Sources indicate that ordinary qubits encode information using two basic states, along with quantum combinations of those states. Non-Abelian anyons work in a fundamentally different way.
Recent findings suggest that these anyons do not appear as ordinary standalone particles in nature. Instead, scientists create them inside quantum circuits by entangling many conventional qubits into a collective state that behaves as though it were a new type of particle with its own unusual rules.
"The way I think about these codes is they're creating little universes -- alternative universes, but ones that reflect some of the properties of our own," Verresen said.
Industry observers note that each non-Abelian anyon carries an internal state that changes when one anyon is moved around another in a process known as braiding. The sequence of those braiding operations matters (that's what non-Abelian means), allowing information to be encoded and manipulated in ways that are unavailable to ordinary particles.
Because the information is spread across many entangled qubits rather than stored in a single location, it can also be naturally protected from some of the small disturbances that frequently disrupt conventional qubits. Braiding the anyons can also perform computational operations.
Why Braiding Alone Was Not Enough.
In 2024, a research team that included Verresen used a Quantinuum trapped-ion computer to create anyons associated with a symmetry group called D4 -- the rotations and reflections that leave a square unchanged -- demonstrating this form of non-Abelian order on quantum hardware for the first time.
That experiment indicated that the unusual particles could be created and manipulated, but braiding them alone was not sufficient to carry out every operation required for universal quantum computing.
"In that work, we didn't demonstrate that those emergent forces were enough to do quantum computation," said Verresen. "That particular universe we created was not powerful enough.".
Fusion Unlocks Universal Quantum Operations.
For the new study, the researchers switched to another symmetry known as S3 -- the rotations and mirror-image flips that leave an equilateral triangle unchanged -- and created the corresponding anyons on Quantinuum's H2 trapped-ion processor using 54 entangled qubits.
The S3 system had the properties needed for universal quantum computation, but only when braiding was combined with another operation called fusion. During fusion, two anyons are brought together and the resulting state is measured.
The underlying concept was proposed theoretically in 2003 by Carlos Mochon, then a student of John Preskill at Caltech. Turning that theoretical idea into an experiment that could actually run on quantum hardware, however, required extensive additional theoretical and experimental work.
The researchers used pairs of anyons to encode "topological qutrits" which store three possible levels of quantum information instead of the two levels used by ordinary qubits.
By combining different braiding and fusion operations, the team demonstrated three key tools: one entangling gate produced through braiding and two different measurements created through fusion. Together, those operations can in principle produce any quantum operation, including operations that braiding alone could not achieve.
Beyond their possible computing applications, these unusual quantum states could also help researchers investigate fundamental aspects of physics.
"It is gratifying to see ideas we have spent our PhD work thinking about realized in the lab, and it has been made possible by remarkable advances in quantum hardware over the past few years," stated Anasuya Lyons and Chiu Fan Bowen Lo, graduate students at Harvard University in the group of Ashvin Vishwanath who helped lead the work.
Toward Fault-Tolerant Quantum Computers.
The researchers also demonstrated that non-Abelian anyons could directly produce a magic state using topological operations -- sidestepping the costly distillation process used in most quantum systems.
The experiment did not yet include active error correction. Instead, the researchers focused on testing the individual building blocks of the method and confirming that they could create a magic state consistent with theoretical expectations.
According to recent reports, "So far, we've ignored the question of error correction. Here, it's more like a proof of principle," Verresen mentioned.
In a recent development, the next major step will be combining these operations with active error correction. If that can be achieved, non-Abelian anyons could eventually become a practical basis for large-scale, fault-tolerant quantum computers. Verresen is already working with other PME researchers on new techniques for stabilizing non-Abelian quantum memories.
According to recent reports, materials provided by University of Chicago. Original written by Sarah C.P. Williams. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #23072. Computing Effective Dimension for Quantum ML Models in PyTorch 📰 #18333. Catching rogue agents and preventing cyberattacks—quantum computing is about to have its ‘ChatGPT moment’ 📰 #17714. The upcoming BMW i3 just proved how efficient an EV can be after a nearly 3,700-mile road trip
Hardware & Chips
📈 Bullish
🌐 Eurogamer
#11362. Latest Update: Tell us your favourite Grand Theft Auto gaming memory and win a copy of GTA 6
📅 13 Nov 2026 • ⏱️ 3m • 📚 Deep Dive (615 w)
Latest Update: Tell us your favourite Grand Theft Auto gaming memory and win a copy of GTA 6
📅 13 Nov 2026 | ⏱️ 3 min read (615 words, 📚 Deep Dive) | Source: Eurogamer
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- This piece is part of our GTA Week coverage here on Eurogamer, as we explore all things Grand Theft Auto across the launch period of the wildly anticipated Grand Theft Auto 6.
- Sources indicate that these are my favourite competitions to run on Eurogamer, so I'm glad to be able to announce a newly introduced one.
- It has been revealed that I love these competitions because they result in hundreds of funny, heartwarming and often poignant stories about playing games.
Hello! This piece is part of our GTA Week coverage here on Eurogamer, as we explore all things Grand Theft Auto across the launch period of the wildly anticipated Grand Theft Auto 6. For more like this, see our GTA Week hub - or for the exact opposite, look out for our Not-GTA week of counterprogramming, running from 23rd November.
Sources indicate that these are my favourite competitions to run on Eurogamer, so I'm glad to be able to announce a newly introduced one. We'd like you to share your favourite gaming memory related to playing a Grand Theft Auto game - any Grand Theft Auto game - in the comments below, and if we end up liking yours the most, we'll give you a copy of GTA 6.
It has been revealed that I love these competitions because they result in hundreds of funny, heartwarming and often poignant stories about playing games. We've done similar memory-offs for other major gaming franchises in the past: Street Fighter, The Legend of Zelda, Star Wars. We did one about Christmas. We even did one about Eurogamer for our 25th birthday. So it's only right that we do one for arguably the biggest franchise in video games: Grand Theft Auto.
I'll let this run over the weekend and put a deadline of Monday, 16th November at noon UK time on entries. I'll comb through replies early next week in the interest of selecting a winner and giving them - you? - a copy of the game before (or as) GTA 6 releases next Thursday. I notify people using the email address associated with their Eurogamer commenting account, and reply in the comments as well, making it explicitly clear if you've won. Please keep an eye on this thread and your inbox because if I don't hear back, I'll offer the prize elsewhere.
It has been revealed that with that said, let's talk memories! I have a couple when it comes to Grand Theft Auto. My earliest memory is of a teenage me playing the first GTA at a friend's house. In a convoluted 90s way, one friend had taken their PC to another friend's house, where the three of us had assembled to play it. We'd take it in turns to burn around the top-down city, and when we weren't at the controls, we'd still be active in the experience, with the huge paper map unfolded, looking for spray shops the player could nip into when chased by the police. It was like being the passenger in a car. I can picture now, almost 30 years later, vividly.
The other distinct GTA memory I have is of playing Vice City and San Andreas one summer after I'd broken my arm and leg. I jumped off a roof in Australia when I was drunk; I wouldn't recommend it. Anyway, upon returning home, there wasn't a lot I could do - the breaks were both on one side so I'd crutch around (they gave me a wooden crutch in Australia) like a pirate - so a friend and I spent that summer taking turns playing GTA. It's all those shared moments laughing at Tommy Vercetti driving up staircases on vintage scooters that I remember, or CJ flapping his wooden-block hands around like paddles while gesticulating in cutscenes. Us just messing around. Friendship. That's what remembering Vice City and San Andreas conjures for me.
Industry observers note that but what about you - what do you remember about playing GTA games? Let your mind wander, let your mind remember, and thank you in advance for sharing your stories with us and everyone else. Have a lovely weekend.
🔗 Related Articles
📰 #23621. Industry News: Grand Theft Auto: San Andreas is GTA 5 without the finesse - so why is the 2004 classic such a strange delight to return to? 📰 #18366. 10 Grand Theft Auto milestones, from a Scottish studio's 1997 original to GTA 6 📰 #16660. Get your hands on Grand Theft Auto 6 for free over on GTA 6 Bible
General
⚖️ Neutral
🌐 Sitepoint
#11361. Breaking: How to Build an Accessible Gold Value Calculator in Vanilla JavaScript
📅 10 Nov 2026 • ⏱️ 6m • 📚 Deep Dive (1250 w)
Breaking: How to Build an Accessible Gold Value Calculator in Vanilla JavaScript
📅 10 Nov 2026 | ⏱️ 6 min read (1250 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- Ask anyone selling an old chain or a broken ring what they want to know, and it's one thing: what is this worth?
- According to recent reports, in this tutorial, we'll build a gold value calculator that gets those details right.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Weekly. Free. One click to leave.
7 Day Free Trial. Cancel Anytime.
Ask anyone selling an old chain or a broken ring what they want to know, and it's one thing: what is this worth? A small calculator can answer that in a second, but most of the ones you find online get the details wrong. They ignore troy ounces, treat 14K as 58.5% one day and 58.3% the next, or show a "value" that no buyer will ever pay.
According to recent reports, in this tutorial, we'll build a gold value calculator that gets those details right. It runs on plain HTML and JavaScript, updates as the user types, works with a screen reader, keeps its state in a shareable URL and pulls a live spot price through a small Node.js endpoint. The calculation lives in one pure function, so we can test it in a few lines.
Every gold calculator comes down to three inputs: how much the item weighs, how much of that weight is actually gold, and what pure gold is trading for today.
Purity is measured in karats, out of 24. A 14K ring is 14 parts gold and 10 parts other metals, so it's 14 ÷ 24 = 58.3% gold. You'll also see 14K stamped as "585", which is the hallmark many manufacturers use for the same alloy. For a calculator, the karat fraction is the safer default:.
According to recent reports, the second detail most tutorials miss is the unit. Gold spot prices are quoted in USD per troy ounce, which is 31.1035 grams, not the 28.35-gram ounce on a kitchen scale. Jewelers also use pennyweight (dwt), which is 1.5552 grams. If your calculator multiplies grams by a per-ounce price without converting, every result is wrong by a factor of 31.
Put together, the formula looks like this:.
For example, with gold at $2,400 per troy ounce, 10 grams of 14K gold contains 5.83 grams of pure gold, which is worth $449.85 at melt.
That $449.85 is the value of the gold content alone. Refiners and buyers pay a percentage of it, because refining, assaying and handling cost money. Depending on the buyer, the item and the market, the payout can sit well below melt value.
That gap is why good production tools separate the two numbers. A dedicated scrap jewelry gold calculator, like the one The Alloy Market offers, lets sellers estimate what their gold is worth from its weight and karat before they send anything in. Our calculator does the same job with a payout field: leave it at 100% to see melt value, or enter a buyer's rate to see a realistic offer.
Start with real form controls and a visible for each one. Placeholder text is not a label: it disappears as soon as the user types, and screen readers handle it inconsistently. The W3C forms tutorial covers the rules in detail.
A few choices here matter more than they look:.
Recent findings suggest that A little CSS gives touch-friendly controls. Keeping inputs at 16px (1rem) also stops iOS Safari from zooming in when a field gets focus.
It has been revealed that the biggest problem with most calculator snippets is that the math is buried inside an event handler, mixed with getElementById calls. You can't test it, and you can't reuse it on a server. Put the calculation and validation in their own module instead:.
Both functions take plain values and return plain values. They don't know a DOM exists, which means the same file can run in the browser, in Node.js and in your test runner.
Industry observers note that notice that we don't round inside the calculation. Rounding happens once, at display time. Rounding in the middle of a chain of multiplications is a classic way to end up a few cents off.
Industry observers note that now connect the form to the module. Listening for the input event on the form itself catches changes from every field, including the dropdowns, so there's no need to wire up each control separately.
With the markup, CSS and script in place, here's the finished calculator showing our 10 g, 14K example with an 80% buyer payout:.
Here's what this code is doing:.
It has been revealed that asking people to type the spot price works, but prefilling it is friendlier. Don't call a metals price API straight from the browser, though. Your API key would be visible to anyone who opens DevTools, and every visitor would spend one of your API calls.
Recent findings suggest that instead, put a small endpoint in front of your price provider and cache the result. This example uses Express and the fetch built into Node.js 18 and later:.
Three things keep this endpoint dependable:.
It has been revealed that on the page, the loadSpot() function from Step 3 fills the field and shows the time of the price. The field stays editable, so a seller who has a quote from a specific buyer can type that instead.
It has been revealed that A seller comparing offers might want to send their numbers to a family member, or come back to them tomorrow. Because every input has a name, turning the form into a query string is one line with URLSearchParams.
Industry observers note that the syncUrl() function in Step 3 runs on every change and uses history.replaceState instead of pushState, so typing doesn't fill the back button with dozens of entries. On load, restoreFromUrl() puts the values back. A link like this opens with the form already filled in:.
Industry observers note that this is also the progressive enhancement story. If JavaScript fails to load, the form still submits as a GET request. Your server can read the same parameters, import the same gold.js and render the result in HTML.
It has been revealed that because goldValue() is a pure function, testing it needs no browser and no mocks. Node.js ships with a built-in test runner, so there's nothing to install:.
Run it with node --test. (Add "type": "module" to your package.json so Node treats the files as ES modules.) The troy ounce test is the one worth keeping forever: if anyone "simplifies" the conversion later, it fails immediately.
A quick checklist for putting this calculator on a real store:.
A gold calculator looks like a ten-line script, but the details are what make it useful: converting troy ounces properly, separating melt value from payout, keeping the math testable and making the result accessible and shareable. The same pattern of a pure calculation module, a thin DOM layer and a cached server endpoint works for any calculator where the price depends on several inputs, from shipping estimates to currency conversion.
Recent findings suggest that mathematically, 14K is 14 ÷ 24 = 58.3%. Many manufacturers stamp 14K jewelry "585" and alloy it to that standard, so both numbers are common. Pick one, state it in the dropdown, and use it consistently.
In a recent development, let the user choose. Most people weigh jewelry in grams, but spot prices are quoted per troy ounce, so the calculator should accept either and convert internally.
Yes. Drop Step 4 and let customers type the spot price, or have a scheduled job write the current price into a static JSON file. Everything else runs entirely in the browser.
It has been revealed that 7 Day Free Trial. Cancel Anytime.

General
⚖️ Neutral
🌐 Dexerto
#11360. Students hospitalized after muffins with batteries in them served at school bake sale
📅 16 Nov 2026 • ⏱️ 2m • 📖 Standard (376 w)
Students hospitalized after muffins with batteries in them served at school bake sale
📅 16 Nov 2026 | ⏱️ 2 min read (376 words, 📖 Standard) | Source: Dexerto
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- If you thought raisins in muffins were bad, you haven’t seen anything yet.
- The incident occurred on November 12 at Fröbel Elementary School in Coswig, where a student had brought homemade muffins to sell during a school event.
- According to German broadcaster MDR, two students discovered small objects inside their muffins while eating them.
If you thought raisins in muffins were bad, you haven’t seen anything yet. Sixteen students were hospitalized after muffins containing small batteries were served at an elementary school bake sale in Germany, sparking a massive emergency response.
The incident occurred on November 12 at Fröbel Elementary School in Coswig, where a student had brought homemade muffins to sell during a school event.
According to German broadcaster MDR, two students discovered small objects inside their muffins while eating them.
The objects were identified as button-cell batteries, prompting fears that other children might have unknowingly swallowed them.
Police subsequently recovered three batteries from two muffins, while 16 students who had eaten the baked goods were sent to nearby hospitals as a precaution.
According to an official statement from Wittenberg district authorities, at least 35 emergency responders and 12 ambulances were dispatched to the school.
However, just one child was transported to the hospital by ambulance, while the remaining 15 were taken by their parents or other private transportation.
Fortunately, none of the students suffered injuries, and medical examinations confirmed that no batteries had been swallowed.
Ten students treated at Dessau Municipal Hospital were even given free ice cream following their examinations.
As for how the batteries ended up inside the muffins, police believe they were accidentally mixed into the batter during preparation.
Recent findings suggest that investigators mentioned witness accounts supported the explanation and found no evidence of deliberate wrongdoing. In other words, the school didn’t do muffin.
School sued for $1 million after students served pretzels with oven cleaner as seasoning.
Hackers turn supermarket fridges up to 122 degrees forcing stores to throw away food.
School apologizes after students accidentally fed dirt at charity event.
The incident did, however, raise serious concerns because swallowing button-cell batteries can cause potentially life-threatening internal burns, particularly if they become lodged in the esophagus.
It comes just weeks after a school in Oregon was sued for nearly $1 million after students were served pretzels seasoned with crushed oven cleaner.
Earlier in 2026, another school apologized after accidentally serving students baked dirt that had been prepared for a science experiment.
In the German muffin incident, police confirmed that all 16 children had returned home safely by November 13.
General
⚖️ Neutral
🌐 Eurogamer
#11359. What we've been playing - "Whether he means to or not, he serves sass all over town"
📅 14 Nov 2026 • ⏱️ 4m • 📚 Deep Dive (720 w)
What we've been playing - "Whether he means to or not, he serves sass all over town"
📅 14 Nov 2026 | ⏱️ 4 min read (720 words, 📚 Deep Dive) | Source: Eurogamer
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that another week has climaxed and I'm so sorry you had to read that on a Saturday morning.
- But enough about us, what about you?
- Sources indicate that my favourite thing so far about Ocarina of Time is the judgement plastered on little Link's face when he encounters, well, almost everyone.
Sources indicate that another week has climaxed and I'm so sorry you had to read that on a Saturday morning. But here we are again, with our regular feature, where we talk about what we've been playing in order that you do too. This week, Marie has been staring at monster butts; Connor has capitulated to World of Warcraft; Kelsey is discovering the joys of a beloved Zelda game for the first time; and Bertie enjoys someone being punched in the face, because I guess he's that sort of person?
But enough about us, what about you? What have you been playing this week? Do tell all! And don't forget we have an entire archive of previous What We've Been Playings for your leisurely perusal, just in case you forgot what you were playing a year or a month or a week ago. And now onward!
Sources indicate that my favourite thing so far about Ocarina of Time is the judgement plastered on little Link's face when he encounters, well, almost everyone. Whether he means to or not, he serves sass all over town, and in Kakariko Village, and I am very much here for it.
In a recent development, also, I wasn't prepared to come face-to-face with a monster's butt cheeks. At all. Imagine the scene: I'm enjoying the tunes of the Lost Woods, processing the changes that have happened to Hyrule in the last seven years, all while making my way to the Forest Temple. Then the Moblin's turn their backs to reveal... Well, everything.
Industry observers note that this week I've spent an ungodly amount of time playing World of Warcraft: Forever (you may have read my preview on the website) and have been essentially glued to it during every minute of free time I've had away from work. I've got both my main professions above the level 225 mark and I'm firmly in the thick of it now. Levels take longer, items are actually getting good, and I've had to make a second alt character for extra bank space.
Sources indicate that as a result, I've not been to the gym in a while. I actually got one of those emails asking why I've fallen off, offering some tips to get back into the routine. Sorry Nuffield Health, my sleep schedule is ruined and I've substituted proper workouts for squats and basic at-home cardio. Surely, this can't go wrong...
I don't have the same level of nostalgia for Ocarina of Time that my peers do, but that has not stopped me from enjoying every minute of running around Hyrule smashing pots and trying not to cry over the touching cutscenes and, well, Saria.
In a recent development, the game feels like Dark Souls for children (endearing) and that is completely my jam. It's magical, satisfying, and often sad. There's creepy enemies as well as cute ones, trap floors and doors, mysterious NPCs... and my heart just feels so warm whenever I'm playing it. My fingers are now crossed that there's a Majora's Mask remake in the pipeline over at Nintendo. (As well as a Super Mario 64 remake, which I admit, is pushing it. But for what it’s worth, I'd probably sell my soul to see it get the Ocarina treatment.).
It takes me a while to settle with games; it takes me a while to settle full stop. I suppose in Fire Emblem's case I'm out of touch, seeing as the last instalment I played was on 3DS. But I struggled with the garish enthusiasm early on and the whole thing seemed overly simple. Nevertheless, I've settled a bit now, and now that the game's layering on more strategy and Intelligent System's expertise is coming to the fore, I'm beginning to enjoy myself much more.
In a recent development, I wasn't expecting it to be quite so boobsy, though. Was Fire Emblem always this way? Perhaps it's my fault for picking the scantily clad queen Theodora, though that sort of presentation isn't reserved only for her. She's no wallflower, though. My favourite moment so far was when she got off her elephant during a parade - yes, her elephant - and walked over to punch a teenage boy in the face for halting proceedings. Apparently she was doing him a favour.
🔗 Related Articles
📰 #14459. Maldini admits career could’ve been different without father and Liedholm: “Liked playing goalkeeper” 📰 #11387. Industry News: What we've been playing - "Sniffing out the warehouses on Prawn Island" 📰 #23582. Breaking: The Moat Isn't The Agentic Data; It's Knowing What The Data Means
AI & Tech
⚖️ Neutral
🌐 9to5google
#11358. Samsung’s paid Galaxy AI plan has a giant Gemini problem
📅 10 Nov 2026 • ⏱️ 8m • 📚 Deep Dive (1518 w)
Samsung’s paid Galaxy AI plan has a giant Gemini problem
📅 10 Nov 2026 | ⏱️ 8 min read (1518 words, 📚 Deep Dive) | Source: 9to5google
⏱️ ~8 mins left to finish
📖 0% read
💡 Key Takeaways
- Today I’m trying desperately not to buy Sony’s fresh nostalgia-bait headphones, reeling from how emotionally invested I was in Spider-Man: Brand New Day (yes, I know I’m late), trying to figure out what a “private, agentic notebook” is, and slowly coming around to the idea of the New York Times owning Letterboxd.
- Recent findings suggest that inbox is written by Daniel Bader.
- According to recent reports, the relationship between Samsung and Google has, over the years, waxed and waned depending on their respective interdependence.
Good morning. Today I’m trying desperately not to buy Sony’s fresh nostalgia-bait headphones, reeling from how emotionally invested I was in Spider-Man: Brand New Day (yes, I know I’m late), trying to figure out what a “private, agentic notebook” is, and slowly coming around to the idea of the New York Times owning Letterboxd.
Recent findings suggest that inbox is written by Daniel Bader. Read previous issues here, and then catch up with Ben Schoon’s excellent Weekender column published every Sunday.
According to recent reports, the relationship between Samsung and Google has, over the years, waxed and waned depending on their respective interdependence. Samsung is Android’s physical emissary, powering a plurality of all its handsets globally. But Google, and in particular its services, is the glue that holds Samsung’s smartphone experience together.
It has been revealed that the back and forth is over a decade old; back in early 2014, Samsung shipped a refreshed magazine-style skin with its Galaxy tablets that eschewed many of the design tenets Google had been pushing its partners to adhere to. Not only was Samsung willfully defying its most important partner, but it made a point of barely mentioning Android during its press conferences.
Around the same time, it transitioned its smartwatches from Android Wear to Tizen and began shipping duplicative apps on its devices (many of which persist to this day). The goal was to distance itself from Google as much as possible.
While we don’t know exactly what happened behind closed doors, we saw the outcome quite clearly: Magazine UX lasted one product cycle, and the two companies signed a 10-year cross-license patent deal, which may have helped Samsung prevent any future lawsuits with Apple. Google then sold Motorola to Lenovo, clearing the way for Samsung to continue building its burgeoning hardware business on the back of Google’s mobile ecosystem.
Since then, the two companies have grown even closer. In 2021, they co-confirmed a upcoming Wear OS along with an overarching wearables partnership that has since grown to include Android XR as well. And Google is still the default search engine for Samsung devices, despite reported inroads made by Microsoft in 2023 to convince the Korean giant to switch to a ChatGPT-powered version of Bing Search. (Samsung’s ongoing relationship with Microsoft, which bundles its Office suite on most Galaxy devices, could be seen as a point of leverage for negotiations with Google, too.).
Sources indicate that this brings us to today, and to AI. Samsung was among the first companies to adopt Google’s full suite of Gemini Intelligence products, and its phones often get new AI features before anyone else. But like a decade ago, when Samsung shipped Bixby to kind-of-sort-of compete with Google Assistant, it still wants to offer its own services alongside Google’s.
So a rumor that Samsung may launch a paid Galaxy AI Premium subscription next year for $5/month piqued my interest for the same reason Magazine UX did 12 years ago. Galaxy AI features today are a blend of first-party and third-party capabilities, but none of them are especially useful, particularly when compared to Google’s own Android equivalents powered by Gemini Intelligence. Now Bar and Now Brief, two heavily promoted features in Samsung’s marketing, are wildly disappointing.
Sources indicate that at I/O this past May, Google announced Spark, an agent that goes out and performs actions on your behalf. And while it’s since been somewhat eclipsed by more capable mobile options like Meta’s Muse, it’s obvious that Google is working on a follow-up that will perform functions both on the phone and inside apps.
That’s exactly what Samsung is rumored to be working on with Bixby Action, a spiritual successor to its namesake that, when it debuted, prioritized on-device tasks like turning on Wi-Fi over web-based actions Google Assistant did better.
According to leaks from SamMobile, Galaxy AI Premium will offer agentic upgrades for phone users to “create commands triggers and system routines for daily tasks” or “automate routine daily tasks using Galaxy AI.” Gen Video will reportedly “convert static photos into dynamic video clips,” while a fresh Daily Briefing likely does what it indicates on the tin.
Will Samsung users see enough value in this hodgepodge of features paywalled only because they use a surfeit of compute? And what models will power them on the backend?
Right now, Google is in the enviable position of being able to offer its AI at three distinct layers: the model itself, which is invisible to the user; the OS level, which can promulgate Gemini across every Android phone that runs Google services; and the hardware level, where Pixel lets it specialize and optimize.
In a recent development, samsung, not particularly known for its software prowess, will likely need to step gingerly around Google’s AI shadow while also justifying the cost to shore up its much-needed services revenue. Based on this leaked roadmap, though, I’m not confident it will work out.
It has been revealed that instead, Samsung may want to acquire one of the many up-and-coming AI agent startups whose valuations are rising more quickly than their user bases. While Muse and OpenAI’s Dots have taken up most of the recent conversation, I’ve been using Hark, Town, and Instinct pretty regularly for a month or so and could see them being brought in-house by Samsung and offered either as standalone products or customized for Galaxy devices. As Google is doing with its own AI plans, Samsung could provide Galaxy consumers a year of free service, after which they would be expected to pay.
Samsung doesn’t have a great history of building software, but many of its acquisitions, from SmartThings to Viv Labs (which became “next-gen” Bixby) to LoopPay (which became Samsung Pay) to Whisk (which became Samsung Food), have proven successful. Given the current urgent state of mobile AI, I’d forgo the hodgepodge and bring in some outside expertise.
Industry observers note that jensen Huang’s affair with an alleged Chinese spy is the only thing tech media can talk about right now, likely because it has implications far beyond just Nvidia’s stock price. The Nvidia CEO, who is one of the world’s richest and most powerful tech executives, is believed to have been targeted by Chinese intelligence to potentially influence American trade policy around AI.
Alex Kantrowitz’s Major Technology piece is a useful starting point for why this matters at a global scale:.
It has been revealed that beyond the affair, the real problem is that Huang’s love interest, ex-Megaspeed International executive Alice Huang, is someone the United States government believes passed information to the Chinese government while building data centers with Nvidia’s help in Asia. There’s simply no getting away from this detail. This isn’t just an affair, it’s a corporate and national security issue.
Whether Huang can survive the impending investigation by Nvidia’s board remains to be seen, but the CEO has been a stalwart in the tech space for 33 years, and there is no clear successor to his position should he be forced to resign.
Damien reviewed DroidDeck, which I wrote about last week as part of a broader look at Android’s gaming renaissance.
Over the last few days, things have become even more preposterous: the Ocarina of Time remake, which was released on Thursday, has already been recompiled to run natively on Android (though it runs better on PC), largely with the help of frontier AI models.
All of these AI-powered shenanigans come after Anthropic said it would stop making it possible to recreate copies of games, claiming that “recreating someone else’s specific game using Claude to infringe IP is against our usage policy.” Good thing there are no other models capable of doing the same thing.
I think when you zoom out and look at production, AI really has the potential to be the biggest creative unlock in modern history. The last time we saw anything close to this was really the, you know, advent of CGI and digital composites in the early ’90s. That technology gave birth to amazing stories like Jurassic Park and Terminator 2, and it’s hard to imagine that AI is not going to have a more significant impact than that. And I personally believe that’s going to be an incredible unlock on creativity.
—David Ellison, Skydance CEO, when asked about how AI could impact the movie-making process.
Recent findings suggest that you can also support us by becoming a 9to5Google Pro member, starting at just $5/month. You get bonus podcast episodes, access to our members-only Discord server, and lots more.
According to recent reports, thanks for reading, and have a great day. I’ll talk to you on Thursday.
It has been revealed that FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Inbox by 9to5Google is a twice-weekly newsletter….
In a recent development, daniel is a writer, editor, podcaster and analyst covering the substantial stories, small milestones, and amazing people behind tech’s biggest moments. He was previously editor-in-chief of MobileSyrup, Android Central, and Android Police, and has been a content director of tech publications since 2010.

General
⚖️ Neutral
🌐 Hugging Face
#11357. Introducing Waypoint-1: Real-time interactive video diffusion from Overworld
📅 20 Jan 2026 • ⏱️ 3m • 📚 Deep Dive (564 w)
Introducing Waypoint-1: Real-time interactive video diffusion from Overworld
📅 20 Jan 2026 | ⏱️ 3 min read (564 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Waypoint-1 is Overworld’s real-time-interactive video diffusion model, controllable and prompted via text, mouse, and keyboard.
- The backbone of the model is a frame-causal rectified flow transformer trained on 10,000 hours of diverse video game footage paired with control inputs and text captions.
- In a recent development, the standard among existing world models has become taking pre-trained video models and fine-tuning them with brief and simplified control inputs.
Overworld Stream: https://overworld.stream.
Waypoint-1 is Overworld’s real-time-interactive video diffusion model, controllable and prompted via text, mouse, and keyboard. You can give the model some frames, run the model, and have it create a world you can step into and interact with.
The backbone of the model is a frame-causal rectified flow transformer trained on 10,000 hours of diverse video game footage paired with control inputs and text captions. Waypoint-1 is a latent model, meaning that it is trained on compressed frames.
In a recent development, the standard among existing world models has become taking pre-trained video models and fine-tuning them with brief and simplified control inputs. In contrast, Waypoint-1 is trained from the get-go with a focus on interactive experiences. With other models, controls are simple: you can move and rotate the camera once every few frames, with severe latency challenges. With Waypoint-1 you are not limited at all as far as controls are concerned. You can move the camera freely with the mouse, and input any key on the keyboard, and all this with zero latency. Each frame is generated with your controls as context. Additionally, the model runs fast enough to provide a seamless experience even on consumer hardware.
Sources indicate that waypoint-1 was pre-trained via diffusion forcing, a technique with which the model learns to denoise future frames given past frames. A causal attention mask is applied such that a token in any given frame can only attend to tokens in its own frame, or past frames, but not future frames. Each frame is noised randomly, and as such the model learns to denoise each frame separately. During inference, you can then denoise fresh frames one at a time, allowing you to generate a procedural stream of new frames.
Sources indicate that while diffusion forcing presents a strong baseline, randomly noising all frames is misaligned with a frame-by-frame autoregressive rollout. This inference mismatch results in error accumulation, and noisy long rollouts. To address this problem we post-train with self forcing, a technique that trains the model to produce realistic outputs under a regime which matches inference behavior. Self-forcing via DMD has the added benefit of one-pass CFG, and few-step denoising.
WorldEngine is Overworld’s high‑performance inference library for interactive world model streaming. It provides the core tooling for building inference applications in pure Python, optimized for low latency, high throughput, extensibility, and developer simplicity. The runtime loop is designed for interactivity: it consumes context frame images, keyboard/mouse inputs, and text, and outputs image frames for real‑time streaming.
On Waypoint‑1‑Small (2.3B) running on a 5090, WorldEngine sustains ~30,000 token‑passes/sec (single denoising pass; 256 tokens per frame) and achieves 30 FPS at 4 steps or 60 FPS at 2 steps.
Performance comes from four targeted optimizations:.
We’re running a world_engine hackathon on 1/20/2026 - You can RSVP here. Teams of 2-4 are welcome and the prize is a 5090 GPU on the spot. We’d love to see what you can come up with to extend the world_engine and it should be a great event to meet like-minded founders, engineers, hackers and investors. We hope you can join us at 10am PST on January 20th for 8 hours of friendly competition!
Is this the first open source world model?
good model, i understand it's very difficult to train diffusion model.
It has been revealed that very Exciting! Nice work, team! 💪💎.
🔗 Related Articles
📰 #11655. Hugging Face and Cloudflare Partner to Make Real-Time Speech and Video Seamless with FastRTC 📰 #23552. Magic: The Gathering is getting a Netflix animated series — for real this time 📰 #23513. Latest Update: Introducing Modular Diffusers - Composable Building Blocks for Diffusion Pipelines
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11356. This light-powered AI can spot deepfakes with nearly 98% accuracy
📅 01 Oct 2026 • ⏱️ 6m • 📚 Deep Dive (1117 w)
This light-powered AI can spot deepfakes with nearly 98% accuracy
📅 01 Oct 2026 | ⏱️ 6 min read (1117 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- According to recent reports, researchers at the University of California, Los Angeles (UCLA) have created a latest optical-neural processor that uses light to help identify deepfake videos rapidly and accurately.
- Industry observers note that the key difference is that part of the detection process takes place through the physical propagation of light.
- In a recent development, the technology is detailed in the study "Scalable, Energy-Efficient Optical-Neural Architecture for Multiplexed Deepfake Video Detection," published in eLight.
According to recent reports, researchers at the University of California, Los Angeles (UCLA) have created a latest optical-neural processor that uses light to help identify deepfake videos rapidly and accurately. Unlike conventional systems that typically examine videos one after another using digital hardware, the UCLA technology can analyze 15 or more video streams at the same time.
Industry observers note that the key difference is that part of the detection process takes place through the physical propagation of light. This allows many videos to be evaluated simultaneously during a single optical pass rather than requiring each one to move separately through a conventional digital processing pipeline.
In a recent development, the technology is detailed in the study "Scalable, Energy-Efficient Optical-Neural Architecture for Multiplexed Deepfake Video Detection," published in eLight. The researchers designed the optical AI system to serve as a high-throughput, attack-resilient first layer of defense for screening large amounts of manipulated and AI-generated video.
The Growing Challenge of Deepfake Detection.
Rapid improvements in generative AI have made synthetic videos increasingly realistic, increasing the need for detection systems that are both accurate and capable of operating at large scale.
In a recent development, many advanced deepfake detectors depend on enormous amounts of digital computation. A single analysis can require hundreds of billions of floating-point operations, and videos are often processed sequentially. As more content must be checked, both the processing time and energy requirements can rise proportionally.
Digital detection systems face another problem. Attackers can deliberately alter fake videos in subtle ways designed to confuse a detector and make manipulated footage appear authentic.
Professor Aydogan Ozcan and his UCLA team developed a hybrid digital-optical system intended to address both challenges.
According to recent reports, A lightweight digital encoder first collects compact information about each video, including spatial, spectral, and temporal features. That information is transformed into a phase pattern and displayed on a programmable spatial light modulator.
The resulting optical wavefront then travels through a free-space-based, passive optical decoder. At the other end, paired optical detectors directly produce an authenticity score for each video.
In effect, the system replaces a computationally demanding digital decoding network with a physical process that can handle many streams in parallel.
Nearly 98% Accuracy Across 15 Videos at Once.
In experiments using visible light, the processor examined 15 Celeb-DF videos simultaneously during each optical pass.
According to recent reports, it achieved an average detection accuracy of 97.79%, along with a sensitivity of 99.86% and a specificity of 95.72%. Sensitivity measures how successfully the system identifies manipulated videos, making the particularly high sensitivity notable for a screening tool designed to keep fake content from slipping through.
According to recent reports, the 99.86% sensitivity translated to an average false-negative rate of ~0.14%. In other words, only a very small fraction of manipulated videos were incorrectly classified as authentic.
The researchers also pushed the system further by increasing its capacity to 18 videos in a single optical pass. Even at that level, average detection accuracy remained at 96.13%.
More Optical Layers Boost Performance.
The team found that the processor could also become more capable by increasing the physical depth of its passive optical decoder without substantially increasing energy use or inference latency.
When researchers added two optimized passive diffractive layers while testing more difficult deepfake manipulations, detection accuracy improved by ~6.8%.
Sources indicate that these phase-only diffractive layers can be manufactured as passive, static optical structures/surfaces. They perform additional calculations through the diffraction of light, meaning they do not require additional electrical power while the system is performing an inference.
That approach could allow more sophisticated processing without the same energy costs that typically accompany larger digital neural networks.
Testing the System Against Google VEO-3 Videos.
According to recent reports, the researchers did not limit their experiments to conventional face swapping deepfakes. They also challenged the processor with videos produced using Google's VEO-3 model.
Newer generative AI systems can create footage that lacks many of the obvious artifacts associated with earlier deepfake technology, making them a more difficult target for detectors trained primarily on older forms of manipulation.
With only minimal fine-tuning, the optical processor achieved 94.80% accuracy and 97.61% sensitivity on previously unseen VEO-3 videos during experiments.
The results suggest that the approach could potentially adapt as generative AI technology continues to evolve.
A Deepfake Detector Designed to Be Harder to Fool.
The optical system also showed resistance to black-box adversarial attacks and provides inherent protection against white-box attacks.
Industry observers note that part of that security comes from the way the detector physically performs its calculations. Because some of the inference process takes place through diffraction, important parameters of the optical model are effectively embedded within the hardware.
It has been revealed that those parameters can be difficult for an attacker to measure, reproduce, or reverse engineer. That makes reconstructing the detector and designing carefully tailored adversarial changes that can evade it considerably more difficult.
The processor also continued working reliably when videos were affected by image noise, blur, JPEG compression, and experimental misalignments. According to the researchers, those results illustrate how optical computation could provide a more secure and dependable foundation for some artificial intelligence systems.
A First Line of Defense Against Deepfakes.
Rather than replacing sophisticated digital detectors entirely, the UCLA processor is designed to work as a highly sensitive first stage of a larger detection system.
It has been revealed that massive volumes of video could initially pass through the parallel optical processor. Content identified as suspicious could then be sent to more computationally demanding digital models for a more detailed final assessment.
Such a system could combine the strengths of both approaches. Optical processing could provide parallel operation, low decoder energy requirements, high sensitivity, resistance to adversarial attacks, and the ability to adapt to newer AI video generators, while conventional digital systems could provide deeper analysis when necessary.
The researchers say this combination could eventually be useful for large-scale content moderation, media authentication, surveillance, and other security-critical AI applications.
In a recent development, the authors of this work are Parnian Ghapandar Kashani and Dr. Shiqi Chen, who contributed equally, and Professor Aydogan Ozcan. The researchers are affiliated with the UCLA Electrical and Computer Engineering Department, the UCLA Bioengineering Department, and the California NanoSystems Institute.
Materials provided by Light Publishing Center, Changchun Institute of Optics, Fine Mechanics And Physics, CAS. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
General
⚖️ Neutral
🌐 Eurogamer
#11355. Vice City was the GTA that established Rockstar's killer formula - and 24 years on, it's still one of the best games ever made
📅 14 Nov 2026 • ⏱️ 10m • 📚 Deep Dive (2088 w)
Vice City was the GTA that established Rockstar's killer formula - and 24 years on, it's still one of the best games ever made
📅 14 Nov 2026 | ⏱️ 10 min read (2088 words, 📚 Deep Dive) | Source: Eurogamer
⏱️ ~10 mins left to finish
📖 0% read
💡 Key Takeaways
- In a recent development, "Get the limey out of here," Burt Reynolds tells the producers of GTA: Vice City during a recording session for the game, as Rockstar co-founder Dan Houser enters the studio.
- Industry observers note that I can't verify the truth of this story.
- And I'm not saying that in a pejorative way at all.
In a recent development, "Get the limey out of here," Burt Reynolds tells the producers of GTA: Vice City during a recording session for the game, as Rockstar co-founder Dan Houser enters the studio. "I'm not going to work if this limey Brit is in here!" Houser refuses to leave, so the story goes - he just came down to meet one of his heroes! - and he and Reynolds end up chest-to-chest, about to come to blows, before a studio engineer breaks up the fight.
Industry observers note that I can't verify the truth of this story. It's one of those development rumours that's been around for a long time, originally written in a book about how games conquered pop culture called "All Your Base Are Belong to Us" by Harold Goldberg. But I like to believe it's true, because in this one moment, the two crucial strands of GTA: Vice City's DNA helix together: its star power and Rockstar's arrogance.
And I'm not saying that in a pejorative way at all. I think a game of Vice City's scope - stretched to breaking with ambition, budget, and technical wizardry - couldn't exist without the ego trip of Rockstar at its highest. This is a game that (somehow!) started as a bit of DLC for GTA 3, supposedly intended to launch as a mission pack when Rockstar North figured out how to port it to PC. GTA 3 launched in October 2001, and by some miracle - and lots of crunch, no doubt - Vice City hit shelves in October 2002.
This game - a game that would come to represent everything the GTA series is, for generations to come - was put together in about a year. I'd feel pretty full of myself, too, if I was able to crank out that sort of quality in that sort of timeframe. With a development budget of approximately $5 million (massive at the time, even though it seems paltry against GTA 6's rumoured $1 billion+) and a marketing spend of $13.2 million, Vice City's budget was indicative of a series shifting toward becoming a cultural milestone - a standard bearer for video games as a whole, and as explosive and attention-grabbing as Hollywood's biggest events.
In a recent development, it's not like Rockstar needed to borrow credibility from the movie industry to inject some panache into its work, but even so, I think it's in its vortex of unbelievable Hollywood talent that Vice City really makes its mark. This was the first time Rockstar used a voiced protagonist, and by the developer's own admission, it was "a riddle" they had to solve. It didn't come easy; by making the protagonist a fullyfleshed-out character, players also had to like him - not an easy ask when he's a bonafide psychopath with a fetish for revenge like Tommy Vercetti. But Ray Liotta pulls it off without breaking a sweat. The actor has gone on record saying it was a rough gig ("You're creating a character that's not there before", he bizarrely complained in one interview), and Vice City director Navid Khonsari often moaned about the actor's unpredictable moods, so I imagine the mood in the booth wasn't great, but the result? The result is phenomenal.
Sources indicate that you shouldn't like Vercetti. He's arrogant, he's brash, he's a totem for all the worst elements of misogynistic 80s excess. And yet, because he's such a cartoon caricature of a Miami gangster, he becomes a sort of quasi-romantic figure; a mob stooge who's been set up by his old 'business associates' and by the very fabric of the American Dream. Vice City is, in a sense, a redemption story dressed in the clothes of a revenge one. Vercetti dreams of being a self-made man, of taming this upcoming frontier of unbridled capitalism and clawing back the years that were taken from him by the mob in Liberty City.
From the moment he arrives in town and a cocaine deal promptly goes south, Vercetti is on the back foot. In the opening hours of the game, he - and, of course, you by extension - work for pocket change, picking up menial jobs here and there while meeting all the freaks and strangers Vice City has to offer. There are no less than 50 story characters here, brought to life by Ray Liotta, Tom Sizemore, Luis Guzmán, Gary Busey, Danny Trejo, Debbie Harry, Danny Dyer, Philip Michael Thomas, William Fichtner, and many, many more besides.
Sources indicate that playing Vice City again in 2026, I was absolutely floored by this cast - and how well their personalities and mannerisms translate to the almost puppet-like visuals Rockstar deployed for the game. Reynolds - despite not having a good time in the booth, if the story up top is anything to go by - is a highlight; the bombast and bravado of his Avery Carrington feels like a prototype for some of the more extreme characters we meet later in the series. I think I can even see a bit of Trevor in him, you know? It's how the Housers would take a trope - say, ruthless Texan oil magnate - and amplify it to its furthest, most cartoon extreme: what does this person look like with all the guardrails off, with the heady intoxication of unlimited capital at their disposal? For Trevor, that trope is 'unhinged redneck' and the cartoonish extreme is 'without a single shred of a conscience'. You can apply the formula to just about anything in the series, and it makes sense.
For Tommy Vercetti, though, it's slightly more nuanced. He isn't just 'Scarface' with a touch more humanity - no, he's a tragic figure, betrayed by all his closest friends. In striving to take back some power and gain a little more control over his life, he ends up decapitating the local drug smuggling scene and taking over as its head. The first half of Vice City is Sisyphean; an endless, uphill slog to scrabble just enough money to get by. Then, all of a sudden, the world opens up: you're now head of a drug smuggling ring, operating out of a suspiciously Scarface-like mansion, with the city at your fingertips.
The way the game, previously tightly-coiled and a bit miserly with its freedom, now unfurls in front of you is a perfect reflection of this new-found power. Suddenly, your world isn't governed by the little mission icons on your minimap, you're not being told what to do over the phone by contacts wanting something from you. No, you're calling the shots. This is the 80s, so those that are making it substantial are making it big, and those that are failing are failing. In a breathless display of uber-capitalist Yuppie thinking, you can even buy out nearly-bankrupt businesses and run them to your liking. The strategy is two-fold: one, you gain fronts for your other illicit activities, and two, you diversify your income streams and safeguard your assets should any one element fail.
And it's here, in its glorious second half, that Vice City becomes a breezy, beautiful bit of open-world catnip that fuses gameplay and story in a way few games have done so successfully since. You can buy a strip club (where you can launder cash), the Malibu Club (which comes with an outlandish set of missions culminating in a heist), the Cherry Popper ice cream van company (a front for dealing), the boatyard (a drug smuggling base run by two excellent potheads), Sunshine Autos (a fence for stolen cars), Kaufman Cabs (headed up by an old controller played by Debbie Harry), Interglobal Studios (an adult movie production company), and the Print Works (a counterfeiting operation). The roleplaying as Vercetti takes off; you're a bigshot touring his empire, helping out here and there, meeting your crew, setting up deals. This should feel like drudgery; workaday tedium unbecoming for a legitimate businessman like yourself. But every job, every bit of flavour text and dialogue, feeds into your growing sense of power… and Vercetti's unstoppable ego.
Industry observers note that alongside these key story beats are Vice City's non-essential tasks - which feel like a precursor to the 'Strangers and Freaks' missions in later GTA and Red Dead games - including the Love Fist missions. These, I think, are the best missions in the game (I'd also like to note here that 'Jez Torrent' is an amazing name for a New Wave of British Heavy metal frontman). But it's the way these core and non-essential missions dovetail that feels so great, and where the open world of Vice City really comes into its own.
In many ways, Rockstar's work here created the blueprint for what would become the Grand Theft Auto 'formula'; galvanising cinematic setpieces with free-roam activities and meta-progression that manage to alloy player agency with this sense of perpetual, unstoppable momentum. And it's all fun, too. There are some abysmal tasks, sure - piloting RC aircraft to ruin building sites, navigating boats with the wonkiest physics you've ever seen around stunt courses, waiting 15 minutes a pop for rare cars to spawn - but generally speaking, Vice City has the fun factor.
I don't think that's something I can say of other GTA games: I think often, they're a bit bloated around the middle, padded out with baggy missions and feckless busywork to give the illusion of depth and breadth. GTA 4 is also one of the most dour and oppressive open worlds I've experienced (this is a compliment, mostly), but it's not particularly fun. GTA 5, especially the Trevor segments out in the rural counties, can get a bit one-note - why introduce us to this massive world, to the state of Los Santos, if you're going to quarantine us to the rural outskirts when we're just starting to familiarise ourselves with the city? Why put up rails in a world begging us to revel in its open-ended sandbox? The only time that happens in Vice City is at the start, and the game is better for it: 'if you want to live the Scarface fantasy, buddy, you've got to earn it'.
Sources indicate that and there's so much to love about the vibes of Vice City. The guys in shorts smoking pot on the beach; the girls in bikinis rollerblading down the promenade; the neon-drenched slick of a Florida night in the rain; the still-unbelievable who's who of music, deployed with panache in certain cutscenes; the incidental chatter of coked-up presenters on the radio; the distinct realisation of the Haitian and Cuban districts on the map; how 'downtown' actually feels like downtown. You'd think all this would have aged out of relevance by now - especially with GTA 5 being as lush and premium as it is - so it's a real credit to all those Rockstar employees that no doubt spent countless nights sleeping under their desks that Vice City still feels this good now, in 2026.
According to recent reports, GTA: Vice City is still one of the best games ever made, I think, and probably one of the most vital, too. Buoyed by Rockstar's ambition, and propelled to mainstream success by the strength of its cast, it represented video games coming out of their awkward teenage years and blossoming into young adults; biting off slightly more than they could chew, but cocksure and confident all at the same time.
Industry observers note that given how much of Vice City is built around the visibility and power of its cast, it's disappointing we're never going to see these characters really represented in any other GTA title again. Liotta, already unhappy about the process of recording his lines, reportedly refused to come back as Vercetti for San Andreas. And that's a real shame because - by former lead writer Dan Houser's own admission - Liotta saved his "awful writing" with his talent. The actor passed away in May 2022.
Though he balked with Reynolds, Vice City director Khonsari could usually corral the rampant ego of his Hollywood hires in the GTA studio. "If you want me to break it down to you," he’d say, "these games gross over half a billion dollars, more than all of your movies put together!" I think you can see that bravado in the spirit of Vice City, and reflected in the runaway ego of Tommy Vercetti. And I think - without that almost toxic sense of self-belief - Vice City would never have happened.
🔗 Related Articles
📰 #23674. Subway reveals Vice City sub for GTA 6, but there’s only one way to get it 📰 #16647. Original GTA 6 leaker pleads guilty to hacking Rockstar Games, years after first revealing Lucia 📰 #16484. Latest Update: 26 Years Later, The Grinch's Best Line Is Still The Greatest Christmas Movie Quote Ever
AI & Tech
⚖️ Neutral
🌐 9to5google
#11354. Meta challenges a high-priority update to prevent some glasses from getting ‘too warm’ when wet [U]
📅 10 Nov 2026 • ⏱️ 2m • 📖 Standard (425 w)
Meta challenges a high-priority update to prevent some glasses from getting ‘too warm’ when wet [U]
📅 10 Nov 2026 | ⏱️ 2 min read (425 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- The latest Meta Glasses (not Ray-Ban or Oakley-branded) may temporarily overheat if they get too wet, but a software patch is here to help prevent that.
- Industry observers note that folks using Meta Glasses in the Adventurer, Fury, Starfire, Nova, or Capri styles should open the Meta AI app on their smartphones and get their glasses updated as soon as possible.
- Meta sent out an email to all Meta Glasses owners with the tagline “Action required,” noting that this could be a potentially serious issue:.
The latest Meta Glasses (not Ray-Ban or Oakley-branded) may temporarily overheat if they get too wet, but a software patch is here to help prevent that.
Industry observers note that folks using Meta Glasses in the Adventurer, Fury, Starfire, Nova, or Capri styles should open the Meta AI app on their smartphones and get their glasses updated as soon as possible. Meta sent out an email to all Glasses owners noting that the organization has “an important software enhancement” related to performance when “excessive moisture or sweat” enters the device. Meta specifically claims this matter does not affect Ray-Ban or Oakley-branded Meta glasses.
Meta sent out an email to all Meta Glasses owners with the tagline “Action required,” noting that this could be a potentially serious issue:.
“We’ve implemented a software patch to fix a rare problem that caused a small number of Meta Glasses to get too warm when moisture entered the device. It works similarly to a phone shutting off automatically when it needs to cool down. If people experience this, they can contact Meta Customer Service for a replacement.”.
Recent findings suggest that the upcoming software revision brings your glasses to version 130, which includes a special software hook that shuts them down if they were to get too warm. Meta told me that the temperature for this threshold is quite low, and that the glasses shut off to prevent any potential challenges. The company was very specific about the wording in the statement, carefully using the word “warm” instead of “hot,” so as to avoid the stigma that comes with that term on wearable technology.
Sources indicate that while I haven’t seen any specific reports of Meta’s newest glasses models overheating, there are plenty of Reddit threads citing overheating complications on Ray-Ban Meta glasses over the years. Ironically, the one post I found related to sweat-related overheating was from a year ago on Ray-Ban Meta glasses, which this software update does not address.
To patch your glasses, follow these steps:.
Sources indicate that meta Glasses were debuted this summer as a budget-minded alternative to the firm’s Ray-Ban and Oakley-branded AI glasses. The glasses start at $299, which is substantially cheaper than the $379 Ray-Ban Meta Gen 2 or the $449 Ray-Ban Meta Gen 3 options. Meta Glasses come in several different styles, including special LISA and Kylie-branded ones, and offer identical functionality to the more expensive Ray-Ban or Oakley options.
FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
🔗 Related Articles
📰 #16048. Google has made some bold promises on privacy for glasses. While Meta’s reputation is still sordid. 📰 #23591. Disney just launched 3D movies on the Meta Quest ahead of Meta VR Glasses’ release 📰 #23544. Latest Update: I’d rather use Android XR glasses over Meta Ray-Bans for the app alone
General
⚖️ Neutral
🌐 Hugging Face
#11353. Differential Transformer V2
📅 20 Jan 2026 • ⏱️ 8m • 📚 Deep Dive (1589 w)
Differential Transformer V2
📅 20 Jan 2026 | ⏱️ 8 min read (1589 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~8 mins left to finish
📖 0% read
💡 Key Takeaways
- In a recent development, (For simplicity, we omit the batch dimension and assume that both the input and output of the following flash_attn_func are three-dimensional tensors (tokens, heads, head dimension).
- Note DIFF V2 subtracts two heads that are in the same GQA group, which means they share the same key and value.
- Full code at: unilm/Diff-Transformer/Diff-Transformer-V2 at master · microsoft/unilm In the script, h represents number of query heads, h_kv represents number of key-value heads, and d means head dimension.
Tianzhu Ye, Li Dong, Yutao Sun, Furu Wei.
Notion Link (for better readability).
We compare DIFF V2 with DIFF V1 below:.
In a recent development, (For simplicity, we omit the batch dimension and assume that both the input and output of the following flash_attn_func are three-dimensional tensors (tokens, heads, head dimension). Heads belonging to the same GQA group are arranged contiguously in the output).
Note DIFF V2 subtracts two heads that are in the same GQA group, which means they share the same key and value. This is crucial to performance. See design ablations section and Github code.
Full code at: unilm/Diff-Transformer/Diff-Transformer-V2 at master · microsoft/unilm In the script, h represents number of query heads, h_kv represents number of key-value heads, and d means head dimension. The λ\lambdaλ in DIFF V2 is projected from XXX for each token each head.
DIFF V2 doubles number of query heads while maintaining number of key value heads, and the extra dimension is reduced back to h*d after the differential operation so the WOW_OWO projection remains the same as baseline Transformer.
DIFF V2 introduces additional query heads compared to the baseline Transformer, but does not increase the number of key-value (KV) heads. Since LLM decoding is typically memory-bound, this design allows DIFF V2 to achieve decoding speeds on par with standard Transformer. Besides, since head dimension is aligned between query, key and value, there is no need for custom attention kernels for DIFF V2. In contrast, DIFF V1 can be slower during decoding because the value cache must be loaded twice, and a custom attention kernel is needed. DIFF V2 can also increase the arithmetic intensity of the attention module during decoding.
During pretraining, when using cutting-edge FlashAttention kernels on H-series and B-series GPUs, the throughput reduction introduced by DIFF V2 is negligible. For long-sequence prefilling, we recommend combining DIFF V2 with techniques such as YOCO (also used in Gemma 3n), which already reduces prefilling complexity to linear time with respect to sequence length.
An alternative perspective is to compare DIFF V2 with a Transformer that has the same query dimension 2h*d. Under this comparison, both models exhibit same attention kernel speed, while DIFF V2 has less parameters and flops in output projection.
It has been revealed that in the standard Scaled Dot-Product Attention (SDPA), let Q,K,V∈Rn×dQ, K, V \in \mathbb{R}^{n \times d}Q,K,V∈Rn×d be the queries, keys, and values. The context vector CCC is defined as:.
C=Softmax(QKTd)V=AV C = \text{Softmax}\left(\frac{QK^T}{\sqrt{d}}\right)V = AV C=Softmax(dQKT)V=AV.
Where A∈Rn×nA \in \mathbb{R}^{n \times n}A∈Rn×n is the attention weight matrix. Let's focus on a single row of CCC, denoted as ci\mathbf{c}_ici, which is a weighted sum of value vectors vj\mathbf{v}_jvj:.
ci=∑j=1naijvj \mathbf{c}_i = \sum_{j=1}^{n} a_{ij} \mathbf{v}_j ci=j=1∑naijvj.
We define the Context RMS (Root Mean Square) to represent the magnitude of this output:.
RMS(ci)=1d∥ci∥2 \text{RMS}(\mathbf{c}_i) = \sqrt{\frac{1}{d} \|\mathbf{c}_i\|^2} RMS(ci)=d1∥ci∥2.
The weights aija_{ij}aij are non-negative and sum to 1 ( ∑j=1naij=1\sum_{j=1}^{n} a_{ij} = 1∑j=1naij=1 ). Assume the value vectors vj\mathbf{v}_jvj are uncorrelated and have an RMS of 1, the Context RMS is strictly bounded in range [1n,1)[\frac{1}{\sqrt{n}},1)[n1,1) however the attention distribution changes:.
In DIFF V1 we add a per-head RMSNorm on context vectors:.
c^i=ciRMS(ci) \mathbf{\hat{c}}_i = \frac{\mathbf{c}_i}{\text{RMS}(\mathbf{c}_i)} c^i=RMS(ci)ci.
Sources indicate that if the model learns a uniform attention distribution in a head, the Context RMS is approximately 1/n1/\sqrt{n}1/n. To normalize this back to 111, RMSNorm must multiply the vector by a scale of n\sqrt{n}n. For n=8192n = 8192n=8192, n≈90.5\sqrt{n} \approx 90.5n≈90.5. This means the RMSNorm layer applies a 100x magnification to the output. In large-scale pretraining, we find this leads to massive gradients and numerical instability.
Recent findings suggest that A typical phenomenon is that when DIFF V1 is pre-trained at a large learning rate, the gradient norm experiences a larger increase compared to Transformer in the later stages, along with higher variance. In DIFF V2, after removing the per-head RMSNorm, the gradient norm scale becomes comparable to that of Transformer, and the gradient norm spike is reduced (will be discussed further below).
We adopted the per-head RMSNorm design in DIFF V1 primarily because of the doubled value head dimension and the globally shared λ\lambdaλ across all tokens. Given the modifications made to these two aspects in DIFF V2, we found that removing RMSNorm is now safe.
Recent findings suggest that we demonstrate DIFF V2 can overcome the constraint of Softmax mentioned above. It can also help eliminate attention sinks.
aij=Softmax(zij)=exp(zij)∑k=1nexp(zik)ci=∑j=1naijvj=∑j=1nSoftmax(zij)vjRMS(ci)∈[1n,1) a_{ij} = \text{Softmax}(z_{ij}) = \frac{\exp(z_{ij})}{\sum_{k=1}^{n} \exp(z_{ik})} \\ \mathbf{c}_i = \sum_{j=1}^{n} a_{ij} \mathbf{v}_j = \sum_{j=1}^{n} \text{Softmax}(z_{ij}) \mathbf{v}_j \\ \text{RMS}(\mathbf{c}_i) \in \left[\frac{1}{\sqrt{n}},1\right) aij=Softmax(zij)=∑k=1nexp(zik)exp(zij)ci=j=1∑naijvj=j=1∑nSoftmax(zij)vjRMS(ci)∈[n1,1).
ci=∑j=1n(Softmax(zij1)−sigmoid(λi)⋅Softmax(zij2))vjRMS(ci)∈(0,2) \mathbf{c}_i = \sum_{j=1}^{n} \left( \text{Softmax}(z_{ij}^\text{1}) - \text{sigmoid}(\lambda_i) \cdot \text{Softmax}(z_{ij}^\text{2}) \right) \mathbf{v}_j \\ \text{RMS}(\mathbf{c}_i) \in \left(0, \sqrt{2}\right) ci=j=1∑n(Softmax(zij1)−sigmoid(λi)⋅Softmax(zij2))vjRMS(ci)∈(0,2).
In a recent development, the projected λi\lambda_iλi helps to control the context RMS. We observe that lowering the lower bound of the context RMS to zero is particularly vital. It can help eliminate attention sinks and improve training stability. The upper bound only needs to remain bounded.
Note that our analysis here consider RMS before output projection WOW_OWO. Although the RMS can be recovered and adjusted after the output projection, the lack of freedom at Softmax still affects the learning performance.
Other recent works alleviate this constraint as well:.
aijoff=exp(zij)1+∑k=1nexp(zik) ci=∑j=1naijoffvj=∑k=1nexp(zik)1+∑k=1nexp(zik)∑j=1nSoftmax(zij)vj RMS(ci)∈(0,1) a_{ij}^{\text{off}} = \frac{\exp(z_{ij})}{1 + \sum_{k=1}^{n} \exp(z_{ik})} \\ \ \\ \mathbf{c}_i = \sum_{j=1}^{n} a_{ij}^{\text{off}} \mathbf{v}_j = \frac{\sum_{k=1}^{n} \exp(z_{ik})}{1 + \sum_{k=1}^{n} \exp(z_{ik})} \sum_{j=1}^{n} \text{Softmax}(z_{ij}) \mathbf{v}_j \\ \ \\ \text{RMS}(\mathbf{c}_i) \in \left(0, 1\right) aijoff=1+∑k=1nexp(zik)exp(zij) ci=j=1∑naijoffvj=1+∑k=1nexp(zik)∑k=1nexp(zik)j=1∑nSoftmax(zij)vj RMS(ci)∈(0,1).
aijoss=exp(zij)exp(s)+∑k=1nexp(zik) ci=∑j=1naijossvj=∑k=1nexp(zik)exp(s)+∑k=1nexp(zik)∑j=1nSoftmax(zij)vj RMS(ci)∈(0,1) a_{ij}^{\text{oss}} = \frac{\exp(z_{ij})}{\exp(s) + \sum_{k=1}^{n} \exp(z_{ik})} \\ \ \\ \mathbf{c}_i = \sum_{j=1}^{n} a_{ij}^{\text{oss}} \mathbf{v}_j = \frac{\sum_{k=1}^{n} \exp(z_{ik})}{\exp(s) + \sum_{k=1}^{n} \exp(z_{ik})} \sum_{j=1}^{n} \text{Softmax}(z_{ij}) \mathbf{v}_j \\ \ \\ \text{RMS}(\mathbf{c}_i) \in \left(0, 1\right) aijoss=exp(s)+∑k=1nexp(zik)exp(zij) ci=j=1∑naijossvj=exp(s)+∑k=1nexp(zik)∑k=1nexp(zik)j=1∑nSoftmax(zij)vj RMS(ci)∈(0,1).
ci=sigmoid(gi)⊙∑j=1nSoftmax(zij)vjRMS(ci)∈(0,1) \mathbf{c}_i = \text{sigmoid} (\mathbf{g}_i) \odot \sum_{j=1}^{n} \text{Softmax}(z_{ij}) \mathbf{v}_j \\ \text{RMS}(\mathbf{c}_i) \in \left(0, 1\right) ci=sigmoid(gi)⊙j=1∑nSoftmax(zij)vjRMS(ci)∈(0,1).
We conduct pretraining experiments on production-scale LLMs, including dense models and a 30A3 MoE on trillions of tokens using large learning rate of 6e-4 to 1e-3.
The experiments are still running. What we have observed now:.
We expect to explore in later stages of training:.
In theory, a standard Transformer with 2h2h2h attention heads can learn the differential operation by learning WO2i=−WO2i+1,i=0,1,…,h−1W_O^{2i}=-W_O^{2i+1}, i=0,1,\ldots,h-1WO2i=−WO2i+1,i=0,1,…,h−1, where WOiW_O^{i}WOi denotes the output projection of head iii, and head 2i2i2i and 2i+12i+12i+1 belong to the same GQA group.
It has been revealed that assumption 1. In practice, such a solution is difficult to learn through optimization, as it requires two sets of parameters to converge to exact negatives of each other.
Assumption 2. The differential operation can be learned by the model and the model chooses to learn it in the training. Then explicitly constructing it before the output projection as in DIFF V2 can save half of the WOW_OWO parameters. The number of saved parameters is also non-trivial. Under the current GQA setting, the parameters in the attention module are dominated by WQW_QWQ and WOW_OWO; Therefore, approximately 25% of the attention-module parameters can be saved. The saved parameter budget can then be reallocated to other parts of the model.
Even if DIFF V2, after reallocating parameters, does not achieve a lower loss than the baseline but merely matches it, the method is still worthwhile if it provides additional benefits such as improved training stability, better control of outliers, or higher training efficiency. This is analogous to GQA, which matches the loss of MHA while reducing KV-cache as an additional benefit. So the key question becomes empirical performance.
(For simplicity, we omit the batch dimension and assume that both the input and output of the following flash_attn_func are three-dimensional tensors (tokens, heads, head dimension). Heads belonging to the same GQA group are arranged contiguously in the output).
In our large learning rate setting, the ablation 1 setting exhibits obvious training instability (much more loss and gradient spikes) and higher loss comparing to DIFF V2. The value should be shared in the two subtraction heads to construct differential operation, as discussed in DIFF V1 paper.
Industry observers note that both ablation 2 and ablation 3 lead to higher language modeling loss than DIFF V2. Ablation 2 maintains training stability similar to DIFF V2, whereas ablation 3 is less stable (still more stable than ablation 1).
Ablation 4 also has higher training loss comparing to DIFF V2.
According to recent reports, this is a fascinating and thorough patch on the Differential Transformer architecture. The transition from DIFF V1 to V2 addresses some critical practical hurdles in a very elegant way.
In a recent development, the key design choice of doubling query heads within shared GQA groups is clever. It successfully decouples the innovative "differential" attention operation from the need for custom kernels, making it a much more viable drop-in replacement for standard attention. The analysis of how this design overcomes the softmax magnitude constraint and helps eliminate attention sinks is particularly convincing.
Industry observers note that the reported early results—lower loss, reduced gradient spikes, and better control of activation outliers, especially at large learning rates—are highly promising. It suggests DIFF V2 isn't just a parameter-saving trick but may offer fundamental improvements in training dynamics and stability.
I have a couple of questions out of curiosity:.
According to recent reports, long-Context Performance: You mention exploring "context rot" alleviation in later stages. Given the modified attention output dynamics, do you have any early hypotheses on whether DIFF V2 might inherently improve performance on very long sequences compared to a baseline Transformer with similar parameter budgets?
Broader Application: The principle seems powerful yet simple. Beyond the dense and MoE models tested here, do you see potential for applying this differential attention mechanism in other architectures, like state-space models or multimodal transformers?
General
⚖️ Neutral
🌐 Eurogamer
#11352. What's the best GTA?
📅 15 Nov 2026 • ⏱️ 7m • 📚 Deep Dive (1356 w)
What's the best GTA?
📅 15 Nov 2026 | ⏱️ 7 min read (1356 words, 📚 Deep Dive) | Source: Eurogamer
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- As we teeter on the brink of gaming's biggest launch of 2026 - perhaps even decade - so many questions swirl: which GTA 6 cars will make the best vrrrrm?
- According to recent reports, because I'm old, my journey with the series began all the way back in 1997, with the advent of GTA 1.
- Recent findings suggest that but is it the best GTA?
As we teeter on the brink of gaming's biggest launch of 2026 - perhaps even decade - so many questions swirl: which GTA 6 cars will make the best vrrrrm? Is it possible for me to be any more obsessed with that Justice theme song? On a scale of one to ten, how many dongs? Answers will inevitably come, but for now - as we crank up the Phil Collins and roar deeper into Eurogamer's GTA Week - there's only one question we're concerned with. Yes, it's the return of our irregular series The Major Question, in which we ponder another topical talking point before wafting it lovingly over to you. And this time around we're asking, what's the best GTA?
According to recent reports, because I'm old, my journey with the series began all the way back in 1997, with the advent of GTA 1. I still vividly remember sitting with the included paper map sprawled across my lap, wide-eyed at the top-down sandbox as my hands reckoned with the weird controls. I remember feeling dizzy at the thrill of high-speed freedom (and possibly the antiquated frame rate) as I tore across Liberty City, San Andreas, and Vice City - particularly whenever this catchy little number came on. I was never massively into those early GTAs, though, not even when the series shifted to full 3D with GTA 3. And it wasn't until Vice City's arrival in 2002, that I began to properly appreciate the series' rhythms - even though I'll readily admit I was at my happiest tearing through the streets with the radio blaring. Vice City's soundtrack, from A Flock of Seagulls to Loverboy and everything in between, is still unmatched today.
Recent findings suggest that but is it the best GTA? Vice City is certainly the GTA I've fondest memories of, even if I did mostly play it as a glorified jukebox. And as much as I've a soft spot for Chinatown Wars on Nintendo DS (a game whose propulsive style and classic top-down aesthetic did a fine job of melding GTAs old and new), Vice City is the GTA I've returned to most. But what about others on the Eurogamer team? I asked, they've answered with their own personal bests, and when they're done yammering, it's over to you - there's even a poll! And don't forget we'll be exploring the series more thoroughly as GTA Week continues.
Industry observers note that I think, even to this day, GTA: Vice City represents what I think the best Grand Theft Auto is. The vibes, even 24 years later, are immaculate: its vision of Miami in the '80's, with all its cocaine-fueled, sun-washed Yuppie excess makes for the perfect backdrop in a game that's all about freedom and fantasy. The first half of Vice City orientates you wonderfully - casting you as Ray Liotta's arrogant, low-key psychopathic Tommy Vercetti - and letting you quietly get to know the rules of this frontier of narcotic hedonism.
Then you're let loose, wide-eyed with nostrils flared, into the second half of the game: a completely open-ended experience that's all about money, moxie, and madness. Take over businesses, build the Vercetti empire, strongarm your way into Vice City's seedy underbelly in any way you see fit. Even in a more nascent form, Rockstar managed to combine open world 'side activities' with its main narrative, building on everything GTA 3 put down without losing sight of the core theme (something I think San Andreas is guilty of; that game goes off the rails by the third island, whereas I think Vice City always keeps its focus quite neat).
With Vice City, it feels like Rockstar was at the peak of its power, the excesses of its neon-soaked in-game world reflected in the developer's ambitions in the real one: Ray Liotta, Burt Reynolds, Tom Sizemore, Luis Guzmán, Gary Busey, Danny Trejo, Debbie Harry, Danny Dyer, Philip Michael Thomas, William Fichtner… that is an absolutely ridiculous cast, and - in researching the game for something else I'm writing - I have learned there was so much on-set tension between this uncontrollable star power and Rockstar's development team that Reynolds nearly had a fistfight with studio co-founder Dan Houser.
That tension, and that slightly arrogant ambition on behalf of Rockstar, manifest in the bones of Vice City. It's a game struggling against its confines, made by a developer feeling like there is nothing in the world that can stop them. I imagine GTA 6 may feel the same, so how fitting, then, that we're going back to Vice City for the pleasure of it.
Recent findings suggest that barring the original, Vice City was the GTA I played longest, so those are the cornerstones of my GTA experiences. But San Andreas left the biggest impression on me. And I think it's because it was the first game I played that really attempted to portray Black culture, albeit through a stereotyped and potentially problematic West Coast rap lens' - I don't know how well it holds up today.
According to recent reports, I was very into West Coast rap and hip-hop at the time, and the idea I could partially experience the lives which were referenced in that music so frequently - that I could live a kind of NWA origin story through the character CJ - really appealed to me, as it obviously did to many other people. It felt like I was coming straight outta Compton, as it were. It was rap tourism, which was probably totally fake and insincere to the actual experience of a life like that, but I drank it up all the same.
Fast-forward to GTA 5, which I think of as San Andreas mark two (in a similar way that I think of GTA 6 as Vice City mark two), and it's still startlingly apparent upon playing it - even now, many years after it was first released - that no other manufacturer attempts Black culture in the same way. No one even dares. And while I'm totally not the right person to evaluate how well Rockstar carries it off, it does make the GTA experience unique.
According to recent reports, back to San Andreas and I also enjoyed its ridiculous bloat: the gym sessions, the mini-games, eating burgers. It was like living a life in that sunny city, a life I couldn't live otherwise. I'm excited that some of those features are making their way back into GTA 6.
Industry observers note that I've never visited America, but I've never been more fond of any city in the world than Upcoming York. It may not have been called that in GTA 4, but it is the closest any game has got to making me realise my dream of living in and exploring the city.
Industry observers note that GTA 4's Liberty City has one of my favourite aesthetics in games: the dreary, autumnal look where the most sunshine you get is an overcast day. Perhaps Fresh York's relatively compact layout (compared to sprawling Los Angeles) is what made it possible to replicate most of its boroughs in-game, and what helped it achieve a sense of place no other GTA comes close to. I knew my way around so much of that map just by landmarks. I was surprised how much of the area around Niko's house I remember when I revisited the game five-ish years ago.
Industry observers note that I also consider GTA 4 to be the last entry in the series' classic era. Despite being the first to use Rockstar's now-standard RAGE engine, its controls were just about as loose and arcadey as its 3D predecessors. RAGE's weighty animations gave its characters and cars the look and motion of their real-life counterparts without interfering too much with how they felt to control. GTA 4 stood on the boundary of old and fresh while delivering the series' next evolution - a tough act for any sequel to follow.
So that's The Major Question, and the best - or at least our favourite - GTAs... now it's over to you!
General
⚖️ Neutral
🌐 Sciencedaily
#11351. This latest qubit could be 100 times less error-prone in superfluid quantum computer breakthrough
📅 01 Oct 2026 • ⏱️ 4m • 📚 Deep Dive (774 w)
This latest qubit could be 100 times less error-prone in superfluid quantum computer breakthrough
📅 01 Oct 2026 | ⏱️ 4 min read (774 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- Researchers at the University of Surrey have proposed a upcoming kind of qubit that could help address one of the biggest obstacles in quantum computing: keeping error rates low as systems become larger.
- The concept uses superfluid helium, a form of helium with unusual quantum properties, to create a qubit that may be less sensitive to some of the disturbances that affect today's leading quantum computers.
- It has been revealed that quantum computers rely on qubits to store and process information in ways that conventional computers cannot.
Researchers at the University of Surrey have proposed a upcoming kind of qubit that could help address one of the biggest obstacles in quantum computing: keeping error rates low as systems become larger.
The concept uses superfluid helium, a form of helium with unusual quantum properties, to create a qubit that may be less sensitive to some of the disturbances that affect today's leading quantum computers.
Why Quantum Computers Struggle With Errors.
It has been revealed that quantum computers rely on qubits to store and process information in ways that conventional computers cannot. Many current systems use superconducting circuits, but these are highly sensitive to electromagnetic noise and stray electrical charges - similar to the static electricity that can make hair cling to a balloon.
Even very small disturbances can disrupt the fragile quantum information stored in a qubit. As more qubits are added, controlling those errors becomes increasingly difficult, making scalability one of the central challenges in quantum computing.
In a study published in npj Quantum Information, researchers from Surrey's Quantum Sciences Group describe a different approach built around superfluid helium-3 - an unusual form of liquid helium that can flow without friction.
It has been revealed that their proposed device, called the Superfluid Helium Oscillator Quantum (SHOQ) device, would use charge-neutral superfluid helium. Because the helium carries no electric charge, the design could be naturally protected from certain types of electromagnetic noise.
A Qubit With Much Lower Predicted Error Rates.
According to the researchers, this is the first reported design for a qubit based on a superfluid. Their calculations suggest the SHOQ device could have error rates about 100 times lower than conventional superconducting qubits.
According to recent reports, dr. Priya Sharma, Daphne Jackson Fellow in Hybrid Quantum Systems at the University of Surrey's School of Mathematics and Physics, and lead author of the study, remarked:.
"We are not the first to think about the individual components behind this idea, but what we have done for the first time is bring them together in a microfluidic device and work out the specific details that could enable the device to function as a qubit.
Sources indicate that "The maths tells us that it should work. We have taken what we already know about superfluid helium and quantum technologies and turned that into an educated design, with the parameters and specifications needed to build one. The next step is to make a prototype and put those predictions to the test.".
Rather than replacing existing quantum computing hardware, the researchers say the SHOQ device could potentially be integrated with superconducting quantum technology.
That could allow different types of qubits to perform different jobs within the same system, depending on their strengths.
A Possible Role as Quantum Memory.
One longer-term possibility is to use the SHOQ device as a form of quantum memory. In that setup, a superfluid based qubit could store quantum information while other hardware carries out calculations.
According to recent reports, dr. Eran Ginossar, Associate Professor at the University of Surrey's Department of Physics and Advanced Technology Institute, and co-author of the study, said:.
Industry observers note that "We don't necessarily need one type of qubit to do everything. Combining different quantum technologies could allow us to take advantage of the strengths of each.
Industry observers note that "Superfluid helium gives us a fundamentally different type of quantum hardware to explore. If the predicted performance can be demonstrated experimentally, it could eventually work alongside existing superconducting technologies as part of a larger quantum system.".
The Next Step Is Building a Prototype.
The team now plans to build a prototype to find out whether the predicted performance can be reproduced in a real device. That effort is being supported by an IAA Commercialisation Fellowship awarded to Dr. Priya Sharma.
The SHOQ device would need to operate at extremely low temperatures, but researchers have already reached the necessary conditions in previous experiments involving superfluid helium-3.
In a recent development, the project was led by the University of Surrey in collaboration with Professor Jens Koch at Northwestern University in the United States. Koch was one of the researchers involved in developing the transmon - a superconducting qubit design that is now widely used in quantum computing.
Recent findings suggest that materials provided by University of Surrey. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Fresh Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.

AI & Tech
⚖️ Neutral
🌐 9to5google
#11350. Samsung Gallery officially adds Google Photos backup, but not for all Galaxy users
📅 10 Nov 2026 • ⏱️ 2m • 📖 Standard (351 w)
Samsung Gallery officially adds Google Photos backup, but not for all Galaxy users
📅 10 Nov 2026 | ⏱️ 2 min read (351 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Samsung has officially launched Google Photos integration in its Gallery app with backup services, and it’s also now widely rolled out for Galaxy devices.
- In a recent development, samsung Gallery started rolling out support for Google Photos backup in September, but it wasn’t widely available at the time.
- It has been revealed that “Gallery Sync” in the Samsung Gallery app replaces the previous Microsoft OneDrive integration with Google Photos, letting owners sign in with their Google account of choice and use the free 15GB or paid Google One storage to back up photos and videos.
Samsung has officially launched Google Photos integration in its Gallery app with backup services, and it’s also now widely rolled out for Galaxy devices.
In a recent development, samsung Gallery started rolling out support for Google Photos backup in September, but it wasn’t widely available at the time. As of this week, though, Samsung is officially announcing the feature as it is now available broadly to Galaxy consumers.
It has been revealed that “Gallery Sync” in the Samsung Gallery app replaces the previous Microsoft OneDrive integration with Google Photos, letting owners sign in with their Google account of choice and use the free 15GB or paid Google One storage to back up photos and videos. This allows the Samsung Gallery app to show media backed up from another Galaxy device, but it doesn’t integrate your full Google Photos library.
Industry observers note that at this point, Google Photos backup via Samsung Gallery should be broadly available to Galaxy owners. We’re seeing Samsung’s pop-up (pictured above) about the feature on our Galaxy Z Fold 8, with the feature fully functional beyond that.
You can also access setup via Menu > Settings > “Sync photos and videos” in the Samsung Gallery app.
Samsung requires your device to be running One UI 9 (Android 17) to access this feature, though it says that support will be “expanding to additional Galaxy devices in phases.” For the time being, though, that means the feature is a bit limited for people, as the One UI 9 rollout is still in progress.
Once media has been backed up to Google Photos, Samsung Gallery also now has a “free up space” button that can delete the local copies of your photos and videos to open up storage on your phone.
Follow Ben: Twitter/X, Threads, Bluesky, and Instagram.
Sources indicate that FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Samsung is a technology conglomerate based out o….
Ben is a Senior Editor for 9to5Google.
Find him on Twitter @NexusBen. Send tips to schoon@9to5g.com or encrypted to benschoon@protonmail.com.
🔗 Related Articles
📰 #23578. Breaking: Hands-on: Google and Samsung’s vision for Android XR glasses is 20/20 📰 #23564. Deals: Galaxy SmartTag 3 up to 30% off, Chromebooks, Google Home Speaker, Walmart early Black Friday now live, more 📰 #23546. Galaxy SmartTag 3 at $20 makes a compelling case to skip the Google Pixel Tag
AI & Tech
⚖️ Neutral
🌐 Sitepoint
#11349. Latest Update: What Breaks When a Self-Hosted LLM Gateway Hits 1,000 Concurrent Streams
📅 10 Nov 2026 • ⏱️ 7m • 📚 Deep Dive (1309 w)
Latest Update: What Breaks When a Self-Hosted LLM Gateway Hits 1,000 Concurrent Streams
📅 10 Nov 2026 | ⏱️ 7 min read (1309 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- Industry observers note that we sent 1,000 streaming calls at the same moment through three self-hosted LLM gateways: the Langfuse AI Gateway, the LiteLLM proxy and AcruxCore.
- According to recent reports, langfuse's failures came from Linux's open-file limit, which Docker sets to 1,024 by default.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Weekly. Free. One click to leave.
7 Day Free Trial. Cancel Anytime.
Industry observers note that we sent 1,000 streaming calls at the same moment through three self-hosted LLM gateways: the Langfuse AI Gateway, the LiteLLM proxy and AcruxCore. Each gateway was limited to 2 CPUs. As shipped, Langfuse finished 261 of the 1,000 streams and LiteLLM finished 403. Neither failure came from the gateway's own code.
According to recent reports, langfuse's failures came from Linux's open-file limit, which Docker sets to 1,024 by default. LiteLLM had that problem too, plus a second one: an empty key cache sent hundreds of database lookups at once, and the ones that waited longer than 10 seconds were rejected. This article shows how each failure looked, how we traced it to its cause, and the settings that fixed it.
This benchmark measured the resource consumption of three LLM gateways under scaling concurrent streaming loads.
Full latency, memory, and feature results are available in the Langfuse vs LiteLLM vs AcruxCore benchmark.
Sources indicate that first-token times are medians of the streams that succeeded. Up to 250 streams, every gateway succeeded. Then the errors started, and they did not look alike:.
Recent findings suggest that A 502 and a 503 point at different layers, so we expected two different causes. Two of the three turned out to share one cause.
Recent findings suggest that linux counts every network connection as an open file, and it caps how many open files one process may hold. The cap has two values. The soft limit is the cap that is in force now. The hard limit is the ceiling: a process may raise its own soft limit up to that value, and no further.
Recent findings suggest that A streaming gateway holds two connections for each stream: one from the client, and one to the model provider. That makes about 1,000 open files at 500 streams, and about 2,000 at 1,000 streams. A gateway also needs a few more files for its database, its logs and its own libraries.
Recent findings suggest that docker on our machine gave every container a soft limit of 1,024 and a hard limit of 524,288. All three gateways received the same two numbers. What differed was how each program treats them when it starts:.
In a recent development, node.js raises its own soft limit to the hard limit at startup. The Rust and Python services keep 1,024, and neither project's Compose file sets a higher value. So the two gateways ran out of open files near 500 streams, which is the point where the errors started.
It has been revealed that the out-of-files error appeared as a failed connection, not as a clear message. The Langfuse gateway's logs indicated failed connections to OpenAI, and also failed connections to Langfuse's own web service, which the gateway asks to check each key. Both come from one cause: a process that cannot open another file cannot open another socket. Its client then receives a 502.
Read the limit the process actually has, not the one you think Docker gave it. Process 1 is usually the main process in a container:.
Recent findings suggest that if the gateway runs under a supervisor or several workers, check each worker's process ID instead of process 1. To see how close a process is to its limit under load, count its open file descriptors:.
Sources indicate that raise the limit for the gateway service in its Compose file. We used 65,536 for all three gateways:.
In a recent development, the same ulimits block works on the LiteLLM service. On Kubernetes or another platform, check /proc//limits inside a running container rather than assuming a value.
Sources indicate that with the open-file limit raised, the Langfuse gateway finished all 1,000 streams. LiteLLM still returned 503 errors. To separate the two causes, we ran LiteLLM with one worker and only the open-file limit raised. All 500 streams succeeded in that ladder, but 595 of 1,000 failed with 503.
It has been revealed that the 503 message names the authentication database, so we read LiteLLM's logs and its source. The log gave the same reason for all 840 failed streams in these runs, 595 in that ladder and 245 in the cold-cache runs below:.
Three settings in LiteLLM explain it:.
Recent findings suggest that when 500 calls arrive while the key is not in the cache, each call looks the key up in Postgres. All of those lookups queue for 10 connections. The worker was also using its whole CPU allowance at this point, which slows every query it sends and receives. We infer that this CPU load lengthens the queue, but we did not measure it separately. Whatever the share of each, the lookups at the back of the queue miss the 10-second deadline.
If that explanation is right, the failures should depend on whether the key is already in the cache. So we ran 500 streams four more times. Three runs started after 75 seconds with no calls, which is longer than the 60-second cache. One run started right after a single warm-up call:.
The warm run had no failures. The cold runs failed by different amounts, 161, 84 and 0, because the result depends on how many lookups miss the deadline, and that changes from run to run. This probably explains why the earlier ladder succeeded at 500 and failed at 1,000. A run is a race between the lookup queue and the deadline, so a single ladder does not show where the limit is.
Sources indicate that the warm-up result is the one we measured. Send one call with each virtual key after LiteLLM starts, and avoid quiet periods longer than 60 seconds before a traffic spike. A steady flow of traffic keeps the key in the cache.
It has been revealed that liteLLM also exposes three settings that act on this path. We did not test them, so treat them as places to look rather than proven fixes:.
We raised the open-file limit to 65,536 for all three gateways and gave LiteLLM 2 workers, one per CPU, as its production guide recommends for a single machine. Then we ran the full ladder again:.
Industry observers note that the open-file errors were gone for every gateway, and the Langfuse gateway gave the fastest first token of the three. LiteLLM still returned 120 × 503 at 500. That level started about 60 seconds after the first call of the ladder, so the cached key had probably just expired. All 1,000 succeeded at the next level, which started within 60 seconds of the 500 level.
Recent findings suggest that once nothing failed, CPU decided the first-token times. LiteLLM used its whole 2-CPU allowance from 100 streams on, and its median first token took 19.2 seconds at 1,000 streams. AcruxCore also used both CPUs from 100 streams on, and its first token at 1,000 streams was 3.8 s at the median and 9.7 s at p95. The Langfuse gateway peaked at 1.65 CPUs and 168 MiB, with a first token of 1.7 s at the median and 9.6 s at p95.
Each gateway also needs the rest of its stack, and that stack uses CPU too. While the Langfuse gateway served 500 streams, its whole stack used up to 3.1 CPUs, because the web service checked keys and the worker and ClickHouse stored usage. AcruxCore's whole stack peaked at 4.0 CPUs, because its API writes a trace for every call to Postgres. Size the stack around the gateway, not only the gateway container.
Talha Anwar is a senior AI and full-stack engineer and writes about building and running AI systems at talhaanwar.com.
It has been revealed that 7 Day Free Trial. Cancel Anytime.
🔗 Related Articles
📰 #23503. Tech Report: How Much Latency Does a Self-Hosted LLM Gateway Add? Langfuse vs LiteLLM vs AcruxCore 📰 #11647. Prefill and Decode for Concurrent Requests - Optimizing LLM Performance 📰 #11552. Tech Report: Self-Hosted LangSmith Alternatives: 4 Tools Tested on One TypeScript Agent
General
⚖️ Neutral
🌐 Hugging Face
#11348. Latest Update: One Year Since the “DeepSeek Moment”
📅 20 Jan 2026 • ⏱️ 8m • 📚 Deep Dive (1644 w)
Latest Update: One Year Since the “DeepSeek Moment”
📅 20 Jan 2026 | ⏱️ 8 min read (1644 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~8 mins left to finish
📖 0% read
💡 Key Takeaways
- Recent findings suggest that the first blog addresses strategic changes and the explosion of newly introduced open models and open source players.
- Industry observers note that for AI researchers and developers contributing to and relying on the open source ecosystem and for policymakers understanding the rapidly changing environment, there has never been a better time to build and release open models and artifacts, as proven by the past year’s immense growth catalyzed by DeepSeek.
- In a recent development, before R1, China’s AI industry was still largely centered on closed models.
Recent findings suggest that the first blog addresses strategic changes and the explosion of newly introduced open models and open source players. The second covers architectural and hardware choices largely by Chinese companies made in the wake of a growing open ecosystem, available here. The third analyzes prominent organizations’ trajectories and the future of the global open source ecosystem, available here.
Industry observers note that for AI researchers and developers contributing to and relying on the open source ecosystem and for policymakers understanding the rapidly changing environment, there has never been a better time to build and release open models and artifacts, as proven by the past year’s immense growth catalyzed by DeepSeek. Notably, geopolitics has driven adoption; while models developed in China have been dominating across metrics throughout 2025 and newly introduced players leapfrogging each other, Western AI communities are seeking commercially deployable alternatives.
In a recent development, before R1, China’s AI industry was still largely centered on closed models. Open models had existed for years, but they were mostly confined to research communities or used only in niche scenarios such as privacy-sensitive applications. For most companies, they were not the default choice. Compute resources were tight, and whether to “open or close” was a subject of debate.
Industry observers note that deepSeek’s R1 model lowered the barrier to advanced AI capabilities and offered a clear pattern to follow, unlocking a second layer. Moreover, the release gave Chinese AI development something extremely valuable: time. It showed that even with limited resources, rapid progress was still possible through open source and fast iteration. This approach aligned naturally with the goals set out in China’s 2017 “AI+” strategy: combining AI with industry as early as possible, while continuing to build up compute capacity over the long term.
One year after the release of R1, what we see emerging is not only a collection of upcoming models, but also a growing organic open source AI ecosystem.
In a recent development, for the first time, an open model from China entered the global mainstream rankings and, over the following year, was repeatedly used as a reference point when new models were released. DeepSeek’s R1 swiftly became the most liked model on Hugging Face of all time and the top liked models are no longer majority U.S.-developed.
But R1’s real significance was not whether it was the strongest model at the time, its importance lay in how it lowered three barriers.
The first was the technical barrier. By openly sharing its reasoning paths and post-training methods, R1 turned advanced reasoning, previously locked behind closed APIs, into an engineering asset that could be downloaded, distilled, and fine-tuned. Many teams no longer needed to train massive models from scratch to gain strong reasoning capabilities. Reasoning started to behave like a reusable module, applied again and again across different systems. This also pushed the industry to rethink the relationship between model capability and compute cost, a shift that was especially meaningful in a compute-constrained environment like China.
Recent findings suggest that the second was the adoption barrier. R1 was released under the MIT license, making its use, modification, and redistribution straightforward. Companies that had relied on closed models began bringing R1 directly into production. Distillation, secondary training, and domain-specific adaptation became routine engineering work rather than special projects. As distribution constraints fell away, the model rapidly spread into cloud platforms and toolchains, and community discussions shifted from “which model scores higher” to “how do we deploy it, reduce cost, and integrate it into real systems.” Over time, R1 moved beyond being a research artifact and became a reusable engineering foundation.
Industry observers note that the third change was psychological. When the question shifted from “can we do this?” to “how do we do this well?”, decision-making across many companies changed. For the Chinese AI community, this was also a rare moment of sustained global attention, one that mattered deeply to an ecosystem long seen mainly as a follower.
Together, the lowering of these three barriers meant that the ecosystem began to gain the ability to replicate itself.
Once open source moved into the mainstream, a natural question followed: how would Chinese companies' strategies change?Over the past year, the answer became clear: competition began to shift from model-to-model comparisons toward system level capabilities.
Compared with 2024, the period after the release of R1 saw China’s AI landscape settle into a newly introduced pattern. Large technology companies took the lead, startups followed quickly, and companies from vertical industries increasingly entered the field. While their paths differed, a shared understanding gradually emerged, especially among leading players: open source was no longer a short-term tactic, but part of long-term competitive strategy.
It has been revealed that the number of competitive Chinese organizations releasing state of the art models and repositories skyrocketed. Reflected in Hugging Face Repository Growth of Chinese Companies, the number of open releases from existing giants substantially increased, with Baidu going from zero releases on Hugging Face in 2024 to over 100 in 2025, and others such as ByteDance and Tencent increasing releases by eight to nine times. An influx of newly open organizations released highly performant models, with Moonshot’s open release, Kimi K2, being a “another DeepSeek moment”.
Releases became stronger and frequent, with performant models released on a weekly basis; newly created Chinese models consistently became most liked and downloaded every week, boasting highest popularity among the top most downloaded fresh models on Hugging Face. The Top Newly Created Models by Week on Hugging Face reveals new repositories labeled by organization location or base model organization location for popular derivatives.
As seen in Hugging Face’s heatmap data, between February and July 2025, open releases from Chinese companies became noticeably more active. Baidu and Moonshot moved from primarily closed approaches toward open release. Zhipu AI’s GLM and Alibaba’s Qwen went a step further, expanding from simply publishing model weights to building engineering systems and ecosystem interfaces. At this stage, comparing raw model performance alone was no longer enough to win. Competition increasingly centered on ecosystems, application scenarios, and infrastructure_._.
This strategy was effectively successful; of newly created models (<1 year), downloads for Chinese models have surpassed any other country including the U.S.
Chinese AI players are not coordinating by agreement, but by constraint. What looks like collaboration is better understood as alignment under shared technical, economic, and regulatory pressures. This does not mean companies formed cooperative alliances. Rather, under similar constraints around compute, cost, and compliance, they began competing along similar technical foundations and engineering paths. When competition takes place on comparable system structures, the ecosystem starts to show the ability to spread and grow on its own. Tech leaders from Zhipu AI (Z.ai), Moonshot AI, Alibaba’s Qwen, and Tencent coordinating on shared questions is rarely seen in other countries.
Positive sentiment toward open source adoption and development has increased worldwide and especially in the U.S., with broader recognition of how open source leadership is critical in global competitiveness.
DeepSeek has been heavily adopted in global markets, especially in Southeast Asia and Africa. In these markets, factors such as multilingual support, open-weight availability, and cost considerations have supported enterprise use.
Often Western organizations seek non-Chinese models for commercial deployment. Major releases from U.S. organizations such as OpenAI’s gpt-oss, AI2’s Olmo, and Meta’s Llama 4 received community engagement. Reflection AI revealed its efforts to build frontier American open-weight models. In France, Mistral released their Mistral Large 3 family, continuously developing their open source roots.
At the same time, major releases in the West build on Chinese models; in November 2025, Deep Cogito released Cogito v2.1 as the leading U.S. open-weight model. The model was a fine-tuned version of DeepSeek-V3. Startups and researchers globally using open-weight models are often defaulting to if not relying on models developed in China.
Industry observers note that the American Truly Open Model (ATOM) project cites DeepSeek and China’s model momentum as a motivator for concerted efforts toward leading in open-weight model development. The project emphasizes the need for multiple efforts and its research also highlights OpenAI’s gpt-oss heavy early adoption.
Recent findings suggest that the world is still responding, with a upcoming open source fervor. 2026 is shaping up for major releases , especially from China and the U.S. Of high relevance are the architectural trends, hardware choices, and organizational directions, which will be covered next in this series.
Industry observers note that all data represented is sourced from Hugging Face. For more related data and analyses of 2025 in open source, we encourage you to read the Data Provenance Initiative and Hugging Face’s Economies of Open Intelligence: Tracing Power & Participation in the Model Ecosystem, aiWorld’s Open Source AI Year In Review 2025, and InterConnects’s 8 plots that explain the state of open models.
Chinese Open Source Model Take off !!!!
Chinese Translation of this Article: https://huggingface.co/blog/vansin/one-year-since-the-deepseek-moment-cn.
As a Chinese AI researcher who has fully experienced the wave of AI technologies and products in 2025, looking back on the series of changes brought about starting from DeepSeek, I have mixed feelings.
It has been revealed that the author's analysis is excellent. The open-sourcing of the R1 model weights and related technologies empowered the most usable technologies to both startups and large companies at that time. Such an "unconventional" change pushed China's AI field, whether in research and development or product development, into a stage of rapid development.
Thanks to open source. May AI technology benefit all of humanity.
This is such a fair and square article highlighting the technology and open trends. The wave of open models from China was a gift to the overall technical community and forever altered the progress of 2025 and beyond.2026 will be another year of open models. It might also be the year to reveal how "open source" would be truly redefined in the next 5 years.

General
⚖️ Neutral
🌐 9to5google
#11347. Amazon’s new Ring cameras are mounted to roving robots, including $250 Drone Cam
📅 10 Nov 2026 • ⏱️ 2m • 📖 Standard (330 w)
Amazon’s new Ring cameras are mounted to roving robots, including $250 Drone Cam
📅 10 Nov 2026 | ⏱️ 2 min read (330 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Amazon’s Ring brand is today launching a upcoming “Robotics” division that will start with two offerings – a $250 Ring Drone Cam and a $1,000 Rover Cam.
- Indoor cameras can be invaluable for securing your home, but also just in keeping an eye on what’s going on when you’re not home.
- Ring first indicated off its Drone Cam in 2020, but never actually brought the product to market.
Amazon’s Ring brand is today launching a upcoming “Robotics” division that will start with two offerings – a $250 Ring Drone Cam and a $1,000 Rover Cam.
Indoor cameras can be invaluable for securing your home, but also just in keeping an eye on what’s going on when you’re not home. To that end, Ring has been working on cameras that can be sent around the home remotely, and they’re finally launching early next year.
Ring first indicated off its Drone Cam in 2020, but never actually brought the product to market. That changes in January of next year, when the Ring Drone Cam will be available for $249.99. The camera, Amazon expains, is “a flying indoor security camera that goes where you need it, when you need it, and stays docked and out of sight when you don’t.” You can set flight routes on a schedule, have the drone automatically investigate tripped sensors in your Ring system, and more. The camera is only active when the drone is in flight, and it’s emphasized that the drone is not “quiet,” it’s “meant to be seen and heard.”.
The other robot Amazon’s Ring is launching is the Rover Cam, which is built on the back of Amazon Astro. It has a telescoping camera and rolls around your home on “scheduled patrols” as well as being able to automatically investigate tripped sensors. It also features two-way audio and a built-in siren to deter intruders from an area, while also features continuous 4K recording.
Ring is mainly pitching this one for businesses, and it costs $999.99 with pre-orders open now ahead of a December 16 release date.
Follow Ben: Twitter/X, Threads, Bluesky, and Instagram.
According to recent reports, FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Ben is a Senior Editor for 9to5Google.
In a recent development, find him on Twitter @NexusBen. Send tips to schoon@9to5g.com or encrypted to benschoon@protonmail.com.
General
⚖️ Neutral
🌐 Sciencedaily
#11346. Scientists recreate a bizarre quantum effect that stops a particle cold
📅 13 Oct 2026 • ⏱️ 7m • 📚 Deep Dive (1301 w)
Scientists recreate a bizarre quantum effect that stops a particle cold
📅 13 Oct 2026 | ⏱️ 7 min read (1301 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that A particle does not have to pass through a magnetic field to be influenced by it.
- The experiment reproduced a phenomenon known as the Aharonov-Bohm effect, in which a charged particle traveling around a region containing magnetic flux experiences a measurable change in its quantum state, even though its path never takes it through the magnetic field itself.
- It has been revealed that the Oxford team achieved this using a quantum system that combines qubits, the basic units of quantum information, with quantum oscillators, which represent vibrating motion.
Sources indicate that A particle does not have to pass through a magnetic field to be influenced by it. That surprising feature of quantum physics has now been recreated by researchers at the University of Oxford, who used a hybrid quantum computer to demonstrate how an invisible magnetic influence can bring a simulated particle's movement to a complete stop.
The experiment reproduced a phenomenon known as the Aharonov-Bohm effect, in which a charged particle traveling around a region containing magnetic flux experiences a measurable change in its quantum state, even though its path never takes it through the magnetic field itself.
It has been revealed that the Oxford team achieved this using a quantum system that combines qubits, the basic units of quantum information, with quantum oscillators, which represent vibrating motion. Their findings, published in Nature Physics, demonstrate how this combination could help scientists investigate fundamental interactions between matter and fields that are increasingly difficult to simulate using conventional computers.
A Strange Quantum Effect Predicted in 1959.
In everyday physics, a charged particle responds to the electric and magnetic fields it encounters. Quantum mechanics, however, reveals that particles can behave in ways that have no straightforward counterpart in our ordinary experience.
In 1959, physicists Yakir Aharonov and David Bohm predicted that a charged particle could be affected by magnetic flux even if it traveled entirely outside the region containing the magnetic field. Rather than experiencing a conventional magnetic force along its path, the particle would undergo a change in its quantum phase.
In a recent development, quantum phase describes an aspect of a particle's wave behavior that influences how different possible paths interfere with one another. Although the phase itself is not directly visible, differences in phase can produce measurable effects.
The prediction became known as the Aharonov-Bohm effect and was eventually verified in experiments involving real electrons. It remains one of the clearest demonstrations that the quantum world operates according to rules that go beyond the familiar laws of classical physics.
Researchers are now exploring how this phenomenon behaves in more complex theoretical systems known as lattice gauge theories.
These theories describe how matter interacts with fields associated with fundamental forces. They represent space as a grid, with matter located at individual points and fields associated with the connections between them. Such models are particularly vital in particle physics and high-energy physics, where scientists study the basic particles and interactions that make up the universe.
The challenge is that the mathematics becomes extraordinarily demanding as these systems grow more complicated. Even powerful conventional computers can struggle to calculate how all the interacting components evolve.
Quantum computers offer a different approach. Instead of attempting to calculate every aspect of a quantum system using classical computing methods, scientists can construct another quantum system that follows the same underlying rules. They can then observe its behavior directly, an approach known as quantum simulation.
How Scientists Built the Quantum Experiment.
Recent findings suggest that the Oxford project began in 2022, when lead author Dr. Sebastian Saner, Dr. Oana Bazavan, and their colleagues started developing a way to simulate lattice gauge theories using a hybrid quantum system. They collaborated with Dr. Alejandro Bermudez of the Instituto de Física Teórica in Madrid.
Their experimental design relied on two different quantum components that performed separate functions.
The first consisted of qubits encoded in the internal states of trapped ions, which are electrically charged atoms held in place using electromagnetic fields. These qubits represented the gauge fields in the theoretical model.
Recent findings suggest that the second component used quantum oscillators, created by the vibrations of those same trapped ions. These oscillators represented matter.
Sources indicate that by combining the two, the researchers constructed a simple loop that served as a basic building block of a lattice gauge theory. Two oscillators represented matter at two different locations, while two qubits represented the fields connecting those locations.
Although the arrangement was small, it was sufficient to reproduce an notable interaction between matter and magnetic flux.
Quantum Entanglement Creates a Surprising Solution.
According to recent reports, the researchers next placed the two qubits into an entangled quantum state. Entanglement is a phenomenon in which quantum systems become linked in ways that cannot be fully explained by classical physics.
Within the team's simulated lattice gauge theory, this entangled state represented magnetic flux passing through the center of the loop.
Initially, the researchers had planned to introduce the magnetic flux as a fixed background condition. However, creating the necessary interaction would have required capabilities that their quantum hardware did not possess.
Encoding the flux directly into the qubits provided a practical alternative. More importantly, it allowed the magnetic flux to become part of the evolving quantum system rather than remaining an unchanging external influence.
"For us, the exciting step was to encode the magnetic flux in a gauge field that was itself dynamical," says Dr. Saner. "Rather than having matter evolve in a fixed background, the matter and gauge field become part of the same quantum dynamics.".
What began as a technical workaround ultimately enabled the researchers to explore a more interesting version of the phenomenon, one in which matter and the field could participate together in the quantum dynamics.
A Quantum Effect That Stops Particle Motion.
With their simulated loop in place, the scientists examined how a matter particle moved between locations through a process known as quantum tunneling.
Quantum tunneling allows particles to move between states in ways that would not be possible under ordinary classical rules.
When the researchers ran their simulation without magnetic flux, the particle could tunnel freely around the loop.
Introducing the simulated flux produced a strikingly different result.
It has been revealed that the particle had two possible paths around the loop, but the magnetic flux changed their relative quantum phases. As a result, the two paths interfered destructively, meaning their quantum contributions canceled each other out.
This interference completely suppressed the tunneling, leaving the simulated particle frozen in its original state.
The outcome demonstrated the Aharonov-Bohm effect within a lattice gauge theory containing a dynamical field. Rather than simply reproducing the familiar behavior of a particle moving around a fixed magnetic influence, the experiment showed how the phenomenon can emerge when matter and the field are both represented by interacting quantum components.
A Latest Tool for Exploring Fundamental Physics.
The Oxford findings were published alongside a related study by researchers at the University of Maryland, led by Professor Norbert Linke.
The Maryland team also used a hybrid quantum system, but their experiment focused on simulating the Yukawa potential, a mathematical description of an interaction relevant to nuclear and particle physics.
Although the two research groups developed their methods independently, they later coordinated the submission of their studies to Nature Physics.
Together, the experiments demonstrate how hybrid quantum computers could become valuable tools for investigating fundamental interactions that are difficult to reproduce using classical simulations.
By combining different types of quantum components, researchers can build systems in which matter and fields are represented in ways that more closely reflect the physics they want to study.
It has been revealed that the Oxford experiment provides an example of that potential. A phenomenon first predicted in 1959 and later observed with electrons has now been recreated in a quantum simulator where the field itself participates in the dynamics, offering scientists another way to explore the unusual rules governing the quantum world.
Materials provided by University of Oxford. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #19483. Scientists Uncover a Bizarre Quantum Effect Where Time Could Flow at Different Speeds Simultaneously 📰 #17239. Quantum computers are getting too powerful to check. Scientists have a solution 📰 #13818. Tech Report: Cole Palmer in bizarre 'Cold Palmer' trademark battle with famous French vineyard
AI & Tech
⚖️ Neutral
🌐 Tomshardware
#11345. Lawyer’s eight-V100 AI server moves DeepSeek from 2-bit to near-NVFP4 precision
📅 14 Nov 2026 • ⏱️ 7m • 📚 Deep Dive (1366 w)
Lawyer’s eight-V100 AI server moves DeepSeek from 2-bit to near-NVFP4 precision
📅 14 Nov 2026 | ⏱️ 7 min read (1366 words, 📚 Deep Dive) | Source: Tomshardware
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- According to recent reports, A lawyer with a private AI server built on eight used Nvidia V100 GPUs returned with an enhancement, moving about 80% of its work up from 2-bit to 4-bit NVFP4 precision and bringing in 1TB of RAM and an RTX 3090.
- In a recent development, once a random hardware nerd lawyer on Reddit, the lawyer's responses to the original breaking story illuminated his identity.
- Industry observers note that he built the software side with AI, specifically Claude Code, which wrote the kernels and ran the benchmarks with his direction.
According to recent reports, A lawyer with a private AI server built on eight used Nvidia V100 GPUs returned with an enhancement, moving about 80% of its work up from 2-bit to 4-bit NVFP4 precision and bringing in 1TB of RAM and an RTX 3090. The server uses DeepSeek V4.1 Flash with a legal harness, the workflows and checks he wraps around the model, for his law practice. The cost? Performance, with code output dropping from 160–215 to 150–180 tokens per second, although the crashes that hit the new build are gone. The culprit behind the crashes, originally blamed on PCIe, was likely a bad PSU.
In a recent development, once a random hardware nerd lawyer on Reddit, the lawyer's responses to the original breaking story illuminated his identity. He’s a trial lawyer in Columbia, South Carolina. ProprietaryLegalAI commented on our first story three times, linking to a code repository, site, and LinkedIn that identify him as Nick Mermiges, founder of PLI Labs and proprietarylegal.ai. His other firm, PLI, is a technology consultancy, not a law firm, and now lists private, on-prem LLM serving as a service.
Industry observers note that he built the software side with AI, specifically Claude Code, which wrote the kernels and ran the benchmarks with his direction. The Opus 5.5 and Fable 5.2 models handled the optimizations, custom kernels, and re-quantizing; he noted he was surprised at how well Fable built custom Volta kernels, and how it re-quantizes the experts his legal harness triggers. From about February to July, he built a legal harness around Claude that worked, while his attempts at a local-model version failed, but then DeepSeek V4.1 Flash arrived, and he was able to port it successfully, even if he says it’s not as good as frontier.
Sources indicate that he reaffirms that “the documents never leave the office” and upgraded the system from 256GB to 1TB of RAM and tossed in a newer GPU, even as the V100s stay on “borrowed time” with R580, the last Nvidia driver branch to support them. The project’s intentions, as listed last time, suggested he wanted the system to be able to offload more of his workload, so this and the precision change are a reasonable upgrade. His previously stated goal of wanting the system to handle more than one request at a time has also been met.
In a recent development, the original “Volta sPLIt” build we covered has transformed into the “Volta Max uPLIft,” still with the clever lettering as his company’s initials are PLI — Proprietary Legal Intelligence. He now claims “near-NVFP4 precision,” having described NVFP4 on our forum earlier this week as “essentially full precision.” NVFP4 is Nvidia’s 4-bit floating-point format, and Nvidia publishes its own NVFP4 version of DeepSeek V4.1 Flash; the project’s README indicates that version matches the precision of the model’s official weights at 4.25 bits per weight.
It has been revealed that deepSeek V4.1 Flash is built from “experts,” the parts of the model that do most of the work for each word. This model didn’t fit at that precision before, as 384 routed experts, in each of 40 layers, counts to 15,360 in all. At official precision, this comes out to about 269 GiB, by his estimate, and eight 32GB V100s have 256 GiB in total before anything else is loaded. With the 2-bit build, the weights were 248.8GB; the latest build’s Hugging Face package is about 556GB.
In a recent development, the workaround is to keep every expert on the cards at 2-bit and swap the most-used ones up until the cards are full, which in this case came out to about 38.7%, or 5,949 experts, at precisely NVFP4. “Most-used,” in this context, refers to a count from a mix of four kinds of text, which are weighted equally, one of which is his own legal harness traffic.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
The payoff is that those experts do most of the work. In testing with one request at a time, between 80% and 86% of decode routes, the calls to an expert made while the model writes, land on the NVFP4 experts, lowest for general text and highest for source code. The prediction for the two-request setup he runs is 78% to 85%. The remaining 15% to 22% of calls would still go to a 2-bit expert.
In a recent development, measured against Nvidia’s own version of the model as the reference, he was able to get good results. Same next token, or how often a build picks the same next token as the reference, went up to 95.1% from 92.2%. For KL divergence, which measures how far a build’s probabilities are from the reference’s, it went down to 0.079 nats from 0.196. In measuring multiple-choice answers that change, across 513 questions from a standard multiple-choice knowledge test, it went from 79 different to just 8.
This does not measure accuracy — which was about the same across all three cases — but fidelity. Those tests ran on the build’s first release, but not on the upcoming two-request setup he now runs.
According to recent reports, the result of the changes: higher fidelity but at a lower level of performance. Code output is 3% to 30% slower, depending on the prompt length, and legal writing is 9% to 23% slower. Before the build, he hoped to maintain about 80 tokens per second on legal and prose; the bench came in at 86 to 106 for legal and 78 to 86 for prose. The upside is that running two requests at once raises total output to 159.0 tokens per second, versus 118.9 with a sole request. The first token also arrives sooner at every prompt length, 108.4 seconds versus 118.7 seconds at 256K tokens.
Each request needs a “slot,” though, and this comes at a cost. Every slot keeps its own state on the cards, which leaves room for fewer NVFP4 experts: 6,215, 5,949, 5,663 for one, two, and three slots, respectively. This means each added slot may push another one to two points of the calls back to 2-bit, which could reduce output quality.
Wait for first token, 2-bit / near-NVFP4.
Code (tokens/s), 2-bit / near-NVFP4.
Legal writing (tokens/s), 2-bit / near-NVFP4.
Builder’s measurements, Nov. 5 (2-bit) and Nov. 12 (near-NVFP4); greedy decoding, thinking off, one request at a time.
According to recent reports, the move to more RAM came this week with eight 128GB modules at 2,933 MT/s, originally eight 32GB modules that had to be run at DDR4-2666 due to ECC errors. After the RAM upgrade, the host reports two NUMA nodes, and two boots hung at the first transfer between the boards, so he reordered the cards in software. The GPUs remain capped at 1,522 MHz, as before.
As for the PSU, he took the common approach of chasing PCIe slots, cards, and cables to narrow down the cause, finally concluding it was “probably one bad PSU.” He also added more fans, but with no temperature changes, this only indicated that airflow was not the problem. He changed the power delivery, and nine of nine long chats read clean afterward. Also, don’t judge his cable management skill; any “advice [there] is welcome and will be ignored,” which is the only comment to make in that situation.
Recent findings suggest that he also already has two DGX Sparks running the same model at 1M context for agent work, and three or four sessions at once, and he isn’t stopping there. Now it comes down to scaling. Eight more V100s and a second server, with 512GB of 3,200 MT/s ECC RAM, are waiting in the wings. The second box would run another high-precision DeepSeek, used as an extra agent or to run tasks in parallel. The initiative is also to move DeepSeek’s small draft model off the V100s and onto the RTX 3090, which hasn’t happened yet.
Follow Tom’s Hardware on Google News, or add us as a preferred source, to get our latest news, analysis, & reviews in your feeds.
Shane Downing is a Contributing Writer for Tom’s Hardware, covering consumer storage, PC hardware, and AI.
🔗 Related Articles
📰 #23228. Quantization-Aware Healing: a compressed, 4-bit model that outperforms its full-precision original 📰 #23622. Researchers ‘recognize that AI will never replace HPC,’ notes AMD executive — high-precision workloads will ‘exist for a very long time’ even as AI usage expands 📰 #23543. AMD attacks Nvidia's FP64 emulation at SC26, touts native double-precision on Instinct MI430X — claims Ozaki schemes fit less than 10% of HPC workloads and triple memory use and emulated FP64 is a poor fit for many HPC workloads
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11344. AssetOpsBench: Bridging the Gap Between AI Agent Benchmarks and Industrial Reality
📅 21 Jan 2026 • ⏱️ 7m • 📚 Deep Dive (1301 w)
AssetOpsBench: Bridging the Gap Between AI Agent Benchmarks and Industrial Reality
📅 21 Jan 2026 | ⏱️ 7 min read (1301 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- AssetOpsBench is a comprehensive benchmark and evaluation system with six qualitative dimensions that bridges the gap for agentic AI in domain-specific settings, starting with industrial Asset Lifecycle Management.
- According to recent reports, while existing AI benchmarks excel at isolated tasks such as coding or web navigation, they often fail to capture the complexity of real-world industrial operations.
- AssetOpsBench is built for asset operations such as chillers and air handling units.
AssetOpsBench is a comprehensive benchmark and evaluation system with six qualitative dimensions that bridges the gap for agentic AI in domain-specific settings, starting with industrial Asset Lifecycle Management.
According to recent reports, while existing AI benchmarks excel at isolated tasks such as coding or web navigation, they often fail to capture the complexity of real-world industrial operations. To bridge this gap, we introduce AssetOpsBench, a framework specifically designed to evaluate agent performance across six critical dimensions of industrial applications. Unlike traditional benchmarks, AssetOpsBench emphasizes the need for multi-agent coordination—moving beyond `lone wolf' models to systems that can handle complex failure modes, integrate multiple data streams, and manage intricate work orders. By focusing on these high-stakes, multi-agent dynamics, the benchmark ensures that AI agents are assessed on their ability to navigate the nuances and safety-critical demands of a true industrial environment.
AssetOpsBench is built for asset operations such as chillers and air handling units. It comprises:.
Experts helped curate 150+ scenarios. Each scenario includes metadata: task type, output format, category, and sub-agents. The tasks designed span across:.
AssetOpsBench evaluates agentic systems across six qualitative dimensions designed to reflect real operational constraints in industrial asset management. Rather than optimizing for a single success metric, the benchmark emphasizes decision trace quality, evidence grounding, failure awareness, and actionability under incomplete and noisy data.
Each agent run is scored across six criteria:.
Across early evaluations, we observe that many general-purpose agents perform well on surface-level reasoning but struggle with sustained multi-step coordination involving work orders, failure semantics, and temporal dependencies. Agents that explicitly model operational context and uncertainty tend to produce more stable and interpretable trajectories, even when final task completion is partial.
This feedback-oriented evaluation is intentional: in industrial settings, understanding why an agent fails is often more valuable than a binary success signal.
A central contribution of AssetOpsBench is the explicit treatment of failure modes as first-class evaluation signals in agentic industrial workflows. Rather than treating failure as a binary outcome, AssetOpsBench analyzes full multi-agent execution trajectories to identify where, how, and why agent behavior breaks down under realistic operational constraints.
Failure analysis in AssetOpsBench is implemented through a dedicated trajectory-level pipeline (TrajFM), which combines LLM-based reasoning with statistical clustering to surface interpretable failure patterns from agent execution traces. This pipeline operates in three stages: (1) trajectory-level failure extraction using an LLM-guided diagnostic prompt, (2) embedding-based clustering to group recurring failure patterns, and (3) analysis and visualization to support developer feedback and iteration.
Across industrial scenarios, recurrent failure modes include:.
Sources indicate that importantly, AssetOpsBench does not rely solely on a fixed, hand-crafted failure taxonomy. While a structured set of predefined failure categories (e.g., verification errors, step repetition, role violations) is used for consistency, the system is explicitly designed to discover fresh failure patterns that emerge in practice. Additional failure modes identified by the LLM are embedded and clustered automatically, allowing the taxonomy to evolve as new agent designs and behaviors are evaluated.
To preserve industrial confidentiality, raw execution traces are never exposed. Instead, agents receive aggregated scores across six evaluation dimensions together with clustered failure-mode summaries that explain why an agent failed, without revealing sensitive data or intermediate reasoning steps. This feedback-driven design enables developers to diagnose weaknesses, refine agent workflows, and iteratively resubmit improved agents.
This failure-aware evaluation reflects the realities of industrial asset management, where cautious, degradation-aware reasoning—and the ability to recognize uncertainty, defer action, or escalate appropriately—is often preferable to aggressive but brittle automation.
Recent findings suggest that assetOpsBench-Live is designed as an open, competition-ready benchmark, and we welcome submissions of agent implementations from the community. Agents are evaluated in a controlled, privacy-preserving environment that reflects real industrial asset management constraints.
In a recent development, to submit an agent, developers first validate their implementation locally using a provided simulated environment, which includes representative sensor data, work orders, alerts, and failure-mode catalogs. Agents are then containerized and submitted for remote execution on hidden evaluation scenarios.
According to recent reports, submitted agents are evaluated across six qualitative dimensions—task completion, accuracy, result verification, action sequencing, clarity, and hallucination—using a consistent, reproducible evaluation protocol. Execution traces are not exposed; instead, participants receive aggregated scores and structured failure-mode feedback that highlights where and why an agent’s reasoning or coordination broke down.
This feedback-driven evaluation loop enables iterative improvement: developers can diagnose failure patterns, refine agent design or workflow structure, and resubmit updated agents for further evaluation. Both planning-focused and execution-focused agents are supported, allowing researchers and practitioners to explore diverse agentic designs within the same benchmark framework.
We performed a community evaluation where we tested two tracks:.
Across 225 consumers and 300+ agents and leading open source models, here are the observations:.
Note: None of the models could pass our evaluation criteria benchmark and get 85 points, which is the threshold for deployment readiness.
Across 881 agent execution traces, failure distribution was as follows:.
Beyond this, 185 traces had one new failure pattern and 164 had multiple novel failures.
According to recent reports, this is an exceptionally key and well-executed benchmark. The shift in focus from "did the task succeed?" to "how and why did the process fail?" is precisely what's needed to move AI agents from research demos into high-stakes industrial environments.
It has been revealed that the six-dimensional evaluation framework and the TrajFM pipeline for analyzing failure modes are standout contributions. The data you've shared is striking—particularly that no tested model, including the top performers, could meet the 85-point deployment readiness threshold. This honest result highlights a critical maturity gap and sets a clear, high bar for the community.
In a recent development, the findings around multi-agent coordination are especially valuable. The significant accuracy drop from single-agent (68%) to multi-agent (47%) workflows quantifies a major challenge many have anecdotally observed but rarely measured so clearly.
I have a couple of questions based on the thoughtful analysis:.
Recent findings suggest that evolving Failure Taxonomy: You mention the system is designed to discover upcoming failure patterns beyond the predefined taxonomy. Have you observed any novel, recurrent failure modes emerging from the community evaluations that are now being considered for inclusion in the core taxonomy?
Measuring Coordination Quality: The benchmark effectively captures that multi-agent coordination fails. Are there prepares to develop more granular metrics to diagnose the quality of coordination itself (e.g., communication efficiency, conflict resolution) as a distinct dimension?
Congratulations to the team on this crucial work. By providing a rigorous, feedback-driven, and privacy-preserving evaluation platform, AssetOpsBench doesn't just measure progress—it actively guides the field toward building more robust and trustworthy industrial agents.
This is an open source project and you are more than welcome to contribute to the thoughtful analysis you have provided -Yes, for evolving failure mode, and we can add it to the core taxonomy.@mcemri / @melissapan Any suggestion?
In a recent development, I’ve been using AssetOpsBench in the context of industrial multi-agent evaluation, and what stands out to me is not just the benchmark itself, but the shift in mindset it represents. We finally have a structured way to stress-test coordination, orchestration, and tool reliability in Industry 4.0-style environments, instead of relying on isolated task accuracy.
In my own exploration, I’ve been particularly interested in:• Failure distributions across agent trajectories• Tool precision and recovery dynamics• Orchestration patterns under realistic industrial constraints• Governance implications for enterprise deployment.
Industry observers note that I wrote a deeper technical perspective on this, especially through an Industry 4.0 and enterprise adoption lens. Kindly check it out:.
https://medium.com/@nijesh-kanjinghat/industrial-autonomy-a-technical-evaluation-of-assetopsbench-for-multi-agent-systems-in-industry-4-0-5fe1eef7fe98.
always a very relevant topic for asset lifecycle management.
AssetOpsBench is a fascinating approach to evaluating AI agents in real industrial environments. The focus on task completion, verification, hallucination, and failure awareness makes the benchmark especially valuable. I also found this resource on LLM evaluation for AI agent development: https://mobisoftinfotech.com/resources/blog/ai-development/llm-evaluation-for-ai-agent-development. Great perspective on agent evaluation!

General
⚖️ Neutral
🌐 9to5google
#11343. Industry News: Galaxy S27 redesign leak shows off Pro vs Ultra size difference, with just a bit of controversy
📅 10 Nov 2026 • ⏱️ 2m • 📖 Standard (353 w)
Industry News: Galaxy S27 redesign leak shows off Pro vs Ultra size difference, with just a bit of controversy
📅 10 Nov 2026 | ⏱️ 2 min read (353 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Samsung is working on a long overdue redesign for its Galaxy S27 series and, this week, we’re getting a fresh look.
- We’ve already seen it in renders, but leaker Sonny Dickson took to Twitter/X today to present an image of Galaxy S27 Pro, Ultra, and S27+ dummy units, and it tells us a few things.
- First, we get to see the redesign again, this time in “real life.” That’s, of course, with the caveat that these aren’t real devices, and probably aren’t reflective of the final design either.
Samsung is working on a long overdue redesign for its Galaxy S27 series and, this week, we’re getting a fresh look.
We’ve already seen it in renders, but leaker Sonny Dickson took to Twitter/X today to present an image of Galaxy S27 Pro, Ultra, and S27+ dummy units, and it tells us a few things.
First, we get to see the redesign again, this time in “real life.” That’s, of course, with the caveat that these aren’t real devices, and probably aren’t reflective of the final design either. The Pro and Ultra both have a full-width camera island akin to Apple’s latest iPhone design language, and a big departure from the vertical camera array that Samsung insisted was its “core identity” mere months ago.
It has been revealed that importantly, we can also see the size difference between Galaxy S27 Ultra and S27 Pro, with the Pro being noticeably smaller compared to both the Ultra and the S27+. For small(er) phone fans, it’s looking great.
All of that said, adding a bit of controversy to this image is leaker Ice Universe, who indicates “this picture is wrong.”.
Sources indicate that ice points out that the Galaxy S27 Ultra and Pro both do not have a fourth camera lens, which is correct based on recent leaks. That said, it’s not much of a leap to assume these dummy units are based on an older design, or are confusing a sensor. After all, these are mainly used to test accessories and, this early on, there’s plenty of room for inaccuracy.
Sources indicate that what do you think of this image? Do you think it’ll look like the final product? Do you like the size difference on the Galaxy S27 Pro?
Follow Ben: Twitter/X, Threads, Bluesky, and Instagram.
Recent findings suggest that FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Samsung is a technology conglomerate based out o….
Ben is a Senior Editor for 9to5Google.
It has been revealed that find him on Twitter @NexusBen. Send tips to schoon@9to5g.com or encrypted to benschoon@protonmail.com.
🔗 Related Articles
📰 #23458. Tech Report: Deals: Early Black Samsung now live – Galaxy Fold 8 $350 off, S26 Ultra $450 off, Tabs from $200, more 📰 #17943. Industry News: Honda just showed off its first high-end electric mountain bike 📰 #16343. Tech Report: Deals: Apple TV 4K release day discount, Apple Watch Ultra $250 off, AirPods Pro 3, AirTag 2 all-time low, more
General
⚖️ Neutral
🌐 Sciencedaily
#11342. Physicists discover “astonishing” property of light that defies expectations
📅 13 Oct 2026 • ⏱️ 7m • 📚 Deep Dive (1400 w)
Physicists discover “astonishing” property of light that defies expectations
📅 13 Oct 2026 | ⏱️ 7 min read (1400 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- Industry observers note that scientists have discovered a surprising ability of light that allows it to develop spinning patterns as it moves through empty space, without relying on special lenses, mirrors, or materials.
- The discovery comes from an international team led by researchers at the University of East Anglia (UEA) in the United Kingdom, working with scientists in South Africa.
- The findings challenge long-standing assumptions about how different properties of light interact.
Industry observers note that scientists have discovered a surprising ability of light that allows it to develop spinning patterns as it moves through empty space, without relying on special lenses, mirrors, or materials. The finding reveals that light possesses a hidden geometric structure that can influence its behavior in ways researchers previously thought were difficult to achieve.
The discovery comes from an international team led by researchers at the University of East Anglia (UEA) in the United Kingdom, working with scientists in South Africa. Their experiments demonstrate that carefully prepared light can be controlled through its own internal geometry, offering a fresh approach to manipulating how light spins and twists.
The findings challenge long-standing assumptions about how different properties of light interact. They could eventually lead to more sensitive medical tests, faster and more secure communications, and advanced quantum technologies that use light to transmit and protect information.
Why the Direction of Light's Spin Matters.
One of the most intriguing aspects of the discovery involves chirality, a scientific term describing the difference between left-handed and right-handed structures.
It has been revealed that human hands provide a familiar example. Although they are mirror images of each other, a left hand cannot be perfectly superimposed on a right hand. Many molecules have a similar property, including compounds used in medicines. Two versions of the same molecule can have nearly identical chemical structures yet produce very different effects in the body.
Sources indicate that scientists can distinguish these molecular forms by studying how they interact with light that has a particular rotational behavior. Traditionally, producing and controlling such light has often involved specialized materials, carefully designed surfaces, or powerful lenses that focus beams extremely tightly.
The research demonstrates that appropriately prepared light can develop this behavior naturally as it travels, without requiring those additional optical components.
"Our work reveals that light can naturally develop this handed behavior all on its own," said Dr. Kayn Forbes from UEA's School of Chemistry, Pharmacy and Pharmacology.
"You just have to prepare it in the right way.
"Most people think of light as traveling in straight lines. But scientists can also create structured light -- light whose brightness, shape, and direction are carefully arranged.
"One extreme example is light that twists as it travels, forming a corkscrew shape known as an optical vortex. Each twist can carry information, making this kind of light valuable for high-speed internet, secure communications, and advanced sensors.
"Light can also spin as it travels, depending on how it is polarized. This spin can be left-handed or right-handed -- another form of chirality.".
Scientists Discover How Light Develops a Hidden Spin.
Light can exhibit different kinds of rotational behavior. An optical vortex, for example, has a wave pattern that twists around its direction of travel, much like a corkscrew. Light also has a property known as polarization, which describes how its electric field oscillates. Certain polarization patterns produce a form of rotation called spin.
Industry observers note that physicists have long studied the relationship between these two properties. However, the interactions responsible for the newly observed effect were generally considered extremely weak and difficult to detect without specialized experimental conditions.
The researchers found that the situation changes when a beam of light is prepared in a particular balanced configuration.
Under those conditions, the beam can initially have no spin, yet distinct regions with spinning behavior emerge as it travels through free space. The effect does not require the light to pass through engineered materials or additional optical devices.
In a recent development, "It starts off with no spin at all," explained MSc student Light Mkhumbuza, who carried out key experiments. "But as the beam travels forward, spinning regions appear and separate out -- almost as if the spin was hiding and then revealed itself.".
Rather than creating spin through an external optical component, the researchers demonstrated how the beam's existing internal structure can determine where spinning regions develop during propagation.
The Hidden Geometry That Controls Light.
To explain this unexpected behavior, the researchers turned to topology, a mathematical field concerned with properties that remain unchanged when objects are continuously stretched, bent, or reshaped.
Dr. Isaac Nape, from the University of the Witwatersrand in Johannesburg, South Africa, offered a simple way to understand the concept.
"To explain it, imagine a mug and a doughnut," he remarked. "You can morph one into the other without tearing it, because they both have one hole. That hole is a topological feature.".
The researchers found that structured light possesses its own topological characteristics, encoded in the arrangement of its polarization.
This underlying pattern acts like a mathematical fingerprint. Even as the light beam changes shape while traveling, its topological structure remains, influencing how different regions of the beam evolve.
As a result, the arrangement of the light itself can determine where its left-handed and right-handed spinning patterns become visible.
The discovery gives scientists a way to guide this behavior by designing the beam's initial structure, rather than depending on specialized materials to produce the desired effect.
Industry observers note that "This gives us a completely newly introduced tuning knob for light. By adjusting its topology, we can decide how and where chirality appears," stated Dr. Nape.
Potential Breakthroughs in Medicine and Communications.
The ability to control light through its geometry could eventually make several important optical technologies simpler, more affordable, and more versatile.
Industry observers note that one particularly promising application involves medical diagnostics and pharmaceutical research. Because many biologically important molecules have left-handed and right-handed forms, carefully structured light could help scientists identify these differences with greater sensitivity. Such tools could be valuable for evaluating drug safety and detecting biological markers associated with disease.
The same principles could support smaller optical sensors capable of identifying chemicals or biological substances without requiring large, sophisticated laboratory instruments.
According to recent reports, communications technology could also benefit. By encoding information into different twisting and spinning patterns, researchers may be able to increase the amount of data carried by individual light beams. This could contribute to faster optical communications, improved information security, and future quantum networks.
Other potential uses include manipulating microscopic particles, cells, and molecules with light, as well as developing more resilient quantum systems. Topological properties may help protect delicate quantum information against certain forms of noise and interference.
Recent findings suggest that "The implications are wide-ranging," stated Dr. Forbes. "This work could lead to simpler and more sensitive medical tests, especially in drug development.
"It could also be used to pack more information into laser beams -- boosting data capacity for communications, including future quantum networks.
"And because the effect doesn't rely on fragile materials or precision-engineered surfaces, it could be easier and cheaper to use in real-world technologies.
"This research could lay the foundations for a newly introduced generation of light-based technologies, by showing that light's behavior can be controlled using its own internal geometry," he added.
These applications remain possibilities for future development, but the underlying discovery provides researchers with another way to design and control the behavior of light.
A Hidden Property of Light Finally Revealed.
Recent findings suggest that for decades, scientists have relied on increasingly sophisticated optical equipment to produce and manipulate unusual forms of light. The findings suggest that some of these behaviors can instead arise from carefully designed structures already encoded within a light beam.
By showing how topology governs the emergence of spinning regions during propagation, the team has revealed a previously underappreciated connection between light's geometry and its physical behavior.
The discovery also illustrates how much remains to be learned about something as familiar and extensively studied as light.
"For something so familiar, light is proving to be far richer, stranger and more powerful than anyone imagined," stated Dr. Forbes.
"And astonishingly, this new behavior has been there all along -- just waiting to be seen.".
The research, 'Topological Control of Chirality and Spin with Structured Light', was published in the journal Light: Science & Applications.
It has been revealed that materials provided by University of East Anglia. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Newly introduced Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
Hardware & Chips
⚖️ Neutral
🌐 Tomshardware
#11341. Save up to $800 on an iBuyPower gaming PC right now in this massive Black Friday sale
📅 14 Nov 2026 • ⏱️ 3m • 📚 Deep Dive (675 w)
Save up to $800 on an iBuyPower gaming PC right now in this massive Black Friday sale
📅 14 Nov 2026 | ⏱️ 3 min read (675 words, 📚 Deep Dive) | Source: Tomshardware
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- It has been revealed that iBuyPower, who specialize in pre-built and customized gaming PC builds, have put together a huge sale for the entire month of November.
- There are sales on PCs that feature some of the best specs available for a gaming PC, with powerful CPUs and GPUs like the AMD Ryzen 7 9800X3D and Nvidia GeForce RTX 5090 on offer.
- These extended deals will run until 11.59 pm PT on November 29.
It has been revealed that iBuyPower, who specialize in pre-built and customized gaming PC builds, have put together a huge sale for the entire month of November. iBuyPower's Black Friday month of sales means you can score a gaming PC with a big discount, with hundreds of dollars knocked off some seriously powerful rigs right now.
There are sales on PCs that feature some of the best specs available for a gaming PC, with powerful CPUs and GPUs like the AMD Ryzen 7 9800X3D and Nvidia GeForce RTX 5090 on offer. These sales will last for almost the entire month, but there's no guarantee that the stock will be around that long.
● Check out these gaming PC deals at iBuyPower.
These extended deals will run until 11.59 pm PT on November 29. If you're quick, you can score up to $200 more off the sale prices of these iBuyPower gaming PCs via the company's store, as long as you're using a coupon code. This deal applies only to iBuyPower's pre-built gaming machines, however.
Make sure to use the coupon code BFMONTH at checkout to check for any extra discounts that might be running. This code will knock up to $200 off pre-builts, for instance, while also giving you 5% off any custom builds you decide to go for, but how much discount you get will depend on the price of the machine you're buying.
To help you pick, here are some of the stand-out deals on gaming PCs running over at iBuyPower right now.
Industry observers note that these are some of iBuyPower's best rigs on sale right now, but be warned. Some of these deals are time-limited, with fresh deals popping up and prices changing, depending on the day. If you want any of these rigs at a deal price, you really will need to be quick, as the best sellers will sell out fast.
An AMD build is all the rage, given the power of 3D V-Cache, which is where this iBuyPower RDY Element 9 Pro R07 gaming PC comes in. It features every gamer's dream in the AMD Ryzen 7 7800X3D, still the best for gaming right now, along with a 2TB SSD, 32GB of RAM, and the AMD Radeon RX 9070 XT 16GB, a formidable option for 1440p.
A good set of specs for 1080p gaming, fitted with an AMD Ryzen 5 9500F CPU and an AMD Radeon RX 9060 XT, along with 16GB DDR5 and a 1TB SSD.
A gorgeous all-white build with specs ready for 1440p and 4K gaming. It has an RTX 5070, along with 32GB DDR5, AMD Ryzen 7 7800X3D, and a 1TB SSD.
According to recent reports, A 4K-ready powerhouse with liquid cooling and a wrap-around glass case. This build combines the 9800X3D with the RTX 5070 Ti, 32GB DDR5 and a 2TB SSD.
According to recent reports, A beautiful all-white build with a liquid cooler and full wrap-around glass case. This Intel rig has the Intel Core Ultra 7 270K with an RTX 5070 Ti, 32GB DDR5 and a 2TB SSD.
You're getting the powerhouse 9800X3D with the RTX 5080 in this formidable 4K gaming PC from iBuyPower. It ships with 32GB DDR5 and a 2TB SSD.
A good budget-friendly rig for 1080p gaming. This build has an AMD Ryzen 5 9500F CPU, along with and AMD Radeon RX 9060 and 16GB DDR5, as well as a 1TB SSD.
In a recent development, A powerhouse gaming PC with some of the best specs available. This rig has the 9950X3D fitted with the RTX 5090 to compliment it, as well as 32GB DDR5 RAM and a 4TB SSD.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
Recent findings suggest that ben Stockton is a deals writer at Tom’s Hardware. He's been writing about technology since 2018, with bylines at PCGamesN, How-To Geek, and Tom’s Guide, among others. When he’s not hunting down the best bargains, he’s busy tinkering with his homelab or watching old Star Trek episodes.
🔗 Related Articles
📰 #13065. Dont wait until Black Friday — the Nintendo Switch 2 is on sale for $30 off right now 📰 #23588. Save $385 on this 4K-ready Alienware gaming PC with an RTX 5080 and 32GB DDR5 right now 📰 #22010. Our Editors Found the Best Walking Shoes on Sale for Black Friday—Save Up to 44%
General
⚖️ Neutral
🌐 9to5google
#11340. Waze rolling out cyclist alerts based on real-time locations from Garmin trackers
📅 10 Nov 2026 • ⏱️ 1m • 📖 Standard (254 w)
Waze rolling out cyclist alerts based on real-time locations from Garmin trackers
📅 10 Nov 2026 | ⏱️ 1 min read (254 words, 📖 Standard) | Source: 9to5google
⏱️ ~1 mins left to finish
📖 0% read
💡 Key Takeaways
- Waze is officially rolling out alerts for cyclists along your route that leverages location data from Garmin trackers.
- It has been revealed that in an effort to “boost driver awareness” of nearby bicycle riders, Waze will start showing real-time alerts for nearby cyclists to drivers in the area.
- Waze knows the location of a nearby cyclist through a partnership with Garmin, with “LiveTrack” location sharing from the Garmin Edge bike computer or Garmin smartwatches users to share location data with the Google-owned navigation app.
Waze is officially rolling out alerts for cyclists along your route that leverages location data from Garmin trackers.
It has been revealed that in an effort to “boost driver awareness” of nearby bicycle riders, Waze will start showing real-time alerts for nearby cyclists to drivers in the area. The feature shows both a location on the map ahead as well as a visible alert on screen.
Waze knows the location of a nearby cyclist through a partnership with Garmin, with “LiveTrack” location sharing from the Garmin Edge bike computer or Garmin smartwatches users to share location data with the Google-owned navigation app.
Cyclists need to opt-in to the feature to have their location shown, and the alerts drivers see are temporary and anonymous. When cyclists end their ride, Waze alerts also go away.
This feature is completely opt-in and built with privacy in mind. Drivers only see a temporary alert that a cyclist is nearby — never information about a specific cyclist or route. Plus, alerts automatically turn off the moment a cyclist ends their ride on their Garmin device.
This is rolling out starting today to the Waze apps on both Android and iOS.
Follow Ben: Twitter/X, Threads, Bluesky, and Instagram.
FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Waze is a third-party navigation application tha….
Ben is a Senior Editor for 9to5Google.
Industry observers note that find him on Twitter @NexusBen. Send tips to schoon@9to5g.com or encrypted to benschoon@protonmail.com.

General
⚖️ Neutral
🌐 Hugging Face
#11339. Unlocking Agentic RL Training for GPT-OSS: A Practical Retrospective
📅 27 Jan 2026 • ⏱️ 20m • 📚 Deep Dive (4063 w)
Unlocking Agentic RL Training for GPT-OSS: A Practical Retrospective
📅 27 Jan 2026 | ⏱️ 20 min read (4063 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~20 mins left to finish
📖 0% read
💡 Key Takeaways
- It has been revealed that agentic reinforcement learning (RL) extends traditional LLM training by optimizing not just a single-turn response, but an entire decision-making process learned through direct interaction with an environment during training.
- Sources indicate that linkedIn is an AI-first tech giant that's built agents to help professionals be more successful.
- The GPT-OSS model has shown comparable performance to OpenAI o3-mini and o4-mini [ref], but its suitability for agentic reinforcement learning training has not yet been validated.
It has been revealed that agentic reinforcement learning (RL) extends traditional LLM training by optimizing not just a single-turn response, but an entire decision-making process learned through direct interaction with an environment during training. Unlike traditional single-turn reinforcement learning or offline preference-based methods that rely on static datasets, agentic RL trains policies by actively collecting on-policy data as the agent prepares actions, invokes tools, observes outcomes, and adapts its behavior over multi-step trajectories in either simulated or real environments. This interaction-driven optimization assigns credit across long-horizon decisions, where intermediate choices such as query reformulation, tool selection, and execution order directly influence downstream success. Training follows an iterative closed loop in which the agent interacts with the environment to collect rollout trajectories, computes rewards over these trajectories, updates the policy based on observed outcomes, and then uses the updated policy to drive the next round of interaction and data collection such as GRPO or PPO algorithms..
Sources indicate that linkedIn is an AI-first tech giant that's built agents to help professionals be more successful. In this setting, models must reason over incomplete information, interact with structured services, and adapt to evolving user intent across multiple steps rather than produce a single static response. These capabilities are especially critical for agents that support the goals of recruiters, job and knowledge seekers, and learners end customers, such as retrieving information, refining queries, coordinating tools, and executing multi-step workflows. By learning robust decision policies through interaction, agentic RL provides a principled foundation for building scalable, reliable, and adaptable AI systems through end-to-end optimization.
The GPT-OSS model has shown comparable performance to OpenAI o3-mini and o4-mini [ref], but its suitability for agentic reinforcement learning training has not yet been validated. Most recent work focuses on fine-tuning without tool calling, such as: Fine-tuning with gpt-oss and Hugging Face Transformers and unsloth tutorial: how to fine-tune gpt-oss. This blog explores the journey to unlock agentic RL training for GPT-OSS as a potential backbone model for agentic applications.
Sources indicate that in our experiments, we use verl as our training framework since it is one of the most popular adopted frameworks in the open source community. We use gsm8k, Retool task, verifiable instruction following task, which are commonly used in RL training. We focus on presenting experimental results for the GPT-OSS-20B model, and our attention-sink fix also works for GPT-OSS-120B. The Qwen-2.5-32B model is additionally used to benchmark standard metric trends during RL training.
It has been revealed that verl has been an OSS framework used by the team, and the team has previously collaborated and contributed to it to help democratize agentic reinforcement learning training. With the introduction of the fresh Harmony chat template in GPT-OSS, the first step is to ensure that the training framework fully supports the updated message format and conversation semantics required by Harmony. This step helps rollout generation, trajectory construction, and tool parsing remain consistent and correct under the new template.
The team uses ReTool as a representative example to verify code correctness. ReTool is an agentic coding task in which the model is asked to solve a math problem with the assistance of a code compiler tool. This setup allows the model to focus on core reasoning and algorithmic logic, while delegating the actual arithmetic and execution to the tool. During an episode, the model interacts with the code tool multiple times, using execution results as feedback to refine its solution. At the end of the trajectory, the model produces a final answer, on which the reward is computed.
During the initial training runs, we observed exploding KL divergence and entropy, along with non-increasing rewards, indicating underlying concerns in the GPT-OSS training setup, as shown in Figure 1.
Figure 1. Left: Qwen32b has significantly higher rewards compared to GPT-OSS 20B; Right: The gradient norm exploded as training progressed.
Sources indicate that figure 2. Non-zero importance sampling clip value even for on-policy training.
We focus on on-policy methods because they provide greater stability and more reliable convergence. The foundation of pure on-policy Proximal Policy Optimization (PPO) mandates that the importance sampling ratio must be exactly 1. The mathematical definition of the importance ratio is:.
ratio=π(a∣s)πold(a∣s) \text{ratio} = \frac{\pi(a \mid s)}{\pi_{\text{old}}(a \mid s)} ratio=πold(a∣s)π(a∣s).
This requirement ensures that the policy update is executed only on the data generated by the current policy π(a | s) = πold(a | s), preventing unintended clipping.
We have observed the non-zero clipping value in our ReTool training, as shown in Figure 2, stemming from a mismatch between the two log-probabilities:.
Root Cause: The Dual Forward Pass and MoE Architecture.
Prior to verl 0.3.0, the implementation relied on two separate forward passes (one to compute the current log_prob and one to retrieve the stored old_log_prob) for the same state-action pair.
In a Mixture of Experts (MoE) architecture like GPT-OSS, the gating network routes the input to different experts. Due to implementation factors (e.g., subtle floating-point differences or explicit stochasticity), the expert routing can differ slightly between the two passes. Readers who are interested can further read Stabilizing MoE Reinforcement Learning by Aligning Training and Inference Routers.
This difference in routing leads to:.
log(π(a∣s))≠log(πold(a∣s)) \log(\pi(a \mid s)) \neq \log(\pi_{\text{old}}(a \mid s)) log(π(a∣s))=log(πold(a∣s)).
The resulting ratio deviates from 1, falsely triggering the PPO clip and violating the core on-policy assumption.
Solution: Enforcing Ratio = 1 via Log-Probability Substitution.
The fix resolves the problem by logically overriding the flawed computation when the environment is known to be on-policy (i.e., when the minibatch size equals the global batch size):.
By setting old_log_prob equal to the newly computed log_prob (detached to prevent gradient flow through the reference value), the importance ratio is mathematically forced back to 1. This strategy bypasses the instability caused by MoE's non-deterministic routing and guarantees strict on-policy behavior during PPO training.
Although fixing the log-probability mismatch reduced the importance-sampling clip ratio to zero, gradient norms continued to explode and rewards failed to improve. To isolate the issue, we simplified training to GSM8K, a single-step task without agentic tool use. The same instability persisted, as shown in the green curves in Figure 3, indicating a fundamental issue in basic RL training with GPT-OSS under verl.
We hypothesize that training–inference mismatch could be a potential cause: discrepancies between inference-time execution—where engines such as vLLM and SGLang aggressively optimize for throughput—and training-time execution under FSDP, which prioritizes numerical precision and stability, can effectively turn otherwise on-policy RL into off-policy optimization.
Sources indicate that this blog details why such mismatches lead to unstable gradients and non-improving rewards. Figure 3 compares training runs with and without rollout correction (see this verl blog for details). After applying rollout correction, training dynamics improve significantly, with gradient norms remaining stable rather than exploding.
However, as shown in the left plot of Figure 4, the reward increases only modestly, and convergence on the simple GSM8K task remains substantially slower compared to smaller dense model variants.
In a recent development, figure 3. Gradient norm behavior under different training configurations. Green: Training without rollout correction, exhibiting unstable gradients. Red: Training with the attention layer frozen to isolate the glitch to the attention mechanism, resulting in partial stabilization. Blue: Training with rollout correction enabled (sequence-level importance sampling), yielding stable gradient norms.
Recent findings suggest that figure 4. Left: Reward improvement on GSM8K remains slow even after applying rollout correction, with performance comparable to runs where the attention layer is frozen during training. Right: A substantial log-ppl mismatch is observed between the inference engine (SGLang with Triton kernels supporting attention-sink forward passes) and the training stack (FSDP with FlashAttention-v2), indicating a large training–inference inconsistency.
Sources indicate that to further isolate the root cause, we freeze the attention layers during training and observe reward dynamics similar to those of runs without freezing (blue curve vs yellow curve in Figure 4). This indicates that learning is primarily driven by the MoE layers, while the attention mechanism contributes less effectively than expected. In addition, we observe a substantial token-level probability mismatch between the inference engine and the distributed training stack which are using different attention kernels. Together, these observations motivate a deeper investigation into the attention mechanism.
Attention sinks used in GPT-OSS are learnable scalar parameters (one per attention head) that act as "virtual tokens" in the softmax computation. They allow the model to allocate attention mass to a learned sink rather than forcing all attention to content tokens, which has been shown to improve attention stability in streaming inference and training with sliding-window attention.
After a deeper investigation, we identified several major complications:.
Key difference: The sink participates in softmax normalization but doesn't contribute to the output.
The attention weight for content token j in row i is defined as:.
Pij=exp(Sij)∑j′=1Nkexp(Sij′)+exp(Sh) P_{ij} = \frac{\exp(S_{ij})} {\sum_{j'=1}^{N_k} \exp(S_{ij'}) + \exp(S_h)} Pij=∑j′=1Nkexp(Sij′)+exp(Sh)exp(Sij).
The sink probability is computed but not used in the output:.
Pi,h=exp(Sh)∑j′=1Nkexp(Sij′)+exp(Sh) P_{i,h} = \frac{\exp(S_h)} {\sum_{j'=1}^{N_k} \exp(S_{ij'}) + \exp(S_h)} Pi,h=∑j′=1Nkexp(Sij′)+exp(Sh)exp(Sh).
The gradient of the loss L with respect to the sink parameter Sh is:.
∂L∂Sh=−∑iPi,h(∂L∂Si,h−∑j∈{1,…,Nk}Pij∂L∂Sij) \frac{\partial L}{\partial S_h} = - \sum_i P_{i,h} \left( \frac{\partial L}{\partial S_{i,h}} - \sum_{j \in \{1,\ldots,N_k\}} P_{ij} \frac{\partial L}{\partial S_{ij}} \right) ∂Sh∂L=−i∑Pi,h∂Si,h∂L−j∈{1,…,Nk}∑Pij∂Sij∂L.
Since the sink is computed but not used in the output, its gradient ∂L/∂Si,h = 0.
Therefore, the backward equation simplifies to:.
∂L∂Sh=−∑iPi,h(∑j∈{1,…,Nk}Pij∂L∂Sij) \frac{\partial L}{\partial S_h} = - \sum_i P_{i,h} \left( \sum_{j \in \{1,\ldots,N_k\}} P_{ij} \frac{\partial L}{\partial S_{ij}} \right) ∂Sh∂L=−i∑Pi,hj∈{1,…,Nk}∑Pij∂Sij∂L.
In a recent development, the forward pass was adapted from vLLM's FlashAttention fork, and we implemented the backward pass to compute gradients for the sink parameters. The implementation will be released following the internal review process.
According to recent reports, after applying the fix in FlashAttention v3, we observe substantially faster convergence for GPT-OSS-20B across a range of reinforcement learning tasks. These include single-turn RL on math reasoning (GSM8K — red curve in Figure 5), instruction following (VerifyIf, evaluated on an out-of-domain multi-if benchmark — Figure 6), and multi-turn agentic RL with tool use (ReTool — Figure 7).
Across all settings, training becomes stable and exhibits steady reward improvement.
Figure 5.. Single Turn GSM8K, the red curve converges much faster than the rest without the fix.
Figure 6. On verifiable instruction following the task, the run without the fix collapsed (blue), and the run with fix showed steady reward improvement.
In a recent development, figure 7. On the Retool task, the run with fix revealed steady reward improvement and no gradient exploding (fa2 is the flash attention 2 without the fix while fa3 is the flash attention 3 with the fix). After the fix, the validation accuracy score goes up now.
One issue we consistently encountered was excessive memory allocation during the FSDP forward pass, which led to repeated out-of-memory (OOM) failures when training GPT-OSS-20B bf16 models on 16 H200 nodes (max response length: 16k, prompt length: 8k). This behavior is highly unexpected for a 20B-parameter MoE model.
We identified the concern as originating from two different implementations of the MoE forward path in Hugging Face Transformers. This issue has also been reported by other users: https://github.com/huggingface/transformers/complications/40073; When verl computes log-probabilities under FSDP, the inference forward path is triggered. In the current Hugging Face implementation, this path duplicates hidden states for all experts and performs batched matrix multiplication, materializing extremely large tensors in GPU memory. By contrast, the training forward path uses a for-loop to process each expert sequentially and then combines the results. While slower, this approach is significantly more memory efficient.
We patched the Hugging Face implementation to use a more memory-efficient execution path, avoiding repeated materialization of experts.
According to recent reports, agentic RL requires the agent to interact with the environment over multiple steps while maintaining an ever-expanding context. Observations and environment feedback from each step are appended to the context and used as input for subsequent decision-making, which introduces significant challenges for memory efficiency and scalability during training.
Industry observers note that under fully sharded data parallelism (FSDP), model parameters, optimizer states, and gradients are sharded across the entire world size (i.e., all GPUs in the training cluster). Each GPU stores and updates only its assigned parameter shards, while rollout data are replicated across all GPUs—meaning every GPU processes the full agent interaction history for each rollout.
Industry observers note that during the forward pass, when computation reaches a layer whose parameters are not locally available, an all_gather operation is triggered to materialize the full parameters across GPUs. During the backward pass, a corresponding reduce_scatter operation aggregates gradients and ensures that each GPU retains only its local shard. This provides a degree of scaling: as the number of GPUs increases, the per-GPU memory footprint decreases.
FSDP provides model-level scaling by sharding model parameters, gradients, and optimizer states across GPUs. Sequence parallelism (or context parallelism) further reduces per-GPU memory consumption by partitioning the input sequence across devices, thereby lowering the peak activation memory on each GPU.
As the number of sequence-parallel dimensions increases, the maximum activation memory per GPU correspondingly decreases. We have implemented sequence parallelism to be attention-sink-aware and compatible with FlashAttention v3 (Figure 8, right).
Figure 8. Left: Inference without sequence parallelism. Right: Inference with sequence parallelism, where additional all-to-all communication is performed before and after the attention layer. This partitions the sequence across parallel workers and reduces the peak memory footprint of attention computation by a factor proportional to the sequence-parallelism degree.
Sequence parallelism scales along the sequence dimension to reduce the per-GPU activation footprint. Input tokens from all sequences are packed into a single contiguous list by removing padding tokens, while position IDs are used to distinguish tokens belonging to different sequences. This design naturally benefits from FlashAttention’s variable-length support. For sequence parallelism, layers other than the attention layer do not have inter-position dependencies; therefore, they do not require each GPU to hold a complete sequence shard, and no additional communication is needed for these layers.
The attention layer, however, requires all tokens belonging to the same sequence to be present on the same GPU in order to compute attention weights correctly. To satisfy this constraint, an all-to-all communication is performed to gather sequence elements, with the split performed at the attention-head level. This design avoids communication within the attention computation itself, which would otherwise be prohibitively expensive. After the attention layer, a single all-to-all communication redistributes the outputs back to their original sequence-parallel layout, after which the remaining non-attention layers can proceed without further synchronization.
Our journey to enable agentic RL training for the GPT-OSS backbone model was a practical retrospective, highlighting that unlocking advanced capabilities in open-source LLMs requires meticulous, deep-dive engineering.
We made contributions that transformed the viability of GPT-OSS for agentic applications, specifically by:.
Stabilizing PPO: We contributed a fix to restore on-policy integrity, overriding the log-probability mismatch caused by the MoE architecture’s non-determinism (Figure 2).
Enabling Attention Sink Support: We successfully implemented and integrated the attention sink backward pass into FlashAttention v3, correcting the catastrophic training–inference mismatch that had previously caused instability and slow convergence (Figures 5, 6, and 7).
Scaling Memory Efficiency: We introduced crucial memory optimizations, including patching the MoE materialization process and integrating sequence parallelism with the upcoming attention sink support, enabling training with the long context windows essential for multi-step agents (Figure 8).
These engineering efforts validate GPT-OSS as a scalable and high-performance backbone for building the next generation of intelligent, multi-step decision-making agents.
Thanks to Deepak Agarwal, Bee-Chung Chen, Animesh Singh, Gungor Polatkan, Balaji Krishnapuram, and Jitendra Agarwal for their leadership support.
Feng, Jiazhan, et al. Retool: Reinforcement Learning for Strategic Tool Use in LLMs. arXiv preprint arXiv:2504.11536 (2025).
Xiao, Guangxuan, et al. Efficient Streaming Language Models with Attention Sinks. arXiv preprint arXiv:2309.17453 (2023).
When Speed Kills Stability: Demystifying RL Collapse from the Training–Inference Mismatch.https://yingru.notion.site/When-Speed-Kills-Stability-Demystifying-RL-Collapse-from-the-Training-Inference-Mismatch-271211a558b7808d8b12d403fd15edda.
Recent findings suggest that thank you for this detailed retrospective on enabling agentic RL training for GPT-OSS. The article clearly documents key challenges and practical solutions. I have a few questions and observations that might help clarify some aspects.
Mathematical Clarification on Attention Sink Gradient.
It has been revealed that regarding the attention sink backward pass derivation (Section 4), I'd appreciate clarification on the notation and justification. The article presents the general formula: ∂L/∂S_h = -Σ_i P_{i,h} (∂L/∂S_{i,h} - Σ_{j∈{1,...,N_k}} P_{ij} ∂L/∂S_{ij}). Then states that ∂L/∂S_{i,h} = 0 because "the sink is computed but not used in the output," leading to the simplified form: ∂L/∂S_h = -Σ_i P_{i,h} (Σ_j P_{ij} ∂L/∂S_{ij}).
I believe the final formula is correct, but the notation ∂L/∂S_{i,h} is unclear. If this refers to the gradient of the loss with respect to the sink's contribution to the output at position i (i.e., ∂L/∂(P_{i,h} V_sink)), then indeed it would be zero since there's no V_sink term. However, the sink parameter S_h itself does affect the output through softmax normalization: P_{ij} = exp(S_{ij}) / (Σ_{j'} exp(S_{ij'}) + exp(S_h)). When S_h changes, all P_{ij} change, affecting O_i = Σ_j P_{ij} V_j. The gradient ∂L/∂S_h is non-zero and flows through this normalization.
According to recent reports, could you clarify what ∂L/∂S_{i,h} represents in your notation? Also, could you provide the full derivation showing how you arrive at the final form from the chain rule through the softmax operation? A step-by-step derivation would help readers verify the implementation and understand how the gradient flows through the attention mechanism.
On-Policy Fix: Clarification Needed.
Sources indicate that the solution for the MoE log-probability mismatch (Section 2) sets old_log_prob = log_prob.detach() when on_policy=True. While this mathematically forces the importance sampling ratio to 1, I'm curious about the implications. If the policy parameters change between rollout collection and the training step (even slightly), this fix would still assume ratio = 1. How do you ensure true on-policy conditions? Do you collect rollouts and train in the same step, or is there a mechanism to detect policy drift?
Sources indicate that have you considered storing the actual routing decisions during rollout to ensure deterministic replay, or using deterministic routing during training? This might address the root cause rather than working around it. Also, the fix only applies when on_policy=True. How do you handle cases where the policy has drifted? Is there a threshold or mechanism to detect when to switch to off-policy mode?
Several aspects would benefit from additional detail. Which fix had the largest impact? Are all three fixes necessary, or would fixing attention sinks alone have been sufficient? A table showing results with/without each fix would be very helpful. You mention the fixes work for GPT-OSS-120B, but no experimental results are shown. Could you share learning curves or metrics for the 120B model?
According to recent reports, the article mentions both vLLM and SGLang. Which engine is used for rollouts in the final experiments? If different engines are used for different experiments, how does this affect the training-inference mismatch analysis? You also reference "rollout correction (sequence-level importance sampling)" and mention "this verl blog," but the details aren't explained. Could you clarify what this correction does and how it relates to the attention sink fix?
Implementation and Reproducibility.
The article mentions that "The implementation will be released following the internal review process." For reproducibility and verification, it would be valuable to know an approximate timeline for release, whether the backward pass implementation will be contributed to the main FlashAttention repository, and if there are any interim workarounds or partial implementations that could be shared.
It has been revealed that despite these questions, the article makes valuable contributions. It clearly identifies real-world challenges with MoE + RL training, documents the engineering journey transparently, reveals substantial improvements in training stability, and raises awareness of training-inference mismatch issues. The fixes appear to work well for your use case, and the results demonstrate clear improvements. My questions are aimed at understanding the details better and ensuring the solutions are robust and reproducible.
Thank you again for sharing this work with the community!
Hi @sseymens Thank you for your comments.I can help to reply your question about MOE on policy part.
Thank you for taking the time to reply and for clarifying the MoE/on-policy part—that helps a lot.
What you noted (and how I'm reading it):.
You confirmed that forcing old_log_prob = log_prob.detach() does not resolve the on-policy issue: the evaluation uses the current policy π(a|s), but the sampling distribution can still differ because expert selection at rollout time can differ from the training forward pass. Forcing the importance ratio to 1 in the PPO formula therefore doesn't fix the underlying problem—the data can still be effectively off-policy. I agree with that distinction.
You clarified the debugging sequence: root cause was unknown at first; you hypothesized inference–training inconsistency; importance sampling (rollout correction) didn't fix it; then you tried forcing the detach as a hypothesis test to see whether the MoE log-prob mismatch was the cause. That makes it clear the detach was diagnostic, not the actual fix.
You noted that expert router replay wasn't available in verl when you were debugging; you've since tested it (Stabilizing MoE RL, arxiv 2510.11370) and it was not the root cause—the root cause is attention sink. That fits the story: the real mismatch is at the attention layer (training on FA2 without sink support vs. inference on sink-aware kernels), so token-level log-probs diverge between rollout and training. That explains why rollout correction alone didn't fix things (it corrects at sequence level but not at the attention computation) and why freezing attention gave similar reward curves (attention wasn't learning correctly without the sink backward). I'm satisfied on the on-policy/MoE part.
What wasn't addressed: You addressed the MoE/on-policy part; the following from my original comment were not covered. If you have bandwidth, they would help for implementation and reproducibility:.
The article gives the general form∂L/∂S_h = -Σ_i P_{i,h} (∂L/∂S_{i,h} - Σ_j P_{ij} ∂L/∂S_{ij}),then states that ∂L/∂S_{i,h} = 0 because "the sink is computed but not used in the output," yielding∂L/∂S_h = -Σ_i P_{i,h} Σ_j P_{ij} ∂L/∂S_{ij}.
For implementers, two things would help:.
Definition of ∂L/∂S_{i,h}: In the extended softmax, the logits are (S_{i,1}, …, S_{i,N_k}, S_h). The output is O_i = Σ_j P_{ij} V_j with no V_sink term, so the sink affects O_i only through the normalization Z_i = Σ_{j'} exp(S_{ij'}) + exp(S_h). The direct contribution of the sink to the output (e.g. a P_{i,h} V_sink term) is therefore zero, so ∂L/∂S_{i,h} in that sense is 0. If ∂L/∂S_{i,h} is defined differently in your derivation, a one-sentence definition in the article would remove ambiguity.
Chain rule through softmax: A short derivation showing how ∂L/∂S_h is obtained from ∂L/∂P_{ij} (and possibly ∂L/∂O_i) via ∂P_{ij}/∂S_h and ∂P_{i,h}/∂S_h would let readers verify the sign and aggregation over query positions i and match it to the FlashAttention backward API.
To reproduce and extend the results, it would be helpful to have:.
Ablation: Was the FA3 + sink backward sufficient for stable training (with MoE materialization and sequence parallelism only for correctness/memory), or did you still rely on rollout correction or the on-policy detach in the final runs? A small table (e.g. FA2 vs FA3+sink, with/without rollout correction) would make the relative impact clear.
Rollout engine: The article mentions both vLLM and SGLang; Figure 4 references SGLang with Triton kernels for the sink forward. Which engine was used for rollouts in the final experiments (Figures 5–7), and was it the same across GSM8K, VerifyIf, and ReTool? This matters for training–inference consistency.
Rollout correction vs sink fix: A one-sentence summary of what "rollout correction" (sequence-level importance sampling) does in your pipeline and whether it is still enabled in the FA3+sink runs would clarify how the two mechanisms interact.
GPT-OSS-120B: You mention the sink fix also works for 120B; any learning curves or metrics (even high-level) would be valuable for scaling.
For verification and adoption: any update on timeline for releasing the sink backward implementation, whether you blueprint to contribute it to the main FlashAttention repo or keep it in a fork, and whether there are interim options (e.g. a reference PyTorch implementation or a patch description) would help the community reproduce the results and align training with inference.
Thanks again for the clarification; the narrative (hypothesis testing → rollout correction → attention sink as root cause) is much clearer, and the work is clearly valuable for agentic RL on GPT-OSS.
Will you release the weights of the gpt-oss-agentic models you trained? I'm sure they'd be very popular.
Sources indicate that hello, thank you for your work and for explaining the changes required. Are these changes merged to verl and FlashAttention V3?
Legend of Figure 1: Left/Right mixup.
General
⚖️ Neutral
🌐 Sitepoint
#11338. How to Use Developer Time Tracking Data to Improve Sprint Planning and Estimates
📅 10 Nov 2026 • ⏱️ 11m • 📚 Deep Dive (2203 w)
How to Use Developer Time Tracking Data to Improve Sprint Planning and Estimates
📅 10 Nov 2026 | ⏱️ 11 min read (2203 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~11 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- Sources indicate that 7 Day Free Trial.
- Sprint estimates usually fail because development teams heavily rely on memory and assumptions instead of evidence.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Weekly. Free. One click to leave.
Sources indicate that 7 Day Free Trial. Cancel Anytime.
Sprint estimates usually fail because development teams heavily rely on memory and assumptions instead of evidence. They assume similar tasks will take the same amount of time. Based on these half-baked assumptions, most managers plan around ideal sprint working hours. The backlog then fills with commitments that look realistic on paper but often end up delayed.
Recent findings suggest that actual development rarely follows that plan. There are always unexpected bugs and task dependencies that consume more time than teams account for in their estimates. Even the buffer time set aside for unexpected work may not be enough. This causes tasks to take longer than expected and pushes sprint commitments behind schedule.
Developer time tracking helps teams make better estimates with historical data. It highlights how long previous tasks actually took, which provides managers with an evidence-based reference when they are planning similar work.
Reviewing this data before committing to a sprint scope turns estimation from guesswork into an evidence-based process.
Industry observers note that historical time data offers deeper insights, depending on how you collect and analyze it. Most importantly, it explains why planned work took longer than expected.
Before sprint planning, the following records should be reviewed.
Completed task duration: Check the time spent on finished tasks. Managers should compare similar work to understand typical development effort.
Actual versus estimated hours: Management should observe and identify differences between planned and recorded hours. If there are repeated delays, to some extent, it indicates inaccurate estimates.
Carryover work: Review unfinished tasks from previous sprints. Determine whether poor estimates or external delays caused the spillover..
According to recent reports, interruptions: Measure time spent on urgent requests and production problems. These activities reduce the development capacity that you had planned earlier.
Meetings and ceremonies: Review the time being spent on planning sessions and sprint reviews.
Bug-fix time: Examine hours spent resolving defects. You can also compare it to the time for developing new features.
Blocked tasks: Managers should account for the tasks delayed by missing approvals or technical dependencies.
Recent findings suggest that capacity differences: Compare team availability across sprints. Include leave and staffing changes in that time as well.
These records provide the most value when reviewed together. For example, a task may finish three days late even if the development work stayed within its estimated hours. The actual issue could be an external dependency.
Teams should understand these differences before using historical data to estimate future work.
Historical records provide a useful starting point for estimating new tasks. However, teams must interpret the data rather than simply copy previous estimates.
The following approaches can improve estimation accuracy.
The first step is to consider completed tasks that resemble upcoming work. Managers should compare their requirements and technical complexity. Moreover, the development environment should be considered.
It has been revealed that for example, suppose a team needs to estimate a new API integration. Three previous integrations required 12, 15, and 18 hours of active work.
The average is 15 hours. This gives developers a reference point for the new estimate.
However, the average doesn't tell the entire story. The latest integration may involve unfamiliar authentication methods or more complicated testing.
Review the reasons behind differences in previous task durations. Check whether developers encountered unexpected bugs or unclear requirements.
As a project manager, I'd consider these details before estimating for the next project. In my experience, they provide more context than an average alone.
Inaccurate estimates can happen; it doesn’t mean that there is a definite planning problem. However, repeated overruns across similar tasks may reveal an underlying issue.
Research suggests the pattern is widespread. A review of software estimation surveys reports that 60–80% of software projects encounter effort overruns, with the average overrun falling between 30% and 40%.
Start by calculating the difference between estimated and actual effort. Here is the formula for it.
Estimation variance (%) = [(Actual hours − Estimated hours) ÷ Estimated hours] × 100.
It has been revealed that suppose a task was estimated at 10 hours but needed 14 hours. The actual effort exceeded the estimate by 40%.
You can compare the results across similar tasks.
Sources indicate that for example, database migrations may repeatedly require more time than expected. This means that the team might be overlooking data validation or additional testing. Once the cause is clear, adjust future estimates accordingly.
Avoid increasing every estimate by the same percentage. Different types of work involve different risks. Teams can also break large tasks into smaller parts. This makes hidden development activities easier to identify.
The aim is to correct recurring estimation errors without unnecessarily increasing the entire sprint backlog.
Task duration doesn't always reflect the hours spent developing a feature.
It has been revealed that A study of developer workdays by Meyer and colleagues, which tracked 2,197 hours of activity across 20 developers, found that coding accounted for around 21% of the typical day. Collaborative work such as meetings and email took up roughly 24%.
Consider a developer who starts a feature on Monday and finishes it on Wednesday. The task took three days to complete. This is pretty straightforward, and the estimation could be based on it; however, the developer may have spent several hours in meetings. Other than that, urgent support requests could also have consumed additional time.
According to recent reports, the actual development effort could be much lower than three full working days. This distinction matters during estimation.
Teams should record focused development time separately from interruptions. They should also track waiting periods caused by blocked tasks. A more appropriate approach would be to use active development hours to estimate similar future work. They should also account for recurring interruptions when calculating sprint capacity.
For example, a task may regularly wait for security approval. Adding more development hours to its estimate won't resolve that delay.
Instead, the team should recognize the dependency and consider its effect on delivery.
If managers are able to separate these activities, it will help create better estimates without confusing effort with elapsed time.
A precise estimate can create false confidence when a task involves substantial uncertainty.
Suppose similar tasks previously required between 12 and 20 hours. If you estimate the next task at exactly 14 hours, it will overlook vital differences.
A range of 12–20 hours provides a clearer picture of the possible effort. Developers can then discuss what might push the task toward either end of the range.
For example, the lower estimate can be directly applied to integration, and the upper estimate might be considered for unfamiliar code or additional testing.
In such scenarios, if the requirements stay unclear, consider a short technical investigation before finalizing the estimate. This can help identify dependencies and reduce uncertainty.
Industry observers note that however, estimate ranges should still support practical planning decisions. Teams need to determine how much capacity to reserve for the work.
Choose a planning assumption that reflects the task's risk and available capacity.
As developers learn more about the task, they can refine the estimate.
According to recent reports, historical time data should affect how much work a team accepts during sprint planning. Better estimates offer little value if teams continue making unrealistic commitments.
Reduce Scope After Repeated Overruns.
It has been revealed that if several sprints end with unfinished tasks, it is best that you first review why the team missed its commitments in the first place. Once you have identified the causes, use those findings to reduce the next sprint's scope.
Teams should prioritize work that supports the sprint goal. Moreover, avoid adding extra tasks just because they appear manageable during planning.
Reserve Capacity for Unplanned Work.
In a recent development, production incidents and urgent requests can disrupt planned development. To get more reliable estimations, review how much time these activities consumed in previous sprints. Then reserve an appropriate amount of capacity.
Adjust for Complexity and Dependencies.
Sources indicate that historical estimates become less reliable in case unfamiliar technology or additional dependencies are involved. It is best to break complex tasks into smaller components where possible. This helps developers assess the work more accurately.
Nominal capacity represents scheduled working hours, whereas actual capacity reflects the time available after accounting for other commitments.
The Scrum Guide identifies previous performance and upcoming capacity as vital inputs to sprint forecasting.
When you are selecting backlog items, consider both. Additionally, avoid committing every available hour or deducting the same interruption twice.
According to recent reports, historical time data is useful for sprint planning. Most development teams already use project management tools that include basic time tracking features.
Sources indicate that however, these tools don't always break down how developers spend their working hours. For clearer time data, a feature-specific time tracker is more useful because it provides more details about tasks and workloads.
According to recent reports, timeBee is one such developer time tracking tool I've used. It tracks working hours and time spent on projects and tasks. It also provides attendance records and workforce activity reports.
With this data, teams can review how much time previous tasks required. For example, developers can record hours spent building a feature. They can also track debugging and revisions separately. Later, managers can compare these records with the original estimates. This helps them plan similar work more accurately.
According to recent reports, timeBee also tracks website and application activity. These reports can help teams understand how working hours are distributed.
According to recent reports, however, not all activities reflect actual development effort. Sometimes a developer just spends time reviewing documentation or discussing technical problems. Such work may not always appear in TimeBee as active computer use.
Industry observers note that apart from that, attendance, leave, and overtime records from TimeBee can help managers calculate sprint capacity. They can review developer availability before deciding how much work to include in the next sprint.
One thing to remember is that developer time tracking should help teams understand workload patterns. It shouldn't be used to monitor every minute of a developer's day. Management should be careful that the aim is to improve estimates and make more realistic sprint commitments.
Sprint retrospectives should include a review of how the planning is going. If you have made a initiative, it doesn’t mean you cannot make changes to it. During sprints, keep comparing original estimates with actual task hours. Track your unfinished work for recurring delays.
Ask developers what caused significant differences. Some tasks may have required additional testing. Others may have been delayed by dependencies. Select one specific improvement for the next sprint.
Not every estimation difference indicates a planning failure. Unexpected technical challenges are part of software development.
The objective is to improve forecasts over time rather than eliminate every variance.
Historical time data provides a more stable foundation for sprint planning. Developer time tracking helps teams understand what is actually happening within the sprint rather than creating unnecessary pressure for them.
Other than that, the data also reveals how interruptions affect available development hours.
However, time data should guide planning rather than dictate it.
1. What is the difference between sprint velocity and time-based capacity planning?
In a recent development, sprint velocity measures how much work a team has completed during a sprint. It is usually measured in story points. Contrary to this, time-based capacity planning calculates the hours available for planned work. It accounts for meetings and other responsibilities.
Velocity helps predict future delivery based on past performance. Capacity planning shows whether the team has enough time to meet its commitments.
According to recent reports, 2. Which time tracking metrics are most useful for improving Agile sprint forecasts? The most useful metrics include estimated versus actual hours, task completion time, and unplanned work.
Bug-fix time, rework, and blocked tasks also provide valuable insights. Teams should also review available capacity across previous sprints.
Sources indicate that these metrics help sort out recurring delays and estimation errors. They allow teams to forecast workloads more accurately and make realistic sprint commitments.
Recent findings suggest that **3. How can development teams improve estimates when historical time tracking data is incomplete? **.
According to recent reports, teams can start with available task records and completed sprint backlogs. Developer feedback can help fill information gaps. Similar tasks from previous projects may also provide useful estimates.
Recent findings suggest that when data is limited, teams should use estimate ranges instead of fixed hours. Consistent time tracking in future sprints will gradually provide more reliable planning data.
According to recent reports, 4. How can time tracking data help balance workloads across developers during sprint planning?
Recent findings suggest that time tracking data shows how much time developers spend on assigned tasks and other responsibilities. Managers can review these records to identify uneven workloads. They can then distribute upcoming tasks based on available capacity.
Recent findings suggest that technical expertise and task complexity should also influence assignments. This helps prevent over commitment and supports a more balanced workload across the development team.
In a recent development, 7 Day Free Trial. Cancel Anytime.

AI & Tech
⚖️ Neutral
🌐 9to5google
#11337. Tech Report: Google and Adobe partner to add app integration in Google Drive, Gemini
📅 10 Nov 2026 • ⏱️ 2m • 📖 Standard (347 w)
Tech Report: Google and Adobe partner to add app integration in Google Drive, Gemini
📅 10 Nov 2026 | ⏱️ 2 min read (347 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Google Drive will soon prompt consumers to switch to Adobe Acrobat while viewing PDFs, and Gemini will get a few new tricks powered by the tech giant’s creative suite.
- The pipeline from PDFs opened in Google Drive and Gmail to Adobe Acrobat is notoriously strained.
- Google announced prepares to ease the process.
Google Drive will soon prompt consumers to switch to Adobe Acrobat while viewing PDFs, and Gemini will get a few new tricks powered by the tech giant’s creative suite.
The pipeline from PDFs opened in Google Drive and Gmail to Adobe Acrobat is notoriously strained. That goes for any PDF viewer, but as soon as certain tools are necessary, a large number of people rely on Adobe’s products to edit and store documents.
Google announced prepares to ease the process. According to a press release today, Google will be adding a “direct pathway” from Google Drive and Gmail in Adobe Acrobat. Acrobat will be suggested to users within the services, which will likely act as a quick transfer sort of feature. It doesn’t seem to indicate users will see any Adobe PDF editing tools within Google Drive. Google Drive has notoriously fallen short in this regard.
Industry observers note that the partnership announcement also means Gemini will get access to some of Adobe’s creative tools. Further detail isn’t clear, but that includes Gemini, Gemini Enterprise, and Google AI Mode in Search. It sounds like the integration will allow users to edit or manage PDFs and other files straight from Google’s AI interfaces.
Industry observers note that it’s not just PDFs and Google Drive; Adobe’s Photoshop gets a shout, too. Expected sometimes in the future, we may see more powerful image editing powered by Gemini within Adobe Photoshop, as opposed to the current models and limitations within. Gemini Nano Banana models are right now in use, but AI generation and editing could go further with a more focused effort. Google claims the push “could enable near-real-time edits,” but there’s no concrete timeline set for when we could see that.
That goes for each of these byproducts of the new partnership. Google Drive and Gmail integration with Adobe Acrobat will likely be the first to roll out, with Gemini features to follow shortly after.
According to recent reports, FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11336. AI can act exactly like a human, but we still don't think it's conscious
📅 14 Oct 2026 • ⏱️ 4m • 📚 Deep Dive (873 w)
AI can act exactly like a human, but we still don't think it's conscious
📅 14 Oct 2026 | ⏱️ 4 min read (873 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- Even when artificial intelligence behaves exactly like a human, people are reluctant to consider it conscious, according to a new study from Ludwig Maximilian University of Munich (LMU).
- Industry observers note that as artificial intelligence becomes more advanced, reports of AI systems misleading people, working together, or appearing to pursue independent goals are becoming increasingly common.
- Latest research from LMU suggests that people make a clear distinction between displaying intelligent behavior and possessing a conscious mind, even when humans and AI act in precisely the same way.
Even when artificial intelligence behaves exactly like a human, people are reluctant to consider it conscious, according to a new study from Ludwig Maximilian University of Munich (LMU).
Industry observers note that as artificial intelligence becomes more advanced, reports of AI systems misleading people, working together, or appearing to pursue independent goals are becoming increasingly common. These behaviors often lead people to describe AI as though it can think, feel, or make decisions for itself. But does behaving like a human actually convince people that a machine has consciousness?
Latest research from LMU suggests that people make a clear distinction between displaying intelligent behavior and possessing a conscious mind, even when humans and AI act in precisely the same way.
How Scientists Tested Perceptions of AI Consciousness.
According to recent reports, published in the journal Cognition, the study was led by Dr. Louis Longin of LMU's Chair of Philosophy of Mind, working alongside Dr. Bahador Bahrami, Professor Ophelia Deroy, and other researchers.
"Whereas previous studies have typically asked general questions about whether AI actually has mental states, our study is the first to directly compare how people attribute the same mental states to AI and humans behaving in exactly the same way, under identical circumstances," states Longin.
"We may be using mental terms to refer to AI, but this may only be because we lack better words," notes Ophelia Deroy, philosopher and a senior author of the study. "After all, AI is trained to act and speak like a human, so these descriptions seem natural.".
Sources indicate that to investigate how people judge consciousness, the researchers conducted experiments involving nearly 1,100 participants. One group read brief descriptions of artificial agents that highlighted different levels of responsiveness to their environments. For example, some agents reacted to sounds or recognized the emotional states of others.
Another group encountered the same situations, except the characters were described as humans rather than AI systems. Participants then evaluated how conscious or aware each character seemed to be of its surroundings.
A Surprising Gap Between Human and AI Consciousness.
The experiments revealed that responsiveness influenced how participants judged both humans and artificial intelligence. Characters that reacted more actively to their surroundings were generally considered more conscious and more aware.
Recent findings suggest that however, a striking difference emerged when participants evaluated consciousness specifically. Even the most responsive AI was rated as less conscious than the least responsive human. In other words, identical behavior did not lead people to assign the same level of consciousness to humans and machines.
The results changed considerably when participants were asked about awareness instead. For this characteristic, judgments of humans and AI followed largely similar patterns, suggesting that people interpret awareness and consciousness in fundamentally different ways.
"There is a growing worry in public discussion that people will see AI behaving in a human-like way and start treating these systems as if they had human-like mental states," indicates Longin, lead author of the study. "We found something much more nuanced: People are quite willing to say that an AI notices things and is aware of its surroundings. But they clearly draw a line when it comes to the term 'consciousness'. People consistently attribute less consciousness to AI than humans -- even when their behavior is identical.".
Although people sometimes describe AI as conscious when discussing its actions, the findings indicate that they still distinguish between artificial systems and human minds.
Why One Word Changes How We Perceive AI.
The researchers believe the difference between consciousness and awareness offers an vital insight into how people understand artificial intelligence.
Sources indicate that awareness is a relatively neutral term that can describe an agent's ability to detect and respond to information in its environment. Consciousness, however, carries deeper implications about subjective experience and what it means to have an inner mental life.
Sources indicate that because awareness focuses more directly on observable behavior, people appear comfortable applying it to both humans and AI. Consciousness carries a different meaning, leading people to judge the two much less similarly.
The findings also highlight why the language used to discuss artificial intelligence matters, particularly as AI systems become increasingly capable of producing convincing human behavior.
Industry observers note that "Our study teaches us lessons for how we communicate about AI," says Bahador Bahrami, who is also a senior author of the study and an expert in social neuroscience. "Companies and journalists often reach for hyped descriptions of AI models, and credit them with intentions, prepares, or even moral conscience and hesitation. What our study indicates is that everyday judgments are much more discriminating: People do not simply put AI and humans on the same mental scale. But the boundary also depends on which terms we use. For more neutral descriptors such as 'awareness', the distinction can largely disappear. That makes our choice of language important.".
Materials provided by Ludwig-Maximilians-Universität München. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Fresh Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
Business & Policy
⚖️ Neutral
🌐 Tomshardware
#11335. Weeks after shipment was swiped by China, Pentagon ‘struggles to account for’ $31 billion in missing F-35 aircraft parts
📅 14 Nov 2026 • ⏱️ 3m • 📚 Deep Dive (539 w)
Weeks after shipment was swiped by China, Pentagon ‘struggles to account for’ $31 billion in missing F-35 aircraft parts
📅 14 Nov 2026 | ⏱️ 3 min read (539 words, 📚 Deep Dive) | Source: Tomshardware
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that the Pentagon is struggling to track an astonishing 26 million F-35 warfighter parts, worth an estimated $31 billion, according to analysis published by the Government Accountability Office (GAO) this week.
- Recent findings suggest that inventory problems have been a long-standing feature of the deployment of the F-35, notes the source.
- Chief among the issues that need to be addressed is the headlining massive unmonitored pool of roughly 26 million spare parts.
Sources indicate that the Pentagon is struggling to track an astonishing 26 million F-35 warfighter parts, worth an estimated $31 billion, according to analysis published by the Government Accountability Office (GAO) this week. In its report — published just weeks after China purportedly swiped a classified shipment of F-35 parts diverted through Hong Kong — the GAO criticized the current inventory system as “outdated, inaccurate, and incomplete.” Possible solutions were also provided by the GAO; however, the implications are that the most advanced and costly fighter jets in U.S. history may not be ready and reliable due to inventory management deficiencies.
Recent findings suggest that inventory problems have been a long-standing feature of the deployment of the F-35, notes the source. The F-35 program is estimated to cost $1.9 trillion over its lifecycle. It is the most costly weapon system in history, says the GAO. But the Department of Defense (DOD) has “long-standing and ongoing deficiencies related to the accountability and financial reporting of F-35 parts,” asserts the watchdog.
Chief among the issues that need to be addressed is the headlining massive unmonitored pool of roughly 26 million spare parts. These are spread among 700 government and contractor facilities worldwide, but the technology for managing massive inventories has existed for decades.
According to recent reports, we might have seen a telling symptom of the inadequate F-35 parts tracking system back in September. A communications and/or accountability breakdown resulted in a UPS worker routing top-secret parts through Hong Kong to save time. They were allegedly swiped by China after an employee is thought to have missed an email warning not to divert the parts.
Frustratingly, this is the third report since 2019 from the GAO, and the latest published report complains that the DOD has “made minimal progress” in implementing past recommendations. For example, in a 2022 report, periodic physical inventories of F-35 parts were recommended but have not been implemented yet, notes Stars and Stripes. There is also no reliable procedure for verifying data from prime contractors, which can be “inaccurate and incomplete.”.
Currently, it is believed that there are over 1 million parts, worth more than $85 million, that are lost or missing. Moreover, about 17,000 parts that have been sent in for repair, worth as much as $42.5 billion, aren’t tracked.
Stars and Stripes mentions that the Pentagon is working on “a live connection” for the F-35 Joint Program Office (JPO), bridging its inventory software and that of prime contractors with F-35 parts. The JPO asserts that it is now modernizing its infrastructure with direct real-time interfaces. “This integration directly addresses previous system gaps to ensure seamless accountability of F-35 spare parts,” remarked a JPO spokesperson, quoted by Breaking Defense.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
In a recent development, download the Tom's Hardware app for up-to-the-minute updates on iOS and Android. Also follow Tom's Hardware on Google News, or add us as a preferred source, to get our latest news, analysis, & reviews in your feeds.
Mark Tyson is a news editor at Tom's Hardware. He enjoys covering the full breadth of PC tech; from business and semiconductor design to products approaching the edge of reason.
🔗 Related Articles
📰 #23602. China engineers behind J-35 fighter jet pioneer 3D-printed load-bearing structures in military aircraft 📰 #19467. The First Foreign Astronaut Will Visit China's Tiangong Space Station in Two Weeks 📰 #19424. The Grand Canyon is missing over a billion years of rocks. Now scientists know why.
General
⚖️ Neutral
🌐 Hugging Face
#11334. Alyah ⭐️: Toward Robust Evaluation of Emirati Dialect Capabilities in Arabic LLMs
📅 27 Jan 2026 • ⏱️ 6m • 📚 Deep Dive (1254 w)
Alyah ⭐️: Toward Robust Evaluation of Emirati Dialect Capabilities in Arabic LLMs
📅 27 Jan 2026 | ⏱️ 6 min read (1254 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- Arabic is one of the most widely spoken languages in the world, with hundreds of millions of speakers across more than twenty countries.
- Recent findings suggest that this gap is particularly problematic as large language models increasingly interact with customers in informal, culturally grounded, and conversational settings.
- Recent findings suggest that the Emirati dialect is deeply intertwined with local culture, heritage, and history.
📦 Dataset on HuggingFace | 🔧 Code on GitHub.
Arabic is one of the most widely spoken languages in the world, with hundreds of millions of speakers across more than twenty countries. Despite this global reach, Arabic is not a monolithic language. Modern Standard Arabic coexists with a rich landscape of regional dialects that differ significantly in vocabulary, syntax, phonology, and cultural grounding. These dialects are the primary medium of daily communication, oral storytelling, poetry, and social interaction. However, most existing benchmarks for Arabic large language models focus almost exclusively on Modern Standard Arabic, leaving dialectal Arabic largely under-evaluated and under-represented.
Recent findings suggest that this gap is particularly problematic as large language models increasingly interact with customers in informal, culturally grounded, and conversational settings. A model that performs well on formal newswire text may still fail to understand a greeting, an idiomatic expression, or a short anecdote expressed in a local dialect. To address this limitation, our team introduces Alyah الياه (which means North Star ⭐️ in Emirati), an Emirati-centric benchmark designed to assess how well Arabic LLMs capture the linguistic, cultural, and pragmatic aspects of the Emirati dialect.
Recent findings suggest that the Emirati dialect is deeply intertwined with local culture, heritage, and history. It appears in everyday greetings, oral poetry, proverbs, folk narratives, and expressions whose meanings cannot be inferred through literal translation alone. Our benchmark is intentionally designed to probe this depth. Rather than testing surface-level lexical knowledge, it challenges models on their ability to interpret culturally embedded meaning, pragmatic usage, and dialect-specific nuances.
The benchmark covers a wide range of content, including common and uncommon local expressions, culturally grounded greetings, short anecdotes, heritage-related questions, and references to Emirati poetry. The goal is not only to measure correctness, but also to understand where models systematically succeed or fail when confronted with authentic Emirati language use.
Following further development and consolidation, the benchmark has been unified into a single dataset called Alyah. The final benchmark contains 1,173 samples, all collected manually from native Emirati speakers to ensure linguistic authenticity and cultural grounding. This manual curation step was essential to capture expressions, meanings, and usages that are rarely documented in written resources and are difficult to infer from Modern Standard Arabic alone.
In a recent development, each sample is formulated as a multiple-choice question with four candidate answers, exactly one of which is correct. Large language models were used to synthetically generate the distractor choices, after which they were reviewed to ensure plausibility and semantic closeness to the correct answer. To avoid positional bias during evaluation, the index of the correct answer follows a randomized distribution across the dataset. Below is the distribution of word count per query and candidate answers.
Alyah spans a broad spectrum of linguistic and cultural phenomena in the Emirati dialect, ranging from everyday expressions to culturally sensitive and figurative language. The distribution across categories is summarized below.
Below are examples of each category:.
This composition allows Alyah to jointly evaluate surface-level conversational fluency and deeper cultural, semantic, and pragmatic understanding, with a particular emphasis on dialect-specific language phenomena that remain challenging for current models.
It has been revealed that we evaluated a total of 54 language models, comprising 23 base models and 31 instruction-tuned models, spanning several architectural and training paradigms. These include Arabic-native LLMs such as Jais and Allam, multilingual models with strong Arabic support such as Qwen and LLaMA, and adapted or regionally specialized models such as Fanar and AceGPT. For each family, both base and instruction-tuned variants were evaluated in order to understand the impact of alignment and instruction tuning on dialectal performance.
In a recent development, all models were evaluated under a consistent prompting and scoring protocol. Responses were assessed for semantic correctness and appropriateness with respect to Emirati usage, rather than literal overlap with a reference answer. This is particularly key for dialectal evaluation, where multiple valid phrasings may exist.
For each question category, we estimated difficulty empirically based on model performance. Categories where most models struggled were labeled as harder, while those consistently answered correctly across model families were considered easier. This approach allows difficulty to emerge from observed behavior rather than from subjective annotation alone.
We evaluate a broad set of contemporary Arabic and multilingual large language models on Alyah, using accuracy on multiple-choice questions as the primary metric. The evaluation covers 53 models in total, including 22 base models and 31 instruction-tuned models, spanning Arabic-native, multilingual, and regionally adapted systems. Below is a radar plot showing the performance of top models of different sizes per question category.
These results are intended as reference measurements within the scope of Alyah, rather than absolute rankings across all Arabic benchmarks.
Several trends emerge from the evaluation. Instruction-tuned models generally outperform their base counterparts as shown in Figures 1 and 2. This is particularly the case on questions involving conversational norms and culturally appropriate responses (i.e. the Etiquette & Values Category). Furthermore, it is the case with questions that test imagery and figurative meaning. This can be attributed, to the model’s original strong capabilities with understanding MSA-based imagery and figurative language regardless of the dialect at hand. The models are able to draw patterns of non-literal description regardless of dialect. Generally, the most difficult categories for the models were consistently “Language and Dialect” and “Greeting and Daily expressions” across model sizes as shown in figure 1. These results reflect the current state of Emirati dialect presence in written media, as the dialect is mostly spoken rarely written, which explains its novelty relative to the evaluated models. Nonetheless, there is a clear benefit to instruct models with understanding the dialect (and the other evaluation categories) in comparison to their counterparts, especially in small and medium models. This is particularly noticeable with the Poetry and Creative Expression category, which is where the large instruct models performed marginally better than the smaller models.
Sources indicate that as shown in Figure 3, even strong multilingual models show notable degradation on the most challenging Alyah questions, suggesting that dialect-specific semantic knowledge is not easily acquired through generic multilingual training alone. It must be noted that while Arabic-native models tend to perform more robustly on culturally grounded content, their performances are not uniform across all categories (figure 2). In particular, questions involving implicit meanings and rare expressions remain difficult across nearly all evaluated models. This highlights a persistent gap between surface-level dialect familiarity and deeper cultural understanding. The high variance in performance across categories , where a model that excels at imagery and figurative meaning may still struggle with poetry or heritage-related creative questions, indicates that dialectal competence is multi-dimensional and cannot be captured by a single score. Figure 3 shows that the highest scoring large model in Jais-2-70B, followed by the two small models jais-2-8B and ALLaM-7B-instruct, which are all Arabic instruct-tuned models.
This benchmark represents a step toward more realistic and culturally grounded evaluation of Arabic language models. By focusing on the Emirati dialect, we aim to support the development of models that better serve local communities, institutions, and customers in the UAE. Beyond model ranking, the benchmark is intended as a diagnostic tool to guide future data collection, training, and adaptation efforts.
In a recent development, we invite researchers, practitioners, and the broader community to use the benchmark, explore the results, and share feedback. Community input will be essential to refining the dataset, expanding coverage, and ensuring that dialectal Arabic receives the attention it deserves in the evaluation of Large Language Models.
🔗 Related Articles
📰 #11878. Introducing the LiveCodeBench Leaderboard - Holistic and Contamination-Free Evaluation of Code LLMs 📰 #11850. CyberSecEval 2 - A Comprehensive Evaluation Framework for Cybersecurity Risks and Capabilities of Large Language Models 📰 #11810. LAVE: Zero-shot VQA Evaluation on Docmatix with LLMs - Do We Still Need Fine-Tuning?
AI & Tech
⚖️ Neutral
🌐 9to5google
#11333. Gemini 4 Carbon rolling out to Gemini app for AI Ultra, Argon remains
📅 10 Nov 2026 • ⏱️ 2m • 📖 Standard (338 w)
Gemini 4 Carbon rolling out to Gemini app for AI Ultra, Argon remains
📅 10 Nov 2026 | ⏱️ 2 min read (338 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Following the preview at the end of last month, Google is now bringing its latest Gemini 4 Carbon model to the Gemini app.
- Officially, Google indicates “Argon remains the ideal choice for the majority of software engineering and knowledge work, while Carbon is built for tasks that test the limits of a model’s intelligence.” Examples include “complex, multi-step coding and debugging and open-ended scientific research and discovery.”.
- In the model picker, 4 Argon is for “Code & analysis” and 4 Carbon is for “Most complex work.” Notably, the Gemini app has removed 3.1 Pro with this launch.
Following the preview at the end of last month, Google is now bringing its latest Gemini 4 Carbon model to the Gemini app.
Officially, Google indicates “Argon remains the ideal choice for the majority of software engineering and knowledge work, while Carbon is built for tasks that test the limits of a model’s intelligence.” Examples include “complex, multi-step coding and debugging and open-ended scientific research and discovery.”.
In the model picker, 4 Argon is for “Code & analysis” and 4 Carbon is for “Most complex work.” Notably, the Gemini app has removed 3.1 Pro with this launch.
Sources indicate that to showcase performance on larger, more complex projects, Google Antigravity is previewing /swarm. This turns a “single prompt into a coordinated team of agents you can track in real time.”.
Developers can assign Carbon to roles that demand the deepest reasoning, like architectural design, coordination, and auditing, while pairing it with faster, lighter models across parallel isolated workspaces and adversarial verifiers that test every change.
For legal, finance, and enterprise work, Carbon is said to bring “higher-precision knowledge work, artifact generation, and data analysis.” This includes how the model will follow “strict schemas and formatting to generate polished and precise spreadsheets, presentations, and reports.”.
Existing benchmarks don’t adequately capture how agents reason natively over dense files with charts, images, blueprints, schematics, and tables, so we partnered with Artificial Analysis to launch the new Multimodal Knowledge Agents (MKA) benchmark. Carbon ranks #1 while using 3X fewer tokens than the next best model across 200 tasks that test a model’s multimodal performance in agentic workflows.
Other domain highlights include:.
The introductory pricing for Carbon is $2 per million input tokens and $10 per million output tokens until November 30. Afterward, it will cost $4 per 1M input tokens and $20 per 1M output tokens.
FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
In a recent development, editor-in-chief. Interested in the minutiae of Google and Alphabet. Tips/talk: abner@9to5g.com.
General
⚖️ Neutral
🌐 Tomshardware
#11332. Contractor turns a Milwaukee Hackzall into a portable Ethernet untwister after facing job requiring 50,000 custom Cat6 cables
📅 14 Nov 2026 • ⏱️ 4m • 📚 Deep Dive (725 w)
Contractor turns a Milwaukee Hackzall into a portable Ethernet untwister after facing job requiring 50,000 custom Cat6 cables
📅 14 Nov 2026 | ⏱️ 4 min read (725 words, 📚 Deep Dive) | Source: Tomshardware
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- A contractor faced a project that required them to create 50,000 custom Cat6 cables from scratch, requiring 100,000 Cat6 terminations.
- It has been revealed that his first solution to the problem was to buy a “Wire Straightening Machine” from Alibaba for $500.
- It worked well at first, but he soon discovered that it was too bulky to use in the tight and hard-to-reach places where Ethernet cables sometimes terminate, like when you’re installing this heavy-duty outdoor Wi-Fi 7 access point.
A contractor faced a project that required them to create 50,000 custom Cat6 cables from scratch, requiring 100,000 Cat6 terminations. The contractor, who goes by Analytical Horsepower on YouTube, had used a large, rare tool to streamline the job, but afterward he decided to build his own portable tool by modifying a Milwaukee Hackzall, cutting the time to straighten the twisted pairs to under two seconds.
It has been revealed that his first solution to the problem was to buy a “Wire Straightening Machine” from Alibaba for $500. It does the job well enough, but it’s an industrial machine designed for tabletop use, requiring an AC power source for the power brick and compressed air to run. The concept is that it clamps the wire between two rubber grips using air pressure, and then a linkage converts the rotary motion of the motor into a linear one, allowing the grip to untwist the cable. Since he wanted to use the machine in the field, he needed to make the thing portable — so he disassembled the entire thing, replaced the DC power brick with a 20V DeWalt battery with an adapter, added a push-button switch for power control, and a portable bike pump to deliver compressed air on the go.
It worked well at first, but he soon discovered that it was too bulky to use in the tight and hard-to-reach places where Ethernet cables sometimes terminate, like when you’re installing this heavy-duty outdoor Wi-Fi 7 access point. So, he studied the concept — it involved two flat, grippy surfaces grabbing the twisted cables and then moving back and forth. The back-and-forth motion of the surfaces causes the cables to untwist, with the clamping force ensuring that it remains in contact with the cables as they become flatter.
With this, he realized that he did not need such a bulky machine to do the job — he just needed a reciprocating tool that could accept a clamp. He first looked at a reciprocating saw, but he found that it still had the same bulky problem and also called it “not overly precise.” But when he looked at the Milwaukee Hackzall, he found that it offered the perfect balance of portability and precision. More importantly, it came with a detailed data sheet, instruction manual, and parts breakdown that allowed him to accurately 3D print the plastic parts and laser-cut and bend the metal parts he needed to build his machine. He also used a toggle clamp to hold the Cat6 cable in place instead of a pneumatic piston, which further simplified the machine and cut its size and weight.
According to recent reports, after a few steps of trial and error, especially in the quality of the grippy materials used for the clamping surfaces, he finally got it to work. He could reliably untwist softer copper-clad aluminum cables in one go in under two seconds. Harder 100% pure copper conductors, sometimes called solid copper or pure bare copper Ethernet cables, must be untwisted pair-by-pair, though, requiring a bit more time, but it’s still undoubtedly much faster and more convenient than doing the job with just your bare hands.
This tool isn’t worth it if you only untwist a few Ethernet cables every month or so, like this telephone-to-gigabit internet conversion job. But if you’re facing a massive job like Analytical Horsepower, that half a minute you save with every cable end could translate to over 830 cumulative hours of labor saved on the jobsite. It’s a great first-generation tool, with its practical use apparent in the YouTube video. Some commenters suggest extending the toggle clamp handle to reach the trigger so activating the tool is easier, while it also looks like a good idea if there’s a way to incorporate the entire system into a crimper.
Download the Tom's Hardware app for up-to-the-minute updates on iOS and Android. Also follow Tom's Hardware on Google News, or add us as a preferred source, to get our latest news, analysis, & reviews in your feeds.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
According to recent reports, jowi Morales is a tech enthusiast with years of experience working in the industry. He’s been writing with several tech publications since 2021, where he’s been interested in tech hardware and consumer electronics.
🔗 Related Articles
📰 #23606. What’s !vital #19: CSS Refraction Effects, Scroll State Queries, @custom-media, and More 📰 #23554. Breaking: This tiny gamepad with dual analog thumbsticks pushes the limits of portable controllers 📰 #23529. The Xiaomi 18 Pro’s rear displays support Google apps, Spotify, and custom GenAI apps
AI & Tech
⚖️ Neutral
🌐 9to5google
#11331. Latest Update: One UI 9.5 might bring Pixel 11’s ‘Rambler’ feature to Samsung Keyboard before Google’s
📅 10 Nov 2026 • ⏱️ 2m • 📖 Standard (331 w)
Latest Update: One UI 9.5 might bring Pixel 11’s ‘Rambler’ feature to Samsung Keyboard before Google’s
📅 10 Nov 2026 | ⏱️ 2 min read (331 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- The Pixel 11 launched with one AI tool most people got on board with, called “Rambler.” It’s a transcription tool that overhauls and cleans up voice-to-text messages.
- According to recent reports, the Rambler-like keyboard feature was found in an internal test build of Samsung’s One UI 9.5, thanks to SamMobile.
- In a recent development, clean up filler words, hesitations, and more.
The Pixel 11 launched with one AI tool most people got on board with, called “Rambler.” It’s a transcription tool that overhauls and cleans up voice-to-text messages. Too bad this Rambler clone will only be available on Samsung Keyboard.
According to recent reports, the Rambler-like keyboard feature was found in an internal test build of Samsung’s One UI 9.5, thanks to SamMobile. The settings include a feature named “Refine Voice Input,” and the description removes any doubt that it might be something other than a Rambler clone.
In a recent development, clean up filler words, hesitations, and more. Text appears after you finish speaking.
Much like the Pixel 11’s Rambler tool, the final product is only available after you’re done dictating. The audio is then processed and turned into something coherent, devoid of the onomatopoeic words we often say when gathering our thoughts in a voice-to-text message. Unlike Rambler, though, it sounds like Samsung’s tool will automatically process your message instead of requiring an end action, like tapping the checkmark.
It has been revealed that the biggest downside to this Rambler variant is that it falls under Samsung Keyboard’s feature set, not Google Keyboard. Even though One UI 9.5 is largely based on Android 17, Samsung still offers its own keyboard as the default experience.
Sources indicate that this isn’t the first Google Keyboard feature Samsung Keyboard has emulated. Magic Cue was a massive addition to Samsung Galaxy devices, in the form of Now Nudge. It works wonderfully if you happen to like using Samsung Keyboard.
In a recent development, google still hasn’t made Rambler available for any other Pixel devices besides the Pixel 11, and it’s the same story for Google Keyboard builds on Galaxy devices. Workarounds exist, but they aren’t official and shouldn’t be treated as such.
Sources indicate that FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Samsung is a technology conglomerate based out o….
🔗 Related Articles
📰 #23493. Google Pixel rolls out new ‘Family Hub’ feature with useful controls [Gallery] 📰 #23425. Latest Update: Google’s latest ‘Fast Switch’ feature leaks, lets you use one number on two Android phones 📰 #11305. Tech Report: November 2026 Pixel Drop: Create My Widget, HiLight for Google Messages, Pixel 10 Rambler, & more
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11330. People are taking an unapproved weight-loss drug. AI found something surprising
📅 22 Oct 2026 • ⏱️ 7m • 📚 Deep Dive (1457 w)
People are taking an unapproved weight-loss drug. AI found something surprising
📅 22 Oct 2026 | ⏱️ 7 min read (1457 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- Recent findings suggest that an experimental weight-loss drug that has not yet received regulatory approval is already attracting users willing to obtain unapproved versions online.
- According to recent reports, the drug, retatrutide, belongs to a upcoming generation of GLP-1 medications designed to help regulate appetite and body weight.
- Industry observers note that researchers at the University of Pennsylvania analyzed nearly 150,000 Reddit posts and comments from approximately 40,000 users to investigate these accounts.
Recent findings suggest that an experimental weight-loss drug that has not yet received regulatory approval is already attracting users willing to obtain unapproved versions online. Now, scientists are using artificial intelligence to investigate their experiences, uncovering unexpected symptom reports that differ from those documented in clinical trials.
According to recent reports, the drug, retatrutide, belongs to a upcoming generation of GLP-1 medications designed to help regulate appetite and body weight. Although it remains under investigation and is not approved for use, people are purchasing unapproved formulations that are not intended for human consumption and discussing their experiences on internet forums.
Industry observers note that researchers at the University of Pennsylvania analyzed nearly 150,000 Reddit posts and comments from approximately 40,000 users to investigate these accounts. Their study, published in JAMA Network Open, provides the first systematic examination of potential side effects reported by people claiming to use unapproved retatrutide.
One finding stood out. Among users whose reported symptoms could be classified, increased appetite was the most common complaint. That was particularly unexpected because retatrutide is designed to suppress hunger, and its Phase 2 clinical trials primarily identified digestive problems as the most frequent side effects.
AI Uncovers Unexpected Weight-Loss Drug Reports.
"Our goal is to identify hypotheses in online conversations that we could test. AI helps us find recurring patterns in people's self-reports, including experiences that may be missed by conventional drug-safety monitoring," notes Sharath Chandra Guntuku, Research Associate Professor in Computer and Information Science (CIS), Director of Penn's Computational Social Listening Lab and senior author of the study.
Industry observers note that however, the researchers emphasize that the findings should not be interpreted as proof of previously unknown side effects. Reddit users represent a very different population from clinical trial participants, and their accounts cannot establish whether the drug caused the symptoms they described.
There is also considerable uncertainty about what these individuals are actually taking. Products sold outside regulated medical channels may differ from the genuine experimental medication in their ingredients, purity, and dosage.
"We can't say that retatrutide is causing these symptoms, or even that Reddit users are actually taking genuine retatrutide, since the drug is not legally available, and gray market formulations vary," says Lyle Ungar, Professor in CIS and a co-author of the study.
Rather than confirming fresh risks, the research offers scientists an opportunity to identify questions that warrant more rigorous investigation.
"This is the first glimpse into the experiences of a population that is otherwise outside conventional drug safety monitoring because they are taking unapproved versions of a drug that has yet to finish clinical trials," states Neil Sehgal, the study's first author and a doctoral student in CIS.
How Researchers Analyzed 150,000 Reddit Posts.
Recent findings suggest that the project builds on previous research by the University of Pennsylvania team. In that earlier investigation, scientists used large language models (LLMs), the type of artificial intelligence that powers many modern chatbots, to examine more than 400,000 Reddit posts discussing semaglutide and tirzepatide.
That analysis revealed reports of possible side effects, including menstrual irregularities, that may not have been fully documented in clinical trials or official drug safety records.
"We wanted to apply the same methodology to gray-market retatrutide," says Sehgal.
In a recent development, retatrutide is particularly interesting because it works differently from existing GLP-1 medications. Semaglutide acts on one hormone receptor involved in blood sugar control and appetite regulation, while tirzepatide targets two. Retatrutide activates three receptors, potentially producing a different combination of effects throughout the body.
To investigate what people were experiencing, the researchers used AI to examine nearly 150,000 Reddit posts and comments. They identified approximately 14,000 owners who claimed to have personally taken an unapproved version of retatrutide.
It has been revealed that the AI systems then extracted descriptions of symptoms that people associated with the medication and translated those descriptions into standardized medical terminology. This allowed researchers to compare reports even when different people used different words to describe similar experiences.
After excluding expected effects such as weight loss and reduced appetite, the team identified 7,823 people who reported at least one symptom that could be medically classified.
In a recent development, "A researcher might be able to examine a few thousand Reddit posts by hand, but looking at nearly 150,000 would be an enormous undertaking," indicates Sehgal. "AI makes it possible to analyze these conversations at scale, identifying patterns in what people are sharing that would otherwise be difficult to recognize.".
A Surprising Appetite Paradox Emerges.
The most striking difference involved hunger.
It has been revealed that in retatrutide's Phase 2 clinical trials (the drug is right now in Phase 3 trials, the final step before FDA approval), participants most commonly experienced gastrointestinal complaints, including nausea. These effects are familiar concerns with medications that influence appetite and digestion.
Industry observers note that but among Reddit customers who reported taking unapproved retatrutide, the pattern looked different. Increased appetite emerged as the most frequently described classifiable symptom, despite the substantial weight-loss effects demonstrated in clinical testing.
The researchers also compared the new findings with their earlier analysis of semaglutide and tirzepatide.
Sources indicate that compared with those earlier Reddit reports, discussions involving unapproved retatrutide contained proportionally more mentions of appetite-related changes, sleep disturbances, increased heart rate, and muscle-related symptoms. Reports of nausea and other digestive complaints were proportionally less common.
Industry observers note that these differences could reflect how retatrutide interacts with the body. However, they could also result from differences between the groups of people discussing the medications, their other drug use, or the contents of the unapproved products.
"Retatrutide works differently from existing GLP-1 drugs, so it's possible that its effects on the body are different, too," indicates Jena Shaw Tronieri, Senior Research Investigator at Penn's Center for Weight and Eating Disorders and a co-author of the study.
Sources indicate that "But the people discussing it on Reddit also may be different," she notes. "Users willing to obtain an unapproved medication on the gray market likely differ from other clinical populations. Some may be taking multiple experimental peptides, and we can't verify exactly what they're taking. We need more research to understand what, if anything, these differences in self-reported symptoms mean.".
Can AI Detect Drug Safety Concerns Earlier?
Beyond the findings about retatrutide, the study demonstrates how AI could potentially improve the early detection of drug safety concerns.
Industry observers note that traditional monitoring systems depend heavily on clinical trials, reports submitted to regulators, and information collected by healthcare professionals. People obtaining experimental medications through unapproved channels may not be represented in those systems.
It has been revealed that social media offers another source of information, allowing researchers to identify recurring experiences that might otherwise escape attention. However, these reports must be independently investigated before they can be considered reliable evidence of a drug-related problem.
The Penn team has already seen an example of how this approach can help guide further research.
In their previous investigation of semaglutide and tirzepatide, researchers identified online reports of menstrual irregularities. Those findings subsequently encouraged another scientific team to examine similar symptoms using the FDA's database of reported adverse drug events.
The follow-up study, published in Obstetrics & Gynecology, also detected disproportionate reports of certain menstrual changes. Although those findings did not establish causation, they provided additional reasons to investigate the potential connection.
The researchers hope their retatrutide findings will lead to similar independent studies, particularly as the drug advances through clinical development.
Industry observers note that "That's what we hope will happen with this study," says Sehgal. "Other researchers can take what we find on Reddit and look for the same patterns in other datasets, using entirely different methods. Whether those signals hold up or not, the goal is to build a better understanding of what people are actually experiencing.".
The research was conducted through the University of Pennsylvania's School of Engineering and Applied Science and Perelman School of Medicine. Benjamin Rader of Boston Children's Hospital also contributed as a co-author. Funding was provided in part by the University of Pennsylvania's Penn Medical Communication Research Institute. Tronieri disclosed receiving an investigator-initiated grant from Novo Nordisk on behalf of the University of Pennsylvania, along with consulting fees from Currax Pharmaceuticals, LLC. No conflicts of interest were reported by the other authors.
It has been revealed that materials provided by University of Pennsylvania School of Engineering and Applied Science. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #22152. Latest Update: Everyone Wants This Unapproved Weight Loss Drug—And Some Have Found a Way to Get It 📰 #17931. The Next Generation of Weight-Loss Drugs Is Reshaping People’s Looks—And Not in a Flattering Way 📰 #22803. People With Depression May Be Missing Something Their Brains Normally Produce (M)
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11329. Industry News: Architectural Choices in China's Open-Source AI Ecosystem: Building Beyond DeepSeek
📅 27 Jan 2026 • ⏱️ 7m • 📚 Deep Dive (1364 w)
Industry News: Architectural Choices in China's Open-Source AI Ecosystem: Building Beyond DeepSeek
📅 27 Jan 2026 | ⏱️ 7 min read (1364 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- In this second piece we turn our focus from models to the architectural and hardware choices Chinese companies have made as openness becomes the norm.
- For AI researchers and developers contributing to and relying on the open source ecosystem and for policymakers understanding the rapidly changing environment, architectural preferences, modality diversification, license permissiveness, small model popularity, and growing adoption of Chinese hardware point to leadership strategies across a multitude of paths.
- Industry observers note that in the past year, leading models from the Chinese community had almost unanimously moved toward Mixture-of-Experts (MoE) architectures, including Kimi K2, MiniMax M2, and Qwen3.
In this second piece we turn our focus from models to the architectural and hardware choices Chinese companies have made as openness becomes the norm.
For AI researchers and developers contributing to and relying on the open source ecosystem and for policymakers understanding the rapidly changing environment, architectural preferences, modality diversification, license permissiveness, small model popularity, and growing adoption of Chinese hardware point to leadership strategies across a multitude of paths. DeepSeek R1's own characteristics inspired overlap and competition, and contributed to heavier focus on domestic hardware in China.
Industry observers note that in the past year, leading models from the Chinese community had almost unanimously moved toward Mixture-of-Experts (MoE) architectures, including Kimi K2, MiniMax M2, and Qwen3. R1 itself was an MoE model, it also proved a crucial point: strong reasoning could be open, reproducible, and engineered in practice. Under China's real-world constraints, maintaining high capability while controlling cost, and ensuring models could be trained, deployed, and widely adopted, MoE emerged as a natural solution.
According to recent reports, moE is like a controllable compute distribution system; under a single capability framework, compute resources are allocated across requests and deployment environments by dynamically activating different numbers of experts according to task complexity and value. More importantly, it does not require every inference to consume the full set of resources, nor does it assume that all deployment environments share identical hardware conditions.
The overall direction of Chinese open-source models in 2025 was clear: not necessarily the strongest possible performance, but ability to operate sustainably, deploy flexibly, and evolve continuously, achieving the best cost performance balance.
Starting in February 2025, open-source activity was no longer focused only on text models. It quickly expanded into multimodal and agent-based directions: Any-to-Any models, text-to-image, image-to-video, text-to-video, TTS, 3D, and agents all progressed in parallel. What the community pushed forward was not just model weights, but a full set of engineering assets, including inference deployment, datasets and evaluation, toolchains, workflows, and edge-to-cloud coordination. The parallel emergence of video generation tools, 3D components, distillation datasets, and agent frameworks pointed to something larger than isolated breakthroughs---it pointed to reusable system-level capabilities.
The competition to lead similar to DeepSeek in a non-text modality heated up. StepFun's released high performance multimodal models, excelling in audio, video, and image generation and processing or editing. Their latest speech-to-speech model Step-Audio-R1.1 boasts state-of-the-art performance, beating proprietary models. Tencent also reflected this shift through open-source work in video and 3D. Its Hunyuan Video models and projects such as Hunyuan 3D reflect growing competition beyond text-centric models.
Models in the 0.5B--30B range were easier to run locally, fine-tune, and integrate into business systems and agent workflows. For example: Among the Qwen series, Qwen 1.5-0.5B has the most derivative models. In environments with limited compute or strict compliance requirements, these models were far better suited for long-term operation. At the same time, leading players often used large MoE models in the 100B--700B range as capability ceilings or "teacher models," then distilled those capabilities down into many smaller models. This created a clear structure: a few very large models at the top, and many practical models underneath. The growing share of small models in monthly summaries reflected real usage needs in the community.
https://huggingface.co/spaces/cfahlgren1/hub-model-tree-stats.
After R1, Apache 2.0 became close to the default choice for open models from the Chinese community. More permissive licenses lowered the friction around using, modifying, and deploying models in production, making it much easier for companies to move open models into real systems. Familiarity with standard licenses, such as Apache 2.0 and MIT, similarly eased usage; prescriptive and tailored licenses add friction through unfamiliarity and newly introduced legal barriers, contributing to the decline seen in the graph below.
Based on the releases of all organizations shown in Chinese Open Source Heatmap.
In 2025, model releases increasingly aligned with inference frameworks, quantization formats, serving engines, and edge runtimes. A prominent goal was no longer just to make weights downloadable, but to ensure that models could run directly on target domestic hardware---and run reliably and efficiently. This change was most visible on the inference side. For example, With DeepSeek-V3.2-Exp, both Huawei Ascend and Cambricon chips achieved day-zero support, not as cloud demos, but as reproducible inference pipelines released alongside the weights, enabling developers to validate real-world performance directly.
In a recent development, at the same time, training-side signals began to appear. Ant Group's Ling open models use optimized training on domestic AI chips to achieve near NVIDIA H800 performance, cutting the cost of training 1 trillion tokens by about 20%. Baidu's open Qianfan-VL models clearly documented that the model was trained on a cluster of more than 5,000 Baidu Kunlun P800 accelerators, their flagship AI chip, with details on parallelization and efficiency. At the beginning of 2026, Zhipu's GLM-Image and China Telecom's latest open model - TeleChat3, were both declared as being trained entirely on domestic chips. These disclosures demonstrated that domestic computers were no longer limited to inference, but had started to enter key stages of the training pipeline.
In a recent development, on the serving and infrastructure side, engineering capabilities are being systematically open-sourced. Moonshot AI released its serving system: Mooncake, and explicitly supported features such as prefill/decoding separation. By open-sourcing production-grade experience, these efforts significantly raised the baseline for deployment and operations across the community, making it easier to run models reliably at scale. This direction was echoed across the ecosystem. Baidu's FastDeploy 2.0 emphasized extreme quantization and cluster-level optimization to reduce inference costs under tight compute budgets. Alibaba's Qwen ecosystem pursued full-stack integration, tightly aligning models, inference frameworks, quantization strategies, and cloud deployment workflows to minimize friction from development to production. Still, reports of compute constraints in China threaten expansion; Zhipu AI is reportedly restricting usage amid a computing crunch.
According to recent reports, when models, tools, and engineering are delivered together, the ecosystem no longer grows by adding projects, but by structurally differentiating on a shared foundation-and beginning to evolve on its own. How China will respond to U.S. hardware sales and export controls as NVIDIA sells H200s continues to be an open question. Read more about the shifting global compute landscape here.
The "DeepSeek Moment" of January 2025 did more than trigger a wave of upcoming open models. It forced a deeper reconsideration of how AI systems should be built when open source is no longer optional but foundational and why those underlying choices now carry strategic weight.
Chinese companies are no longer optimizing isolated models. Instead, they are pursuing distinct architectural paths aimed at building full ecosystems suited to an open-source world. In an increasingly commoditized model landscape, these decisions signal a clear shift in competition from model performance to system design.
Our next blog will go deeper into organizational wins and share some of what we expect to see in 2026.
This sentence is very insightful: In today's world where models are becoming increasingly homogeneous, these decisions mark a significant shift in the competitive landscape from model performance to system design. What China has made open-source has never been a single model weight, but the entire AI ecosystem.
I would love to hear your views on China's system design.
According to recent reports, really interesting anniversary post! It’s inspiring to see how the DeepSeek R1 release helped expand the global open-source AI ecosystem, lowering barriers and sparking fresh innovation over the past year.
According to recent reports, insightful analysis of architectural innovations in the open-source AI ecosystem! Understanding these different architectural approaches is crucial for making informed design decisions. When documenting our own system architectures and evaluating different approaches, I've found InfraSketch (https://www.infrasketch.net/) incredibly valuable—it turns plain English system descriptions into architecture diagrams that you can iterate on through conversation. Makes it much easier to communicate architectural trade-offs and maintain living documentation.
One point that strikes me is that Chinese open source seems to have internalized something that the West still treats as secondary: when models become commodities, the real differentiator becomes systemic operability. It's not about "the best weight," but about who delivers a complete system—from training to inference—that works under real cost, hardware, and compliance constraints. This completely changes the axis of competition.

AI & Tech
⚖️ Neutral
🌐 9to5google
#11328. Deals: Amazon early Black Friday sale, Dell Googlebook, Google Home Speaker, Galaxy Tab S12 Ultra up to $330 off, more
📅 10 Nov 2026 • ⏱️ 7m • 📚 Deep Dive (1464 w)
Deals: Amazon early Black Friday sale, Dell Googlebook, Google Home Speaker, Galaxy Tab S12 Ultra up to $330 off, more
📅 10 Nov 2026 | ⏱️ 7 min read (1464 words, 📚 Deep Dive) | Source: 9to5google
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- Industry observers note that this morning Amazon now officially confirmed its Black Friday sale and subsequently introduced its early Black Friday event you can shop right now, alongside the Best Buy Week 2 early Black Friday deals.
- According to recent reports, googlebooks have only been on the market for a couple of months, and we’re already seeing one of the first chances to save on one of the more premium models.
- Industry observers note that the Samsung Black Friday sale has sort of soft debuted now on the official site, but there is now cash discounts live on its upcoming Galaxy Tab S12 Ultra.
Industry observers note that this morning Amazon now officially confirmed its Black Friday sale and subsequently introduced its early Black Friday event you can shop right now, alongside the Best Buy Week 2 early Black Friday deals. Joining the all-time low on the Google Home Speaker, we have also have your first chance to save on Dell’s upcoming touchscreen XPS Googlebook at nearly $300 off and its 2026 Windows laptop with the 15.3-inch 2K touchscreen at $350 off. From there we move over to the most affordable Galaxy Tab S12 Ultra at over $330 off the list price and Galaxy Z Fold 8 Ultra at $420 off in Best Buy “excellent” open-box condition alongside a host of other early Black Friday deals. Check it all out below.
According to recent reports, googlebooks have only been on the market for a couple of months, and we’re already seeing one of the first chances to save on one of the more premium models. Best Buy currently has the Dell XPS Googlebook in Open-Box Excellent condition for $723.99 shipped, down from its usual $1,000 price. That works out to $276 in savings just for going the open-box route. We’re yet to see any meaningful deals land on these new Googlebook laptops, so you might want to jump in and snag this one while it’s still available. Head below for more details.
Industry observers note that the Samsung Black Friday sale has sort of soft debuted now on the official site, but there is now cash discounts live on its upcoming Galaxy Tab S12 Ultra. Amazon doesn’t carry the Ultra and, while there were some notable gift card offers ahead of launch, we are now tracking a chance to land the most affordable Galaxy Tab S12 Ultra at over $330 off the list price.
Industry observers note that we are yet to catch any straight cash discounts on the new Galaxy Tab S12 Ultra in brand new condition. And while that could happen during Black Friday, it remains to be seen whether or not Samsung or retailers like Best Buy will be serving up hundreds in savings like we are tracking today.
Best Buy’s “excellent” condition open-box listing on the 256GB Galaxy Tab S12 Ultra in Gray with the S-Pen included is at the moment sitting down at $1,065.99 shipped.
It has been revealed that this is a regularly $1,400 flagship tablet Samsung just released not more than a couple months ago now. It is right now available in Best Buy’s top quality open-box condition at $334 under the price you’ll pay in latest condition to deliver the best deal we have tracked on this configuration since release. Even with the pre-order gift card offers, you’re still landing an additional $130+ in savings here.
While Samsung’s cash deals on its latest series 8 foldables have ow disappeared, we wanted to highlight this even deeper deal we spotted over at Best Buy this morning. You can now score the most affordable Galaxy Z Fold 8 Ultra at $420 off the list price in “excellent” open-box condition.
While not all colors and configs are down this low, you will find the striking Violet Shadow treatment on the 256GB Z Fold 8 Ultra sitting down at $1,679.99 shipped in “excellent” open-box condition.
This is a regularly $1,900 device that is right now selling at the full list via Samsung and over $1,870 at Amazon.
Sources indicate that while we have seen some fleeting deals for Prime members on this device previously and there is a strong chance it drops in price for the upcoming Amazon Black Friday sale that starts next week, there’s no telling where it might land at this point. Some colors have dropped down to $1,700 in the past, so that’s not out of the question, but the $420 in savings we have here today in near-perfect condition is quite notable.
It also joins some other notable open-box offers on the latest Fold devices:.
The all-latest Samsung Galaxy SmartTag 3 tracker is now live and available for purchase. You’ll find the single 1-pack listing live at $30 and the 4-pack at $99.99 – both are now live at Amazon and the official Samsung site.
Sources indicate that alongside its now-live Week 2 early Black Friday deals, and as part of its Deals of the Day lineup, Best Buy has listed Dell’s 2026 Windows laptop with a 15.3-inch 2K touchscreen down to $479.99 shipped. You’re looking at the base variant of this laptop in the 8GB/256GB config, which typically goes for $830. Today’s deal delivers a $350 discount on it to mark the lowest price we have tracked for it to date. We saw the 8GB/512GB variant of this notebook see a $300 discount just last week, but today’s early Black Friday deal delivers an even better value on this notebook for folks looking to buy a simple, everyday laptop for casual use. Head below for more details.
It has been revealed that dell’s 15.3-inch 2K touchscreen laptop highlighted here is a solid everyday machine if you want something a little nicer than the typical budget Windows notebook in this price range. This 2026 model is powered by Intel’s newer Core 5 Series 3 processor alongside 8GB of RAM and 256GB of storage, giving you enough performance for browsing, streaming, schoolwork, office apps, and other day-to-day tasks. The standout feature here is its 15.3-inch 2K touchscreen, which delivers a sharper picture than a standard Full HD panel while also giving you the added convenience of touch input. You’re also looking at a relatively slim and lightweight design in Dell’s Celestial Blue finish, along with a useful selection of ports for hooking up accessories and other peripherals.
Industry observers note that lenovo’s IdeaPad Slim 3 is also worth checking out today, if you’re looking for something with more memory and storage. It’s currently down to $700 from its usual $950 price tag and comes with a 2K touchscreen display as well.
Amazon has now officially revealed its 2026 Black Friday details and launched the early sale deal pages, but it has also introduced a countdown clock on the all-time low pricing for its new Fire TV Stick 4K at $25 – you have until midnight tonight to score one at the lowest price yet.
Amazon is delivering early Black Friday deals across its Fire TV Stick streaming media player lineup right now headlined by the brand upcoming 4K model at $24.99 with free shipping for Prime members or in orders over $35.
According to recent reports, this model debuted a few months ago at $60 with a 50% launch discount at $30. It, however, dropped even lower as part of Amazon’s early Black Friday offerings and it looks as though the deal is going to end tonight.
Industry observers note that there’s nothing quite like an LG C or G series OLED TV upgrade if you ask me, but the B series line is more than capable enough for most folks and comes in at a much more affordable price. Plus, Amazon just knocked $1,000 off the 65-inch 2026 model to deliver the lowest price we have tracked there.
Amazon is now offering the 2026 model 65-inch LG Class LG OLED AI B6 4K Smart TV down at $999.99 shipped.
Recent findings suggest that this one launched earlier this year at $2,000 and is now 50% off to deliver a new Amazon all-time low, and right before the release of Grand Theft Auto VI no less. While it has been selling for closer to $1,200 and $1,300 over the last few months at Amazon and elsewhere, we are, nonetheless, looking at a new Amazon low, and a price coming in at a whole lot lower than it was at launch.
This one is still fetching full price on the official LG site and, while it is on sale at Best Buy in its Week 2 early Black Friday event, you will pay $200 more there right now.
It’s not quite as high-end an offering as the C6 or the G6 for sure, but it is likely more than good enough for most gamers and home theater setups – all but the most hardcore TV pros will be perfectly happy with this OLED in my opinion.
As far as its gaming prowess is concerned, you can expect to find a 0.1ms response time and up to 120Hz refresh rate alongside NVIDIA G-Sync, AMD FreeSync Premium, and VRR to “further improve gaming quality. Whether you game on consoles or on the cloud, the LG Game Dashboard and Game Optimizer put all the control at your fingertips.”.
It has been revealed that FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
🔗 Related Articles
📰 #23564. Deals: Galaxy SmartTag 3 up to 30% off, Chromebooks, Google Home Speaker, Walmart early Black Friday now live, more 📰 #23458. Tech Report: Deals: Early Black Samsung now live – Galaxy Fold 8 $350 off, S26 Ultra $450 off, Tabs from $200, more 📰 #20934. The Home Depot’s Early Black Friday Holiday Decor Sale Takes Up to 43% Off Christmas Trees and More
AI & Tech
⚖️ Neutral
🌐 Tomshardware
#11327. Researchers allege DeepSeek, Kimi, and other Chinese AI models were trained using banned Nvidia Blackwell GPUs
📅 14 Nov 2026 • ⏱️ 4m • 📚 Deep Dive (713 w)
Researchers allege DeepSeek, Kimi, and other Chinese AI models were trained using banned Nvidia Blackwell GPUs
📅 14 Nov 2026 | ⏱️ 4 min read (713 words, 📚 Deep Dive) | Source: Tomshardware
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that the topic of U.S.
- The scientists are careful to hedge their findings, noting that while their math checks out, it does not reveal where the chips were, how they were accessed, or prove that export controls were broken.
- This identification method is limited to models with open weights, and depends on both hardware and software stacks used for model training — and yet it's both clever and simple, like the Egg of Columbus.
Sources indicate that the topic of U.S. trade controls precluding the export of Nvidia and AMD high-end AI accelerator chips to China has taken a few twists lately. Jensen Huang's affairs aside, it's an open secret in the industry that Nvidia's Blackwell silicon finds its way into China, whether physically or virtually. UnemploymentLabs, an independent research outfit, has come up with strong evidence that those chips were used for training open-weight Chinese AI models, including DeepSeek V4, Kimi K3.1, MiniMax-M3, and Ling-3.1-Flash.
The scientists are careful to hedge their findings, noting that while their math checks out, it does not reveal where the chips were, how they were accessed, or prove that export controls were broken. As far as we can tell, it's presently not illegal for Chinese companies to rent Blackwell hardware abroad, and even though Nvidia's grip is tightening, U.S. companies aren't strictly prohibited from doing so, as evidenced by the recent Tencent-Oracle deal.
This identification method is limited to models with open weights, and depends on both hardware and software stacks used for model training — and yet it's both clever and simple, like the Egg of Columbus.
According to recent reports, let's establish some base facts. First, different AI accelerator families have unique counts of shader modules (SMs), marginally analogous to CPU cores — Nvidia's Hopper chips have 132, Blackwell B series have 148, and Blackwell GBs come with 152. Second, while there's more than one software stack for training AI models, PyTorch and its CUDA-aware friends are by far the most widely used on the green team's hardware.
It has been revealed that the first step for training a model is initializing its weights, or how strongly the model considers each individual input. In modern LLM architectures, their initialization goes through a randomization step in which their values are adjusted plus/minus pseudo-randomly, using cuRAND — as in, randomly, but a seed starting value results in the same adjustment figures every time.
According to recent reports, as you'd expect, doing this for an entire model is a lot of computational work, so this process is spread out across all the SMs, further subdivided into threads. For large weight sets, the thread count per SM is 2,048 for Blackwell and Hopper silicon, and it's surely carefully chosen and optimized for.
Sources indicate that the researchers repeated a facsimile of the initialization process using the same chips, software, and thread counts. Using relatively simple statistical analysis, they spotted that their final statistical distribution of weight values precisely matched that of DeepSeek, Kimi, et al. As a test, they changed the SM and thread counts, and predictably, the correlation completely broke down.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
Industry observers note that this let them pick out each family of Blackwell/Hopper chip used for each model, and eventually they also figured out an approximate count of cards used. They cannot, however, pinpoint which exact variation produced the weights, as this analysis is linked to initialization layout counts alone, thus SM count and usage pattern — not to VRAM capacity, memory bandwidth, or other characteristics that distinguish individual cards.
Industry observers note that what about AMD cards like the MI300X, or other silicon with a high enough SM count, using the same software stack? The scientists say that it's not impossible that an AMD card could be set up to show up as two groups of 152 or 148 shaders, although we imagine there'd be little reason to do so. Nevertheless, for DeepSeek V4, they also ruled out that possibility by analyzing the actual weight values themselves, and found that AMD cards still didn't produce the same weight value pattern.
Download the Tom's Hardware app for up-to-the-minute updates on iOS and Android. Also follow Tom's Hardware on Google News, or add us as a preferred source, to get our latest news, analysis, & reviews in your feeds.
Bruno Ferreira is a contributing writer for Tom's Hardware. He has decades of experience with PC hardware and assorted sundries, alongside a career as a developer. He's obsessed with detail and has a tendency to ramble on the topics he loves. When not doing that, he's usually playing games, or at live music indicates and festivals.

Gadgets
⚖️ Neutral
🌐 9to5google
#11326. Nintendo Switch 2 emulation on Android already has The Legend of Zelda: Ocarina of Time remake up and running
📅 10 Nov 2026 • ⏱️ 2m • 📖 Standard (346 w)
Nintendo Switch 2 emulation on Android already has The Legend of Zelda: Ocarina of Time remake up and running
📅 10 Nov 2026 | ⏱️ 2 min read (346 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- The Legend of Zelda: Ocarina of Time remake now runs surprisingly well on phones after just a week of additional emulator development.
- In a recent development, legend of Zelda fans all over the world have been marveling at the Ocarina of Time remake’s visuals and enhanced gameplay systems on the Nintendo Switch 2, but the Android emulator scene has been busy marveling over something just a little bit different.
- It has been revealed that ocarina of Time remake performance has now reached a major milestone into the 30 FPS territory with frame gen, which means the game is actually running at around 15 FPS, but then scaled and interpolated using AI frame generation to appear like 30 FPS.
The Legend of Zelda: Ocarina of Time remake now runs surprisingly well on phones after just a week of additional emulator development.
In a recent development, legend of Zelda fans all over the world have been marveling at the Ocarina of Time remake’s visuals and enhanced gameplay systems on the Nintendo Switch 2, but the Android emulator scene has been busy marveling over something just a little bit different. One Redditor got the latest Zelda game running on Banana Native, a free emulator that’s available right now on GitHub.
It has been revealed that ocarina of Time remake performance has now reached a major milestone into the 30 FPS territory with frame gen, which means the game is actually running at around 15 FPS, but then scaled and interpolated using AI frame generation to appear like 30 FPS. Banana Native isn’t a traditional emulator, as it doesn’t emulate hardware. Rather, it uses the game’s own ARM64 code to run on the phone’s CPU. The Switch 2 is powered by a mobile Nvidia chip, after all.
According to recent reports, the user is running the Ocarina of Time remake on a Poco F7 Ultra, which sports a two-generation-old Qualcomm Snapdragon 8 Elite (Gen 4) processor. The latest phones that are coming out, like the Redmagic 12 Pro, run a 6th-gen Snapdragon 8 Elite Extreme chip, so performance could be a lot better on a newer phone. Apps like Banana Native require specific driver support for each phone to run, and as I pointed out in my Redmagic 12 Pro review, platforms like Droid Deck and Game Native don’t yet have proper drivers for the newest chips.
9to5Google’s Damien Wilde recently reviewed Droid Deck, another native-type emulator that lets you legally play Steam games you own on your phone by just signing into your Steam account. It works extremely well on lots of Android phones and helps showcase just how far Android emulation has come this year.
FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
🔗 Related Articles
📰 #17150. Breaking: The Legend Of Zelda: Ocarina Of Time Remake Is Nintendo's Fastest-Selling Switch 2 Game Ever 📰 #16870. The Legend of Zelda: Ocarina of Time remake sells in huge numbers, becoming the fastest-selling Switch 2 game 📰 #16607. Latest Update: The Legend of Zelda: Ocarina of Time on Switch 2 is the US' best-selling physical game so far this year
General
⚖️ Neutral
🌐 Sitepoint
#11325. Industry News: How to Improve Email Deliverability Rates
📅 10 Nov 2026 • ⏱️ 7m • 📚 Deep Dive (1333 w)
Industry News: How to Improve Email Deliverability Rates
📅 10 Nov 2026 | ⏱️ 7 min read (1333 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- According to recent reports, 7 Day Free Trial.
- Then half your list never saw it, because it went straight to spam.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Weekly. Free. One click to leave.
According to recent reports, 7 Day Free Trial. Cancel Anytime.
You wrote a good email. You hit send. Then half your list never saw it, because it went straight to spam.
Industry observers note that that is a deliverability problem, and it costs more than most teams think. Every email that misses the inbox is a lead you paid for and never reached.
The good part is that deliverability is not luck. Mailbox providers like Gmail, Yahoo and Outlook judge you on a short list of things: who you are, who you send to, and how people react. Fix those and your inbox placement goes up.
This guide covers 10 email deliverability best practices in the order you should fix them, starting with SPF and ending with sender reputation.
Email deliverability is the share of your emails that land in the inbox instead of the spam folder or nowhere at all.
In a recent development, people often mix it up with delivery rate. They are not the same thing.
Industry observers note that you can have a 99% delivery rate and still have most of your emails sitting in spam. That is why your email tool can say "delivered" while your open rate keeps dropping.
The big mailbox providers stopped treating authentication as optional.
Sources indicate that microsoft followed on May 5, 2025. If you send more than 5,000 emails a day to Outlook.com, Hotmail or Live addresses, you need all three records in place or your mail goes to junk.
In a recent development, send less than 5,000 a day? Follow the rules anyway. The same checks decide inbox placement for small senders too, just without the public warning.
SPF (Sender Policy Framework) is a TXT record in your DNS. It lists the servers allowed to send email from your domain.
When your email arrives, the receiving server checks that list. If the sending server is not on it, the email looks suspicious.
A basic SPF record looks like this:.
DKIM (DomainKeys Identified Mail) adds a digital signature to each email. The receiving server uses a public key in your DNS to check two things: the email came from you, and nobody changed it on the way.
According to recent reports, your email provider gives you the DKIM record. You paste it into your DNS and switch signing on.
In a recent development, DKIM also survives forwarding, which SPF does not. If you can only get one of the two perfect, get DKIM right.
In a recent development, DMARC ties SPF and DKIM together. It tells mailbox providers what to do when an email fails both checks, and it sends you reports on who is sending mail under your domain name.
Start with a monitoring policy:.
p=none means "take no action, just send me reports." It is the minimum Gmail, Yahoo and Microsoft accept from bulk senders.
According to recent reports, don't stop there. Read the reports for a few weeks, fix any real sender that is failing, then move up:.
According to recent reports, one more thing: DMARC needs alignment. The domain in your From address has to match the domain used in SPF or DKIM. Plenty of senders have all three records and still fail DMARC because their email tool signs with its own domain.
If you'd rather not handle this in-house, you can also hire a B2B cold email marketing agency such as IntentSignal, Martal or Belkins. A good agency will set up the domains, mailboxes, warm-up and SPF, DKIM and DMARC records for you, and keep an eye on deliverability while the campaigns run.
A latest domain has no history. If it sends 10,000 emails on day one, it looks exactly like a spammer who just bought a domain.
Warm-up means starting small and growing a little each day, so mailbox providers can watch how people react to you.
A simple schedule for a new domain:.
Recent findings suggest that send to your most active contacts first. Their opens and replies are what build trust early. If bounces or complaints jump, hold at that volume until they settle.
According to recent reports, and if you run cold outreach, do it from a separate domain or subdomain. That way a bad campaign can't hurt the domain your invoices and password resets come from.
A bigger list is not a better list. Dead addresses and people who stopped caring pull your numbers down.
According to recent reports, never buy a list. Bought lists are full of spam traps, which are addresses that exist only to catch senders who email people without permission. Hitting a few of them can get your domain blocklisted.
According to recent reports, yes, you lose some sign-ups. What you keep is real people with working inboxes who actually want your emails. That means fewer bounces, fewer complaints and better opens from day one.
It also keeps bots and fake addresses out of your forms, which matters a lot if your sign-up form is public.
Most email platforms add these for you. Check that yours does.
These two numbers tell you the most about where you stand.
The complaint figures come from Gmail's own rules. The bounce figures are the working limits most email platforms use.
Sources indicate that A 0.3% complaint rate is only 3 complaints per 1,000 emails. It does not take much to cross that line.
If complaints are climbing, ask three questions:.
Most complaint problems come from one of those three, not from the email itself.
Spam filters got smarter. A single word like "free" won't sink you anymore. Patterns will.
According to recent reports, replies help a lot. When someone replies, the mailbox provider sees a real conversation. Ask a question in your welcome email and you'll get some.
In a recent development, sender reputation is the score mailbox providers give your domain and IP. Everything above feeds into it. A good score means inbox. A bad one means spam, no matter how good the email is.
You can't see the exact score, but these free tools get you close:.
Check them weekly, and right after any significant campaign.
A few habits protect your reputation over time:.
Industry observers note that aim for 95% or higher inbox placement. Below 90% means something needs fixing, usually authentication or list quality.
The common causes are missing or broken SPF, DKIM or DMARC records, a high complaint rate, an old list with lots of dead addresses, or a upcoming domain that sent too much too soon. Check authentication first because it is the fastest to fix.
Sources indicate that DNS fixes like SPF and DKIM take effect within a day or two. Reputation is slower. Expect two to six weeks of steady, clean sending before inbox placement recovers.
According to recent reports, yes. The 5,000 mark is where Gmail, Yahoo and Microsoft start enforcing openly. Small senders are still judged on the same signals, and Gmail asks every sender for at least SPF or DKIM.
Only if you send enough to keep it warm, roughly 100,000 emails a month or more. Below that, a good shared IP from a trusted provider usually performs better.
Sender reputation covers both your IP address and your domain. Domain reputation is the part tied to your domain name, and it follows you even if you switch email providers. Gmail leans on domain reputation more than IP.
If you only have an hour this week, spend it on SPF, DKIM and DMARC. Nothing else works until those pass.
Sources indicate that after that, clean your list and keep an eye on complaints. Send emails people asked for, to people who still want them, from a domain that proves who it is. Do that for a few weeks and your emails will land in the inbox again.
According to recent reports, 7 Day Free Trial. Cancel Anytime.
🔗 Related Articles
📰 #20569. Industry News: Senior ML Engineer - Email Security (remote work) at CloudLinux 📰 #18070. Industry News: A Good Pair of Pickleball Shoes Can Help Improve Your Game. Here Are Our Top Picks. 📰 #16318. Industry News: Microsoft blames monster email outage on software defect introduced in July fix
AI & Tech
⚖️ Neutral
🌐 Sciencedaily
#11324. MIT scientists build a tiny robot that swims using living muscle cells
📅 23 Oct 2026 • ⏱️ 7m • 📚 Deep Dive (1465 w)
MIT scientists build a tiny robot that swims using living muscle cells
📅 23 Oct 2026 | ⏱️ 7 min read (1465 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- A swimming robot does not necessarily need a bulky motor or powerful mechanical parts to move through water.
- The engineers developed an extremely thin swimming robot that uses living muscle tissue to move its fins.
- In a recent development, by directing light onto either fin, the researchers can trigger muscle contractions that make the fin flap and push the robot through water.
A swimming robot does not necessarily need a bulky motor or powerful mechanical parts to move through water. MIT researchers have demonstrated that a single, carefully engineered layer of living muscle cells can generate enough force to propel a tiny robot forward.
The engineers developed an extremely thin swimming robot that uses living muscle tissue to move its fins. Described in a newly introduced study published in Advanced Functional Materials, the device has a flexible gel framework roughly the length and width of a stick of gum. The gel forms two fins, each coated with a layer of muscle cells far thinner than a human hair. These cells have been genetically modified to contract when exposed to light.
In a recent development, by directing light onto either fin, the researchers can trigger muscle contractions that make the fin flap and push the robot through water. Adjusting which fin receives light and how frequently it is illuminated allows the team to control both its speed and direction.
In experiments, the remarkably thin robot successfully swam and turned through a simple underwater maze. At maximum speed, it covered approximately four times its body length per minute. Although that is much slower than an Olympic swimmer, who can travel up to 65 body lengths per minute, it is comparable to the swimming pace of a cow shark moving leisurely through the ocean.
"It takes a lot of force to move through water versus air," says study author Ritu Raman, associate professor of mechanical engineering at MIT. "The robot's quite strong, given its size. ".
A Newly introduced Generation of Robots Powered by Living Muscle.
The device represents the first demonstration of a very thin, two-dimensional robot that can move from place to place using living muscle tissue.
Recent findings suggest that most existing biohybrid robots rely on relatively large, three-dimensional structures made from laboratory-grown skeletal muscle. Producing these structures typically requires millions of cells. Raman explains that thinner designs could reduce manufacturing costs while potentially improving movement efficiency.
In a recent development, "At the moment, biohybrid robots from our group and others' are built from bulky, 3D chunks of lab-grown skeletal muscle that require millions of cells to fabricate," states Raman, who notes that thinner, less bulky designs such as the team's fresh bot could be cheaper to build and could move more efficiently. "We believe that biohybrid robots powered by living muscle could one day perform delicate jobs like exploring environments too fragile or unpredictable for conventional hardware, because living tissue is soft, responsive to its surroundings, and can heal itself.".
The MIT research team also included first author Maheera Bawa, along with Arielle Berman, Laura Schwendeman, Ferdows Afghah, and Seanbiron Johnson.
From Artificial Muscle to a Swimming Robot.
The new swimming robot builds on an earlier achievement by Raman's laboratory. Last year, the researchers created an artificial muscle disk inspired by the human iris, demonstrating how a thin layer of living cells could produce precisely controlled movements.
Sources indicate that for that project, the engineers patterned a gel disk with grooves extending outward from its center and forming concentric circles. They then placed living muscle cells on the surface, where the cells grew into a thin layer following the patterned channels.
When illuminated, the muscle tissue contracted in different directions, causing the disk to stretch and compress. Its movements resembled the way the iris of the human eye changes shape as the pupil expands or narrows.
The experiment established that researchers could grow extremely thin muscle layers in intricate arrangements and use light to control their movements along multiple directions.
According to recent reports, "People hadn't seen this muscle architecture engineered from scratch before," Raman notes. "And the cells were moving in multiple directions. But they only moved about 100 microns. From a robotics perspective, their movements were tiny.".
For the latest project, the researchers wanted to dramatically increase the amount of movement and force generated by the muscle cells. Their goal was to produce contractions powerful enough to propel a robot through water.
They determined that achieving this would require a better foundation for the living muscle tissue.
The earlier artificial iris had used fibrin, an exceptionally soft gel, as its underlying structure. However, the team found that fibrin could swiftly shrink under the forces exerted by contracting muscle cells, limiting the effectiveness of the resulting movement.
To overcome this problem, the engineers investigated three characteristics of the gel foundation: its chemical composition, its stiffness, and the dimensions and geometry of the grooves used to organize muscle growth.
Recent findings suggest that "For engineering any type of tissue, it's known that these are knobs you can tune," Raman says. "And we wanted to optimize all these parameters to support live muscle cells.".
Engineering a Stronger Muscle-Powered Robot.
Finding the right supporting material required testing gels with different formulations, stiffness levels, and surface patterns.
The researchers compared several groove shapes, including narrow channels with square profiles and longer channels with curved bottoms. They discovered that muscle cells aligned more effectively inside square-shaped grooves.
Recent findings suggest that this alignment was key because muscle cells that grow in the same direction are more likely to merge into fibers. Those fibers can then form stronger muscle tissue that contracts in a coordinated way. The square grooves therefore provided a more effective structure for producing force.
The team also replaced fibrin with gelatin methacrylate (GelMA), a material commonly used to grow and engineer biological tissue.
According to recent reports, by adjusting the formulation of GelMA, the researchers produced supporting gels with varying degrees of stiffness. They then examined how muscle cells developed on each surface and measured their ability to generate force.
Recent findings suggest that stiffer gels produced the best results. On these firmer surfaces, muscle cells grew in better alignment and generated stronger contractions.
The engineers next investigated how thick the gel should be. They determined that a film measuring approximately half a millimeter offered an effective balance. It was sturdy enough to support a single layer of muscle cells while remaining sufficiently lightweight to prevent the contracting cells from detaching from the surface.
The team further improved muscle performance through a form of exercise. Repeated pulses of light stimulated the cells to contract, strengthening the muscle tissue before it was incorporated into the swimming robot.
How Light Makes the Living Robot Swim.
With the gel structure optimized and the muscle cells strengthened, the researchers assembled their swimming device.
Industry observers note that the finished robot consisted of a thin gel framework divided into two fins. Both sides of the gel were patterned with square-bottomed grooves and covered with living muscle cells. As the cells developed, they fused into organized muscle fibers capable of contracting together.
Each fin could be activated independently using light, giving the researchers a simple way to control the robot's movements.
Industry observers note that "You can think of the robot as having two independent muscles," Raman says. "If we shine a light on just one, only that muscle moves. If shining on both, they both flap.".
Industry observers note that to test the device, the researchers placed it inside a large petri dish filled with water. They then moved a light source by hand, illuminating the fins to guide the robot through a maze positioned inside the dish.
Industry observers note that as the muscles contracted, the fins flapped and propelled the robot through the water. By changing the light stimulation, the engineers successfully controlled its movement and helped it navigate the obstacles.
Although the robot demonstrated the ability to swim and steer, its current shape remains relatively simple. The primary objective of the experiment was to establish that an exceptionally thin layer of engineered muscle tissue could generate enough force for swimming.
The researchers now plan to refine the robot's body to improve its speed. Beyond demonstrating a new approach to biohybrid robotics, the technology could eventually be useful for monitoring aquatic environments or operating in locations where conventional rigid machines might cause damage.
Recent findings suggest that "Our next goal is to optimize the body design to enable faster swimming," Raman says. "But even at slow swim speeds, one could imagine a muscle-powered swimmer being used for purposes like environmental monitoring in aquatic environments.".
The Office of Naval Research provided partial funding for this research.
Sources indicate that materials provided by Massachusetts Institute of Technology. Original written by Jennifer Chu. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.

AI & Tech
⚖️ Neutral
🌐 9to5google
#11323. Google Pixel Tag Initial Review: The gold standard for Find Hub trackers, whatever that’s worth
📅 10 Nov 2026 • ⏱️ 5m • 📚 Deep Dive (1031 w)
Google Pixel Tag Initial Review: The gold standard for Find Hub trackers, whatever that’s worth
📅 10 Nov 2026 | ⏱️ 5 min read (1031 words, 📚 Deep Dive) | Source: 9to5google
⏱️ ~5 mins left to finish
📖 0% read
💡 Key Takeaways
- Recent findings suggest that google’s Find Hub had a tumultuous launch for its performance, but also for a lack of clear direction in hardware.
- Google Pixel Tag is now available for purchase at the Google Store and Amazon.
- There are plenty of really good Android Find Hub trackers on the market.
Recent findings suggest that google’s Find Hub had a tumultuous launch for its performance, but also for a lack of clear direction in hardware. Over two years later, that’s finally arriving in the Google Pixel Tag which, even just a few days in, is the obvious gold standard in the race to build an AirTag for Android devices.
Google Pixel Tag is now available for purchase at the Google Store and Amazon.
There are plenty of really good Android Find Hub trackers on the market. Pebblebee and Chipolo have been long-standing examples of how to build good dual-network trackers that work on both Android and iOS, while Motorola’s Moto Tag series has delivered two Android-only trackers that deliver better performance and more focused features. But even with the Moto Tag, there’s a clear compromise. Features like the ability to ring your phone are tied to a separate app and, in turn, have some inherent clunkiness.
Pixel Tag is the device that finally brings it all together, and it’s brilliant so far.
In a recent development, I’ve only had the Pixel Tag for a week and, frankly, it’s impossible to properly review a tracker in that time. There are only so many ways to artificially test out how a tracker works, as most cases where you’ll find value in this sort of product can only occur in real life.
So, with that said, let’s focus on the fundamentals.
Google Pixel Tag pairs to your Android phone just like any other Find Hub tracker – though much faster compared to some others I’ve tested – but the differences are obvious towards the end of that process. The final screen shows options for setting ringer volume and an option to set up “Ring this phone.”.
Those latest features are what make the Pixel Tag so good, and so appealing compared to all of the competition. A quick double-tap on the Tag’s button rings whichever phone you connected it to, assuming it’s in range, and it works pretty reliably. You can also set up “left behind” alerts (now available on other Find Hub trackers too) for when the phone leaves the tracker behind – you can set up exclusion zones such as your home or work address.
In a recent development, one of my favorite examples of the added polish from Google is the ability to adjust the ringer volume on the page where you actually want to ring the tracker. In a crowded but quiet space where you know the tracker is close by, being able to swiftly set the volume to low is a great addition. In my book, it’s the reason to buy Pixel Tag over any other Android tracker.
UWB, of course, only makes up-close finding all the better. I found this decently reliable on my Pixel 11 Pro XL, but it is a little bit frustrating that the directional cues vanish within about 10-12 feet. Fine for a backpack or something like that, potentially a problem if your Tag is attached to a set of keys.
According to recent reports, on that note, my biggest hardware complaint is that Google took the Apple route of having no built-in mounting mechanism. The super thin and light hardware of Pixel Tag is wonderful, don’t get me wrong, but being forced to buy a separate accessory just to attach it to my bag is frustrating! One of Google’s partners, Bellroy, built one of these accessories and it’s simple enough – a silicone case with a rope. I wish I didn’t need it, but it works, and at least you get two of them in a pack for $25.
According to recent reports, the hardware itself is pretty good across the board, really, with the battery door also being slightly easier to open compared to the Moto Tag. Inside is a standard CR2032 battery that Google claims will last “over one year.” I’d personally still prefer a rechargeable battery with USB-C or wireless charging, but this is a good enough solution given the amount of time the battery lasts – hopefully Google’s claim lives up.
According to recent reports, rounding out some of the key aspects here, it’s worth saying that the built-in speaker is more than loud enough at its highest setting, but the value for me so far has really come in that the low setting is actually low enough to not be a nuisance. I do find it a little strange that there’s no visual indication of where the Tag’s button is, but the packaging and app both do a good enough job of letting you know.
It has been revealed that I really just wish it would have a rechargeable battery, preferably via USB-C. It would have been the only tracker on the market to support UWB and be rechargeable.
According to recent reports, overall performance in Find Hub seems fine, but as mentioned at the outset, this is a really hard thing to test artificially, all the more so in the span of just a few days. Google’s Find Hub network has gotten a lot better in the past two years, but it’s still hit or miss in my experience. It’s very clear that Google is making an effort to reverse the privacy-inspired decision to effectively disable the Find Hub network outside of crowded areas, but the damage has been done. I’m not sure the network will ever fully recover from that misstep, regardless of what tracker you’re using it with.
I’m looking forward to seeing how Pixel Tag performs as the travel season spins back up, so stay tuned for a later long-term review of Google’s tracker in the coming months. Initial impressions, though, are solid. Sound off in the comments below if you have any questions around Pixel Tag, I’ll answer everything I can!
Google Pixel Tag is now available at the Google Store and Amazon.
Follow Ben: Twitter/X, Threads, Bluesky, and Instagram.
FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Ben is a Senior Editor for 9to5Google.
Sources indicate that find him on Twitter @NexusBen. Send tips to schoon@9to5g.com or encrypted to benschoon@protonmail.com.
🔗 Related Articles
📰 #23489. Pixel Tag is a brilliant Band-Aid on a Find Hub network Google can’t easily fix 📰 #11319. Pixel Tag tidbits: Surprise NFC, Find Hub setup, & Bellroy keychain cases 📰 #23646. Deals: Google Pixel Tag, Pixel Watch 5 $100 off, Googlebook from $680, Lenovo Yoga Mini $460 off, more
AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11322. We Got Claude to Build CUDA Kernels and teach open models!
📅 28 Jan 2026 • ⏱️ 8m • 📚 Deep Dive (1651 w)
We Got Claude to Build CUDA Kernels and teach open models!
📅 28 Jan 2026 | ⏱️ 8 min read (1651 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~8 mins left to finish
📖 0% read
💡 Key Takeaways
- The best thing about agent skills is upskilling your agents on hard problems.
- This blog post walks through the process of using a new tool, upskill, to generate and evaluate agent skills with large models and use them with smaller models.
- In case you missed it, agent skills are taking the coding agent game by storm.
The best thing about agent skills is upskilling your agents on hard problems. There are two ways to look at that:.
This blog post walks through the process of using a new tool, upskill, to generate and evaluate agent skills with large models and use them with smaller models. We will benchmark upskill on the task of writing CUDA kernels for diffusers models, but the process is generally useful for cutting costs, or using smaller models on hard and domain-specific problems.
In case you missed it, agent skills are taking the coding agent game by storm. In fact, they’re a straightforward concept to define model context as files, like instructions as markdown and code as scripts. The file format makes them easy to generate, share, and review. In short, they’re a practical medium to share capabilities across models and tools, and they're most useful in specific domains or hard problems. Not stuff the model can do well anyway.
This post showcases this process by using Claude to generate a Skill file that can be used by open source models for a complex and specialized task: write CUDA kernels. We first tried a simple skill based on existing documentation, and we found that it improved performance for some others, but not all. In fact, it could even degrade performance or increase token usage for some models. Check out the plot below to see the performance of the model with and without the basic skill.
Now, let's walk through how you can use upskill to upskill your agents on hard problems, and measure performance.
First, we use Claude Code to build a kernel interactively and export the trace. We worked through the process by instructing, validating, and adding documentation links. This somewhat naive process is notable to reveal the models' initial challenges. In fact, you can iterate on this multiple times, by trying to solve the task with draft versions of the skill, and experimenting with smaller models. Each time, you can instruct the agent to improve the skill and test it on the smaller model.
In a recent development, here's an example of the skill that we created and have been using to build kernels. We started from this agent trace where the agent was able to build a kernel, but not without some help.
Recent findings suggest that once the teacher model has performed the task, we need them to make a skill. There are a number of effective ways to do this.
In most cases, the first 2 options result in functional skills. However, the performance of an agent with the skill is unknown. That’s where upskill is useful, because it will also generate test cases for your skill based on the trace. It then compares the results under both scenarios: using the trace, or applying the skill. We see below that the original model (Claude Opus) met the same performance with and without the skill. This means the skill captured the task for this model. Great!
Finally, we need to transfer our newly created skill to the tool or model we intend to use. Most tools like codex, cursor, and opencode have settled on a consistent format for skills, which is a directory at {agent}/skills/{skill_name}/SKILL.md , so we just need to copy the skill directory to this location.
With upskill we can pass a skill and a set of models to the eval command and upskill will run the test cases on those models with and without the skill to compare performance. We can see here that the skill increases accuracy on some open models, but not on all.
In this case, we might want to iterate further on the gpt-oss skills by regenerating the skill. We can do upskill generate --from {skill}.
There is more to agent skills than model performance. Often agents can reach a given accuracy with or without a skill, they just need to consume more tokens to get there. For recurring tasks, we want to optimize agents to use less tokens to achieve the same accuracy. The results below reveal another dimension to the skill. Some models are significantly reducing their performance token usage, whilst others are using more tokens with the skill. For example, with moonshotai/Kimi-K2-Thinking the skill is clearly effective in terms of accuracy and token usage. However, for Claude Opus 4.5 there is no clear performance increase and an increase in token usage, so you would not want to use this skill with Claude Opus 4.5.
Recent findings suggest that tldr; try out and evaluate models with the skills you create. Use upskill eval or a similar tool to evaluate the models performance with and without skills.
In a recent development, that’s the high level end to end of upskilling your coding agents on hard problems. Try out upskill now like this:.
We have a high level understanding of how we can upskill an agent. Let’s now look at the use case we solved for writing CUDA kernels.
We didn’t just want to write kernel code, but understand the full kernel-builder workflow: project structure, build.toml configuration, architecture-specific optimizations, and PyTorch bindings. This tutorial indicates how upskill creates validated skills that actually work.
The kernel-builder-cuda-kernels skill teaches Claude everything it needs to know about CUDA development: which GPU architecture to target, how to structure a kernel-builder project, when to use shared memory versus registers, and how to write PyTorch bindings.
With this skill, you can tell Claude things like:.
And Claude will create the complete project structure, CUDA implementation, and build configuration—following the exact conventions that kernel-builder expects.
This isn't about generating boilerplate. The skill encodes domain expertise: H100 uses compute capability 9.0, shared memory should be aligned to 128 bytes, async memory copies require __CUDA_ARCH__ >= 900. Knowledge that would take hours to gather from documentation gets packaged into ~500 tokens that load on demand.
That's it. Upskill uses Anthropic Claude Opus-4.5 model by default but also supports OpenAI and local models via OpenAI-compatible endpoints as generators. We want to use the more expensive and higher quality models to generate skills, and the smaller ones to use them. Think robin hood.
Let's walk through generating a skill that teaches agents how to build CUDA kernels with HuggingFace's kernels library.
Start with a clear task description:.
Above we used upskill, but it could in fact be any agent or chat tool and an exported trace.
Also, we could start from an existing skill and add to it:.
upskill loads the existing skill, applies your improvements, and re-evaluates to ensure the changes help.
upskill creates a skill, generates test cases, evaluates performance, and refines based on failures:.
It has been revealed that the baseline reveals how the model performs without any skill. The "with skill" result shows performance after the skill is injected into context. A 35% improvement means the skill is working.
The skill is saved as a directory following the Agent Skills specification:.
The crucial test is: does this skill help local or cheaper models to build kernels?
A 45% improvement on "unsloth/GLM-4.7-Flash-GGUF:Q4_0" means the skill successfully transfers domain knowledge from a capable model to a faster, cheaper one. Skills that work on weaker models will definitely work on stronger ones.
This is the core value proposition: use expensive models to create skills, then deploy those skills with cheap or local models.
upskill uses a teacher-student approach to evaluate models where the teacher model generates test cases for the student model to be evaluated on.
According to recent reports, if you pass an existing skill to upskill eval, it will generate test cases for the skill and evaluate the model on them. Test cases are simple input/output pairs that verify the agent understands the task:.
We can also test how a skill performs across different models:.
This helps you find the cost-performance sweet spot: maybe Haiku with the skill is good enough for your use case, saving significant API costs.
Sources indicate that we've shown that upskill can create validated skills that transfer domain expertise from powerful models to cheaper ones. The kernel-builder skill is just one example of what's possible.
The approach works for any specialized task where you'd otherwise write detailed prompts repeatedly. Skills are portable across Claude Code, Codex, Cursor, and other tools that support the Agent Skills specification.
This article is very inspiring to me.
Great post! Haven't tried upskill yet, but I'll give it a shot.I think the agent trace link is broken — it points to trace.md but the actual file is agent-trace.txt: https://huggingface.co/hf-skills/h100-diffusers-kernel-builder/blob/main/agent-trace.txt.
Industry observers note that thank you @ClementeH ! Would you like to open a PR to fix it? :) If you don't have time we'll do it!
Thanks for this article! Can this be replicated to use open-source models such as Qwen/Qwen3-30B-A3B-Thinking-2507 to generate the agent trace and the skill file? From my initial exploration, I assume it requires an API key from Anthropic to generate and evaluate skills.
It can -- the only place where a model string is included is here: https://github.com/huggingface/upskill/blob/16a688fa32e03ee6859f01f3e13f23986e67006f/src/upskill/agent_cards/test_gen.md?plain=1#L5 where we use Opus' structured output to generate test cases. All else should be configurable from the --model switch.
Sources indicate that we need to talk about the 'magic' behind Claude’s CUDA kernels. Is it superior synthetic data, or did Anthropic find a better way to teach LLMs hardware-level logic? Open to all technical theories.
Upskill generate worked mostly as intended, but when I tried to do the actually interesting part and ran upskill eval, everything started falling apart.
A few concrete issues I hit (Windows + Ubuntu/WSL):.
Model selection confusion / fast-agent flag collision.
Provider / model parameter mismatches.
In a recent development, overall: the concept is awesome, but eval is super brittle right now. Did anyone get eval actually working reliably?
Thanks for the feedback - we're planning a sweep of PR/Problems early next week, and considering incorporating a sandbox mechanism!
Hardware & Chips
⚖️ Neutral
🌐 Tomshardware
#11321. AMD's fastest gaming CPU and the Radeon RX 9070 just hit a massive $550 discount
📅 14 Nov 2026 • ⏱️ 2m • 📖 Standard (468 w)
AMD's fastest gaming CPU and the Radeon RX 9070 just hit a massive $550 discount
📅 14 Nov 2026 | ⏱️ 2 min read (468 words, 📖 Standard) | Source: Tomshardware
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that building a gaming PC is expensive, especially with ongoing price inflation for memory, storage, and graphics cards.
- It has been revealed that the prebuilt system is powered by AMD’s Ryzen 7 9800X3D, which is regarded as the gold standard for gaming PCs.
- In a recent development, the CPU is paired with an AMD B650 M-ATX motherboard that offers built-in Wi-Fi 6 and Bluetooth, gigabit Ethernet, and multiple USB ports.
Sources indicate that building a gaming PC is expensive, especially with ongoing price inflation for memory, storage, and graphics cards. Putting together a balanced system with a high-end gaming CPU and a capable graphics card can quickly push budgets beyond what many enthusiasts are willing to spend. If you'd rather skip the hassle of sourcing individual components, we've found a compelling deal on a CyberPowerPC prebuilt gaming desktop, currently available at Best Buy and eBay for $1,749.99. That's a substantial $550 discount off its original price of $2,299.99.
It has been revealed that the prebuilt system is powered by AMD’s Ryzen 7 9800X3D, which is regarded as the gold standard for gaming PCs. This 8-core, 16-thread chip may not be the fastest desktop CPU, but thanks to its 3D V-Cache, it reduces how often your CPU has to fall back on system RAM, drastically improving frame rates while gaming. It also has a modest power draw, making it our pick for the best gaming CPU on the market.
In a recent development, the CPU is paired with an AMD B650 M-ATX motherboard that offers built-in Wi-Fi 6 and Bluetooth, gigabit Ethernet, and multiple USB ports. For memory, there's 32GB of dual-channel DDR5-5600 RAM along with a 1TB SSD for storage. There are also additional M.2 and SATA ports for future storage expansion.
The CyberPowerPC desktop combines AMD's Ryzen 7 9800X3D with a Radeon RX 9070 featuring 16GB of VRAM, alongside 32GB of DDR5 memory and a 1TB SSD, making it a capable option for 1440p and 4K gaming.
In a recent development, powering the graphics is AMD’s Radeon RX 9070, featuring RDNA 4 architecture, 16GB of GDDR6 VRAM, and 56 Compute Units. The GPU can handle 1440p and 4K gaming and has a rated TDP of 220W. As per our 16-game rasterization geomean, the RX 9070 averages 86.6 FPS at 1440p Ultra settings and 52.2 FPS at 4K Ultra settings.
The system is built inside a premium mid-tower chassis with dual USB Type-A and Type-C ports at the front and an RGB LED strip running across the front and side glass panels. It also includes a 360mm AIO liquid cooler, five additional ARGB case fans, an 850W power supply unit, and an RGB keyboard and mouse bundle.
At its discounted price of $1,749.99, this CyberPowerPC prebuilt offers great value for anyone looking to purchase a high-end gaming system. The deal is currently available at Best Buy, but you can also buy it for the same price on eBay.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
Kunal Khullar is a contributing writer at Tom’s Hardware. He is a long time technology journalist and reviewer specializing in PC components and peripherals, and welcomes any and every question around building a PC.
Hardware & Chips
⚖️ Neutral
🌐 Sciencedaily
#11320. Latest Update: Cambridge scientists create a $10 chip that could put a medical lab on your wrist
📅 23 Oct 2026 • ⏱️ 7m • 📚 Deep Dive (1316 w)
Latest Update: Cambridge scientists create a $10 chip that could put a medical lab on your wrist
📅 23 Oct 2026 | ⏱️ 7 min read (1316 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- Recent findings suggest that A new optical sensor costing just $10 could bring laboratory-level precision to wearable health monitors, potentially allowing people to track blood glucose without needles.
- According to recent reports, researchers at the University of Cambridge and GlitterinTech (a start-up founded by the same research group) have developed a latest type of optical spectrometer that combines exceptional accuracy with a remarkably small size and low cost.
- Optical spectrometers work by analyzing light to reveal information about the substances it interacts with.
Recent findings suggest that A new optical sensor costing just $10 could bring laboratory-level precision to wearable health monitors, potentially allowing people to track blood glucose without needles. The technology could also transform food testing, industrial quality control, and environmental monitoring.
According to recent reports, researchers at the University of Cambridge and GlitterinTech (a start-up founded by the same research group) have developed a latest type of optical spectrometer that combines exceptional accuracy with a remarkably small size and low cost. Measuring just centimeters across, the device could be incorporated into portable electronics and wearable health technology. Its potential applications range from monitoring notable health markers in real time to identifying materials and detecting changes in chemical composition.
Optical spectrometers work by analyzing light to reveal information about the substances it interacts with. They are essential tools in medicine, manufacturing, chemical testing, and environmental research. However, making these instruments smaller has traditionally meant compromising their performance. Compact spectrometers often have limited measurement ranges, reduced resolution, or lower accuracy, making them better suited to identifying substances than performing precise measurements.
Sources indicate that the researchers believe their latest design could overcome these limitations. Known as a convolutional spectrometer, it uses a mathematical principle called the convolution theorem to analyze light in a fundamentally different way. According to the team, this approach delivers performance that surpasses existing types of spectrometers in several key areas, including designs based on light dispersion, Fourier transforms, and computational reconstruction.
A Newly introduced Way to Analyze Light With Extraordinary Precision.
Traditional spectrometers generally separate incoming light into its component wavelengths or use complex calculations to reconstruct its spectrum. The new device takes another approach by performing a mathematical operation called convolution directly on the incoming light.
To accomplish this, the researchers arranged optical components with repeating spectral responses in a sequence. These components can include unbalanced Mach-Zehnder interferometers or micro-ring resonators. By adjusting them in proportion to one another, the system can shift its response to different wavelengths in a controlled, linear fashion. Fast Fourier transforms are then used to accurately recover the light spectrum.
It has been revealed that "The key insight was to go back to the mathematics and ask whether there was a fundamentally cleaner way to retrieve spectra," said Dr. Chunhui Yao, a lead author of the study. "By using the convolution theorem directly in the optical domain, we avoid many of the limitations that have held miniaturized spectrometers back. This gives us high precision, strong noise tolerance, and very low computational overhead, all in a compact and low-cost system.".
Recent findings suggest that the researchers built the spectrometer using a silicon nitride photonic platform and integrated it with onboard electronics. It operates across a broad range of near-infrared wavelengths (1200-1700 nm) and can collect and process measurements in less than a second.
Another crucial advantage is its ability to expand its measurement capabilities without major hardware changes. Because the system uses repeating optical patterns, its spectral bandwidth can theoretically be extended almost without limit. Adding more optical components in sequence can also increase its resolution exponentially.
A $10 Sensor That Could Transform Food Testing and Healthcare.
It has been revealed that to evaluate the device outside purely theoretical measurements, the researchers tested it on a variety of materials and substances. The results demonstrated its potential for applications that normally depend on larger, more expensive laboratory instruments.
Recent findings suggest that when used to identify plastics, pharmaceuticals, coffee, flour, and tea, the spectrometer achieved a 100% classification success rate in the reported tests. It also measured concentrations in water-based and organic solutions with accuracies of approximately 0.01%, exceeding the performance of commercial benchtop spectrometers in those experiments.
Industry observers note that the healthcare demonstrations were particularly promising. Under conditions designed to reflect real physiological environments, the device accurately measured several human biomarkers, including skin moisture, blood alcohol, blood lactate, and blood glucose.
Sources indicate that the researchers also demonstrated noninvasive glucose tracking over an extended period in one participant. Although further testing would be needed before the technology could become a practical medical product, the finding suggests a possible route toward monitoring blood sugar without repeatedly piercing the skin.
"These biomedical demonstrations are particularly exciting," noted Prof. Qixiang Cheng, who led the project. "What makes this work stand out is not just performance in the lab, but technical readiness. Dr. Chunhui Yao's contribution was crucial in translating a mathematical concept into a fully packaged, robust system that operates reliably across temperature extremes and real-world conditions. That combination is what opens the door to practical deployment.".
The sensor also demonstrated impressive resistance to temperature changes. It continued operating reliably between -20°C and 80°C, an unusually wide temperature range for a miniature spectrometer. This durability could be especially valuable for wearable devices, factory equipment, and sensors operating outdoors.
Why a Simpler Design Could Be a Major Breakthrough.
Recent findings suggest that the new spectrometer's advantages extend beyond its accuracy, size, and price. Its internal design also reduces the amount of computing power needed to analyze incoming light.
Many existing miniature spectrometers depend on complicated calibration procedures and demanding algorithms to reconstruct spectral information. These methods can become unreliable when measurements contain noise, and they often require substantial processing resources.
Recent findings suggest that the Cambridge team's convolution-based approach avoids much of this complexity. Because the measurements follow a linear mathematical relationship, the system can recover spectra rapidly and consistently while using relatively little computational power.
In a recent development, "This is a beautiful example of how elegant engineering can unlock real impact," stated Prof. Richard Penty, who contributed to the photonic system design and integration. "The architecture is simple, scalable, and manufacturable, yet it delivers precision that rivals or exceeds much larger instruments. Dr. Chunhui Yao played a central role in bringing together the photonic design, system integration, and experimental validation that made this possible.".
Its relatively simple construction could also make the technology easier to manufacture on a large scale, potentially bringing sophisticated optical measurements to devices where conventional spectrometers would be too bulky or expensive.
Bringing Laboratory-Grade Measurements to Everyday Devices.
The researchers envision a future in which accurate optical sensing becomes a routine feature of everyday technology rather than something largely confined to specialized laboratories.
In industrial settings, inexpensive spectrometers could be installed throughout manufacturing facilities to continuously check material composition and product quality. Similar sensors could monitor food freshness, identify substances, and analyze environmental conditions on a much larger scale than is at the moment practical.
Healthcare could see equally significant changes. Compact sensors might eventually enable wearables to measure hydration levels, detect signs of alcohol intoxication, track biomarkers related to physical fitness, or continuously monitor glucose levels for people managing diabetes.
Sources indicate that "Our vision is to make spectrometry as ubiquitous as temperature or motion sensing," added Prof. Qixiang Cheng. "This work demonstrates that high-quality spectral information doesn't have to be confined to the laboratory -- it can be embedded directly into the technologies people use every day.".
In a recent development, as photonic technology becomes smaller and more advanced, the convolutional spectrometer provides a promising example of how mathematical insights and practical engineering can make sophisticated scientific instruments simpler, cheaper, and more accessible. By combining high precision with a device that costs around $10, the researchers have opened a potential path toward a new generation of smart sensors capable of measuring the hidden chemistry of our bodies and surroundings.
According to recent reports, materials provided by University of Cambridge. Original written by Michael Shuff. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Fresh Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #22623. Scientists create a needle-thin brain implant that can do three jobs at once 📰 #22570. Scientists discover a natural compound that could protect the brain from too much salt 📰 #19483. Scientists Uncover a Bizarre Quantum Effect Where Time Could Flow at Different Speeds Simultaneously
Gadgets
📈 Bullish
🌐 9to5google
#11319. Pixel Tag tidbits: Surprise NFC, Find Hub setup, & Bellroy keychain cases
📅 10 Nov 2026 • ⏱️ 2m • 📖 Standard (337 w)
Pixel Tag tidbits: Surprise NFC, Find Hub setup, & Bellroy keychain cases
📅 10 Nov 2026 | ⏱️ 2 min read (337 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Industry observers note that the Made by Google 2026 lineup is finally complete with tomorrow’s retail launch of the Pixel Tag.
- The Pixel Tag is the first Find Hub tracker with NFC.
- Sources indicate that on Android 17 QPR2, tapping immediately opens the details page.
Industry observers note that the Made by Google 2026 lineup is finally complete with tomorrow’s retail launch of the Pixel Tag. You can find our review here, while there are some additional details about the device since the August announcement.
The Pixel Tag is the first Find Hub tracker with NFC. Google did not mention this connectivity specification in August, with Near Field Communication letting you tap the tracker to the back of your phone to immediately open device settings. The NFC area on the Pixel Tag is below the circular battery door, which you hold down and twist counterclockwise to open.
Sources indicate that on Android 17 QPR2, tapping immediately opens the details page. On QPR1, you first get a system notification that you need to click. NFC joins Bluetooth 6.0 with Channel Sounding and Ultra Wideband (UWB).
It has been revealed that the Pixel Tag has a physical button on the rear side below the battery cover. Clicking twice plays a loud sound on your phone if both devices are nearby. Once found, you can tap the button once to silence, or turn it off from your phone. This feature can be disabled from the Pixel Tag’s device details page on a tracker-by-tracker basis.
Google does not have a first-party case for the Pixel Tag. Instead, it’s working with Made for Google partner Bellroy.
Industry observers note that there are two models available from the Google Store, with the first made of silicone. The Bellroy Lite Case Duo costs $24.99 and comes in a pack of two: Mist and Shadow colorways. It wraps everything but the face of the Pixel Tag (and its speaker cutout), while giving you a hole in the corner and color-matching cord.
There’s also the Bellroy Leather Tag Case in Artichoke, Azalea, Black, Pewter, and Red Ochre for $29.99.
FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Editor-in-chief. Interested in the minutiae of Google and Alphabet. Tips/talk: abner@9to5g.com.

General
⚖️ Neutral
🌐 Hugging Face
#11318. Latest Update: Introducing Daggr: Chain apps programmatically, inspect visually
📅 29 Jan 2026 • ⏱️ 6m • 📚 Deep Dive (1165 w)
Latest Update: Introducing Daggr: Chain apps programmatically, inspect visually
📅 29 Jan 2026 | ⏱️ 6 min read (1165 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- Industry observers note that TL;DR: Daggr is a new, open-source Python library for building AI workflows that connect Gradio apps, ML models, and custom functions.
- If you've built AI applications that combine multiple models or processing steps, you know the pain: chaining API calls, debugging pipelines, and losing track of intermediate results.
- Most developers either build fragile scripts that are hard to debug or turn to heavy orchestration platforms designed for production pipelines—not rapid experimentation.
Industry observers note that TL;DR: Daggr is a new, open-source Python library for building AI workflows that connect Gradio apps, ML models, and custom functions. It automatically generates a visual canvas where you can inspect intermediate outputs, rerun individual steps, and manage state for complex pipelines, all in a few lines of Python code!
If you've built AI applications that combine multiple models or processing steps, you know the pain: chaining API calls, debugging pipelines, and losing track of intermediate results. When something goes wrong in step 5 of a 10-step workflow, you often have to re-run everything just to see what happened.
Most developers either build fragile scripts that are hard to debug or turn to heavy orchestration platforms designed for production pipelines—not rapid experimentation.
We've been working on Daggr to solve problems we kept running into when building AI demos and workflows:.
In a recent development, visualize your code flow: Unlike node-based GUI editors, where you drag and connect nodes visually, Daggr takes a code-first approach. You define workflows in Python, and a visual canvas is generated automatically. This means you get the best of both worlds: version-controllable code and visual inspection of intermediate outputs.
It has been revealed that inspect and Rerun Any Step: The visual canvas isn't just for show. You can inspect the output of any node, modify inputs, and rerun individual steps without executing the entire pipeline. This is invaluable when you're debugging a 10-step workflow and only step 7 is misbehaving. You can even provide “backup nodes” – replacing one model or Space with another – to build resilient workflows.
First-Class Gradio Integration: Since Daggr is built by the Gradio team, it works seamlessly with Gradio Spaces. Point to any public (or private) Space and you can use it as a node in your workflow. No adapters, no wrappers—just reference the Space name and API endpoint.
According to recent reports, state Persistence: Daggr automatically saves your workflow state, input values, cached results, canvas position—so you can pick up where you left off. Use "sheets" to maintain multiple workspaces within the same app.
Install daggr with pip or uv, it just requires Python 3.10 or higher:.
Here's a simple example that generates an image and removes its background. Check out this Space’s API reference from the bottom of the Space to see which inputs it takes and which outputs it yields. In this example, the Space returns both original image and the edited image, so we return only the edited image.
In a recent development, that's it. Run this script and you get a visual canvas served on port 7860 introduced automatically, as well as a shareable live link, showing both nodes connected, with inputs you can modify and outputs you can inspect at each step.
Daggr supports three types of nodes:.
Industry observers note that gradioNode calls a Gradio Space API endpoint or locally served Gradio app. Passing run_locally=True, Daggr automatically clones the Space, creates an isolated virtual environment, and releases the app. If local execution fails, it gracefully falls back to the remote API.
FnNode — runs a custom Python function:.
InferenceNode — calls a model via Hugging Face Inference Providers:.
Generate a public URL with Gradio's tunneling:.
For permanent hosting, deploy on Hugging Face Spaces using the Gradio SDK—just add daggr to your requirements.txt.
We will now develop an app that takes in an image and generates a 3D asset. This demo can run on daggr 0.4.3. Here are the steps:.
Spaces that are run locally might take models to CUDA (with to.(“cuda”)) or ZeroGPU within the application file. To disable this behavior to run the model on CPU (useful if you have a device with no NVIDIA GPU) duplicate the Space you want to use and clone it.
The resulting graph looks like below.
Let’s write the first step, which is the background remover. We will clone and run this Space locally. This Space runs on CPU, and takes ~13 seconds to run. You can swap with this app if you have an NVIDIA GPU.
For the second step, we need to write a helper function to downscale the image and pass it to FnNode.
We can now pass in the function to initialize the FnNode.
We will now write the InferenceNode with the Flux model.
When deploying apps with InferenceNode to Hugging Face Spaces, use a fine-grained Hugging Face access token with the option "Make calls to Inference Providers" only.
Last node is 3D generation with querying the Trellis.2 Space on Hugging Face.
Chaining them together and launching the app is as simple as follows.
You can find the complete example running in this Space, to run locally you just need to take app.py, install requirements and login to Hugging Face Hub.
Daggr is in beta and intentionally lightweight. APIs may change between versions, and while we persist workflow state locally, data loss is possible during updates. If you have feature requests or find bugs, please open an issue here. We’re looking forward to your feedback! Share your daggr workflows on socials with Gradio for a chance to be featured. Check out all the featured works here.
It has been revealed that what about conditional nodes? I mean the node where the next selected node is determined based on the current node's output.
Recent findings suggest that this is a great point. We'd like to support them, but are thinking about the right API because we'd also like programmatic inspection / API usage, which requires some level of determinism. If you have any suggestions, please feel free to open an matter here: https://github.com/gradio-app/daggr.
It has been revealed that do you have any concerns running Daggr in a jupyter notebook? It should be supported, but if run into issues, please feel free to open an problem here: https://github.com/gradio-app/daggr.
According to recent reports, the visual inspection capability for chained apps is brilliant! Being able to see the flow programmatically while maintaining visibility is so key for debugging and understanding system behavior. Speaking of visualizing system flows, I've been using InfraSketch (https://www.infrasketch.net/) for documenting our application architectures—it generates diagrams from plain English descriptions and lets you refine through conversation. It's been a great complement to tools like Daggr for communicating the overall system design to the broader team.
Recent findings suggest that this is a solid approach to pipeline transparency. Working with Funnelsflex deployments, we often see a friction point between rigid UI funnel builders and the flexibility of raw Python scripts. Daggr seems to bridge that gap by keeping the logic in the code where it belongs, while providing the visual state persistence that’s usually missing in standard Gradio chains.
Industry observers note that the ability to rerun individual nodes without triggering the entire inference stack is a huge win for debugging complex flexible workflows. I’m curious to see how it handles state management when scaling to high-concurrency environments, but for rapid prototyping and 'inspectable' AI apps, it’s a very clean implementation.https://funnelsflex.io/.

AI & Tech
⚖️ Neutral
🌐 9to5google
#11317. Industry News: Google Fi brings back network switching with ‘secondary’ partner, expands W+ beyond Pixel
📅 10 Nov 2026 • ⏱️ 2m • 📖 Standard (394 w)
Industry News: Google Fi brings back network switching with ‘secondary’ partner, expands W+ beyond Pixel
📅 10 Nov 2026 | ⏱️ 2 min read (394 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Google Fi Wireless is rolling out a major update today with the return of network switching thanks to a “secondary” partner.
- Google Fi is now bringing back a second partner as part of its newly introduced “super network.” Most people will be on the “Primary network,” but Google Fi will automatically switch users to the “Secondary network” if it meaningfully improves performance with so-called “smart thresholds” for doing so.
- Sources indicate that google is not naming the second network today, but did share that Ultra Wideband is supported.
Google Fi Wireless is rolling out a major update today with the return of network switching thanks to a “secondary” partner.
Google Fi is now bringing back a second partner as part of its newly introduced “super network.” Most people will be on the “Primary network,” but Google Fi will automatically switch users to the “Secondary network” if it meaningfully improves performance with so-called “smart thresholds” for doing so. At launch, there is no manual switching.
Sources indicate that google is not naming the second network today, but did share that Ultra Wideband is supported. Officially, you are switching between “two of America’s fastest 5G networks.”.
Network switching will first be supported on Pixel 9 and newer devices that have a Google Fi eSIM (and no other SIM active). It makes use of Android’s Multiple Enabled Profiles (MEP) eSIM technology that allows for two carrier profiles on a single chip.
It might be important to note that T-Mobile actually bought out Sprint, and added their towers to their network so its safe to say that Google Fi still works with the same coverage as before the merger.
It has been revealed that the Google Fi app gains a “Your super network” card in the Home tab that indicates whether you’re connected to the Primary or Secondary network. “See activity” lets you view switching history and when it last occurred. Google will also note if you’re in range of W+ networks.
It has been revealed that google today is also expanding its Wi-Fi Auto Connect+ network beyond Pixel phones to select Samsung Galaxy (S23, Fold/Flip 5, and newer) and modern Motorola phones. These premium Wi-Fi networks are available in millions of airports, malls, stores, and restaurants. The connection happens automatically, with the Google Fi Virtual Carrier Network encrypting data.
Recent findings suggest that the final patch today sees the companion app gain “Ask Fi.” This AI-powered chat is meant to quickly provide answers and guided troubleshooting for common concerns. You can request human support with seamless handoff that keeps the chat context.
These Google Fi updates start rolling out today, with network switching seeing gradual availability. This launch is accompanied by several deals:.
FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Editor-in-chief. Interested in the minutiae of Google and Alphabet. Tips/talk: abner@9to5g.com.
🔗 Related Articles
📰 #23625. Industry News: Google Home brings back sounds for Gemini, and I’m both elated and irritated [Video] 📰 #23489. Pixel Tag is a brilliant Band-Aid on a Find Hub network Google can’t easily fix 📰 #16286. Industry News: If Your Google Pixel's Camera Is Suddenly Broken, Here's the Fix
General
⚖️ Neutral
🌐 Fastcompany
#11316. Why an answer isn’t always the answer
📅 16 Nov 2026 • ⏱️ 7m • 📚 Deep Dive (1423 w)
Why an answer isn’t always the answer
📅 16 Nov 2026 | ⏱️ 7 min read (1423 words, 📚 Deep Dive) | Source: Fastcompany
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- When I tried Googling “what is an answer,” I got: “Please provide the specific question, puzzle, or problem you are trying to solve so I can give you the right answer.” It seems answers are defined only in relation to their questions.
- When I tried Googling “what is an answer,” I got: “Please provide the specific question, puzzle, or problem you are trying to solve so I can give you the right answer.”.
- It has been revealed that it seems answers are defined only in relation to their questions.
When I tried Googling “what is an answer,” I got: “Please provide the specific question, puzzle, or problem you are trying to solve so I can give you the right answer.” It seems answers are defined only in relation to their questions. There is no definition of an “answer” on its own. I looked into this and found plenty of philosophy on “what is a question?” and far less on “what is an answer?” I came across mathematics papers on how to get to a solution, which is related, but still focused on the question. Searching for an answer on “answers” is a lot harder than it sounds. WHEN CONTEXT DILUTES THE ANSWER This becomes interesting in a world where answers are now delivered at scale. We’re getting extraordinarily good at producing them, but a gap remains. We don’t really know what an answer is. Basing an answer on the question is no longer enough. AI has dramatically increased our ability to find answers quickly and provide a wider aperture of information. Competition for this service has shifted into which tools can provide the best, fastest, and most accurate answers. We may be able to determine “fastest” and “most accurate,” but how do we determine “best?” Is it correct? Relevant? Complete? That works when a question has a definitive endpoint or when I am looking for a fact. I can ask, “How far is the moon from Earth?” get a number, and move on. Chatbots do this well. Often, the one-sentence answer is perfect, and adding too much context around the distance to the moon dilutes the information I need. Other times, the answer is the first thing I need, not the endpoint. “How far is the moon from Earth?” can lead to “How long does it take to get there?” Now the answer depends on how, who, and why. It gets more complex. It gives me enough context to ask the next question, compare sources, explore something I didn’t understand, form a point of view, or build something from it. If every answer is optimized to close the tab, what happens to the answers that are supposed to start something? A BUILDING PROCESS Building knowledge is a process. Sometimes it’s serendipitous discovery; other times, it’s methodical. A good answer depends on what you are trying to do with it. Correctness is necessary, but not always enough. It needs context, comparison, sources, or follow-up questions. So when is an answer best? Is it a human source? Is it longer? Does it have more citations? There still is no clear answer here. It depends on what I need. I view this as the pipeline: Information → answer → understanding → application. The answer is not the end goal; it’s merely the midpoint. Answers unlock deeper understanding and, ultimately, application. AI has made the first half of this pipeline wildly easier. That’s both a gift and a risk: it can dull the curiosity to dig deeper. Beyond a quick answer is how other people have approached the question before, what they asked next, and what they did with it. I find the back half much more interesting. But it’s more difficult, too. Understanding is subjective. Application is contextual. Both are much harder to measure than whether a system returned the correct answer. I think a lot about this at Scribd, Inc. We are a knowledge tech giant, and we want to help people get to the second half of that pipeline. But that does not mean we skip over the answer. You can’t get to application without it. I don’t know if anyone can “win” this. I don’t even think anyone can quite define it yet. Google was right in a way. It couldn’t tell me what an answer was without knowing what I wanted it for. The “best” answer is the one that meets your objective, whether that’s finding a fact or learning something upcoming. We’ve gotten very good at the answers that provide a fact. We are just scratching the surface on the ones that open something new.The next step is “beyond the answer”—what it allows someone to learn, create, or do. Tony Grimminck is CEO of Scribd, Inc.
When I tried Googling “what is an answer,” I got: “Please provide the specific question, puzzle, or problem you are trying to solve so I can give you the right answer.”.
It has been revealed that it seems answers are defined only in relation to their questions. There is no definition of an “answer” on its own.
I looked into this and found plenty of philosophy on “what is a question?” and far less on “what is an answer?” I came across mathematics papers on how to get to a solution, which is related, but still focused on the question. Searching for an answer on “answers” is a lot harder than it sounds.
This becomes interesting in a world where answers are now delivered at scale. We’re getting extraordinarily good at producing them, but a gap remains. We don’t really know what an answer is. Basing an answer on the question is no longer enough.
AI has dramatically increased our ability to find answers quickly and provide a wider aperture of information. Competition for this service has shifted into which tools can provide the best, fastest, and most accurate answers.
We may be able to determine “fastest” and “most accurate,” but how do we determine “best?” Is it correct? Relevant? Complete? That works when a question has a definitive endpoint or when I am looking for a fact. I can ask, “How far is the moon from Earth?” get a number, and move on. Chatbots do this well. Often, the one-sentence answer is perfect, and adding too much context around the distance to the moon dilutes the information I need.
It has been revealed that other times, the answer is the first thing I need, not the endpoint. “How far is the moon from Earth?” can lead to “How long does it take to get there?” Now the answer depends on how, who, and why. It gets more complex. It gives me enough context to ask the next question, compare sources, explore something I didn’t understand, form a point of view, or build something from it.
If every answer is optimized to close the tab, what happens to the answers that are supposed to start something?
According to recent reports, building knowledge is a process. Sometimes it’s serendipitous discovery; other times, it’s methodical.
Sources indicate that A good answer depends on what you are trying to do with it. Correctness is necessary, but not always enough. It needs context, comparison, sources, or follow-up questions.
Industry observers note that so when is an answer best? Is it a human source? Is it longer? Does it have more citations? There still is no clear answer here. It depends on what I need.
I view this as the pipeline: Information → answer → understanding → application.
It has been revealed that the answer is not the end goal; it’s merely the midpoint. Answers unlock deeper understanding and, ultimately, application. AI has made the first half of this pipeline wildly easier. That’s both a gift and a risk: it can dull the curiosity to dig deeper. Beyond a quick answer is how other people have approached the question before, what they asked next, and what they did with it.
I find the back half much more interesting. But it’s more difficult, too. Understanding is subjective. Application is contextual. Both are much harder to measure than whether a system returned the correct answer.
I think a lot about this at Scribd, Inc. We are a knowledge manufacturer, and we want to help people get to the second half of that pipeline. But that does not mean we skip over the answer. You can’t get to application without it.
Industry observers note that I don’t know if anyone can “win” this. I don’t even think anyone can quite define it yet. Google was right in a way. It couldn’t tell me what an answer was without knowing what I wanted it for.
The “best” answer is the one that meets your objective, whether that’s finding a fact or learning something upcoming. We’ve gotten very good at the answers that provide a fact. We are just scratching the surface on the ones that open something new.The next step is “beyond the answer”—what it allows someone to learn, create, or do.
Tony Grimminck is CEO of Scribd, Inc.
🔗 Related Articles
📰 #17749. What makes food 'organic?' For many consumers, the answer isn't always on the label 📰 #21370. Now 40, Alex Honnold Must Juggle Climbing with Fatherhood and Fame. It Isn’t Always Easy. 📰 #16795. 'Game dev isn't always straightforward': Overwatch's director responds to players upset about season 6's hero being a DPS
AI & Tech
⚖️ Neutral
🌐 Tomshardware
#11315. Malaysia intends newly introduced law using data center power consumption to catch AI GPU smugglers
📅 14 Nov 2026 • ⏱️ 3m • 📚 Deep Dive (682 w)
Malaysia intends newly introduced law using data center power consumption to catch AI GPU smugglers
📅 14 Nov 2026 | ⏱️ 3 min read (682 words, 📚 Deep Dive) | Source: Tomshardware
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Recent findings suggest that malaysia aims to introduce a new law requiring data center operators to disclose their AI accelerator imports and power consumption to prevent diversion of restricted hardware to countries like China and optimize the use of the country’s power infrastructure, reports Malay Mail.
- Malaysia's Minister of Investment, Trade and Industry Datuk Seri Johari Abdul Ghani acknowledged on Thursday that some companies had rented space in Malaysian data centers to import GPUs legally, which they then shipped abroad in smuggling operations.
- The proposed legislation will require data center operators to disclose the number of GPUs they import, their power consumption (presumably nameplate power consumption), the physical locations of their facilities, and the identities of operators and hyperscale customers.
Recent findings suggest that malaysia aims to introduce a new law requiring data center operators to disclose their AI accelerator imports and power consumption to prevent diversion of restricted hardware to countries like China and optimize the use of the country’s power infrastructure, reports Malay Mail. The authorities also proposal to charge data center operators for unused electricity capacity they reserve. While the idea to use power consumption to detect potential GPU smuggling has merit, it also has flaws.
Malaysia's Minister of Investment, Trade and Industry Datuk Seri Johari Abdul Ghani acknowledged on Thursday that some companies had rented space in Malaysian data centers to import GPUs legally, which they then shipped abroad in smuggling operations. To prevent such practices, Malaysia's Digital Ministry is now reviewing existing legislation to determine whether local authorities can take action against entities that re-export processors subject to U.S. export bans. The minister stressed that Malaysia wants AI accelerators imported into the country to be used domestically.
The proposed legislation will require data center operators to disclose the number of GPUs they import, their power consumption (presumably nameplate power consumption), the physical locations of their facilities, and the identities of operators and hyperscale customers. The government intends to track data center operations throughout their lifetime rather than limit oversight to the project approval stage.
Meanwhile, data center operators will have to pay for all the electricity capacity they reserve, irrespective of their actual power consumption. For example, if a data center secures 100 MW of power capacity but only uses 50 MW, its operator will still have to pay for the remaining 50 MW. The measure is meant to discourage companies from reserving electricity capacity they may not need for another one to three years. As an added bonus, the measure will further discourage rerouting AI hardware to China while pretending it is used in Malaysia.
According to recent reports, while data on power consumption could help Malaysian authorities spot suspicious discrepancies between AI GPU imports and actual data center operations, it is virtually impossible to accurately determine the number of AI accelerators deployed at a facility based on power consumption alone. For example, Nvidia's H100 and H200 SXM GPUs are rated at 700W, whereas its B200 SXM accelerators are rated at 1,000W, yet neither necessarily consumes its rated power under actual workloads.
Furthermore, without knowledge of server configurations, the power consumption of CPUs, memory, storage, and networking equipment, or the power usage effectiveness (PUE) of a particular facility, any estimates of the number of operational GPUs would be imprecise, to put it mildly. Also, there may be a considerable delay between GPU imports and their actual deployment. As a result, reliable verification would require physical inventory audits or other mechanisms to track individual processors.
Johari mentioned that Malaysian authorities were prepared to cooperate with their U.S. counterparts and provide information about facilities that house particular GPUs upon request. However, the minister did not specify whether the new legislation would require data center operators to disclose GPU models and serial numbers, or whether authorities would conduct on-site inspections.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
In a recent development, malaysia has emerged as a major destination for data center investments in Southeast Asia as cloud service providers and AI infrastructure companies expand their presence in the region. To date, Malaysian authorities have approved 117 data center projects, 55 of which are already operational, according to Johari. The proliferation of local AI data centers makes Malaysia a suitable venue for rerouting restricted hardware to countries like China, as it is easier to hide a needle in a pile of needles than in a haystack.
Follow Tom's Hardware on Google News, or add us as a preferred source, to get our latest news, analysis, & reviews in your feeds.
Sources indicate that anton Shilov is a contributing writer at Tom’s Hardware. Over the past couple of decades, he has covered everything from CPUs and GPUs to supercomputers and from modern process technologies and latest fab tools to high-tech industry trends.
General
⚖️ Neutral
🌐 Sitepoint
#11314. How to Use IP Geolocation to Stop Bots and Fraud (Without Hurting UX)
📅 11 Nov 2026 • ⏱️ 5m • 📚 Deep Dive (938 w)
How to Use IP Geolocation to Stop Bots and Fraud (Without Hurting UX)
📅 11 Nov 2026 | ⏱️ 5 min read (938 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~5 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- Several methods can help you deal with online threats and strengthen security.
- Those of you who browse online daily know that credential stuffing, fake signups & payment fraud keep growing.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Weekly. Free. One click to leave.
7 Day Free Trial. Cancel Anytime.
Several methods can help you deal with online threats and strengthen security. All are effective, but each has a trade-off. For example, the harder you make it for bots to affect your website’s performance, the more likely you are to frustrate real customers.
Those of you who browse online daily know that credential stuffing, fake signups & payment fraud keep growing. To prevent fraud, businesses install CAPTCHAs & hard blocks that treat bots and legitimate customers the same, diverting them to your competitors.
IP geolocation maps an IP address to a physical location & network details, letting you spot suspicious traffic before it reaches sensitive actions. Used well, it’s an invisible, low-friction risk signal. In this guide, you will learn how to flag high-risk activity and apply soft geo-fencing with step-up authentication.
Today, an IP lookup returns far more than a country & city. It can also reveal several other parameters, like.
Each of these fields acts as a clue telling who is really behind a request.
Recent findings suggest that this data powers anomaly detection. You can start by building a baseline for normal behavior for each user with aspects like.
Sources indicate that then, you can watch for deviations from that pattern. An attacker won’t look like the account’s real owner, so you'll catch them.
Geolocation makes several common attack patterns easy to spot:.
The first is traffic bursts from data center ASNs. These are bots, as real customers don’t browse from cloud servers.
Many accounts created from one IP or subnet. This is a clear sign of fake signups.
Impossible travel, such as logins from two distant locations within minutes.
Industry observers note that timezone vs. IP mismatch. A device’s clock disagrees with its apparent location.
Note: Geolocation is just a signal, not a verdict. VPNs, travel, & mobile carriers can all create false alarms, so it works best when combined with other signals. That’s exactly why a proportional, soft response beats a hard block.
In short, IP geolocation turns a bare IP address into context, helping you separate real customers from automated or fraudulent traffic.
Not every IP geolocation anomaly deserves the same response. The simplest way to stay consistent is to define a clear risk-signal framework.
That can be a short list of checks. Each check can have a weight that reflects how strongly it suggests fraud.
Industry observers note that with risk scoring, you can turn these checks into a decision. You just have to assign each signal a numeric weight.
For example, medium can be 10 & 30 can be high.
Now, you need to add up every signal that comes up & map the total to thresholds like.
A single medium signal passes quietly, but several can trigger action.
A customer who has a US billing address logs in from Germany. This is a strong signal, but not proof of fraud. The user could be traveling, an expat, or a privacy-conscious user using a VPN.
It has been revealed that if you treat this as an automatic block, it would punish legitimate customers. Instead, let it raise the score & you take action only if it stacks with other signals, like a hosting IP or a fresh device.
Now that you know how to quantify the risk, here is how you can protect yourself without damaging UX.
In a recent development, before soft, let us learn about hard blocking. This is where you completely deny or permanently ban traffic from specific geographic regions.
Now, hard blocking by country may look effective, but it can backfire promptly. Here is how.
In the worst case, determined bot operators simply rotate to IPs in allowed regions, so the only people you stop are your real customers.
This is where the balance between security and user experience becomes critical. As the digital strategist and Founder at LawRank, Mariano Rodriguez emphasizes, "Your website's security should be a silent guardian, not a roadblock. If your fraud prevention creates friction, you aren't just stopping bots—you're turning away real clients. True digital trust is built when backend protections are seamless and invisible to the legitimate user.".
Now, with soft geo-fencing, you can respond to risk proportionally instead of making a simple allow-or-deny call. Instead of totally banning the owners, you adjust the level of friction to match the risk score from the previous section:.
It has been revealed that **Note: **For soft geo-fencing, passkeys are safest because they are phishing-resistant. Only a legitimate user can take the biometric tap and pass.
Industry observers note that before we start, let’s understand Express.js middleware. An Express.js middleware for Geolocation Risk Scores is a custom or 3rd party function that intercepts the incoming HTTP requests, extracts the client's IP address, fetches a security risk profile based on their geographic location & attaches that data to the request object (req) before it reaches your route handlers.
Here is how you can use it for fraud prevention and bot mitigation:.
Note: You can make it stronger by adding velocity checks (too many attempts from one IP or account) & device fingerprints.
It has been revealed that from a broader angle, IP geolocation isn't the final verdict. It is just a signal. But with this signal, you can score each request, respond in proportion to the risk & save hard blocks for clear abuse. This increases the friction for bots and keeps the flow easy for legitimate users.
7 Day Free Trial. Cancel Anytime.
🔗 Related Articles
📰 #22999. Latest Update: Grok Bots Attempt to Access Corporate Data Without User Approval 📰 #22072. Tech Report: How to use fitness trackers to enhance performance and wellbeing—without losing touch with yourself 📰 #18415. Latest Update: SuperDial revamps its healthcare voice agent platform to stop AI bots wasting time calling each other
General
⚖️ Neutral
🌐 Fastcompany
#11313. Elderly people are buying Teslas for the ‘full self-driving.’ This is a problem
📅 16 Nov 2026 • ⏱️ 21m • 📚 Deep Dive (4260 w)
Elderly people are buying Teslas for the ‘full self-driving.’ This is a problem
📅 16 Nov 2026 | ⏱️ 21 min read (4260 words, 📚 Deep Dive) | Source: Fastcompany
⏱️ ~21 mins left to finish
📖 0% read
💡 Key Takeaways
- After retiring a few years ago, my parents moved into a wooded retirement community in North Carolina.
- In a recent development, after retiring a few years ago, my parents moved into a wooded retirement community in North Carolina.
- Recent findings suggest that his solution: Get a Tesla.
After retiring a few years ago, my parents moved into a wooded retirement community in North Carolina. One of their neighbors is a former physician, now in his 90s, who sensed that his reflexes had deteriorated. He no longer trusted himself behind the wheel, but he valued the independence that a car can provide. His solution: Get a Tesla. He now relies on Full Self-Driving (Supervised), Tesla’s driver assistance system, to get around. That decision is a dubious one at best. Tesla’s driver assistance system is just that: technology that can make the act of driving less onerous, but cannot replace it. A person operating Full Self-Driving (Supervised)—let’s call it FSD—must be able to intervene immediately if the system makes a mistake, which does happen. If not, their use of FSD endangers themselves along with everyone else on the road. My parents’ neighbor is far from alone. A quick scan of Facebook or TikTok reveals numerous adults with declining health who depend on FSD to keep driving. And Tesla itself has amplified these narratives—despite officially claiming that drivers, not the tech giant, are responsible for the vehicle while FSD is in operation. A post on X earlier this year featured a 71-year-old man who bought a Cybertruck “because my eyes are getting bad.” Tesla’s North America X account shared the clip with a one-word comment: “Freedom.” Questions of whether and how older Americans can safely use driver assistance systems like FSD are devilishly tricky. But as the ranks of retired baby boomers expand, finding answers is increasingly urgent. “The extent to which people are willing to adopt these vehicles, and ways that they’re using them are completely wide open,” mentioned Johnathon Ehsani, an associate professor at the Johns Hopkins Bloomberg School of Public Health. “We know nothing.” A fraught decision Although people age differently, virtually everyone who grows old will eventually struggle to drive. Even if they avoid cognitive decline, Ehsani said, “older adults have reduced physical abilities like their reaction time, neck rotation, and ability to check blind spots.” Many seniors are excellent drivers: Overall, people in their 60s are less likely to be in a deadly collision than the general public, and those in their 70s are about on par with teenagers. But drivers in their 80s are significantly more prone to being involved in a fatal crash. Part of that risk is due to the fragility of their bodies, but research suggests that drivers over 85 are also more likely to be in collisions. Ehsani said that seniors typically recognize when their driving ability declines, and they are eager to stay safe. Some can do so by avoiding using a car at night or during inclement weather. “A lot of driving as people get older is discretionary,” he said. “They don’t have to get up and be somewhere at 9 a.m. or come home at 5 p.m.” But relinquishing a car is a move many reject, even if their health is severely compromised. Case in point: Surveys indicate that three in 10 Americans with dementia continue to drive. Such resistance is understandable, given the general difficulty of doing errands or visiting friends without using an automobile. “In the United States, we take great pride in being able to be independent in our actions,” said Jennifer Crawley, deputy secretary at the Maryland Department of Aging. “The inability to continue to drive can impact people’s view of themselves and the ways they connect with their broader community.” Ehsani agreed, noting that losing the ability to drive can be mentally devastating. “Families often tell me stories of the day they took mom’s or dad’s keys, and how that was the beginning of their decline,” he said. To his point, researchers at Columbia University found that “older adults experienced faster declines in cognitive function and physical health” after they ceased driving. Given the stakes, the decision to stop using a car is often fraught. “There’s a grieving process that can occur when people give up the keys,” Crawley said. According to the AARP, its most-clicked site about driver safety is a free webinar, entitled “We Need to Talk,” offering suggestions to family members unsure how to broach the subject. The choice facing older Americans can be agonizing: Do they continue to drive, putting themselves and others road people at risk, or do they accept the loneliness and dependence that can follow the loss of a car? Presented with that dilemma, a third option involving a vehicle that safely drives itself would be cause for celebration. But no such option exists. The only autonomous trips at the moment available to consumers are from robotaxi companies like Waymo and Zoox. No senior—nor anyone else—can acquire their own self-driving car. But they can buy a Tesla. A pattern of boosterism Full Self-Driving (Supervised) is Tesla’s version of what the Society of Automotive Engineers (SAE) calls a Level 2 Advanced Driver Assistance System, akin to Ford’s BlueCruise or General Motors’ Super Cruise. Such systems can handle many driving tasks, including changing lanes, accelerating, braking, and turning. Convenient though they can be, Level 2 systems rely on active human oversight. In its public guidance, SAE warns that “you are driving whenever these driver support features are engaged—even if your feet are off the pedals and you are not steering.” Tesla owners can purchase a FSD subscription for $99 per month. Consistent with SAE’s guidance, Tesla’s manual gives owners bold-faced instructions: “You must remain attentive and be ready to take over at all times.” But in contrast to the manual’s clear messaging, Tesla’s marketing often exaggerates FSD’s capabilities. In May, the company posted a video on social media featuring a FSD-enabled car whose driver is making an espresso—an activity that would seemingly be impossible while focusing on the road. When asked if most Tesla owners read the manual, Birsen Donmez, an engineering professor at the University of Toronto who specializes in human factors, gave a short chuckle. “No, absolutely not,” she replied. “They don’t know the limitations of these systems.” (Tesla did not respond to a request for comment.) In fact, the very name Full Self-Driving could confuse consumers. In February, California regulators forced Tesla to append the parenthetical (Supervised) to the feature’s name, but Donmez does not think that move is sufficient. “It still indicates ‘full self-driving’,” she shrugged. “That could be misleading.” Tesla has spread misinformation in other ways, too. In September, CEO Elon Musk shared a viral in-car video about Larry, a 98-year-old who waxes euphoric about FSD. After his Tesla clears an intersection, Larry exclaims “Look, I didn’t have to look, you know! I don’t want to look, it’s just doing it.” But according to Tesla’s own manual, Larry does indeed have to look. As the automotive outlet Electrek noted at the time, “this is exactly what the terms forbid.” Musk’s resharing of Larry’s video is part of a pattern of boosterism. In July, Tesla posted a video on X about Lois, a 93-year-old woman who “noticed how tired she was on her daily drives,” before acquiring a Tesla that allows her to travel by car comfortably. Musk reshared that post, too, adding: “Tesla self-driving enables safer mobility for senior citizens.” Ehsani, the Johns Hopkins public health professor, was skeptical. If anything, the video led him to question whether Lois can safely use FSD. “Her feeling tired is a bit of a red flag,” he said. “She may not be awake while this [Tesla] is in operation.” And Tesla’s supercharged fan base has amplified the company’s messaging for seniors. On the TeslaModelY subreddit, plaudits poured in for a 90-year-old man who obtained a Model Y because “his kids thought it would be a good fit for him.” One poster called FSD “a digital chauffeur,” a sobriquet that implies self-driving capabilities that the system cannot deliver. A dearth of data The relative safety of Level 2 systems like FSD is highly contested. Tesla maintains that cars operating FSD are less crash prone, but Donmez noted that “it’s based on their analysis only” and lacks independent validation. She remains “very suspicious” of Tesla’s FSD claims, because most people struggle to remain vigilant without doing anything for long periods of time. Joseph Young, a spokesperson at the Insurance Institute for Highway Safety, said that specific features like automatic emergency braking can clearly reduce collisions, but it remains an open question whether combining many of them within a product like FSD provides additional upside. “Level 2 systems should be considered convenience features rather than safety systems,” he said. For seniors specifically, little is known about the safety of FSD or other Level 2 systems. Several high-profile crashes have involved older Tesla drivers, including a recent one in California, in which a 91-year-old driver killed one and injured five people in a Trader Joe’s parking lot. (Whether the driver was using FSD is unclear.) Credulous journalists have exacerbated public misunderstanding. A feature story in The Detroit News earlier this year declared that seniors are buying Teslas to “self-drive,” and claimed “FSD helps elderly drivers maintain a cocoon around their car as their confidence in reflexes and eyesight naturally deteriorate”—even though Tesla’s own manual makes clear that the company’s technology is reliant upon the driver, not the other way around. (The author of the Detroit News story did not respond to a request for comment.) Acknowledging a dearth of data, Ehsani said it is theoretically possible that a Level 2 system like FSD could reduce overall crashes among seniors, if the system—even with compromised oversight—is safer than the counterfactual of their driving themselves. On the other hand, it is also possible that seniors’ use of FSD increases total crashes. If this is the case, it could be because seniors drive more miles, each of which carries a degree of danger, or because they are unable to intervene in an emergency. Worryingly, research suggests that older drivers need more time to react when a Level 2 system’s mishap requires them to respond. Donmez, the University of Toronto engineering professor, proposed a simple rubric for seniors tempted by Tesla’s pitch. “If you can’t drive yourself,” she said, “you shouldn’t be driving with FSD.” A safer path forward A common-sense solution to help seniors—and everyone else—make better driving decisions would be to force Tesla and Musk to stop exaggerating FSD’s capabilities. European officials recently required Tesla to change the name of the system to Full Assisted Driving, after China had already made a similar move. The United States is “the last [massive car market] that doesn’t have a rule saying you can’t say that a system that isn’t self-driving is self-driving,” Ed Niedermeyer, the author of two books about Tesla, observed recently on the Autonocast podcast. “Why is it taking so long to say that up is up and down is down?” Ascendant leaders in Washington may be thinking along similar lines. Following the midterm election “bluenami,” Senator Ed Markey, Democrat of Massachusetts, vowed “to hold Musk and Tesla accountable for the risk their systems pose to our families and communities.” But reining in Tesla’s marketing would still leave millions of seniors struggling to maintain their quality of life as they become incapable of driving safely. If and when genuine autonomous vehicles go on sale, they could be a godsend. Crawley, the Maryland official, is optimistic about their long-term potential—she called autonomy a “new frontier” in elder care—provided that being affluent and tech savvy is not a prerequisite for using them. She also noted that fully autonomous vehicles may need modifications to serve seniors, such as the capability of loading a walker or wheelchair. (Disability advocates have called on robotaxi companies to speed the introduction of wheelchair-accessible robotaxis, which are not widely deployed.) Given the uncertainties about autonomy’s future, a more foolproof way to enhance senior mobility would be to enable more people to live in places where a car is unnecessary. As an example, the Atlanta exurb of Peachtree City features a separated golf cart network that enables residents to get practically anywhere without using an automobile. Peachtree City benefits from being master planned, but other cities like Long Beach, California, have envisioned roadway retrofits that enable people to travel by Low-Speed Vehicles that are slower and smaller than full-sized cars, and therefore pose less danger. These are worthy endeavors, even if they will take years to bear fruit. In the meantime, seniors—and all Americans—deserve clear information about what driver assistance systems can and cannot do. There is no excuse for letting a company exploit a vulnerable population and endanger the public by dangling false hope.
In a recent development, after retiring a few years ago, my parents moved into a wooded retirement community in North Carolina. One of their neighbors is a former physician, now in his 90s, who sensed that his reflexes had deteriorated. He no longer trusted himself behind the wheel, but he valued the independence that a car can provide.
Recent findings suggest that his solution: Get a Tesla. He now relies on Full Self-Driving (Supervised), Tesla’s driver assistance system, to get around.
It has been revealed that that decision is a dubious one at best. Tesla’s driver assistance system is just that: technology that can make the act of driving less onerous, but cannot replace it. A person operating Full Self-Driving (Supervised)—let’s call it FSD—must be able to intervene immediately if the system makes a mistake, which does happen. If not, their use of FSD endangers themselves along with everyone else on the road.
My parents’ neighbor is far from alone. A quick scan of Facebook or TikTok reveals numerous adults with declining health who depend on FSD to keep driving. And Tesla itself has amplified these narratives—despite officially claiming that drivers, not the organization, are responsible for the vehicle while FSD is in operation. A post on X earlier this year featured a 71-year-old man who bought a Cybertruck “because my eyes are getting bad.” Tesla’s North America X account shared the clip with a one-word comment: “Freedom.”.
Questions of whether and how older Americans can safely use driver assistance systems like FSD are devilishly tricky. But as the ranks of retired baby boomers expand, finding answers is increasingly urgent.
“The extent to which people are willing to adopt these vehicles, and ways that they’re using them are completely wide open,” said Johnathon Ehsani, an associate professor at the Johns Hopkins Bloomberg School of Public Health. “We know nothing.”.
Although people age differently, virtually everyone who grows old will eventually struggle to drive. Even if they avoid cognitive decline, Ehsani remarked, “older adults have reduced physical abilities like their reaction time, neck rotation, and ability to check blind spots.”.
Many seniors are excellent drivers: Overall, people in their 60s are less likely to be in a deadly collision than the general public, and those in their 70s are about on par with teenagers. But drivers in their 80s are significantly more prone to being involved in a fatal crash. Part of that risk is due to the fragility of their bodies, but research suggests that drivers over 85 are also more likely to be in collisions.
Industry observers note that ehsani mentioned that seniors typically recognize when their driving ability declines, and they are eager to stay safe. Some can do so by avoiding using a car at night or during inclement weather. “A lot of driving as people get older is discretionary,” he said. “They don’t have to get up and be somewhere at 9 a.m. or come home at 5 p.m.”.
But relinquishing a car is a move many reject, even if their health is severely compromised. Case in point: Surveys indicate that three in 10 Americans with dementia continue to drive.
Sources indicate that such resistance is understandable, given the general difficulty of doing errands or visiting friends without using an automobile. “In the United States, we take great pride in being able to be independent in our actions,” said Jennifer Crawley, deputy secretary at the Maryland Department of Aging. “The inability to continue to drive can impact people’s view of themselves and the ways they connect with their broader community.”.
Recent findings suggest that ehsani agreed, noting that losing the ability to drive can be mentally devastating. “Families often tell me stories of the day they took mom’s or dad’s keys, and how that was the beginning of their decline,” he said. To his point, researchers at Columbia University found that “older adults experienced faster declines in cognitive function and physical health” after they ceased driving.
According to recent reports, given the stakes, the decision to stop using a car is often fraught. “There’s a grieving process that can occur when people give up the keys,” Crawley remarked. According to the AARP, its most-clicked site about driver safety is a free webinar, entitled “We Need to Talk,” offering suggestions to family members unsure how to broach the subject.
The choice facing older Americans can be agonizing: Do they continue to drive, putting themselves and others road people at risk, or do they accept the loneliness and dependence that can follow the loss of a car?
Presented with that dilemma, a third option involving a vehicle that safely drives itself would be cause for celebration. But no such option exists. The only autonomous trips currently available to consumers are from robotaxi companies like Waymo and Zoox. No senior—nor anyone else—can acquire their own self-driving car.
But they can buy a Tesla.
Full Self-Driving (Supervised) is Tesla’s version of what the Society of Automotive Engineers (SAE) calls a Level 2 Advanced Driver Assistance System, akin to Ford’s BlueCruise or General Motors’ Super Cruise. Such systems can handle many driving tasks, including changing lanes, accelerating, braking, and turning.
Sources indicate that convenient though they can be, Level 2 systems rely on active human oversight. In its public guidance, SAE warns that “you are driving whenever these driver support features are engaged—even if your feet are off the pedals and you are not steering.”.
Tesla owners can purchase a FSD subscription for $99 per month. Consistent with SAE’s guidance, Tesla’s manual gives owners bold-faced instructions: “You must remain attentive and be ready to take over at all times.”.
But in contrast to the manual’s clear messaging, Tesla’s marketing often exaggerates FSD’s capabilities. In May, the manufacturer posted a video on social media featuring a FSD-enabled car whose driver is making an espresso—an activity that would seemingly be impossible while focusing on the road.
Recent findings suggest that when asked if most Tesla owners read the manual, Birsen Donmez, an engineering professor at the University of Toronto who specializes in human factors, gave a short chuckle. “No, absolutely not,” she replied. “They don’t know the limitations of these systems.” (Tesla did not respond to a request for comment.).
Industry observers note that in fact, the very name Full Self-Driving could confuse consumers. In February, California regulators forced Tesla to append the parenthetical (Supervised) to the feature’s name, but Donmez does not think that move is sufficient. “It still notes ‘full self-driving’,” she shrugged. “That could be misleading.”.
In a recent development, tesla has spread misinformation in other ways, too. In September, CEO Elon Musk shared a viral in-car video about Larry, a 98-year-old who waxes euphoric about FSD. After his Tesla clears an intersection, Larry exclaims “Look, I didn’t have to look, you know! I don’t want to look, it’s just doing it.” But according to Tesla’s own manual, Larry does indeed have to look. As the automotive outlet Electrek noted at the time, “this is exactly what the terms forbid.”.
It has been revealed that musk’s resharing of Larry’s video is part of a pattern of boosterism. In July, Tesla posted a video on X about Lois, a 93-year-old woman who “noticed how tired she was on her daily drives,” before acquiring a Tesla that allows her to travel by car comfortably. Musk reshared that post, too, adding: “Tesla self-driving enables safer mobility for senior citizens.” Ehsani, the Johns Hopkins public health professor, was skeptical. If anything, the video led him to question whether Lois can safely use FSD. “Her feeling tired is a bit of a red flag,” he said. “She may not be awake while this [Tesla] is in operation.”.
And Tesla’s supercharged fan base has amplified the firm’s messaging for seniors. On the TeslaModelY subreddit, plaudits poured in for a 90-year-old man who obtained a Model Y because “his kids thought it would be a good fit for him.” One poster called FSD “a digital chauffeur,” a sobriquet that implies self-driving capabilities that the system cannot deliver.
The relative safety of Level 2 systems like FSD is highly contested. Tesla maintains that cars operating FSD are less crash prone, but Donmez noted that “it’s based on their analysis only” and lacks independent validation. She remains “very suspicious” of Tesla’s FSD claims, because most people struggle to remain vigilant without doing anything for long periods of time.
Joseph Young, a spokesperson at the Insurance Institute for Highway Safety, remarked that specific features like automatic emergency braking can clearly reduce collisions, but it remains an open question whether combining many of them within a product like FSD provides additional upside. “Level 2 systems should be considered convenience features rather than safety systems,” he said.
In a recent development, for seniors specifically, little is known about the safety of FSD or other Level 2 systems. Several high-profile crashes have involved older Tesla drivers, including a recent one in California, in which a 91-year-old driver killed one and injured five people in a Trader Joe’s parking lot. (Whether the driver was using FSD is unclear.).
It has been revealed that credulous journalists have exacerbated public misunderstanding. A feature story in The Detroit News earlier this year declared that seniors are buying Teslas to “self-drive,” and claimed “FSD helps elderly drivers maintain a cocoon around their car as their confidence in reflexes and eyesight naturally deteriorate”—even though Tesla’s own manual makes clear that the tech giant’s technology is reliant upon the driver, not the other way around. (The author of the Detroit News story did not respond to a request for comment.).
Sources indicate that acknowledging a dearth of data, Ehsani remarked it is theoretically possible that a Level 2 system like FSD could reduce overall crashes among seniors, if the system—even with compromised oversight—is safer than the counterfactual of their driving themselves. On the other hand, it is also possible that seniors’ use of FSD increases total crashes. If this is the case, it could be because seniors drive more miles, each of which carries a degree of danger, or because they are unable to intervene in an emergency. Worryingly, research suggests that older drivers need more time to react when a Level 2 system’s mishap requires them to respond.
Recent findings suggest that donmez, the University of Toronto engineering professor, proposed a simple rubric for seniors tempted by Tesla’s pitch. “If you can’t drive yourself,” she remarked, “you shouldn’t be driving with FSD.”.
A common-sense solution to help seniors—and everyone else—make better driving decisions would be to force Tesla and Musk to stop exaggerating FSD’s capabilities.
It has been revealed that european officials recently required Tesla to change the name of the system to Full Assisted Driving, after China had already made a similar move. The United States is “the last [significant car market] that doesn’t have a rule saying you can’t say that a system that isn’t self-driving is self-driving,” Ed Niedermeyer, the author of two books about Tesla, observed recently on the Autonocast podcast. “Why is it taking so long to say that up is up and down is down?”.
Sources indicate that ascendant leaders in Washington may be thinking along similar lines. Following the midterm election “bluenami,” Senator Ed Markey, Democrat of Massachusetts, vowed “to hold Musk and Tesla accountable for the risk their systems pose to our families and communities.”.
But reining in Tesla’s marketing would still leave millions of seniors struggling to maintain their quality of life as they become incapable of driving safely.
Industry observers note that if and when genuine autonomous vehicles go on sale, they could be a godsend. Crawley, the Maryland official, is optimistic about their long-term potential—she called autonomy a “latest frontier” in elder care—provided that being affluent and tech savvy is not a prerequisite for using them. She also noted that fully autonomous vehicles may need modifications to serve seniors, such as the capability of loading a walker or wheelchair. (Disability advocates have called on robotaxi companies to speed the introduction of wheelchair-accessible robotaxis, which are not widely deployed.).
In a recent development, given the uncertainties about autonomy’s future, a more foolproof way to enhance senior mobility would be to enable more people to live in places where a car is unnecessary. As an example, the Atlanta exurb of Peachtree City features a separated golf cart network that enables residents to get practically anywhere without using an automobile. Peachtree City benefits from being master planned, but other cities like Long Beach, California, have envisioned roadway retrofits that enable people to travel by Low-Speed Vehicles that are slower and smaller than full-sized cars, and therefore pose less danger.
Sources indicate that these are worthy endeavors, even if they will take years to bear fruit. In the meantime, seniors—and all Americans—deserve clear information about what driver assistance systems can and cannot do. There is no excuse for letting a firm exploit a vulnerable population and endanger the public by dangling false hope.
🔗 Related Articles
📰 #17614. BYD’s full-size luxury SUV has a wheel problem, and it’s fixing it for free 📰 #17439. Tesla Opens Self-Driving Cybercab Orders To 'Select Customers' At $29,990 📰 #16594. WoW: Forever's economy has a problem, as a now-hotfixed grind rakes in thousands of gold for the people who got in early
General
⚖️ Neutral
🌐 Sciencedaily
#11312. Tech Report: Scientists overcome a hidden obstacle to more powerful quantum computers
📅 26 Oct 2026 • ⏱️ 5m • 📚 Deep Dive (970 w)
Tech Report: Scientists overcome a hidden obstacle to more powerful quantum computers
📅 26 Oct 2026 | ⏱️ 5 min read (970 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~5 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that silicon spin qubits could play a major role in the future of quantum computing because they can be produced using the same semiconductor manufacturing methods that make today's computer chips.
- Researchers at the RIKEN Center for Emergent Matter Science and their collaborators have now made important progress toward solving this problem.
- Leon Camenzind, a RIKEN research scientist and co-first author who supervised the experiments, explains the significance of the results: "This demonstrates that high-fidelity control can be maintained even when several qubits are operated at the same time and represents an vital step toward scaling up silicon-based quantum processors.".
Sources indicate that silicon spin qubits could play a major role in the future of quantum computing because they can be produced using the same semiconductor manufacturing methods that make today's computer chips. However, researchers have faced a significant challenge. When multiple silicon qubits are controlled at the same time, their operations tend to become less accurate. Building practical, large quantum computers will require scientists to control many qubits simultaneously while keeping errors to a minimum.
Researchers at the RIKEN Center for Emergent Matter Science and their collaborators have now made important progress toward solving this problem. In a study published in Nature Physics, the team demonstrated highly accurate control of several silicon spin qubits operating simultaneously. Their experiments used an array of five qubits connected to a shared microwave control line. By identifying a major cause of errors during simultaneous operation, the scientists developed a technique to reduce those errors and maintain precision.
Leon Camenzind, a RIKEN research scientist and co-first author who supervised the experiments, explains the significance of the results: "This demonstrates that high-fidelity control can be maintained even when several qubits are operated at the same time and represents an vital step toward scaling up silicon-based quantum processors.".
Scientists Identify a Hidden Source of Quantum Computing Errors.
Unlike conventional computers, which store information as bits representing either 0 or 1, quantum computers use quantum bits, or qubits, that can exist in combinations of both states. Silicon spin qubits store this information using the spin of individual electrons confined within silicon. Performing reliable quantum calculations requires extremely precise control over these electron spins.
Microwave signals provide that control, but operating multiple qubits simultaneously can create unwanted effects that interfere with their accuracy. The researchers traced much of this problem to a phenomenon called the AC Stark shift.
This effect occurs when microwave control signals alter a qubit's effective energy levels, producing changes in the phase of its quantum state. Those phase shifts can disrupt the intended operation of individual qubits, particularly when several are being controlled at once.
To counteract the problem, the team created a calibration method that compensates for these unwanted shifts. Rather than separately calibrating every possible combination of qubits, the technique relies on calibrations performed between pairs of qubits. This makes the approach more practical for systems containing larger numbers of quantum bits.
"Rather than requiring an entirely separate calibration procedure for every possible combination of qubits, our method uses calibrations between pairs of qubits to compensate for the unwanted phase shifts," explains Yi-Hsien Wu, the first author who carried out the experiments as part of his PhD research.
Quantum Qubits Achieve Accuracy Above 99.99%.
According to recent reports, the researchers combined their calibration technique with an improved device design and carefully adjusted microwave control pulses. Their results showed that exceptionally high accuracy could be maintained even when multiple qubits were operating simultaneously.
Industry observers note that when the five qubits were tested individually, each achieved single-qubit gate fidelity well above 99.99%, with the highest approaching 99.999%. Fidelity describes how closely a quantum operation matches its intended result.
In a recent development, the team then tested how well the system performed when several qubits were active together. With as many as three qubits operating simultaneously, fidelity remained above 99.99%. Even when all five qubits were controlled at once, accuracy stayed at approximately 99.9%, approaching the levels needed for practical fault-tolerant quantum computing.
In a recent development, although the calibration method greatly reduced errors, it did not eliminate them entirely. The researchers found that the remaining loss of accuracy was linked to drive-induced decoherence, an effect caused by the greater microwave power required to operate multiple qubits simultaneously.
Unlike the unwanted phase shifts corrected by the latest technique, decoherence involves the loss of the delicate quantum coherence needed for reliable operations.
According to Camenzind, "This is a limitation, but further improvements to device design could help mitigate this source of error.".
A Upcoming Path Toward Larger Quantum Processors.
In a recent development, the findings show that controlling several silicon spin qubits at the same time does not necessarily require a major sacrifice in accuracy. By correcting a key source of errors, the researchers have demonstrated a promising approach for operating more qubits through shared microwave control lines.
This is especially important for the development of large quantum processors. Giving every qubit its own independent control system would make increasingly complex devices difficult to manage. Shared control lines could offer a more practical way to expand these systems while maintaining the precision needed for quantum calculations.
"By addressing a key source of control errors through pairwise calibration," notes Camenzind. "Our study supports the use of shared control lines as a practical approach to scaling up quantum processors. Combined with silicon's compatibility with established semiconductor manufacturing, we believe that this advance could help pave the way toward larger quantum processors capable of performing increasingly complex computations.".
It has been revealed that the broader objective is to develop quantum computers that can reliably perform calculations despite the errors and disturbances that affect quantum systems. Such machines, known as fault-tolerant quantum computers, will require precise, dependable control over large numbers of qubits.
"Our long-term goal is to build a fault-tolerant quantum computer based on silicon spin qubits, and reliable parallel control is an essential step toward that goal," adds Seigo Tarucha, project manager of a silicon quantum computing project under JST's Moonshot Goal 6.
Materials provided by RIKEN. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Fresh Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
EV & Auto
⚖️ Neutral
🌐 9to5google
#11311. Tech Report: Wyze’s new door lock has speedy fingerprint recognition and 12-month battery life
📅 10 Nov 2026 • ⏱️ 1m • 📖 Standard (269 w)
Tech Report: Wyze’s new door lock has speedy fingerprint recognition and 12-month battery life
📅 10 Nov 2026 | ⏱️ 1 min read (269 words, 📖 Standard) | Source: 9to5google
⏱️ ~1 mins left to finish
📖 0% read
💡 Key Takeaways
- Wyze is today launching its latest “Lever Lock,” a smart lock for your front door that has a year of battery life and fast fingerprint recognition, all for an affordable price tag.
- Available starting today, the Wyze Level Lock is not your typical deadbolt smart lock.
- Industry observers note that the Lever Lock has a PIN entry and a fingerprint sensor, the latter of which Wyze states recognizes your fingerprint in about half a second.
Wyze is today launching its latest “Lever Lock,” a smart lock for your front door that has a year of battery life and fast fingerprint recognition, all for an affordable price tag.
Available starting today, the Wyze Level Lock is not your typical deadbolt smart lock. Rather, this is a smart lock designed for your standard single-bore latch, meaning it’s available for doors that other smart locks aren’t compatible with. You can still have a deadbolt, but you’ll need enough space for both (per Wyze’s guidelines below).
Industry observers note that the Lever Lock has a PIN entry and a fingerprint sensor, the latter of which Wyze states recognizes your fingerprint in about half a second. It uses local storage for biometric data and works to improve that data with each successful unlock.
According to recent reports, the PIN has a clever feature (though it’s presented in somewhat poor taste) that lets you input random digits before or after your actual code to prevent onlookers from being able to see your code. There’s also a physical key backup as well as a USB-C input on the outside in the case that the battery dies – Wyze states it lasts about 12 months on a charge using eight AA batteries.
The Wyze Lever Lock is available today for $99.98 and shipping immediately.
Follow Ben: Twitter/X, Threads, Bluesky, and Instagram.
FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
Ben is a Senior Editor for 9to5Google.
Find him on Twitter @NexusBen. Send tips to schoon@9to5g.com or encrypted to benschoon@protonmail.com.
🔗 Related Articles
📰 #23610. 15 retro tech gift ideas for the nostalgic gamer or builder in your life 📰 #22586. Tech Report: Could Firenze Lai’s first UK solo show signal a shift in global market recognition for Hong Kong artists? 📰 #21968. Latest Update: 6 Budget Running Watches That Deliver Accurate GPS, Long Battery Life, and Much More
General
⚖️ Neutral
🌐 Hugging Face
#11310. Breaking: Training Design for Text-to-Image Models: Lessons from Ablations
📅 03 Feb 2026 • ⏱️ 30m • 📚 Deep Dive (6057 w)
Breaking: Training Design for Text-to-Image Models: Lessons from Ablations
📅 03 Feb 2026 | ⏱️ 30 min read (6057 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~30 mins left to finish
📖 0% read
💡 Key Takeaways
- This is the second part of our series on training efficient text-to-image models from scratch.
- In the first post of this series, we introduced our goal: training a competitive text-to-image foundation model entirely from scratch, in the open, and at scale.
- According to recent reports, in this post, we shift our focus from architecture to training.
Welcome back! This is the second part of our series on training efficient text-to-image models from scratch.
In the first post of this series, we introduced our goal: training a competitive text-to-image foundation model entirely from scratch, in the open, and at scale. We focused primarily on architectural choices and motivated the core design decisions behind our model PRX. We also released an early, small (1.2B parameters) version of the model as a preview of what we are building (go try it if you haven't already 😉).
According to recent reports, in this post, we shift our focus from architecture to training. The goal is to document what actually moved the needle for us when trying to make models train faster, converge more reliably, and learn better representations. The field is moving swiftly and the list of “training tricks” keeps growing, so rather than attempting an exhaustive survey, we structured this as an experimental logbook: we reproduce (or adapt) a set of recent ideas, implement them in a consistent setup, and report how they affect optimization and convergence in practice. Finally, we do not only report these techniques in isolation; we also explore which ones remain useful when combined.
According to recent reports, in the next post, we will publish the full training recipe as code, including the experiments in this post. We will also run and report on a public "speedrun" where we put the best pieces together into a single configuration and stress-test it end-to-end. This exercise will serve both as a stress test of our current training pipeline and as a concrete demonstration of how far careful training design can go under tight constraints. If you haven’t already, we invite you to join our Discord to continue the discussion. A significant part of this project has been shaped by exchanges with community members, and we place a high value on external feedback, ablations, and alternative interpretations of the results.
In a recent development, before introducing any training-efficiency techniques, we first establish a clean reference run. This baseline is intentionally simple. It uses standard components, avoids auxiliary objectives, and does not rely on architectural shortcuts or tricks to save compute resources. Its role is to serve as a stable point of comparison for all subsequent experiments.Concretely, this is a pure Flow Matching (Lipman et al., 2022) training setup (as introduced in Part 1) with no extra objectives and no architectural speed hacks. We will use the small PRX-1.2B model we presented in the first post of this series (single stream architecture with global attention for the image tokens and text tokens) as our baseline and train it in Flux VAE latent space, keeping the configuration fixed across all comparisons unless stated otherwise.
The baseline training setup is as follows:.
This baseline configuration provides a transparent and reproducible anchor. It allows us to attribute observed improvements and regressions to specific training interventions, rather than to shifting hyperparameters or hidden setup changes. Throughout the remainder of this post, every technique is evaluated against this reference with a single guiding question in mind:.
Does this modification improve convergence or training efficiency relative to the baseline?
Examples of baseline model generations after 100K training steps.
It has been revealed that to keep this post grounded, we rely on a small set of metrics to monitor checkpoints over time. None of them is a perfect proxy for perceived image quality, but together they provide a practical scoreboard while we iterate.
Fréchet Inception Distance (FID): (Heusel et al., 2017) Measures how close the distributions of generated and real images are, using Inception-v3 feature statistics (mean and covariance). Lower values typically correlate with higher sample fidelity.
CLIP Maximum Mean Discrepancy (CMMD): (Jayasumana et al., 2024) Measures the distance between real and generated image distributions using CLIP image embeddings and Maximum Mean Discrepancy (MMD). Unlike FID, CMMD does not assume Gaussian feature distributions and can be more sample-efficient; in practice it often tracks perceptual quality better than FID, though it is still an imperfect proxy.
DINOv2 Maximum Mean Discrepancy (DINO-MMD): Same MMD-based distance as CMMD, but computed on DINOv2 (Oquab et al. 2023) image embeddings instead of CLIP. This provides a complementary view of distribution shift under a self-supervised vision backbone.
Network throughput: Average number of samples processed per second (samples/s), as a measure of end-to-end training efficiency.
With the scoreboard defined, we can now dive into the methods we explored, grouped into four buckets: Representation Alignment, Training Objectives, Token Routing and Sparsification, and Data.
Industry observers note that diffusion and flow models are typically trained with a single objective: predict a noise-like target (or vector field) from a corrupted input. Early in training, that one objective is doing two jobs at once: it must build a useful internal representation and learn to denoise on top of it. Representation alignment makes this explicit by keeping the denoising objective and adding an auxiliary loss that directly supervises intermediate features using a strong, frozen vision encoder. This tends to speed up early learning and bring the model’s features closer to those of modern self-supervised encoders. As a result, you often need less compute to hit the same quality.
Recent findings suggest that A useful way to view it is to decompose the denoiser into an implicit encoder that produces intermediate hidden states, and a decoder that maps those states to the denoising target. The claim is that representation learning is the bottleneck: diffusion and flow transformers do learn discriminative features, but they lag behind foundation vision encoders when training is compute-limited. Therefore, borrowing a powerful representation space can make the denoising problem easier.
According to recent reports, REPA adds a representation matching term on top of the base flow-matching objective.Let x0∼pdatax_0 \sim p_{\text{data}}x0∼pdata be a clean sample and x1∼ppriorx_1 \sim p_{\text{prior}}x1∼pprior be the noise sample. The model is trained on an interpolated state xtx_txt (for t∈[0,1]t \in [0,1]t∈[0,1]) and predicts a vector field vθ(xt,t)v_\theta(x_t, t)vθ(xt,t). In REPA, a pretrained vision encoder fff processes the clean sample x0x_0x0 to produce patch embeddings y0=f(x0)∈RN×Dy_0 = f(x_0) \in \mathbb{R}^{N \times D}y0=f(x0)∈RN×D, where NNN is the number of patch tokens and DDD is the teacher embedding dimension. In parallel, the denoiser processes xtx_txt and produces intermediate hidden tokens hth_tht (one token per patch). A small projection head hϕh_\phihϕ maps these student hidden tokens into the teacher embedding space, and an auxiliary loss maximizes patch-wise similarity between corresponding teacher and student tokens: LREPA(θ,ϕ)=−Ex0,x1,t[1N∑n=1Nsim(y0,[n], hϕ(ht,[n]))] \mathcal{L}_{\text{REPA}}(\theta,\phi) = -\mathbb{E}_{x_0,x_1,t}\Big[\frac{1}{N}\sum_{n=1}^{N} \text{sim}\big(y_{0,[n]},\, h_\phi(h_{t,[n]})\big)\Big] LREPA(θ,ϕ)=−Ex0,x1,t[N1n=1∑Nsim(y0,[n],hϕ(ht,[n]))] Here n∈{1,…,N}n \in \{1,\dots,N\}n∈{1,…,N} indexes patch tokens, y0,[n]y_{0,[n]}y0,[n] is the teacher embedding for patch nnn, ht,[n]h_{t,[n]}ht,[n] is the corresponding student hidden token at time ttt, and sim(⋅,⋅)\text{sim}(\cdot,\cdot)sim(⋅,⋅) is typically cosine similarity.
This term is combined with the main flow-matching loss:.
L=LFM+λ LREPA \mathcal{L} = \mathcal{L}_{\text{FM}} + \lambda\,\mathcal{L}_{\text{REPA}} L=LFM+λLREPA.
with λ\lambdaλ controlling the trade-off.
In practice, the student is trained to produce noise-robust, data-consistent patch representations from xtx_txt, so later layers can focus on predicting the vector field and generating details rather than rediscovering a semantic scaffold from scratch.
According to recent reports, we ran REPA on top of our baseline PRX training, using two frozen teachers: DINOv2 and DINOv3 (Siméoni et al., 2025). The pattern was very consistent: adding alignment improves quality metrics, and the stronger teacher helps more, at the cost of a bit of speed.
Industry observers note that on the quality metrics, both teachers improve over the baseline. The effect is strongest with DINOv3, which achieves the best overall numbers in this run.
According to recent reports, REPA is not free: we pay for an extra frozen teacher forward and the patch-level similarity loss, which shows up as a throughput drop from 3.95 batches/s to 3.66 (DINOv2) or 3.46 (DINOv3). In other words, DINOv3 prioritizes maximum representation quality at the cost of slower training, while DINOv2 offers a more efficient tradeoff, still delivering substantial gains with a smaller slowdown.
Our practical takeaway is that REPA is a strong lever for text-to-image training. In our setup, the throughput trade-off is real and the net speedup (time required to reach a given level of image quality) felt a bit less dramatic than what the authors of the paper report on ImageNet-style, class-conditioned generation. That mentioned, the quality gains are still clearly significant. Qualitatively, we also saw the difference early: after ~100K steps, samples trained with alignment tended to lock in cleaner global structure and more coherent layouts, which makes it easy to see why REPA (and alignment variants more broadly) have become a go-to ingredient in modern T2I training recipes.
According to recent reports, A natural follow-up to REPA is: what exactly should we be aligning? iREPA argues that the answer is spatial structure, not global semantics. Across a large sweep of 27 vision encoders, the authors find that ImageNet-style “global” quality (e.g., linear-probe accuracy on patch tokens) is only weakly predictive of downstream generation quality under REPA, while simple measures of patch-token spatial self-similarity correlate much more strongly with FID. Based on that diagnosis, iREPA makes two tiny but targeted changes to the REPA recipe to better preserve and transfer spatial information:.
Despite representing “less than 4 lines of code”, these tweaks consistently speed up convergence and improve quality across encoders, model sizes, and even REPA-adjacent training recipes.
In our setup, we observed a similar kind of boost when applying the iREPA spatial tweaks on top of DINOv2: convergence was a bit smoother and the metrics improved more steadily over the first 100K steps. Interestingly, the same changes did not transfer as cleanly when applied on top of a DINOv3 teacher and they tended to degrade performance rather than help. We do not want to over-interpret that result: this could easily be an interaction with our specific architecture, resolution/patching, loss weighting, or even small implementation details. Still, given this inconsistency across teachers, we will likely not include these tweaks in our default recipe, even if they remain an interesting option to revisit when tuning for a specific setup.
The paper REPA Works Until It Doesn't: Early-Stopped, Holistic Alignment Supercharges Diffusion Training (Wang et al., 2025) highlights a key caveat: REPA is a powerful early accelerator, but it can plateau or even become a brake later in training. The authors describe a capacity mismatch. Once the generative model starts fitting the full data distribution (especially high-frequency details), forcing it to stay close to a frozen recognition encoder’s lower-dimensional embedding manifold becomes constraining. Their practical takeaway is simple: keep alignment for the “burn-in” phase, then turn it off with a stage-wise schedule.
We observed the same qualitative pattern in our own runs. When training our preview model, removing REPA after ~200K steps noticeably improved the overall feel of image quality, textures, micro-contrast, and fine detail continued to sharpen instead of looking slightly muted. For that reason, we also recommend treating representation alignment as a transient scaffold. Use it to get fast early progress, then drop it after a while once the model’s own generative features have caught up.
So far, “alignment” meant regularizing the generator’s internal features against a frozen teacher while treating the tokenizer / latent space as fixed. A more direct lever is to shape the latent space itself so the representation presented to the flow backbone is intrinsically easier to model, without sacrificing the reconstruction fidelity needed for editing and downstream workflows.
It has been revealed that REPA-E (Leng et al., 2025) makes this concrete. Its starting point is a failure mode: if you simply backprop the diffusion / flow loss into the VAE, the tokenizer swiftly learns a pathologically easy latent for the denoiser, which can even degrade final generation quality. REPA-E’s fix is a two-signal training recipe:.
Thanks to these two tricks, the tokenizer is explicitly optimized to produce latents that yield higher alignment and empirically better generations.
In parallel, Black Forest Labs’ FLUX.2 AE work frames latent design as a trade-off between learnability, quality, and compression.Their core argument is that improving learnability requires injecting semantic structure into the representation, rather than treating the tokenizer as a pure compression module. This motivates retraining the latent space to explicitly target “better learnability and higher image quality at the same time". They do not share the full recipe, but they do clearly state the key idea: make the AE’s latent space more learnable by adding semantic or representation alignment, and explicitly point to REPA-style alignment with a frozen vision encoder as the mechanism they build on and integrate into the FLUX.2 AE.
Recent findings suggest that to probe alignment in the latent space, we compared two pretrained autoencoders as drop-in tokenizers for the same flow backbone: a REPA-E-VAE (where we do add the REPA alignment objective, as in the paper) and the Flux2-AE (where we do not add REPA, following their recommendation). The results were, honestly, extremely impressive, both quantitatively and qualitatively. In samples, the gap is immediately visible: generations show more coherent global structure and cleaner layouts, with far fewer “early training” artifacts.
Sources indicate that A first striking point is that both latent-space interventions lower the FID by ~6 points (18.20 to ~12.08), which is a much larger jump than what we typically get from “just” aligning intermediate features. This strongly supports the core idea: if the tokenizer produces a representation that is intrinsically more learnable, the flow model benefits everywhere.
According to recent reports, the two AEs then behave quite differently in the details. Flux2-AE dominates most metrics (very low CMMD and DINO_MMD, but it comes with a huge throughput penalty: batches/sec drops from 3.95 to 1.79. In our case this slowdown is explained by practical factors they also emphasize: the model is simply heavier, and it also produces a larger latent (32 channels), which increases the amount of work the diffusion backbone has to do per step.
REPA-E-VAE is the “balanced” option: it reaches essentially the same FID as Flux2-AE while keeping throughput much closer to the baseline (3.39 batches/sec).
Recent findings suggest that architecture gets you capacity, but the training objective is what decides how that capacity is used. In practice, small changes to the loss often have outsized effects on convergence speed, conditional fidelity, and how quickly a model “locks in” global structure. In the sections below, we will go through the objectives we tested on top of our baseline rectified flow setup, starting with a simple but surprisingly effective modification: Contrastive Flow Matching.
It has been revealed that flow matching has a nice property in the unconditional case: trajectories are implicitly encouraged to be unique (flows should not intersect). But once we move to conditional generation (class- or text-conditioned), different conditions can still induce overlapping flows, which empirically demonstrates up as “averaging” behavior: weaker conditional specificity, and muddier global structure. Contrastive flow matching addresses this directly by adding a contrastive term that pushes conditional flows away from other flows in the batch.
Recent findings suggest that for a given training triplet (x,y,ε)(x, y, \varepsilon)(x,y,ε), standard conditional flow matching trains the model velocity vθ(xt,t,y)v_\theta(x_t,t,y)vθ(xt,t,y) to match the target transport direction. Contrastive flow matching keeps that positive term, but additionally samples a negative pair (x~,y~,ε~)(\tilde{x}, \tilde{y}, \tilde{\varepsilon})(x~,y~,ε~) from the batch and penalizes the model if its predicted flow is also compatible with that other trajectory. In the paper’s notation, this becomes:.
LΔFM(θ)=E[∥vθ(xt,t,y)−(α˙tx+σ˙tε)∥2 − λ∥vθ(xt,t,y)−(α˙tx~+σ˙tε~)∥2] \mathcal{L}_{\Delta \text{FM}}(\theta) = \mathbb{E}\Big[ \|v_\theta(x_t,t,y)-(\dot{\alpha}_t x+\dot{\sigma}_t\varepsilon)\|^2 \;-\; \lambda \|v_\theta(x_t,t,y)-(\dot{\alpha}_t \tilde{x}+\dot{\sigma}_t\tilde{\varepsilon})\|^2 \Big] LΔFM(θ)=E[∥vθ(xt,t,y)−(α˙tx+σ˙tε)∥2−λ∥vθ(xt,t,y)−(α˙tx~+σ˙tε~)∥2].
Industry observers note that where λ∈[0,1)\lambda\in[0,1)λ∈[0,1) controls the strength of the “push-away” term. Intuitively: match your own trajectory, and be incompatible with someone else’s.
According to recent reports, the authors show that contrastive flow matching produces more discriminative trajectories and that this translates into both quality and efficiency gains: faster convergence (reported up to 9× fewer training iterations to reach similar FID) and fewer sampling steps (reported up to 5× fewer denoising steps) on ImageNet (Deng et al. 2009) and CC3M(Sharma et al., 2018) experiments.
A key advantage is that the objective is almost a drop-in replacement: you keep the usual flow-matching loss, then add a single contrastive “push-away” term using other samples in the same batch as negatives which provides the extra supervision without introducing additional model passes.
Sources indicate that on this run, contrastive flow matching yields a small but measurable improvement on the representation-driven metrics: CMMD goes from 0.41 → 0.40 and DINO-MMD from 0.39 → 0.36. The magnitude of the gain is smaller than what the paper reports on ImageNet, which is not too surprising: text conditioning is much more complex than discrete classes, and the training data distribution is likely less “separable” than ImageNet, making the contrastive signal harder to exploit.
Sources indicate that we do not see an improvement in FID in this specific experiment (it slightly worsens), but the throughput cost is negligible in practice (3.95 → 3.75 batches/sec). Given the simplicity of the change and the consistent movement in the right direction for the conditioning/representation metrics, we will likely still keep contrastive flow matching in our training pipeline as a low-cost regularizer.
Back to Basics: Let Denoising Generative Models Denoise is probably one of our favorite recent papers in the diffusion space because it is not a new trick but a reset: stop asking the network to predict off-manifold quantities (noise or velocity) and just let it denoise. Most modern diffusion and flow models train the network to predict noise ε\varepsilonε or a mixed quantity like velocity vvv. Under the manifold assumption, natural images live on a low-dimensional manifold, while ε\varepsilonε and vvv are inherently off-manifold, so predicting them can be a harder learning problem than it looks.
According to recent reports, the authors frame the problem with the standard linear interpolation between the clean image xxx and the noise ε\varepsilonε: zt=t x+(1−t) ε, z_t = t\,x + (1-t)\,\varepsilon, zt=tx+(1−t)ε, and the corresponding flow velocity: v=dztdt=x−ε. v = \frac{d z_t}{dt} = x - \varepsilon. v=dtdzt=x−ε.
It has been revealed that instead of outputting vθv_\thetavθ directly, the model predicts a clean image estimate: xθ(zt,t):=netθ(zt,t), x_\theta(z_t,t) := \mathrm{net}_\theta(z_t,t), xθ(zt,t):=netθ(zt,t), and we convert it to a velocity prediction via: vθ(zt,t)=xθ(zt,t)−zt1−t. v_\theta(z_t,t) = \frac{x_\theta(z_t,t) - z_t}{1-t}. vθ(zt,t)=1−txθ(zt,t)−zt.
Then we can keep the exact same flow-style objective in v-space: Lv=Et,x,ε[∥vθ(zt,t)−v∥22]withv=x−ε. \mathcal{L}_{v} = \mathbb{E}_{t,x,\varepsilon}\left[\left\|v_\theta(z_t,t) - v\right\|_2^2\right] \quad\text{with}\quad v = x-\varepsilon. Lv=Et,x,ε[∥vθ(zt,t)−v∥22]withv=x−ε.
According to recent reports, this formulation makes the learning problem substantially easier in high dimensions: instead of predicting noise or velocity (which are essentially unconstrained in pixel space), the network predicts the clean image xxx, i.e., something that lies on the data manifold. In practice, this makes it feasible to train large-patch Transformers directly on pixels without a VAE or tokenizer while keeping optimization stable and the total number of tokens manageable.
We first evaluated x-prediction in the same setting as the rest of our objective experiments, namely training in the FLUX latent space at 256×256 resolution.
In this regime, the benefit of x-prediction is unclear. While FID improves slightly compared to the baseline, both CMMD and DINO-MMD degrade noticeably, and throughput is unchanged. This suggests that, when working in an already well-structured latent space, predicting clean images instead of velocity does not consistently dominate the baseline objective, and can even hurt representation-level alignment.
That said, this experiment is not where x-prediction really shines.
The exciting part is that x-prediction stabilizes high-dimensional training, making it feasible to use larger patches and denoise directly in pixel space, without a VAE, at much higher resolutions. Using JiT, we trained a model directly on 1024×1024 images with 32×32 patches, instead of operating in a compressed latent space. Despite the much higher resolution and the absence of a tokenizer, optimization remained stable and fast. We reached FID 17.42, DINO_MMD 0.56, and CMMD 0.71 with a throughput of 1.33 batches/sec.
These results are remarkable: training directly on 1024×1024 images is only about 3× slower than training in a 256×256 latent space, while operating on raw pixels. This strongly supports the core claim of Back to Basics: letting the model predict clean images makes the learning problem significantly easier, and opens the door to high-resolution, tokenizer-free text-to-image training without prohibitive compute costs.
Recent findings suggest that as a result, we initiative to use this formulation as the backbone of our upcoming speedrun experiments, to see how far we can push it when combined with the other efficiency and sparsification techniques discussed above. The main downside for now is that this approach does not let us benefit from the very nice properties of the FLUX.2 VAE; exploring whether some form of alignment or hybrid training could make these two worlds compatible is an open direction we plan to investigate further.
Recent findings suggest that so far, most of the techniques we discussed focus on making each training step more effective: improving the objective, shaping the representations, or accelerating convergence. The next lever is orthogonal: make each step cheaper.
For diffusion and flow transformers, the dominant cost is running deep transformer stacks over a large set of image/latent tokens where attention scales poorly with sequence length. Token sparsification methods target this directly by ensuring that only a subset of tokens pays the full compute price in the expensive parts of the network, while still preserving enough information flow to keep quality high.Most masking approaches accelerate training by removing tokens from the forward pass, then asking the model to hallucinate the missing content from learned placeholders. That works surprisingly well, but it violates the spirit of iterative denoising. Instead of refining all the content in each step, we are reconstructing parts from scratch.
Recent findings suggest that two recent papers illustrate a cleaner alternative: instead of deleting information, they reorganize where compute is spent. TREAD and SPRINT share the same high-level objective of avoiding full-depth computation for every token at every layer, but they pursue it through complementary strategies.
In a recent development, TREAD's (Krause et al., 2025) core idea is to replace compute reduction through information loss, such as dropping or masking tokens, with compute reduction through information transport using token routing. It introduces a route: for each training sample, it randomly selects a fraction of tokens and temporarily bypasses a contiguous chunk of layers, then re-injects those tokens later. Tokens are not discarded. Instead, they avoid paying the cost of full depth. Concretely, for a denoiser with a stack of blocks L0,…,LB−1L_0, \dots, L_{B-1}L0,…,LB−1, TREAD defines a route ritojr_{i\\to j}ritoj (start layer iii, end layer jjj). A subset of tokens follows the cheap path (identity) across Li,…,LjL_i,\dots,L_jLi,…,Lj, while the rest follows the normal full computation. Then both streams merge again at LjL_jLj. In practice, the paper shows that routing up to 50% of tokens remains effective, while higher rates begin to degrade quality.
Industry observers note that SPRINT (Park et al., 2025) extends this approach by introducing sparsity in the most computationally expensive parts of the network, while preserving a dense information pathway. Its recipe is intentionally structured: run dense early layers over all tokens to build reliable low-level features, then keep only a subset of tokens through the sparse middle layers where compute is heaviest, and finally go dense again by re-expanding and fusing sparse deep features with a dense residual stream from the early layers, before producing the output. The key distinction from TREAD is where robustness comes from: TREAD keeps tokens “present” but shallower (routing), whereas SPRINT allows many tokens to be absent in the middle blocks, relying on the dense residual path to preserve full-resolution information. This is what enables more aggressive sparsification in practice. The paper explores drop ratios around 75%, versus ~50% for TREAD.
In a recent development, under our standard 256×256 latent setup, both methods deliver the primary benefit we were targeting. TREAD goes from 3.95 → 4.11 batches/sec, and SPRINT pushes it a bit further to 4.20 batches/sec. The cost is that under our evaluation protocol, this extra throughput comes with a clear loss in quality: FID rises from 18.20 to 21.61 (TREAD) and 22.56 (SPRINT), with the same pattern observed in CMMD and DINO-MMD.
Taken at face value, routing yields a modest ~7–9% throughput gain, but it comes with worse metrics in this benchmark, with SPRINT (the more aggressive scheme) degrading quality slightly more than TREAD.
It has been revealed that one key caveat is that token-sparse / routed models tend to score worse under vanilla Classifier-Free Guidance (CFG), and this effect is likely amplified here because these runs are still relatively undertrained in our setting. The authors of Guiding Token-Sparse Diffusion Models (Krause et al., 2025) argue this is partly an evaluation mismatch: routing changes the model’s effective capacity, and plain “conditional vs. unconditional” CFG often becomes less effective, which can artificially reduce quality. We deliberately did not use specialized guidance schemes to keep our benchmark consistent across methods, and at this stage it would also not be very meaningful to treat the sparse model as a “bad version of itself” for guidance. As a result, we consider these numbers directionally useful, but still pessimistic and worth interpreting with caution.
Industry observers note that at 256×256, routing only gave modest gains because the model processes relatively few tokens. At 1024×1024, the picture changes completely. With 1024 tokens, routing finally targets the dominant cost, and the results are striking.
Industry observers note that both TREAD and SPRINT deliver large throughput gains over the dense baseline, with SPRINT pushing speed the furthest. More importantly, this time the gains do not come at the expense of quality but quite the opposite. TREAD in particular stands out, with a dramatic drop in FID (17.42 → 14.10) alongside strong improvements in CMMD and DINO-MMD. SPRINT is slightly more aggressive and a bit noisier in quality, but still clearly improves over the baseline while being the fastest option.
It has been revealed that in short, this is the regime where token routing really shines: high resolution, many tokens, and JiT-style pixel-space training. Here, routing is no longer a marginal optimization—it’s a major lever that improves both how fast and how well the model trains.
It has been revealed that after covering representation alignment, the core training objective, and token routing, we turned to the fourth axis that kept constantly mattered in practice: data. We found that the choice of training data, including how it is described through captions, can influence the trajectory of a training run as much as optimization techniques. Below are three concrete data experiments that consistently moved the needle in our setup.
Recent findings suggest that captions are an essential part of the training set: for a text-to-image model, they are not just metadata, they are the supervision. The DALL·E 3 (Betker et al., 2023) research paper showed that richer captions can be one of the strongest levers for improving training signal and prompt-following. To isolate the effect in our setup, we kept everything else fixed and changed only the caption style to compare:.
Long, descriptive captions (our baseline): multi-clause captions that mention composition, attributes, lighting, materials, and relationships.
Example "A photograph depicts a fluffy lop-eared rabbit sitting on a weathered wooden surface outdoors. The rabbit is predominantly white with patches of light brown and tan fur, particularly on its head and ears. Its ears droop noticeably, and its fur appears soft and thick. The rabbit's eyes are dark and expressive. It is positioned slightly off-center, facing towards the left of the frame. Behind the rabbit, slightly out of focus, is a miniature dark red metal wheelbarrow. A partially visible orange apple sits to the left of the rabbit. Fallen autumn leaves, predominantly reddish-brown, are scattered around the rabbit and apple on the wooden surface. The background is a blurred but visible expanse of green grass, suggesting an outdoor setting. The lighting is soft and natural, likely diffused daylight, casting no harsh shadows. The overall atmosphere is calm, peaceful, and autumnal. The aesthetic is rustic and charming, with a focus on the rabbit as the main subject. The color palette is muted and natural, consisting mainly of whites, browns, oranges, and greens. The style is naturalistic and straightforward, without any overt artistic manipulation. The vibe is gentle and heartwarming.".
Short, one-line captions: minimal descriptions with much less structure.
Example "A rabbit sitting on top of a wooden table.".
The outcome was unambiguous: switching to short captions severely hurt convergence across all metrics. Long captions provide a richer supervision signal: beyond prompt adherence, there is a very practical optimization reason. More tokens usually means more information, and therefore more learning signal for the denoiser. When the conditioning text specifies composition, attributes, lighting, materials, and relationships, the model gets a sharper “target” for what the denoising trajectory should preserve and refine, especially early in training.
Recent findings suggest that the fun paradox is that this extra detail often makes the learning problem easier, not harder: intuitively, one might expect longer prompts, with more attributes, constraints, and relationships, to increase complexity and burden the model. In practice, the opposite happens. Short captions leave many degrees of freedom unspecified, forcing the model to learn under ambiguity and implicitly average across multiple plausible interpretations. Long captions collapse that uncertainty by turning implicit choices into explicit constraints, allowing the denoiser to focus its capacity on refining a well-posed solution instead of guessing what matters.
Industry observers note that long captions are a strong training-time accelerator, but we still want the model to behave well on short prompts because that is how people actually use these systems. A simple workaround is to end training with a short fine-tuning stage on a mixture of long and short captions. That keeps the benefits of rich supervision early, while teaching the model to stay robust when conditioning is sparse.
Sources indicate that another data-related research question we explore is whether a low-cost synthetic corpus can accelerate early training compared to a real corpus of similar size. For this benchmark, we trained a model on a dataset of real images collected from Pexels and compared it with our Baseline which was trained on synthetic data generated with MidjourneyV6, both of which have around 1M images. We evaluated both runs against the same Unsplash reference set, composed exclusively of real images.
The synthetic-trained model scores better on CMMD and DINO-MMD, while the model trained on real images achieves a lower FID. Rather than a contradiction, this split mostly reflects what these metrics emphasize.
It has been revealed that FID is particularly sensitive to low-level image statistics: fine textures, high-frequency detail, noise patterns, and the subtle irregularities of real photography. Since our evaluation reference is composed of real images, a model trained on real photos naturally matches those statistics more closely, which translates into a better FID. Synthetic images, by contrast, often exhibit slightly different high-frequency signatures, cleaner edges, smoother micro-textures, more uniform noise, which are barely noticeable qualitatively but still get penalized by distributional metrics like FID.
Sources indicate that qualitatively, this difference is easy to spot. Models trained on synthetic data tend to produce images with cleaner global structure and stronger compositional and object coherence, but also exhibit a more synthetic appearance, characterized by smoother textures and reduced photographic noise. In contrast, models trained on real images better capture the irregular, fine-grained textures typical of natural photographs, though they often require more training to achieve comparable global structure.
One plausible explanation synthetic data remains so effective early on is that it exposes the model to a wider range of compositional collisions: unusual pairings of objects, attributes, styles, and viewpoints that rarely co-occur in natural datasets. While this can hurt realism at the texture level, it forces the model to explain a broader space of combinations, which appears to help with early disentanglement and structure learning.
Considered jointly, this suggests a simple but practical strategy: synthetic data is an efficient way to bootstrap training and lock in global structure quickly, while real images remain important later on if matching photographic texture statistics is the priority.
Industry observers note that finally, we experimented with a targeted Supervised Fine-Tuning (SFT) pass using Alchemist (Startsev et al., 2025), a compact dataset explicitly curated for high-impact. Alchemist is small by design (3,350 image–text pairs), but is constructed through a sophisticated curation pipeline that starts from a web-scale pool and progressively distills it down to visually exceptional samples.
In our setup, we fine-tuned our preview models for 20K steps on Alchemist. Despite the dataset’s small size, it had an outsized effect: it adds a distinct “style layer” with better composition, more photographic polish, and richer scenes without a clear impact on generalization.
The samples below show a side-by-side comparison of generations from the same base model, before and after the Alchemist fine-tuning pass.
Last but not least, we will briefly cover two practical training details that turned out to matter more than we expected. These factors are easily overlooked and in our case they had a clear impact on convergence and final image quality.
We generally default to AdamW for our benchmarks because it’s predictable and easy to compare across runs. However, lately, we have seen a renewed interest in optimizers that try to behave more like a good preconditioner without the full overhead of second-order methods. One recent example is Muon (Jordan et al., 2024), which, at a high level, tries to improve optimization by applying a better-conditioned update step, often translating into faster convergence and cleaner progress early in training.
In our setup, Muon was one of the rare cases in which a change of optimizer produced an immediately observable effect on the metrics.
For this experiment, we used the official PyTorch implementation of Muon, which at the moment supports Distributed Data Parallel (DDP) training only. If you’re running Fully Sharded Data Parallel (FSDP), there are community variants available; for example here.
While we refrain from broad conclusions based on a single benchmark, these results indicate that optimizer choice extends beyond stability considerations and can yield tangible gains in time-to-quality.
We eventually identified an error in our setup, where the denoiser weights were mistakenly stored in bfloat16 for a period of time.
Industry observers note that to be clear, using the BF16 autocast is great. Running the forward and backward passes in BF16 or mixed precision is standard and usually what you want for speed and memory. The problem arises from keeping the parameters in BF16 precision, which negatively impacts numerically sensitive operations.
In practice, some layers and operations are much less tolerant to reduced parameter precision:.
So the rule we now follow very strictly is: use BF16 autocast for compute, but keep weights (and optimizer state) in FP32 or at least ensure numerically sensitive modules stay FP32.
It is not a glamorous trick but it is exactly the kind of “silent” detail that can cost you multiple days of work if you do not notice it early.
We ran a systematic set of ablations on PRX training, comparing a range of optimization, representation, efficiency, and data choices against a clean flow-matching baseline using both quality metrics and throughput.
It has been revealed that the biggest gains came from alignment: REPA boosts early convergence (best used as a burn-in, then turned off), and better latents/tokenizers (REPA-E/FLUX2-AE) give a large jump in quality with clear speed trade-offs. Objective tweaks were mixed—contrastive FM helped slightly, while x-prediction mattered most by enabling stable 1024² pixel training. Token routing (TREAD/SPRINT) is minor at 256² but becomes a major win at high resolution. Data and practical details also mattered: long captions are critical, synthetic vs. real data shifts texture vs. structure, small SFT adds polish, Muon helped, and BF16-stored weights quietly hurt training.
In a recent development, that’s it for Part 2! If you want to play with an earlier public checkpoint from this series, the PRX-1024 T2I beta is still available here.
We are really excited about what’s next: in the coming weeks we will release the full source code of the PRX training framework, and we will do a public 24-hour “speedrun” where we combine the best ideas from this post into a single run and see how far the full recipe can go in one day.
If you made it this far, first of all thank you very much for your interest. Furthermore, we would love to have you join our Discord community where we discuss PRX progress and results, along with everything related to diffusion and text-to-image models.
It has been revealed that amazing work ! Super nice to see you work on this !
General
⚖️ Neutral
🌐 Fastcompany
#11309. Industry News: 23 ways to handle tasks that trigger dread
📅 16 Nov 2026 • ⏱️ 20m • 📚 Deep Dive (3988 w)
Industry News: 23 ways to handle tasks that trigger dread
📅 16 Nov 2026 | ⏱️ 20 min read (3988 words, 📚 Deep Dive) | Source: Fastcompany
⏱️ ~20 mins left to finish
📖 0% read
💡 Key Takeaways
- According to recent reports, everyone has them: Tasks they dread.
- Everyone has them: Tasks they dread.
- Recent findings suggest that we asked members of the Fast Company Impact Council how they handle tasks they dread.
According to recent reports, everyone has them: Tasks they dread. They can range from mundane or routine items that clog the calendar to difficult conversations and meetings that cause stress. Avoiding them doesn’t make them go away. It just makes the dread heavier. Figuring out how to get through them frees up the time and headspace they take up. We asked members of the Fast Organization Impact Council how they handle tasks they dread. Here, 23 of them provide their best tips for getting them off your to-do list. 1. BODY-DOUBLE THE TASK I don’t tackle them alone. We call it body doubling: pulling in a teammate for a focused session to knock out the task neither of us wants to face solo. It depends on the task at hand too! My default is our incredible chief of staff. She’s the left brain to my right brain. From there it’s our executive team if the task requires finance, operations, technology, etc. Consistently routing the task with the right team members keeps the business moving forward. — Cody Barbo, Trust & Will 2. JUST DO IT AND DO IT NOW Dread is what you feel when you aren’t just doing it. Just do it. And when you do, more often than not you enter flow state, and you just keep doing stuff. — Eric Simons, Bolt.new 3. APPROACH IT LIKE AN ATHLETE When I face a task I’d rather avoid, I try to tackle it right away, before I give myself a hundred reasons to postpone it. I approach these situations like an athlete: Discomfort is part of progress, not a reason to stop. Whether it’s a challenging negotiation or a difficult decision, I’ve learned to take action even when I don’t feel ready. Years of daily training and building at my company have taught me that motivation comes and goes, and discipline is the key to keeping you moving forward. You can’t always control how you feel about a task, but you can train yourself to show up and get it done anyway. — Victoria Repa, BetterMe 4. TAKE ONE SMALL STEP In my mind, most dread comes from a task that has no clear definition or parameter. I’ve found it helpful to jump on the first physical step, small enough to finish in a few minutes (e.g., open the file, draft the subject line, pull last month’s numbers) and physically stop there to build next steps. This creates a sense of internal accountability. Once the task has a shape, the rest usually goes faster than the dread predicted. Also, if it still sits there after a week, that’s useful information: It may belong to someone else, or it may not need doing at all. — James Chester, WVN 5. CHIP AWAY EACH DAY Momentum beats motivation. I start small and chip away a little each day. Procrastinating doesn’t buy you time, it just weighs you down, and eventually it crowds out the work you love. — Tami Rosen, executive board and advisor to technology and finance companies 6. TACKLE THEM FIRST, EARLY IN THE DAY I do them first, and I make them smaller. Dread grows in the gap between knowing a task needs doing and starting it. So I close that gap early in the day, before anything else competes for my attention. If it’s major, I commit only to the first part. Momentum handles the rest. I’ve also learned to ask what the dread is telling me. Sometimes it’s a sign the task needs a conversation, not more effort, and the fastest way through is a call to the right person. — Megan Noel, Covista 7. NAME WHAT YOU DREAD AND WHY Usually, people dread something because it is uncomfortable, ambiguous, or carries some sort of emotional weight. I try to name what I dread and why, instead of pretending the task itself is the problem. If it matters, do it and do it now, because avoidance compounds just like progress does. The things we put off usually get heavier, not lighter. — Ethan Braden, Texas A&M University 8. TAKE OUT THE TRASH DAY A colleague once inspired me with her “take out the trash day,” dedicating a chunk of time each week to knock through dreaded tasks. With all the noise on Slack, texts, and email, I block an hour at the end of the week, mute my notifications, and cruise through. It’s how I take care of budgets, expenses, and the general paperwork, so I can get back to the creative work where I’m in my flow. Sometimes there’s a snack reward waiting at the end. — Courtney Brigham, Typeface 9. SET A REWARD FOR YOURSELF I break it down into chunks, set a target date and time to complete each chunk, and then block out time and get it done. I also set a reward for myself after doing it. For example, I’ll get to have this great lunch after I finish it. It sounds silly, but it’s nice to have rewards after doing a project that is not enjoyable! — Felicia Curcuru, Binti 10. RELY ON PREPARATION During dreaded high-stakes situations like meetings with multiple stakeholders or delivering sensitive performance-based feedback, I rely on preparation. Coming armed with a brief outline of mission-critical points ensures you stay on track and helps you recover if the conversation gets derailed. If I’m ruminating on a complex problem that I just can’t seem to crack, I put everything down and do something completely unrelated. Taking a walk, listening to a podcast, or even washing the dishes allows my brain to marinate, discover hidden connections, and eventually the solution becomes clear. — Celia Jones, FINN Partners 11. PRIORITIZE ACCORDINGLY Tasks I dread are rarely the most key for our business, so I prioritize them accordingly. However, they tend to bubble up to the higher end of the list of less critical tasks. The longer they remain on my to-do list, the more days they get to impact my morale, so I’m motivated to get them done. — Brad Weber, InspiringApps 12. CONNECT IT TO OUTCOME I try to stay positive by focusing on the value the task will create once it’s completed. I put it in the broader context of the goal it supports and the impact it will have. As a big-picture person, details can be challenging, but connecting the work to a meaningful outcome helps me stay motivated and push through with a positive mindset. — Chris K Bailey, Bailey Brand Consulting 13. TAKE THE MEDICINE ALL AT ONCE I put them off. Then I bundle them up and take care of them all at once. Like medicine. It tastes bad but works. Sort of like Buckley’s cough and cold medicine. — Phillip Haid, Public Inc. 14. STOP AND MAP IT OUT If I catch myself spending real time on something where I’m just going through the motions, I stop and map it out. What are the inputs, what am I doing with them, and what does the output need to look like? Once the process is clearly mapped, it’s usually pretty obvious that a lot of it doesn’t need me. Then I build an automation around it. I still get the result; I just skip the mundane part. — Mike Sewell, Gresham Smith 15. ASK WHETHER YOU’RE THE RIGHT PERSON TO DO IT I try not to spend too much time negotiating with myself. If something needs to be done, I focus on the next step and start. Usually, the anticipation is worse than the task itself. As a CEO, I’ve also learned to ask whether I’m the right person to do it. There are many things I can do, but I don’t need to do all of them. Sometimes leadership means taking something on yourself. Other times it means trusting someone else to own it. What I try to avoid is letting something I don’t enjoy become something the organization has to wait for. — Yuping Huang, Quantum Computing Inc. 16. CARVE UP YOUR DAY Technology marketing is constant context switching and rapid decision-making. If you’re not careful, a whole day passes without a minute of real thought or creativity. You give in to the “critical” transactions, and eventually the work that’s most critical to your job disappears entirely. So I carve up my day. Mornings are for content, strategy, and creative problem-solving. Midday is the transactional work. The last couple of hours go to administration and anything that wasn’t urgent. And if something that needs real creativity slips through until late in the day, it gets the first look the next morning, with fresh eyes. — Colby Proffitt, Seekr 17. DIVIDE IT INTO MANAGEABLE STEPS When I face a task I dread, I focus on understanding what makes it difficult and what depends on completing it. This matters because postponing an uncomfortable responsibility does not remove it. It can affect decisions, relationships, and other people’s work. I divide the task into manageable steps, establish a clear deadline, and begin with the first action. For me, discipline is not about enjoying every responsibility. It is about addressing what needs to be done before hesitation becomes a larger problem. — Manuel Freire-Garabal, Gioya HEI 18. DO THE WORST THING FIRST Do it first. I was told once that you should always do the worst thing on your to-do list first because the day then only gets better. Have stuck to it ever since. And never overlook the power of reward: For every annoying task give yourself a little treat in return. The promise of a future good thing coming your way works every time. — Helen Andrews, Johannes Leonardo 19. AUTOMATE THE MUNDANE Recently, I’ve unlocked a new cheat code in chipping away at those dreaded tasks. When walking to work, I’ll start talking with my favorite large language model of the moment and we can hammer out 10 open items from unanswered Slack messages and emails to meeting recaps and other nagging tasks that can rapidly pile up. When all the right connectors are in place, the efficiency unlock is tremendous and has been a game changer for knocking out those dreaded to-dos. — Matt Conlin, Fluent 20. KNOW WHEN THE TASK BELONGS TO SOMEONE ELSE I like to understand every aspect of my business, even the things that don’t come naturally to me. I’m always open to learning something new, but I also recognize when something falls outside my skill set. I believe in knowing your strengths and surrounding yourself with people who bring expertise you don’t have. If it’s something I can tackle, I get it done. If someone else can do it better, I delegate. My time is best spent where I can make the greatest impact. — Kim Wileman, No Makeup Makeup 21. USE THE HEADWIND AS A TAILWIND I once heard Jimmy Iovine, co-founder of Beats, talk about using a headwind as a tailwind, and it’s stuck with me ever since. If there’s something you hate doing, run towards it, not away from it. Delay is a false economy because it just extends the dread. Then I break it into tiny actions and get the first one done. Momentum beats motivation every time, and most tasks are never as bad as the story you’ve told yourself about them. — Emily Kortlang, Meaco 22. MEET IT AT YOUR COGNITIVE PEAK I use power hours. I know my brain is sharpest late in the evening or early in the morning, so I save the tasks I would normally procrastinate on for that window. I don’t do it every day. The idea is simple: Dreaded work takes far less energy when you meet it at your cognitive peak, so an hour or two of focus can clear what would otherwise linger for weeks. — Muneer Panjwani, Engage for Good | The Halo Awards 23. ATTACK THE FIRST FIVE MINUTES I try to attack the first five minutes rather than the whole task. Dread grows in the space between knowing you have to do something and starting it. Once I take action, the task usually gets a lot less intimidating. — Ran Mullins, Psympl.
Everyone has them: Tasks they dread. They can range from mundane or routine items that clog the calendar to difficult conversations and meetings that cause stress. Avoiding them doesn’t make them go away. It just makes the dread heavier. Figuring out how to get through them frees up the time and headspace they take up.
Recent findings suggest that we asked members of the Fast Company Impact Council how they handle tasks they dread. Here, 23 of them provide their best tips for getting them off your to-do list.
According to recent reports, I don’t tackle them alone. We call it body doubling: pulling in a teammate for a focused session to knock out the task neither of us wants to face solo. It depends on the task at hand too! My default is our incredible chief of staff. She’s the left brain to my right brain. From there it’s our executive team if the task requires finance, operations, technology, etc. Consistently routing the task with the right team members keeps the business moving forward. — Cody Barbo, Trust & Will.
Dread is what you feel when you aren’t just doing it. Just do it. And when you do, more often than not you enter flow state, and you just keep doing stuff. — Eric Simons, Bolt.new.
Sources indicate that when I face a task I’d rather avoid, I try to tackle it right away, before I give myself a hundred reasons to postpone it. I approach these situations like an athlete: Discomfort is part of progress, not a reason to stop. Whether it’s a challenging negotiation or a difficult decision, I’ve learned to take action even when I don’t feel ready. Years of daily training and building at my tech giant have taught me that motivation comes and goes, and discipline is the key to keeping you moving forward. You can’t always control how you feel about a task, but you can train yourself to show up and get it done anyway. — Victoria Repa, BetterMe.
In my mind, most dread comes from a task that has no clear definition or parameter. I’ve found it helpful to jump on the first physical step, small enough to finish in a few minutes (e.g., open the file, draft the subject line, pull last month’s numbers) and physically stop there to build next steps. This creates a sense of internal accountability. Once the task has a shape, the rest usually goes faster than the dread predicted. Also, if it still sits there after a week, that’s useful information: It may belong to someone else, or it may not need doing at all. — James Chester, WVN.
Recent findings suggest that momentum beats motivation. I start small and chip away a little each day. Procrastinating doesn’t buy you time, it just weighs you down, and eventually it crowds out the work you love. — Tami Rosen, executive board and advisor to technology and finance companies.
Sources indicate that I do them first, and I make them smaller. Dread grows in the gap between knowing a task needs doing and starting it. So I close that gap early in the day, before anything else competes for my attention. If it’s big, I commit only to the first part. Momentum handles the rest. I’ve also learned to ask what the dread is telling me. Sometimes it’s a sign the task needs a conversation, not more effort, and the fastest way through is a call to the right person. — Megan Noel, Covista.
It has been revealed that usually, people dread something because it is uncomfortable, ambiguous, or carries some sort of emotional weight. I try to name what I dread and why, instead of pretending the task itself is the problem. If it matters, do it and do it now, because avoidance compounds just like progress does. The things we put off usually get heavier, not lighter. — Ethan Braden, Texas A&M University.
Sources indicate that A colleague once inspired me with her “take out the trash day,” dedicating a chunk of time each week to knock through dreaded tasks. With all the noise on Slack, texts, and email, I block an hour at the end of the week, mute my notifications, and cruise through. It’s how I take care of budgets, expenses, and the general paperwork, so I can get back to the creative work where I’m in my flow. Sometimes there’s a snack reward waiting at the end. — Courtney Brigham, Typeface.
According to recent reports, I break it down into chunks, set a target date and time to complete each chunk, and then block out time and get it done. I also set a reward for myself after doing it. For example, I’ll get to have this great lunch after I finish it. It sounds silly, but it’s nice to have rewards after doing a project that is not enjoyable! — Felicia Curcuru, Binti.
Industry observers note that during dreaded high-stakes situations like meetings with multiple stakeholders or delivering sensitive performance-based feedback, I rely on preparation. Coming armed with a brief outline of mission-critical points ensures you stay on track and helps you recover if the conversation gets derailed. If I’m ruminating on a complex problem that I just can’t seem to crack, I put everything down and do something completely unrelated. Taking a walk, listening to a podcast, or even washing the dishes allows my brain to marinate, discover hidden connections, and eventually the solution becomes clear. — Celia Jones, FINN Partners.
Tasks I dread are rarely the most important for our business, so I prioritize them accordingly. However, they tend to bubble up to the higher end of the list of less critical tasks. The longer they remain on my to-do list, the more days they get to impact my morale, so I’m motivated to get them done. — Brad Weber, InspiringApps.
Recent findings suggest that I try to stay positive by focusing on the value the task will create once it’s completed. I put it in the broader context of the goal it supports and the impact it will have. As a big-picture person, details can be challenging, but connecting the work to a meaningful outcome helps me stay motivated and push through with a positive mindset. — Chris K Bailey, Bailey Brand Consulting.
I put them off. Then I bundle them up and take care of them all at once. Like medicine. It tastes bad but works. Sort of like Buckley’s cough and cold medicine. — Phillip Haid, Public Inc.
If I catch myself spending real time on something where I’m just going through the motions, I stop and map it out. What are the inputs, what am I doing with them, and what does the output need to look like? Once the process is clearly mapped, it’s usually pretty obvious that a lot of it doesn’t need me. Then I build an automation around it. I still get the result; I just skip the mundane part. — Mike Sewell, Gresham Smith.
It has been revealed that I try not to spend too much time negotiating with myself. If something needs to be done, I focus on the next step and start. Usually, the anticipation is worse than the task itself. As a CEO, I’ve also learned to ask whether I’m the right person to do it. There are many things I can do, but I don’t need to do all of them. Sometimes leadership means taking something on yourself. Other times it means trusting someone else to own it. What I try to avoid is letting something I don’t enjoy become something the organization has to wait for. — Yuping Huang, Quantum Computing Inc.
Industry observers note that technology marketing is constant context switching and rapid decision-making. If you’re not careful, a whole day passes without a minute of real thought or creativity. You give in to the “critical” transactions, and eventually the work that’s most critical to your job disappears entirely. So I carve up my day. Mornings are for content, strategy, and creative problem-solving. Midday is the transactional work. The last couple of hours go to administration and anything that wasn’t urgent. And if something that needs real creativity slips through until late in the day, it gets the first look the next morning, with fresh eyes. — Colby Proffitt, Seekr.
In a recent development, when I face a task I dread, I focus on understanding what makes it difficult and what depends on completing it. This matters because postponing an uncomfortable responsibility does not remove it. It can affect decisions, relationships, and other people’s work. I divide the task into manageable steps, establish a clear deadline, and begin with the first action. For me, discipline is not about enjoying every responsibility. It is about addressing what needs to be done before hesitation becomes a larger problem. — Manuel Freire-Garabal, Gioya HEI.
In a recent development, do it first. I was told once that you should always do the worst thing on your to-do list first because the day then only gets better. Have stuck to it ever since. And never overlook the power of reward: For every annoying task give yourself a little treat in return. The promise of a future good thing coming your way works every time. — Helen Andrews, Johannes Leonardo.
Recently, I’ve unlocked a latest cheat code in chipping away at those dreaded tasks. When walking to work, I’ll start talking with my favorite large language model of the moment and we can hammer out 10 open items from unanswered Slack messages and emails to meeting recaps and other nagging tasks that can promptly pile up. When all the right connectors are in place, the efficiency unlock is tremendous and has been a game changer for knocking out those dreaded to-dos. — Matt Conlin, Fluent.
I like to understand every aspect of my business, even the things that don’t come naturally to me. I’m always open to learning something fresh, but I also recognize when something falls outside my skill set. I believe in knowing your strengths and surrounding yourself with people who bring expertise you don’t have. If it’s something I can tackle, I get it done. If someone else can do it better, I delegate. My time is best spent where I can make the greatest impact. — Kim Wileman, No Makeup Makeup.
Recent findings suggest that I once heard Jimmy Iovine, co-founder of Beats, talk about using a headwind as a tailwind, and it’s stuck with me ever since. If there’s something you hate doing, run towards it, not away from it. Delay is a false economy because it just extends the dread. Then I break it into tiny actions and get the first one done. Momentum beats motivation every time, and most tasks are never as bad as the story you’ve told yourself about them. — Emily Kortlang, Meaco.
Recent findings suggest that I use power hours. I know my brain is sharpest late in the evening or early in the morning, so I save the tasks I would normally procrastinate on for that window. I don’t do it every day. The idea is simple: Dreaded work takes far less energy when you meet it at your cognitive peak, so an hour or two of focus can clear what would otherwise linger for weeks. — Muneer Panjwani, Engage for Good | The Halo Awards.
I try to attack the first five minutes rather than the whole task. Dread grows in the space between knowing you have to do something and starting it. Once I take action, the task usually gets a lot less intimidating. — Ran Mullins, Psympl.
General
⚖️ Neutral
🌐 Tomshardware
#11308. Tech Report: We tested the RAM-saving storage tech in Gears of War: E-Day
📅 14 Nov 2026 • ⏱️ 6m • 📚 Deep Dive (1115 w)
Tech Report: We tested the RAM-saving storage tech in Gears of War: E-Day
📅 14 Nov 2026 | ⏱️ 6 min read (1115 words, 📚 Deep Dive) | Source: Tomshardware
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- Gears of War: E-Day delivers an impressive visual and technical showcase.
- However, today we’re focusing on a less-discussed technology that plays an equally crucial role in bringing this visually rich, densely detailed world to systems with more limited hardware resources: storage technology designed to reduce RAM usage.
- Industry observers note that we’ll begin by examining its behavior on a high-end system with plenty of resources to spare, before moving to a more modest configuration that better represents the hardware available to the average PC gamer.
Gears of War: E-Day delivers an impressive visual and technical showcase. The game brings together several advanced graphics technologies, including Unreal Engine 5’s Nanite and Lumen, MegaLights, and RTX Mega Geometry for more accurate ray-traced shadows and reflections, alongside a range of upscaling and frame generation technologies.
However, today we’re focusing on a less-discussed technology that plays an equally crucial role in bringing this visually rich, densely detailed world to systems with more limited hardware resources: storage technology designed to reduce RAM usage.
Industry observers note that we’ll begin by examining its behavior on a high-end system with plenty of resources to spare, before moving to a more modest configuration that better represents the hardware available to the average PC gamer. This will allow us to see how much of a difference the technology makes, particularly on lower-end systems.
In an interview with Digital Foundry, The Coalition explained how they leveraged the Xbox Series S’s fast SSD to bring the dense world of Gears of War: E-Day to a memory-limited system. By effectively using the NVMe SSD as an extension of system memory, they can dynamically load and offload complex city data in real time. This approach allows the game to stream the necessary assets for each scene just in time, overcoming the console’s limited RAM.
Digital Foundry notes that the true “special sauce” lies in The Coalition’s smart data management. The team employs advanced heuristics to determine which assets are fetched from the SSD and when, carefully balancing performance. Overusing this technique could harm frame rates, so the system is tuned to swap data only when it benefits the experience.
Gears of War: E-Day also supports DirectStorage, although based on our previous testing, this alone does not always result in high SSD activity or read rates.
YouTuber Mostly Positive Reviews shared his findings in a recent post on X, where he found higher-than-usual SSD activity in Task Manager when playing the game.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
It has been revealed that gears of War E-Day is visually very impressive, but something has to be done with how the game either compiles shaders or streams data. My 14400F is constantly sitting at 80% CPU usage, 16GB RAM is maxed out, and disk read is sitting at a constant 120 MBps, with spikes up to 500 MBps. Will test this with the 9060 XT as well. These are settings I chose to maintain 60 fps, which it does, except for the massive shader compilation stutters every so often.October 7, 2026.
Based on his findings, we decided to investigate further.
According to recent reports, task Manager does not use a low enough polling period to measure SSD activity accurately, so we used HWInfo with the polling period set to 20 milliseconds. We tested SSD activity across all of the game’s graphics presets at 4K using DLSS Quality.
It has been revealed that in our previous tests of games that relied heavily on the SSD, none came close to sustaining 1 GB/s of average bandwidth. The highest we recorded was 366 MB/s in Forspoken at 4K with maximum settings, while many titles stayed well under 100 MB/s. Some games did show higher peak bandwidths, but these spikes lasted only a few milliseconds. For our purposes, it’s the sustained throughput – reflected in the average bandwidth – that truly matters.
In Gears of War: E-Day at higher settings, we essentially have a steady stream of a little over 1 GB/s at all times, indicating that the disk is indeed being utilized as an extension of system memory. As you can see, peaks hit up to 3.7 GB/s of throughput.
We measured RAM usage on our high-end system to see how much the game will use across each generation of SSD tested.
The game uses a significant amount of system memory, but having the game installed on an NVMe SSD – regardless of generation – saves about 2GB of RAM. The storage technology seems to be working as expected.
Since the game’s average read bandwidth far exceeds the limits of a SATA SSD, we expect that installing the game on one would lead to visual issues – and that is exactly what we observe.
In the first comparison, textures are slow to load, which noticeably reduces image quality. In the second comparison, lighting and shadows take some time to appear. While everything eventually loads correctly, running the game on a SATA SSD does hurt immersion.
It has been revealed that we tested the game across four generations of SSDs to evaluate any impact on performance. Using a high-end system with ample memory, we aim to determine the behavior of the storage technology on a system that is not resource-constrained. We will then compare the performance of our laptop’s internal PCIe 4.0 NVMe SSD with that of a SATA SSD.
In a recent development, on a system with sufficient memory, installing the game on a SATA SSD has no measurable performance impact. The only drawback is the aforementioned visual degradation.
Now, we focused on our lower-end system with only 16GB of DDR5.
Now we start to see the benefit of installing the game on an NVMe SSD, especially on higher settings.
In a recent development, although the average frame rate remains virtually identical on both the NVMe and SATA SSDs, increasing the graphics preset impacts the 1% lows. The NVMe SSD delivers smoother frametimes, resulting in a more responsive and fluid gaming experience.
While the concept isn’t entirely upcoming – Windows already uses virtual memory to page data to disk when physical memory is exhausted – The Coalition has fine-tuned this technology specifically for their game. Their approach ensures that the data being paged out won’t noticeably slow down gameplay as it’s read from disk. In our testing, this technology successfully reduces RAM usage when the game is installed on an NVMe SSD.
Placing the game on an NVMe SSD also enables near-instant asset loading. For systems with 16GB of RAM or less, an NVMe SSD can deliver higher 1% lows, resulting in smoother performance. With RAM prices climbing and many players using machines with 16GB – or even 8GB – of memory, it’s reasonable to wonder if other developers will adopt similar techniques. For titles striving to create visually dense, richly detailed worlds, leveraging fast storage could be a practical way to preserve their vision on lower-end systems.
In a recent development, dan Mateescu is a PC enthusiast with many years of experience benchmarking PC hardware. In 2021, he started his own YouTube channel called 'Compusemble' where he benchmarks hardware in video games and the latest tech demos.
🔗 Related Articles
📰 #23596. Tech Report: Starbucks Red Cup Day is here: See the full list of qualifying drinks and how to get your cup for free 📰 #21981. Our Editors Ride-Tested Virginia Tech’s Top-Rated Road and Gravel Helmets—Including a $60 Pick That Punches Way Above Its Price 📰 #21728. Tech Report: Qapital Review – Worth the Fee Only If Its Rules Get You Saving
General
📈 Bullish
🌐 Fastcompany
#11307. Is another crypto winter upon us? Why Bitcoin, XRP, and Ethereum fell more than 20% in a month
📅 16 Nov 2026 • ⏱️ 7m • 📚 Deep Dive (1407 w)
Is another crypto winter upon us? Why Bitcoin, XRP, and Ethereum fell more than 20% in a month
📅 16 Nov 2026 | ⏱️ 7 min read (1407 words, 📚 Deep Dive) | Source: Fastcompany
⏱️ ~7 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that the crypto markets are down again today, with major tokens suffering significant losses over the past 30 days.
- The crypto markets are down again today, with major tokens suffering significant losses over the past 30 days.
- As of this writing, Bitcoin is trading below $65,000, Ethereum is nearly down to $1,800, and XRP is below 96 cents.
Sources indicate that the crypto markets are down again today, with major tokens suffering significant losses over the past 30 days. As of this writing, Bitcoin is trading below $65,000, Ethereum is nearly down to $1,800, and XRP is below 96 cents. Those are more than 20%, 25%, and 26% drops, respectively, over the past month. Bitcoin hit an all-time high of more than $126,000 a token in October 2025, meaning its value has roughly halved since then. Those falls are causing some to wonder whether another crypto winter is upon us. The term describes extended bear markets across cryptocurrencies, in which digital tokens drop significantly in value and stay down. Major crypto winters previously hit in 2018–2019 and 2022–2023. It may be too early to tell whether this is the start of another one, but several factors have been driving cryptocurrencies lower in recent weeks. Here’s what you need to know. Expected Federal Reserve interest rate hikes One of the greatest factors likely weighing on cryptocurrencies is the expectation that the Federal Reserve will raise interest rates in December. As Reuters reported, a majority of economists expect the Fed to hike rates next month. The hike is expected to be by 25 basis points, to a range of 4.00%–4.25%. Rate hikes make money more expensive to borrow. This can encourage people to save, which can dampen spending and thus help fight inflation. But when money is more expensive to borrow, those who lend it can earn more. So, when rates are higher, investors tend to pull their money from non-interest-bearing assets, like crypto, and put it into interest-bearing assets like U.S. Treasury bills. This reallocation leads to a selloff in crypto, driving the basket of digital currencies lower. AI stock rut Cryptocurrencies aren’t the only assets having a tough time lately. Big Tech stocks—especially AI-adjacent ones—are having a rough few weeks. Last week was perhaps the worst thanks to the Jensen Huang scandal that sent shares of Nvidia Corporation (Nasdaq: NVDA) down more than 12% during the last five trading days. The tech-heavy Nasdaq is also down about 1% during the same period. AI stocks and cryptocurrencies often tend to move in tandem. Both are highly volatile and act as speculative assets. When one falls, investors tend to get jittery and sell off the other class in an effort to prevent further losses and lock in gains. The 2026 midterm elections A blue tsunami swept across America in early November’s midterm elections. In some ways, that is very good for the markets, as a large political majority brings a certain amount of certainty. Investors may or may not like that party’s policy positions—but knowing what’s coming can help them strategy financially. Unfortunately for crypto, the incoming Democratic Congress may be much less friendly to the industry. Crypto investors fear that this new political leadership could propose stronger regulation, which may stymie the industry’s growth—or at least impose checks it otherwise wouldn’t have had if the GOP had retained control of Congress. Crypto Fear and Greed Index falls to “Extreme Fear” level Unsurprisingly, after a 20-plus percent selloff in major tokens over the past month, investors are fretting about crypto’s future—at least in the near term. And nowhere is that worry more evident than when you take a look at CoinMarketCap’s Crypto Fear and Greed Index. The index tracks investor sentiment surrounding the crypto markets. It ranges from 0 to 100. The higher the index, the more optimistic (and potentially greedy) investors tend to be about Bitcoin and other tokens. The lower the index, the more fearful they tend to be. Right now, the index stands at a paltry 13, placing it in the “Extreme Fear” range—its lowest range. It has not been at this level since February 2026, when Bitcoin fell from around $87,500 to around $60,000 in the first few days of the month. Of course, despite the index’s low rating—and the many factors weighing crypto down over the past month—it’s still too early to tell whether the crypto markets are on the cusp of another prolonged downturn. But the longer the rout lasts, the more the specter of another crypto winter will weigh on investors’ minds.
The crypto markets are down again today, with major tokens suffering significant losses over the past 30 days.
As of this writing, Bitcoin is trading below $65,000, Ethereum is nearly down to $1,800, and XRP is below 96 cents.
Those are more than 20%, 25%, and 26% drops, respectively, over the past month.
Bitcoin hit an all-time high of more than $126,000 a token in October 2025, meaning its value has roughly halved since then.
According to recent reports, those falls are causing some to wonder whether another crypto winter is upon us. The term describes extended bear markets across cryptocurrencies, in which digital tokens drop significantly in value and stay down. Major crypto winters previously hit in 2018–2019 and 2022–2023.
It may be too early to tell whether this is the start of another one, but several factors have been driving cryptocurrencies lower in recent weeks. Here’s what you need to know.
Recent findings suggest that one of the greatest factors likely weighing on cryptocurrencies is the expectation that the Federal Reserve will raise interest rates in December. As Reuters reported, a majority of economists expect the Fed to hike rates next month. The hike is expected to be by 25 basis points, to a range of 4.00%–4.25%.
It has been revealed that rate hikes make money more expensive to borrow. This can encourage people to save, which can dampen spending and thus help fight inflation.
It has been revealed that but when money is more expensive to borrow, those who lend it can earn more. So, when rates are higher, investors tend to pull their money from non-interest-bearing assets, like crypto, and put it into interest-bearing assets like U.S. Treasury bills.
This reallocation leads to a selloff in crypto, driving the basket of digital currencies lower.
Cryptocurrencies aren’t the only assets having a tough time lately.
In a recent development, massive Tech stocks—especially AI-adjacent ones—are having a rough few weeks. Last week was perhaps the worst thanks to the Jensen Huang scandal that sent shares of Nvidia Corporation (Nasdaq: NVDA) down more than 12% during the last five trading days.
The tech-heavy Nasdaq is also down about 1% during the same period.
Recent findings suggest that AI stocks and cryptocurrencies often tend to move in tandem. Both are highly volatile and act as speculative assets. When one falls, investors tend to get jittery and sell off the other class in an effort to prevent further losses and lock in gains.
A blue tsunami swept across America in early November’s midterm elections. In some ways, that is very good for the markets, as a large political majority brings a certain amount of certainty.
Investors may or may not like that party’s policy positions—but knowing what’s coming can help them blueprint financially.
Unfortunately for crypto, the incoming Democratic Congress may be much less friendly to the industry.
Crypto investors fear that this newly introduced political leadership could propose stronger regulation, which may stymie the industry’s growth—or at least impose checks it otherwise wouldn’t have had if the GOP had retained control of Congress.
Unsurprisingly, after a 20-plus percent selloff in major tokens over the past month, investors are fretting about crypto’s future—at least in the near term.
And nowhere is that worry more evident than when you take a look at CoinMarketCap’s Crypto Fear and Greed Index. The index tracks investor sentiment surrounding the crypto markets. It ranges from 0 to 100.
The higher the index, the more optimistic (and potentially greedy) investors tend to be about Bitcoin and other tokens. The lower the index, the more fearful they tend to be.
Right now, the index stands at a paltry 13, placing it in the “Extreme Fear” range—its lowest range. It has not been at this level since February 2026, when Bitcoin fell from around $87,500 to around $60,000 in the first few days of the month.
In a recent development, of course, despite the index’s low rating—and the many factors weighing crypto down over the past month—it’s still too early to tell whether the crypto markets are on the cusp of another prolonged downturn. But the longer the rout lasts, the more the specter of another crypto winter will weigh on investors’ minds.
🔗 Related Articles
📰 #18495. Strategy Bitcoin vs. BitMine Ethereum: Which Crypto Treasury Is Better Positioned for a Market Recovery? 📰 #18399. Industry News: Why Is XRP Bleeding More Than Bitcoin, Ether, and Solana in November Sell-Off? Analyst Cites 3 Brutal Reasons 📰 #16722. Nearly a Decade Ago My Friend’s Private Plane Fell Out of the Sky. Then, in Florida This Month, It Happened to Another Friend.
General
⚖️ Neutral
🌐 Sciencedaily
#11306. Tiny magnetic vortices could help computers work more like your brain
📅 26 Oct 2026 • ⏱️ 4m • 📚 Deep Dive (801 w)
Tiny magnetic vortices could help computers work more like your brain
📅 26 Oct 2026 | ⏱️ 4 min read (801 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- It has been revealed that tiny magnetic structures called skyrmions could help pave the way for a newly introduced generation of computers that process information more like the human brain while using far less electricity.
- Recent findings suggest that A study published in the journal Nature Nanotechnology provides new insights into how skyrmions behave and how scientists can control them.
- Most of the research was conducted at the Institute of Physics at Johannes Gutenberg University in Mainz, Germany, with contributions from a professor at the Norwegian University of Science and Technology (NTNU).
It has been revealed that tiny magnetic structures called skyrmions could help pave the way for a newly introduced generation of computers that process information more like the human brain while using far less electricity. Although most people have never heard of skyrmions, these microscopic magnetic vortices may eventually play an vital role in how computers store and process data.
Recent findings suggest that A study published in the journal Nature Nanotechnology provides new insights into how skyrmions behave and how scientists can control them. The findings could help researchers develop smaller, more efficient computing systems and advance emerging quantum technologies.
Most of the research was conducted at the Institute of Physics at Johannes Gutenberg University in Mainz, Germany, with contributions from a professor at the Norwegian University of Science and Technology (NTNU).
"Skyrmions are small, magnetic vortices that can store information in a completely new way," explained Asle Sudbø, who leads NTNU's Centre for Quantum Spintronics (QuSpin).
Unlike conventional technologies, which require increasing amounts of space and energy to handle growing quantities of data, skyrmions could offer a much more efficient alternative.
"Instead of the current technology, where we constantly need more space and energy to process data, skyrmions could make it possible to build much smaller and more energy-efficient data storage systems," explained Sudbø.
Tiny Magnetic Vortices Could Enable Brain-Like Computers.
The potential applications of skyrmions extend well beyond conventional data storage. They are also important to spintronics, which explores ways to use the magnetic properties of electrons in electronic devices, and to research involving topological quantum effects.
One particularly promising possibility is the development of computers that operate in ways similar to biological brains.
"These nanoscale vortices could help develop computers that resemble biological brains," said Sudbø.
In a recent development, rather than relying on conventional transistor-based computing, such systems could use magnetism to process information. In principle, this approach could dramatically reduce electricity consumption, potentially allowing future computers to perform complex tasks with very little energy.
Turning that possibility into practical technology, however, requires scientists to understand exactly how skyrmions behave and how to manipulate them reliably.
The latest research represents an important advance toward that goal.
Scientists Film Magnetic Skyrmion Lattices Melting for the First Time.
In a recent development, skyrmions do not always exist as isolated magnetic structures. Under certain conditions, they organize themselves into repeating patterns known as lattices, resembling the orderly arrangement of atoms in a crystal, but on a much smaller scale.
Scientists can manipulate these arrangements, a capability that could be essential for using skyrmions in future computing devices.
In the newly introduced study, researchers achieved something that had not been demonstrated before. They recorded the melting of a magnetic skyrmion lattice as it happened while simultaneously controlling individual skyrmions.
Sources indicate that "For the first time, researchers have managed to film how a magnetic skyrmion lattice melts in real time, while simultaneously being able to manipulate each individual skyrmion directly as they film it. For example, both their shape and size can be changed 'on the fly'," said Sudbø.
The ability to observe this process directly provides a clearer picture of how skyrmions respond when their organized structures break apart. It also allows researchers to study how changing the size and shape of individual magnetic vortices affects their behavior.
A Newly introduced Step Toward Energy-Efficient Computing.
Understanding how skyrmions behave during the breakdown of their lattices could help scientists develop more precise ways to control them. That control is particularly important if these magnetic structures are to become useful components in future computer systems.
The findings therefore offer more than a fresh way to observe an unusual magnetic phenomenon. They provide information that could help researchers overcome challenges involved in developing practical skyrmion-based technologies.
"The findings give us fresh insight into how these types of particles behave. This could therefore become important for the development of more energy-efficient computer technology in the future," noted Sudbø.
Although substantial development is still needed before skyrmions can be used in everyday computing devices, the research highlights their potential for improving data storage, enabling upcoming computing architectures, and supporting advances in quantum technology.
By learning to observe and manipulate these tiny magnetic vortices in real time, scientists are gaining capabilities that could eventually help reshape the design of computers.
"This could revolutionize the way we think about computers," concluded Sudbø.
Materials provided by Norwegian University of Science and Technology. Original written by Steinar Brandslet. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.

AI & Tech
⚠️ Warning
🌐 9to5google
#11305. Tech Report: November 2026 Pixel Drop: Create My Widget, HiLight for Google Messages, Pixel 10 Rambler, & more
📅 10 Nov 2026 • ⏱️ 3m • 📚 Deep Dive (628 w)
Tech Report: November 2026 Pixel Drop: Create My Widget, HiLight for Google Messages, Pixel 10 Rambler, & more
📅 10 Nov 2026 | ⏱️ 3 min read (628 words, 📚 Deep Dive) | Source: 9to5google
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- According to recent reports, like last year, the next Pixel Drop is rolling out a month early in November.
- Pixel Watch Drop: Create My Widget, Phone-to-Watch Unlock, and Wear OS 7.1.
- Gemini Intelligence is coming to the Pixel 10, Pixel 10 Pro, Pixel 10 Pro XL, and Pixel 10 Pro Fold.
According to recent reports, like last year, the next Pixel Drop is rolling out a month early in November. Coupled with Android 17 QPR2, it’s quite a big Feature Drop for Gemini and other AI capabilities, as well as the Pixel 10 series.
Pixel Watch Drop: Create My Widget, Phone-to-Watch Unlock, and Wear OS 7.1.
Gemini Intelligence is coming to the Pixel 10, Pixel 10 Pro, Pixel 10 Pro XL, and Pixel 10 Pro Fold. The lead feature is Rambler to automatically remove filler words and format your transcription.
Recent findings suggest that the Pixel 10 series also gets Gemini app automation for ordering groceries, ride-sharing, meal delivery, marketplace transactions, and booking reservations. Proactive Gemini Actions let you “send groceries right to your Google Keep list straight from ongoing conversations” and more.
Sources indicate that the Pixel 11 and 10 are getting Create My Widget. This generative UI capability lets you create custom homescreen objects using natural language. For example, you can create a sports widget or an event countdown. The feature first debuted on Googlebooks.
On the Pixel 11, Gemini Call Screen is an “intelligent, proactive assistant that screens incoming inquiries on demand.” Replacing Manual Call Screen, Gemini will speak to callers in a more conversational manner than before.
In a recent development, meanwhile, the Pixel 10+ now lets Gemini make calls on your behalf in the US. Use cases include changing reservations, putting items on hold, and checking inventory. Beta testing started in September.
According to recent reports, the AI features continue with 10 latest Custom Icon styles. Following the March introduction, Google has upgraded the experience with Nano Banana for higher-quality icons. Available on Pixel 6a+.
According to recent reports, pixel Solver in the Google Calculator app provides generative AI custom templates and allows for conversational, multi-step problem solving using prompts. This is available on Pixel 11+.
Sources indicate that unit Conversion is a “top-tier module” that saves you from switching between your browser and the Calculator app. It offers inline mathematics, combined unit interpretation, and real-time exchange rates on the Pixel 6a+.
On the Pixel 11 Pro, Pro XL, and Pro Fold, HiLight now supports Google Messages notifications after being restricted to phone calls and Gemini at launch.
Pixel Search is now available on the Pixel 6 and newer to provide a more integrated on-device lookup experience that spans apps, web, settings, and other personal content. It allows for natural language search from the search bar at the top of the app grid.
Recent findings suggest that I suspect a lot of these will be server side/app updates. When I went to settings to check for the revision I already noticed the upcoming family hub so it was live even before I installed the new version.
Recent findings suggest that one thing I noticed immediately on my 9 Pro is that the battery life is much better. It's been pretty abysmal lately, I thought it might battery degradation but here we are, it's much improved, fingers crossed it'll stay like that. That alone was worth the upgrade.
Extreme Battery Charging is now available on the Pixel 10 series.
Recent findings suggest that following the 2.0 redesign in September, Pixel VIPs now supports Live Location Sharing. This will surface real-time information and battery status from Find Hub in contact cards and homescreen widgets on the Pixel 6a+.
Transit Mode has been upgraded to automatically trigger based on device sensors. This is available on the Pixel 6a+.
International feature expansions today include:.
Sources indicate that FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
The Pixel is the smaller of two smartphones desi….
Editor-in-chief. Interested in the minutiae of Google and Alphabet. Tips/talk: abner@9to5g.com.

AI & Tech
⚖️ Neutral
🌐 Hugging Face
#11304. The Future of the Global Open-Source AI Ecosystem: From DeepSeek to AI+
📅 03 Feb 2026 • ⏱️ 8m • 📚 Deep Dive (1576 w)
The Future of the Global Open-Source AI Ecosystem: From DeepSeek to AI+
📅 03 Feb 2026 | ⏱️ 8 min read (1576 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~8 mins left to finish
📖 0% read
💡 Key Takeaways
- In this third article, we examine paths and trajectories of prominent Chinese AI organizations, and posit future directions for open source.
- In a recent development, for AI researchers and developers contributing to and relying on the open source ecosystem and for policymakers understanding the rapidly changing environment, due to intraorganizational and global community gains, open source is the dominant and popular approach for Chinese AI organizations for the near future.
- Sources indicate that having examined strategic and architectural changes since DeepSeek's R1, we get a glimpse for the first time at how an organic open source AI ecosystem is taking shape in China.
In this third article, we examine paths and trajectories of prominent Chinese AI organizations, and posit future directions for open source.
In a recent development, for AI researchers and developers contributing to and relying on the open source ecosystem and for policymakers understanding the rapidly changing environment, due to intraorganizational and global community gains, open source is the dominant and popular approach for Chinese AI organizations for the near future. Openly sharing artifacts from models to papers to deployment infrastructure maps to a strategy with the goal of large-scale deployment and integration.
Sources indicate that having examined strategic and architectural changes since DeepSeek's R1, we get a glimpse for the first time at how an organic open source AI ecosystem is taking shape in China. A culmination of powerful players, some established in open source, some new players, and some changing course entirely to contribute to the new open culture, signal that the open collaborative approach is mutually beneficial.
This collaboration is reaching beyond national boundaries; the most followed organization on Hugging Face is DeepSeek, and the fourth most followed is Qwen.
In a recent development, in addition to models, openly sharing science and techniques has not only informed other AI organizations, but also the entire open source community. The most popular papers on Hugging Face largely come from Chinese organizations, namely ByteDance, DeepSeek, Tencent, and Qwen.
source: https://huggingface.co/spaces/evijit/PaperVerse.
Recent findings suggest that alibaba positioned open source as an ecosystem and infrastructure strategy. Qwen was not shaped as a single flagship model, but continuously expanded into a family covering multiple sizes, tasks, and modalities, with frequent updates on Hugging Face and their own platform ModelScope. Its influence did not concentrate on any single version. Instead, it was repeatedly reused as a component across different scenarios, gradually taking on the role of a general AI foundation. By mid-2025, Qwen became the model with most derivatives on Hugging Face, with over 113k models using Qwen as a base, and over 200k model repositories tagging Qwen, far exceeding Meta's Llama's 27k or DeepSeek's 6k. Organization-wide, Alibaba boasts the most derivatives almost as much as both Google and Meta combined.
At the same time, Alibaba aligned model development with cloud and hardware infrastructure, integrating models, chips, platforms, and applications into a single engineering stack.
Industry observers note that tencent also made a significant move from borrowing to building. As one of the first major companies to integrate DeepSeek into core consumer-facing products after R1's release, Tencent did not initially frame open source as a public narrative. Instead, it brought mature models in through plug-in style integration, ran large-scale internal validation, and only later began to release its own capabilities. From May 2025 onward, Tencent accelerated open releases in areas where it already had strengths, such as vision, video, and 3D with its own brand named Tencent Hunyuan (it's now Tencent HY), and these models quickly gained adoption in the community.
ByteDance, by following its "AI application factory" approach, starts selectively open sourcing high value components while keeping its competitive focus on product entry points and large scale usage. In this context, the ByteDance Seed team has contributed several notable open-source artifacts, including UI-TARS-1.5 for multimodal UI understanding, **Seed-Coder **for data-centric code modeling, and the SuperGPQA dataset for systematic reasoning evaluation. Despite a relatively low-profile open-source presence, ByteDance has achieved significant scale in China's AI market, with its AI application Doubao surpassing 100 million DAU in December 2025.
The most notable change within Baidu, whose CEO openly calls short on open source, also started its shift: after years of prioritizing closed models, it re-entered the ecosystem through free access and open release, such as the Ernie 4.5 series. This shift was accompanied by renewed investment in its open-source framework, PaddlePaddle, as well as its own AI chip Kunlunxin, which announced an IPO on January 1, 2026. By connecting models, chips, and PaddlePaddle within a more open system, Baidu can lower costs, attract developers, and influence standards, while maintaining strategic control under shared constraints of compute, cost, and regulation.
Among startups, Moonshot, Z.ai, and MiniMax adjusted rapidly and brought new momentum to the open-source community within months after R1. Models such as Kimi K2, GLM-4.5, and MiniMax M2 all earned places on AI-World's open-model milestone rankings.At the end of 2025, Z.ai and MiniMax released their most advanced open-source models to date and subsequently confirmed their IPO intends in close succession.
The open-sourcing of Kimi K2 was widely described as a "Another DeepSeek moment" for the community. Although Moonshot has not unveiled an IPO, market reports indicate that the tech giant raised approximately $500M in funding by the end of 2025, with AGI and agent-based systems positioned as its primary commercialization objectives.
Those application-first companies such as Xiaohongshu, Bilibili, Xiaomi, and Meituan, previously focused only on the application layer, began training and releasing their own models. With their native advantage in real usage scenarios and domain data, once strong reasoning became available at low cost through open source, building in-house models became practical. It tunes AI around their specific businesses, rather than being constrained by the cost structures or limits of external providers.
If the business world seized the ROI positive opportunity for growth, research institutions and the broader community welcomed the shift even more willingly. Organizations such as BAAI and Shanghai AI Lab redirected more effort toward toolchains, evaluation systems, data platforms, and deployment infrastructure, projects like FlagOpen, OpenDataLab, and OpenCompass. These efforts did not chase single-model performance, but instead strengthened the long-term foundations of the ecosystem.
Recent findings suggest that the defining feature of the latest ecosystem is not that there are more models, but that an entire chain has formed. Models can be open-sourced and extended; deployments can be reused and scaled; software and hardware can be coordinated and swapped; and governance capabilities can be embedded and audited. This is a shift from isolated breakthroughs to a system that can actually run in the real world.
Industry observers note that this ecosystem did not appear overnight. It is built on years of accumulated infrastructure "tailwind" since 2017. Over the past several years, China has periodically invested in data centers and compute centers, gradually forming a nationwide, integrated compute layout centered on the "East Data, West Compute" strategy. The national plan established 8 major compute hubs and 10 data center clusters, guiding compute demand from the east toward the central and western regions.
According to recent reports, public information suggests China intends to invest in continual growth in energy capacity. China's total compute capacity is around 1590 EFLOPS as of the year 2025, ranking among the top globally. Sources in China assert that intelligent compute capacity, tailored for AI training and deployment, is expected to grow by roughly 43% year over year, far outpacing general-purpose compute. At the same time,the average data center power usage effectiveness (PUE) fell to around 1.46, indicating better effectiveness and providing a solid hardware foundation for AI at scale. Energy is a clear key focus.
If the 2017 "Newly introduced Generation AI Development Strategy" was mainly about setting direction and building foundations, then the August 2025 "AI+" action plan clearly shifted focus toward large-scale deployment and deep integration. This marks a directionally different pursuit from AGI. The emergence of R1 provided the missing "lift" at the engineering and ecosystem level. It was the catalyst that systematically activated compute, energy, and data infrastructure that had already been built.
Sources indicate that as a result, in the year following R1's release, China's AI development accelerated along two main paths. First, AI became more deeply embedded in industrial processes, moving beyond chatbots toward agents and workflows. Second, greater emphasis was placed on autonomous and controllable AI systems, reflected in more flexible training pathways and increasingly localized deployment strategies.
Industry observers note that looking back, the real turning point was not the growth in the number of models, but a fundamental change in how open-source models are used. Open source moved from an optional choice to a default assumption in system design. Models became reusable and composable components within larger engineering systems.
Industry observers note that from DeepSeek to "AI+", China's path in 2025 was not about chasing peak performance. It was about building a practical path organized around open source, engineering efficiency, and scalable delivery, a path that has already begun to run on its own.
In a recent development, resource constraints did not limit China's AI development. In some respects, they reshaped its trajectory. The release of DeepSeek R1 acted as a catalytic event, triggering a chain of responses across the domestic industry and accelerating the formation of a more organically structured ecosystem. At the same time, this shift created a critical window for continued domestic research and development. As this ecosystem matures, its longer-term impact---and how the global AI community may engage with an increasingly self-sustaining AI ecosystem in China---will become vital questions for future discussion.
Excellent and insightful observation. Eager to see future discussion on global AI picture built on the momentum of China's open-source ecosystem & its contigent impact on other open-source communities This is probably the core theme of year 2026 for LLM.
The open-source AI movement is evolving rapidly, and it's exciting to see innovations like DeepSeek shaping the future. Greater collaboration, transparency, and accessibility can help drive AI innovation worldwide while benefiting developers, researchers, and businesses alike. Looking forward to seeing how the AI+ ecosystem continues to grow.https://www.pinterest.com/8171PassGovPk/https://x.com/GMustafa76972.
AI & Tech
📈 Bullish
🌐 Tomshardware
#11303. Industry News: U.S. Treasury Secretary questions whether Nvidia knowingly sold AI GPUs to shell companies, states tech giant itself is responsible
📅 14 Nov 2026 • ⏱️ 3m • 📚 Deep Dive (547 w)
Industry News: U.S. Treasury Secretary questions whether Nvidia knowingly sold AI GPUs to shell companies, states tech giant itself is responsible
📅 14 Nov 2026 | ⏱️ 3 min read (547 words, 📚 Deep Dive) | Source: Tomshardware
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Treasury Secretary, admitted that the U.S.
- "I think that there is a lot of leakage in the system, and we are constantly working to close that down," in an interview with CNBC (via @siliconmemes).
- Bessent admitted that despite strict U.S.
Scott Bessent, U.S. Treasury Secretary, admitted that the U.S. export controls cannot prevent all the restricted hardware from reaching China or other adversaries, which is why the country allegedly obtained millions of restricted AI GPUs from Nvidia. At the same time, he questioned the efficiency of Nvidia's internal controls. called for accountability at Nvidia, criticized the firm's general counsel, but stressed that it was unclear whether Nvidia chief executive Jensen Huang knew about the potentially illicit practices.
"I think that there is a lot of leakage in the system, and we are constantly working to close that down," in an interview with CNBC (via @siliconmemes). "One thing here is that the story has been thus far on Jensen Huang's personal foibles. The real story here should be, did Nvidia know their client? And was there a robust effort at Nvidia to make sure that there was no leakage and that they were selling to what were obviously pass-through shell companies? And I think it is key that anyone at the company there be held accountable for that.".
Bessent admitted that despite strict U.S. export controls that prohibit sales of advanced AI GPUs to China, considerable quantities of restricted hardware may still make their way to the country. However, the Treasury Secretary does not believe that the U.S. needs to introduce more stringent export restrictions or grant government agencies additional powers to prevent GPU smuggling. Instead, the authorities should properly enforce existing regulations, according to Bessent.
Recent findings suggest that bessent also criticized Nvidia's general counsel Timothy Teter, who reportedly contacted the U.S. Department of Commerce to inquire whether U.S. authorities were behind the detention of Megaspeed's Alice Wong in Singapore. However, the Treasury Secretary declined to speculate about potential consequences for Nvidia if it turned out that some of its executives knew that their customers acted as intermediaries for Chinese entities. Meanwhile, Bessent expressed confidence that Nvidia's board of directors would conduct a thorough investigation into the matter.
In a recent development, "But let us just say, if this was happening, then there were not robust controls at the manufacturer," Bessent said. "We do not know for a fact that Jensen Huang knew this. The [general council] seems to have been very involved here, probably should have done more oversight rather than the haranguing [government officials at the U.S. DoC].".
Bessent also revealed that the Departments of the Treasury, War, and State, as well as the Office of the U.S. Trade Representative (USTR), had supported the addition of Megaspeed to the Entity List for months. However, the authority to impose such export restrictions belongs to the Department of Commerce's Bureau of Industry and Security (BIS), which reportedly stalled efforts to blacklist Megaspeed for months as Commerce Secretary Howard Lutnick feared that the move could worsen trade tensions with China.
Follow Tom's Hardware on Google News, or add us as a preferred source, to get our latest news, analysis, & reviews in your feeds.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
Anton Shilov is a contributing writer at Tom’s Hardware. Over the past couple of decades, he has covered everything from CPUs and GPUs to supercomputers and from modern process technologies and latest fab tools to high-tech industry trends.
🔗 Related Articles
📰 #15813. Tech Report: U.S. companies from Nvidia to Apple face a growing China dilemma 📰 #12456. Whether it's Black Friday or a CEO scandal, NVIDIA GPUs just don't get deep discounts 📰 #23360. Massive Tech takes a beating as online safety experts accuse companies of doing bare minimum
General
⚖️ Neutral
🌐 Fastcompany
#11302. Industry News: Nike spent years reinventing Air. Meet the upcoming Tuned Air (exclusive)
📅 16 Nov 2026 • ⏱️ 11m • 📚 Deep Dive (2156 w)
Industry News: Nike spent years reinventing Air. Meet the upcoming Tuned Air (exclusive)
📅 16 Nov 2026 | ⏱️ 11 min read (2156 words, 📚 Deep Dive) | Source: Fastcompany
⏱️ ~11 mins left to finish
📖 0% read
💡 Key Takeaways
- Recent findings suggest that for half a century, Nike has been synonymous with Air.
- It has been revealed that for half a century, Nike has been synonymous with Air.
- Today, a day before it reveals its financial results, Nike is unveiling Tuned Air, a high-tech evolution of Air that has been in the works for years.
Recent findings suggest that for half a century, Nike has been synonymous with Air. The cushioning—developed at NASA, then incorporated inside a 1978 running shoe and the Air Max 1—came to represent Nike’s commitment to cutting-edge innovation. Now, with Nike on its back foot after several years of missteps, the tech giant is counting on a new version of Air to help pull it out of its slump. Today, a day before it announces its financial results, Nike is unveiling Tuned Air, a high-tech evolution of Air that has been in the works for years. It’s debuting this technology in a running sneaker that will come out within a year. But Nike sees Tuned Air as a broader platform that can be incorporated into other sports and even its apparel lines. [Video: Nike] It’s one way Nike hopes to restore its credibility as an innovator and win back runners who have drifted to rivals. Given how much ground Nike has lost in recent years, it’s unclear whether this strategy will work. But the company is optimistic. “There’s no better innovation that speaks to our formula than Air,” states Phil McCartney, Nike’s chief innovation, design, and product officer. McCartney has spent three decades at Nike, where he ran the footwear business from 2016 until last year, when CEO Elliott Hill put him in charge of innovation, design and product across Nike, Jordan, and Converse. Speaking to me from the LeBron James Innovation Center at Nike’s campus in Beaverton, Oregon, McCartney explained that his team has a motto borrowed from two Nike legends: “Create epic shit. Make athletes better.” (The first comes from Kobe Bryant, the second from Nike’s cofounder, Bill Bowerman.) McCartney says Nike is translating that slogan into a formula, “athlete, science, solution,” that will guide the company’s approach to innovation. His teams gather insights from athletes, then tests ideas at the Nike Sports Research Lab in Beaverton and through field teams in Eldoret, Kenya; London, and Shanghai. [Photo: Nike] Introducing Nike Tuned Air The original Air technology created tough pockets of nitrogen using two sheets of plastic. In that case, the air was evenly distributed, creating cushioning throughout the pocket. With Tuned Air, Nike adds nuance. Before the plastic sheets are pressed together, Nike adds a chemical that allows it to create a pattern; it can now fine-tune where the gas is located and how much air is in each pocket. In doing so, it can make one part of the cushion soft and springy, and another part firm and stable. “It allows us to completely change the relationship between cushioning and support, and precision-tune the experience,” says McCartney. Nike has given this technology to runners over the last few years. “The feedback that we’ve had from the runners who have been trying this for a couple of years now is it feels like no other cushioning system out there,” he says. “Incredibly well cushioned, but also has stability. That’s the sort of holy grail that we’ve been trying to unlock in Air.” While Nike’s approach to achieving this balance might be distinct, many other running brands are also trying to balance cushioning with structure with their own innovations. Brooks’s DNA Tuned foam uses a dual-cell construction, with large cells in the heel to cushion landings and smaller cells in the front to make the toes more responsive. Hoka’s H-Frame features a firm strip of foam in the midsole, surrounded by softer cushioning. On’s CloudTec technology uses hollow tubes of foam molded to the bottom of the sole to absorb impact, along with a steel plate in the midsole. With this newfound ability to modulate how much air is in each pocket, Nike can now explore “wildly different expressions” of the technology, McCartney says. Besides running, Tuned Air will be incorporated into other sports, like soccer, and into clothing like the Air Milano jacket, creating air pockets that improve temperature regulation. Nike can even integrate Tuned Air into lifestyle shoes, like vintage sneakers, creating more comfort. “How could we make an Air Force 1 using a sock liner that is Tuned Air, so you get comfort and support?” McCartney says. Nike has streamlined the manufacturing of Tuned Air so that it can move 70% faster than it typically does from idea to product. This is crucial to allowing Nike to be nimble as it seeks to compete with the many rivals that are also spinning out innovative new products quickly. [Video: Nike] Nike Needs a Win Nike needs this innovation to resonate with consumers. Last quarter, revenue declined 4% to $11.2 billion, and the company expects full-year sales to fall by a high single digit percentage. Sportswear, which accounts for nearly half the business, fell by double digits. Sales in China dropped 26% and Converse sank 28%. Nike has declared a restructuring strategy that will cut more jobs after several rounds of layoffs in recent years. Nike’s rivals have been closely observing its missteps, and taken advantage of the opportunity to steal market share. In running, a category Nike once dominated, it’s now in third place, trailing Brooks and Hoka. In the lifestyle sphere, Adidas has had hit after hit by bringing back its classic Samba and Gazelle, and New Balance has turned its retro styles like the 550 into bestsellers. Meanwhile, Nike hasn’t had a lifestyle sneaker hit in years. Nike’s running business is starting to recover. It’s grown by double digits for more than a year, helped by the successful Vomero line. “We’re seeing market share gains almost daily right now,” says McCartney. Historically, Nike has built running technology for elite athletes that tries to shave seconds off on their race times. But that technology takes a long time to trickle down into running shoes that the average person can lace up. Nike doesn’t have the luxury of time anymore. That’s why its Tuned Air is designed for the everyday runner. “The entry point will be that everyday run,” McCartney says. “When you’re just trying to log your Tuesday morning run, you want the maximum amount of running with precision-tuned support.” Nike is making a big bet on Tuned Air. But whether enough consumers get excited about the technology—and the forthcoming sneakers—to boost Nike’s fortunes is unclear. Tomorrow, when Nike lays out its long-term financial prepares, we’ll get a better glimpse into how much ground it has yet to make up.
It has been revealed that for half a century, Nike has been synonymous with Air. The cushioning—developed at NASA, then incorporated inside a 1978 running shoe and the Air Max 1—came to represent Nike’s commitment to cutting-edge innovation. Now, with Nike on its back foot after several years of missteps, the manufacturer is counting on a new version of Air to help pull it out of its slump.
Today, a day before it reveals its financial results, Nike is unveiling Tuned Air, a high-tech evolution of Air that has been in the works for years. It’s debuting this technology in a running sneaker that will come out within a year. But Nike sees Tuned Air as a broader platform that can be incorporated into other sports and even its apparel lines.
According to recent reports, it’s one way Nike hopes to restore its credibility as an innovator and win back runners who have drifted to rivals. Given how much ground Nike has lost in recent years, it’s unclear whether this strategy will work. But the firm is optimistic.
“There’s no better innovation that speaks to our formula than Air,” notes Phil McCartney, Nike’s chief innovation, design, and product officer.
It has been revealed that mcCartney has spent three decades at Nike, where he ran the footwear business from 2016 until last year, when CEO Elliott Hill put him in charge of innovation, design and product across Nike, Jordan, and Converse. Speaking to me from the LeBron James Innovation Center at Nike’s campus in Beaverton, Oregon, McCartney explained that his team has a motto borrowed from two Nike legends: “Create epic shit. Make athletes better.” (The first comes from Kobe Bryant, the second from Nike’s cofounder, Bill Bowerman.).
Recent findings suggest that mcCartney indicates Nike is translating that slogan into a formula, “athlete, science, solution,” that will guide the firm’s approach to innovation. His teams gather insights from athletes, then tests ideas at the Nike Sports Research Lab in Beaverton and through field teams in Eldoret, Kenya; London, and Shanghai.
The original Air technology created tough pockets of nitrogen using two sheets of plastic. In that case, the air was evenly distributed, creating cushioning throughout the pocket. With Tuned Air, Nike adds nuance. Before the plastic sheets are pressed together, Nike adds a chemical that allows it to create a pattern; it can now fine-tune where the gas is located and how much air is in each pocket. In doing so, it can make one part of the cushion soft and springy, and another part firm and stable. “It allows us to completely change the relationship between cushioning and support, and precision-tune the experience,” says McCartney.
It has been revealed that nike has given this technology to runners over the last few years. “The feedback that we’ve had from the runners who have been trying this for a couple of years now is it feels like no other cushioning system out there,” he says. “Incredibly well cushioned, but also has stability. That’s the sort of holy grail that we’ve been trying to unlock in Air.”.
According to recent reports, while Nike’s approach to achieving this balance might be distinct, many other running brands are also trying to balance cushioning with structure with their own innovations. Brooks’s DNA Tuned foam uses a dual-cell construction, with large cells in the heel to cushion landings and smaller cells in the front to make the toes more responsive. Hoka’s H-Frame features a firm strip of foam in the midsole, surrounded by softer cushioning. On’s CloudTec technology uses hollow tubes of foam molded to the bottom of the sole to absorb impact, along with a steel plate in the midsole.
With this newfound ability to modulate how much air is in each pocket, Nike can now explore “wildly different expressions” of the technology, McCartney claims. Besides running, Tuned Air will be incorporated into other sports, like soccer, and into clothing like the Air Milano jacket, creating air pockets that improve temperature regulation.
Nike can even integrate Tuned Air into lifestyle shoes, like vintage sneakers, creating more comfort. “How could we make an Air Force 1 using a sock liner that is Tuned Air, so you get comfort and support?” McCartney says.
Nike has streamlined the manufacturing of Tuned Air so that it can move 70% faster than it typically does from idea to product. This is crucial to allowing Nike to be nimble as it seeks to compete with the many rivals that are also spinning out innovative new products quickly.
According to recent reports, nike needs this innovation to resonate with consumers. Last quarter, revenue declined 4% to $11.2 billion, and the organization expects full-year sales to fall by a high single digit percentage. Sportswear, which accounts for nearly half the business, fell by double digits. Sales in China dropped 26% and Converse sank 28%. Nike has confirmed a restructuring plan that will cut more jobs after several rounds of layoffs in recent years.
Nike’s rivals have been closely observing its missteps, and taken advantage of the opportunity to steal market share. In running, a category Nike once dominated, it’s now in third place, trailing Brooks and Hoka. In the lifestyle sphere, Adidas has had hit after hit by bringing back its classic Samba and Gazelle, and New Balance has turned its retro styles like the 550 into bestsellers. Meanwhile, Nike hasn’t had a lifestyle sneaker hit in years.
In a recent development, nike’s running business is starting to recover. It’s grown by double digits for more than a year, helped by the successful Vomero line. “We’re seeing market share gains almost daily right now,” says McCartney.
Historically, Nike has built running technology for elite athletes that tries to shave seconds off on their race times. But that technology takes a long time to trickle down into running shoes that the average person can lace up.
Sources indicate that nike doesn’t have the luxury of time anymore. That’s why its Tuned Air is designed for the everyday runner. “The entry point will be that everyday run,” McCartney states. “When you’re just trying to log your Tuesday morning run, you want the maximum amount of running with precision-tuned support.”.
It has been revealed that nike is making a big bet on Tuned Air. But whether enough consumers get excited about the technology—and the forthcoming sneakers—to boost Nike’s fortunes is unclear. Tomorrow, when Nike lays out its long-term financial plans, we’ll get a better glimpse into how much ground it has yet to make up.
🔗 Related Articles
📰 #22151. Breaking: Nike Tuned Air "a huge stride forward" in air-filled trainer design claims innovation lead 📰 #19152. Why Allegiant Air Broke Boeing Loyalty For Nearly 10 Years For Exclusive Airbus Operations But Decided To Go Back 📰 #22562. Industry News: Modern neuroscience is rediscovering a surprising idea freud had 130 years ago
AI & Tech
⚖️ Neutral
🌐 9to5google
#11301. Google rolling out Android 17 QPR2 for Pixel
📅 10 Nov 2026 • ⏱️ 3m • 📚 Deep Dive (513 w)
Google rolling out Android 17 QPR2 for Pixel
📅 10 Nov 2026 | ⏱️ 3 min read (513 words, 📚 Deep Dive) | Source: 9to5google
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Android 17 QPR2 is rolling out to Google Pixel devices as a sizable release that comes a month early in a small deviation from the quarterly cycle.
- November 2026 Pixel Drop: Create My Widget, HiLight for Google Messages, Pixel 10 Rambler, & more.
- Pixel Watch Drop: Create My Widget, Phone-to-Watch Unlock, and Wear OS 7.1.
Android 17 QPR2 is rolling out to Google Pixel devices as a sizable release that comes a month early in a small deviation from the quarterly cycle.
November 2026 Pixel Drop: Create My Widget, HiLight for Google Messages, Pixel 10 Rambler, & more.
Pixel Watch Drop: Create My Widget, Phone-to-Watch Unlock, and Wear OS 7.1.
Recent findings suggest that long-pressing on your homescreen reveals a tweaked design for the menu pop-up where the carousel appears first. Going to Wallpaper & style > Color reveals a new paint palette icon that gives you the “Select a color” slider to choose the main accent after previously being limited to presets. The corner pencil icon on the main page lets you choose between Neutral, Soft, Bright, and Bold themes.
Sources indicate that on the Pixel 11 Pro, 11 Pro XL, and 11 Pro Fold, HiLight now supports message notifications — blinking twice — after launching with just calls and Gemini status. Go to Settings > System > HiLight for the new “Messages from favorites: Glows when your favorite contacts send you messages.” When you go to Google Contacts, the HiLight sheet demonstrates individual options for Phone calls and Messages.
In a recent development, when you’re charging or Battery Saver is enabled, there’s now an outline around the battery icon in Quick Settings. Additionally, it’s now Settings > Battery & charging for a more unified menu as introduced on the Pixel 11 series.
In Quick Settings, there are new Tiles for Audio streams and Voice broadcast. A bigger revision that lets you customize the arrangement of the brightness slider and media player is not launching with this release.
The fresh Status bar customization in Settings > System lets you control which Notification icons appear (All, Priority, or None), as well as System icons:.
Fresh features in the Settings app include:.
Android 17 QPR2 is rolling out starting today for the Pixel 6a, Pixel 7, Pixel 7 Pro, Pixel 7a, Pixel Tablet, Pixel Fold, Pixel 8, Pixel 8 Pro, Pixel 8a, Pixel 9, Pixel 9 Pro, Pixel 9 Pro XL, Pixel 9 Pro Fold, Pixel 9a, Pixel 10, Pixel 10 Pro, Pixel 10 Pro XL, Pixel 10 Pro Fold, Pixel 10a, Pixel 11, Pixel 11 Pro, Pixel 11 Pro XL, and Pixel 11 Pro Fold.
Recent findings suggest that visit Settings > System > System update and click the “Check for update” button if the OTA hasn’t already appeared on your device. Android 17 QPR2 Beta consumers will get a small update to this final release.
The Android Beta Program will remain open and continue testing QPRs and feature drops.
Sources indicate that to get the stable version, those running the Android 17 QPR2 Beta have to opt out first. Devices will not be wiped by the stable OTA once that becomes widely available.
Sources indicate that FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
The Pixel is the smaller of two smartphones desi….
Editor-in-chief. Interested in the minutiae of Google and Alphabet. Tips/talk: abner@9to5g.com.
General
⚖️ Neutral
🌐 Sciencedaily
#11300. A tiny supercurrent could unlock quantum information without destroying it
📅 05 Nov 2026 • ⏱️ 12m • 📚 Deep Dive (2315 w)
A tiny supercurrent could unlock quantum information without destroying it
📅 05 Nov 2026 | ⏱️ 12 min read (2315 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~12 mins left to finish
📖 0% read
💡 Key Takeaways
- One of the biggest obstacles in quantum computing is surprisingly simple to describe: how do you read information without changing or destroying it?
- According to recent reports, researchers have now proposed a way to overcome much of this difficulty by using an unusual electrical signal produced by the qubit itself.
- The research, supported by FAPESP, was published in Physical Review B Letters.
One of the biggest obstacles in quantum computing is surprisingly simple to describe: how do you read information without changing or destroying it? Unlike the bits used in ordinary computers, quantum bits, or qubits, are extraordinarily sensitive to measurement. Trying to determine their state can cause that state to collapse, potentially erasing the very information scientists want to retrieve.
According to recent reports, researchers have now proposed a way to overcome much of this difficulty by using an unusual electrical signal produced by the qubit itself. Their approach focuses on a special type known as an "Andreev qubit," which can generate an oscillating electric supercurrent through its own quantum behavior. By monitoring this current, scientists may be able to determine the qubit's state without directly measuring it or significantly disturbing the information it contains.
The research, supported by FAPESP, was published in Physical Review B Letters. It was led by José Carlos Egues, a full professor at the São Carlos Institute of Physics at the University of São Paulo (IFSC-USP) in Brazil, and Yugui Yao of the School of Physics at the Beijing Institute of Technology in China. If experimentally confirmed, their method could simplify quantum computing by removing the need for extra qubits used in certain measurement techniques.
Why Measuring Quantum Information Is So Difficult.
It has been revealed that conventional computers store information in bits that have one of two values, 0 or 1. These values can be checked repeatedly without changing the information. Quantum computers work differently because their qubits can exist in superpositions, meaning they can combine the states 0 and 1 in ways that are not possible with conventional bits.
This unusual ability is central to the potential power of quantum computing. However, it also creates a major vulnerability. Quantum states can be disrupted by interactions with their surroundings, including the instruments scientists use to examine them.
Recent findings suggest that "In the conventional formulation of quantum mechanics, a projective measurement causes the system to assume one of the states associated with the measured quantity. Thus, if a qubit has been prepared in a certain superposition of 0 and 1, its direct measurement tends to destroy that superposition and, consequently, the information it contained," says Egues.
Industry observers note that to minimize this problem, physicists developed techniques known as "quantum nondemolition measurements," or QND. Many of these approaches use an additional quantum system called an ancilla. Rather than measuring the original qubit directly, researchers transfer information to the ancilla and measure that auxiliary system instead.
Industry observers note that the term "ancilla" comes from a Latin word meaning "slave" or "servant." In modern scientific usage, it describes something that performs a supporting function. Here, the ancilla acts as an intermediary, allowing researchers to obtain information while preserving the original qubit as much as possible.
Sources indicate that although effective, these procedures come with practical disadvantages. Scientists must prepare the auxiliary qubits, connect them to the qubits being studied, transfer information between them, and perform repeated measurements. These additional steps require time and equipment, and the complexity becomes increasingly significant as the number of qubits grows.
"Our strategy is different. Instead of transferring the information to an auxiliary qubit, we seek to obtain it from a signal produced by the qubit under study itself," says the researcher.
A Special Quantum Bit That Produces Its Own Signal.
According to recent reports, the proposed technique relies on the unusual properties of an Andreev qubit. Its name honors Soviet physicist Alexander Andreev (1939-2023), who identified a distinctive quantum process in 1964 that occurs where normal materials meet superconductors.
Superconductors are materials that can conduct electricity without electrical resistance under appropriate conditions. At the boundaries involving these materials, special quantum states known as "Andreev states" can form. In the system studied by the researchers, these states are confined to an extremely small region between two superconducting materials.
These quantum states can represent the basic values 0 and 1, along with superpositions of those values, making them suitable for storing quantum information.
"In the system under consideration, this region is a quantum dot - that is, a nanoscale structure in which electrons are spatially confined - formed in an indium arsenide [InAs] nanowire connected to superconducting materials on both sides. It's in this environment that the states characterizing the Andreev qubit are formed," Egues explains.
The key to the latest approach is an electrical phenomenon called a "supercurrent." Unlike the current flowing through ordinary electrical conductors, a supercurrent moves without resistance.
Sources indicate that the researchers found that when the Andreev qubit exists in a superposition, the supercurrent develops a component that oscillates over time. These fluctuations arise from quantum interference between the different states making up the superposition.
Crucially, the oscillations are not random. Their behavior contains information about the qubit's underlying quantum state, potentially allowing scientists to determine what that state is without directly measuring the qubit.
"It's precisely that property that we use to read the qubit. It's that supercurrent that lies at the heart of our proposal," the researcher points out.
How a Tiny Electrical Current Reveals Quantum Information.
To understand how the technique works, it helps to consider how physicists describe a qubit's state mathematically.
One common representation is the "Bloch sphere," a geometric model in which every possible pure state of a single qubit corresponds to a point on the surface of a sphere. Two angles determine the location of that point.
The first angle describes how much each of the two basic states contributes to the superposition. The second describes their relative phase, which specifies how the quantum components are aligned with one another. Together, these two measurements provide the information needed to identify the qubit's state.
According to the new research, both pieces of information can be extracted from the supercurrent. Its steady component and the size of its oscillations reveal the relative contributions of the two basic states. Meanwhile, the timing of the oscillations provides information about their phase relationship.
In a recent development, "Our study showed that this information is encoded in the supercurrent itself. The supercurrent has a constant component and a fluctuating component. The value of the constant component and the amplitude of the oscillation reveal the proportion of each state (0 and 1) in the superposition, and the moment when that oscillation begins reveals the phase relationship between them. Thus, by measuring how the current varies over time, it's possible to reconstruct the initial state of the qubit," Egues explains.
It has been revealed that this means the electrical current effectively carries a signature of the quantum information stored in the system. By observing how that signature changes over time, researchers could reconstruct the qubit's original state.
A Supercurrent That Oscillates Without Voltage.
Another surprising feature of the proposed system is that the electrical current can oscillate without an externally applied voltage.
Ordinarily, producing an oscillating supercurrent in this type of superconducting system requires a voltage. This familiar phenomenon is called the "AC Josephson effect.".
According to recent reports, the researchers predict something different in their Andreev qubit. Here, the current's oscillations arise naturally from the qubit's own quantum evolution. No outside voltage is required to generate them.
It has been revealed that "Our system generates a supercurrent that varies over time like an alternating current but without voltage. It's the very evolution of the qubit's state that produces that oscillation," says Egues.
Industry observers note that this behavior is notable because it transforms quantum activity occurring on an extraordinarily small scale into a detectable electrical signal. The current provides a connection between the microscopic world of quantum states and the larger physical systems scientists can measure.
That connection is what makes the proposed reading technique possible.
Detecting Quantum States With an Extremely Sensitive Sensor.
The researchers envision placing the Andreev qubit inside a closed superconducting circuit, allowing its supercurrent to circulate continuously.
Next to the circuit would sit a SQUID (superconducting quantum interference device), a highly sensitive instrument capable of detecting extremely weak magnetic fields.
Whenever an electric current flows, it produces a magnetic field. Because the supercurrent in this system oscillates, the magnetic field it generates also changes over time.
It has been revealed that the nearby SQUID could detect these tiny magnetic variations and use them to determine the behavior of the circulating current. Since the current contains information about the qubit's quantum state, the researchers could then reconstruct that state without measuring the qubit directly.
Egues compares the arrangement to two compasses that interact through a magnetic field.
"We can think of the qubit as one compass and the SQUID as another compass. The current in the circuit produces a magnetic field, and the SQUID 'senses' that field. Since the coupling between the two is very weak, the effect of the measuring instrument on the qubit tends to be very small.".
In a recent development, the weak interaction between the sensor and the qubit is especially important. It offers a way to gather information while minimizing the disturbance that normally accompanies quantum measurements.
Reading Quantum Information With Almost No Disturbance.
In quantum physics, observing a system is not necessarily a harmless process. A measuring instrument interacts with whatever it is attempting to measure, and that interaction can change the system's behavior.
This fundamental difficulty puzzled the earliest researchers studying quantum mechanics. It remains an unavoidable feature of quantum measurements today.
Industry observers note that the proposed technique does not eliminate this effect entirely. The SQUID still interacts with the circuit, creating a small amount of feedback that can influence the qubit. However, the team's simulations suggest that this disturbance can be reduced to a level so small that it becomes effectively negligible.
Recent findings suggest that "Our method doesn't eliminate the fundamental problem of quantum measurement. But it can approach the limit of a non-destructive readout and, at the same time, avoid the use of auxiliary qubits - the ancillas - employed in other non-destructive quantum measurement protocols," Egues notes.
Recent findings suggest that the approach could also remove another complication found in some existing techniques. Because researchers would not need to restore the qubit to its original state after every measurement, they could make repeated observations as the state changes.
This would allow scientists to follow the qubit's quantum evolution over time, rather than obtaining information only through separate measurement and reset cycles.
Simulations Achieve Up to 99.85% Accuracy.
To investigate whether the method could work outside ideal theoretical conditions, the researchers performed computer simulations designed to account for imperfections that would arise in real experiments.
Industry observers note that these calculations included measurement noise, as well as the small amount of feedback introduced by the detection coil. The goal was to determine whether the qubit's state could still be reconstructed accurately despite these disturbances.
In a recent development, the results were encouraging. Depending on the number of measurements used, the simulations produced accuracies of 99.52%, 99.81%, and 99.85%.
According to the researchers, these values fall within the standard thresholds used in quantum error correction schemes, which are designed to manage errors in quantum information processing.
The findings suggest that the method could provide highly accurate quantum state reconstruction without the additional complexity of auxiliary qubits.
However, the technique has not yet been demonstrated experimentally. The results come entirely from theoretical analysis and computer simulations, so researchers still need to establish whether a physical device can achieve comparable performance.
Could This Make Quantum Computers Simpler?
Despite the lack of experimental confirmation, the researchers emphasize that their proposal does not depend on technologies that have yet to be invented.
The calculations use realistic properties drawn from existing quantum systems, and SQUID sensors are already established tools for detecting exceptionally weak magnetic fields and electric currents.
What remains to be built is the specific arrangement of components required to implement the proposed measurement technique.
"All the numbers we used are realistic. In principle, this can be achieved. In fact, we used parameters from existing systems in our calculations. What doesn't yet exist is that geometry, that setup that we proposed," he argues.
Industry observers note that this makes the approach different from theoretical concepts that cannot be realized until scientists develop entirely fresh materials or manufacturing techniques. In principle, the necessary components already exist, although assembling them into the proposed configuration and demonstrating the predicted behavior remain vital challenges.
The research offers two potentially significant advances.
Sources indicate that from the standpoint of fundamental physics, it predicts that a qubit can produce an oscillating supercurrent resembling the AC Josephson effect, but without requiring an external voltage. Instead, the oscillations emerge from the qubit's own coherent quantum evolution.
Industry observers note that from a technological perspective, the study indicates how those oscillations could serve as a measurable signature of the qubit's internal state. By analyzing the electrical current, researchers could recover quantum information while causing very little disturbance to the system.
Industry observers note that if future experiments confirm these predictions, the method could make reading Andreev qubits substantially simpler. Eliminating auxiliary qubits and repeated resets could reduce the equipment and procedures needed to retrieve quantum information.
More fundamentally, the work points toward an intriguing possibility: information hidden in the microscopic quantum world may be accessible through an electrical current produced by the quantum system itself, offering a promising new way to observe delicate quantum states without destroying them.
Sources indicate that materials provided by Fundação de Amparo à Pesquisa do Estado de São Paulo. Original written by José Tadeu Arantes. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful New Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.
🔗 Related Articles
📰 #17350. Tiny flaws in diamonds could unlock a quantum computing revolution 📰 #11421. Industry News: World’s first superconducting quantum heat engine could help unlock massive quantum computers 📰 #23393. Tech Report: Nanogap architecture could help integrate quantum light sources onto chips
General
⚖️ Neutral
🌐 Fastcompany
#11299. Santa with a cause: Amazon Prime teams up with Arnold Schwarzenegger for its latest holiday campaign
📅 16 Nov 2026 • ⏱️ 9m • 📚 Deep Dive (1787 w)
Santa with a cause: Amazon Prime teams up with Arnold Schwarzenegger for its latest holiday campaign
📅 16 Nov 2026 | ⏱️ 9 min read (1787 words, 📚 Deep Dive) | Source: Fastcompany
⏱️ ~9 mins left to finish
📖 0% read
💡 Key Takeaways
- It has been revealed that after more than five decades in Hollywood, Arnold Schwarzenegger finally feels fit to play his most iconic role yet.
- Sources indicate that after more than five decades in Hollywood, Arnold Schwarzenegger finally feels fit to play his most iconic role yet.
- The Terminator and Total Recall actor is suiting up in bright red and white for Amazon Prime’s new holiday creative campaign, “Santa Schwarzenegger,” which debuts on Monday.
It has been revealed that after more than five decades in Hollywood, Arnold Schwarzenegger finally feels fit to play his most iconic role yet. And he’s taking the reins just in time for the holiday season. The Terminator and Total Recall actor is suiting up in bright red and white for Amazon Prime’s upcoming holiday creative campaign, “Santa Schwarzenegger,” which debuts on Monday. The advertising spot begins with Schwarzenegger looking a little forlorn as the paparazzi chase him around New York. He then orders a Santa suit from Prime, allowing for anonymity as Schwarzenegger donates snacks to a dog rescue center, watches a basketball game, and heaves a Christmas tree onto the roof of a car. “I’m at that age now and it’s believeable” Throughout his career, Schwarzenegger has played plenty of iconic roles. He’s portrayed a killing machine from the future, Batman’s nemesis Mr. Freeze, both Hercules and his father, Zeus, and an undercover cop teaching kindergarteners. But Schwarzenegger states no role he has ever played has been as worldwide as this one. [Photo: Amazon] “This is the perfect time for me to play Santa, because I’m at that age now and it’s more believable,” Schwarzenegger tells Fast Company. “With all the interesting characters that I played in my career—from Conan to Terminator—I thought that Santa is the ultimate.” For Amazon, the Schwarzenegger spot fits neatly into two goals: driving sales and attention to Prime, a core pillar of the online retail giant’s Black Friday, Cyber Monday, and other holiday sales events throughout the season. But it also ties in neatly with Amazon Prime’s The Man with the Bag, an upcoming holiday film that debuts on December 2, starring Schwarzenegger as Santa for a second time. Alan Ritchson, Awkwafina, and Ken Jeong are also featured in the film’s cast. The film also ties into Amazon’s 2026 holiday campaign, which is called “Joy Delivered.” “Arnold is the king of the kids, we saw that when he made Kindergarten Cop,” Jo Shoesmith, Amazon’s vice president and global chief brand officer, tells Fast Company. “There is a warmth and charm to him that lives outside of the character of Santa.” Santa “has to be in shape” “Santa Schwarzenegger” will run through December 23 across several channels including television, digital, social, and streaming audio. Yet another component of the campaign that Amazon is promoting is Schwarzenegger’s curated holiday gift guide, which includes plush dog toys, supplements, toys intended for children and grandchildren, and dumbbells. “Think about it, Santa has to fly all the way from the North Pole, he has to be in shape to hand out the gifts at every single continent to go to every single house,” says Schwarzenegger. “It is a lot of work. He has to be in shape.” [Photo: Amazon] There are also two books: Better Every Day, a self-help book penned by Schwarzenegger that’s due to be published in January, and Arnold, which is written about him. There’s also a cigar lighter, which may seem counterintuitive for the fitness enthusiast, but apparently he’s smoked them for over 40 years, including during his interview with Fast Company. “We never want to twist the arm of the personality to put something in their mouth that doesn’t come across as authentic,” says Shoesmith. “It’s very driven by his holiday ordering list.” As an Austrian, Schwarzenegger says his holiday traditions differed from how he raised his children in America. The holiday is celebrated on December 24 and the gift giver is a baby Jesus called Christkind, not Santa, though Schwarzenegger says the latter has become more popular there in recent years. “I always question with every script I get: is this something that would just be good for America, or just good for Europe, or is this something that can play in every continent,” says Schwarzenegger. Santa, he says, is a role that can “entertain the whole world.” [Photo: Amazon] The rise of star-powered Santas While Santa has been “the face” of the Christmas holiday for marketers for more than a century, the celebrity angle has been a more recent development. John Travolta has played the role in multiple ad spots for Capital One, while Jon Hamm did so for Fox Sports, Steve Carell for Comcast, and Brent Bailey for Target. “He’s kind of just this joyous, universally loved figure,” adds Shoesmith. To be clear, Shoesmith was talking about Schwarzenegger at this moment, not Santa, though she says both have cross-generational appeal. Schwarzenegger is also a safe casting choice for the retailer at a time when the American consumer isn’t optimistic. Unease about the economy was a central theme in the recent midterm elections, and the sales projection forecasts for the upcoming holiday season look fairly mixed. Research firm Circana says average holiday spending will total $779 this year, down from $796 in 2025. The trade association the National Retail Federation is more bullish, expecting retail sales in November and December to increase 4.2% to about $1 trillion, compared to a year ago. “We’re a brand whose logo is a smile, so joy is inherently part of who we are as a brand,” says Shoesmith of the tone approach for Amazon Prime’s campaign. “We really make sure that we have a great selection of brands at a really great price, and that’s really crucial for customers right now . . . they’re very price conscious.”.
Sources indicate that after more than five decades in Hollywood, Arnold Schwarzenegger finally feels fit to play his most iconic role yet. And he’s taking the reins just in time for the holiday season.
The Terminator and Total Recall actor is suiting up in bright red and white for Amazon Prime’s new holiday creative campaign, “Santa Schwarzenegger,” which debuts on Monday.
Industry observers note that the advertising spot begins with Schwarzenegger looking a little forlorn as the paparazzi chase him around Newly introduced York. He then orders a Santa suit from Prime, allowing for anonymity as Schwarzenegger donates snacks to a dog rescue center, watches a basketball game, and heaves a Christmas tree onto the roof of a car.
Throughout his career, Schwarzenegger has played plenty of iconic roles. He’s portrayed a killing machine from the future, Batman’s nemesis Mr. Freeze, both Hercules and his father, Zeus, and an undercover cop teaching kindergarteners.
But Schwarzenegger states no role he has ever played has been as worldwide as this one.
“This is the perfect time for me to play Santa, because I’m at that age now and it’s more believable,” Schwarzenegger tells Fast Company. “With all the interesting characters that I played in my career—from Conan to Terminator—I thought that Santa is the ultimate.”.
For Amazon, the Schwarzenegger spot fits neatly into two goals: driving sales and attention to Prime, a core pillar of the online retail giant’s Black Friday, Cyber Monday, and other holiday sales events throughout the season.
But it also ties in neatly with Amazon Prime’s The Man with the Bag, an upcoming holiday film that debuts on December 2, starring Schwarzenegger as Santa for a second time.
Recent findings suggest that alan Ritchson, Awkwafina, and Ken Jeong are also featured in the film’s cast. The film also ties into Amazon’s 2026 holiday campaign, which is called “Joy Delivered.”.
“Arnold is the king of the kids, we saw that when he made Kindergarten Cop,” Jo Shoesmith, Amazon’s vice president and global chief brand officer, tells Fast Organization. “There is a warmth and charm to him that lives outside of the character of Santa.”.
“Santa Schwarzenegger” will run through December 23 across several channels including television, digital, social, and streaming audio. Yet another component of the campaign that Amazon is promoting is Schwarzenegger’s curated holiday gift guide, which includes plush dog toys, supplements, toys intended for children and grandchildren, and dumbbells.
“Think about it, Santa has to fly all the way from the North Pole, he has to be in shape to hand out the gifts at every single continent to go to every single house,” claims Schwarzenegger. “It is a lot of work. He has to be in shape.”.
There are also two books: Better Every Day, a self-help book penned by Schwarzenegger that’s due to be published in January, and Arnold, which is written about him.
There’s also a cigar lighter, which may seem counterintuitive for the fitness enthusiast, but apparently he’s smoked them for over 40 years, including during his interview with Fast Tech giant.
In a recent development, “We never want to twist the arm of the personality to put something in their mouth that doesn’t come across as authentic,” notes Shoesmith. “It’s very driven by his holiday ordering list.”.
As an Austrian, Schwarzenegger states his holiday traditions differed from how he raised his children in America. The holiday is celebrated on December 24 and the gift giver is a baby Jesus called Christkind, not Santa, though Schwarzenegger says the latter has become more popular there in recent years.
“I always question with every script I get: is this something that would just be good for America, or just good for Europe, or is this something that can play in every continent,” says Schwarzenegger.
Santa, he says, is a role that can “entertain the whole world.”.
While Santa has been “the face” of the Christmas holiday for marketers for more than a century, the celebrity angle has been a more recent development.
John Travolta has played the role in multiple ad spots for Capital One, while Jon Hamm did so for Fox Sports, Steve Carell for Comcast, and Brent Bailey for Target.
“He’s kind of just this joyous, universally loved figure,” adds Shoesmith. To be clear, Shoesmith was talking about Schwarzenegger at this moment, not Santa, though she says both have cross-generational appeal.
In a recent development, schwarzenegger is also a safe casting choice for the retailer at a time when the American consumer isn’t optimistic. Unease about the economy was a central theme in the recent midterm elections, and the sales projection forecasts for the upcoming holiday season look fairly mixed.
Research firm Circana notes average holiday spending will total $779 this year, down from $796 in 2025. The trade association the National Retail Federation is more bullish, expecting retail sales in November and December to increase 4.2% to about $1 trillion, compared to a year ago.
Industry observers note that “We’re a brand whose logo is a smile, so joy is inherently part of who we are as a brand,” notes Shoesmith of the tone approach for Amazon Prime’s campaign. “We really make sure that we have a great selection of brands at a really great price, and that’s really important for customers right now . . . they’re very price conscious.”.

Gadgets
⚠️ Warning
🌐 9to5google
#11298. November Pixel Watch Drop: Create My Widget, Phone-to-Watch Unlock, and Wear OS 7.1
📅 10 Nov 2026 • ⏱️ 2m • 📖 Standard (391 w)
November Pixel Watch Drop: Create My Widget, Phone-to-Watch Unlock, and Wear OS 7.1
📅 10 Nov 2026 | ⏱️ 2 min read (391 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Besides a significant update for phones, there’s also a sizable Pixel Watch Drop today, but it’s mostly a preview of what’s to come.
- In a recent development, on the Pixel Watch 3 and newer (Wear OS 7+), step-by-step workouts are rolling out starting today.
- The other four features previewed today will be available in the next few weeks.
Besides a significant update for phones, there’s also a sizable Pixel Watch Drop today, but it’s mostly a preview of what’s to come.
In a recent development, on the Pixel Watch 3 and newer (Wear OS 7+), step-by-step workouts are rolling out starting today. In addition to instructions, you can log reps and weights, as well as track metrics. Make sure you’re on Google Health 4.12+ on your Pixel Watch and version 5.12+ on Android.
The other four features previewed today will be available in the next few weeks.
Phone-to-Watch unlock is such a welcome addition!
Recent findings suggest that as for "workouts on watch", that's something I was expecting when I first purchased the Pixel Watch 2 about 6 months ago. Since then I moved to PW3, and while I was super disappointed such a basic feature wasn't available (what's the point of all custom workouts on the phone app if they can't be run on the watch!?), I'm super glad that this feature they've announced at the release of Pixel Watch 5 is now being rolled out also to Pixel Watch 3 and 4!
With the Wear OS 7.1 update, the Pixel Watch 3 and newer will summarize “extensive” notification clusters and multi-message chats into overviews. This requires a paired Pixel 9 (excluding the A-Series) or newer.
Like on phones and Googlebooks, Create My Widget lets you create custom displays of information on the Pixel Watch 4 and newer.
Recent findings suggest that manual Call Screen is becoming Gemini Call Screen on the Pixel Watch 5. This “proactive, agentic feature” will filter incoming calls on demand and generate key details in US English.
The final feature lets your nearby phone unlock the Pixel Watch instead of having to manually enter the PIN or pattern on a small screen. After unlocking your phone, a prompt (“Unlocking your watch”) appears at the top of the screen with a button to “Cancel.” Your watch must be on your wrist to unlock. This will be available on the Pixel Watch 3 and newer, with UWB playing a role in the process.
It has been revealed that FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
It has been revealed that editor-in-chief. Interested in the minutiae of Google and Alphabet. Tips/talk: abner@9to5g.com.
🔗 Related Articles
📰 #11305. Tech Report: November 2026 Pixel Drop: Create My Widget, HiLight for Google Messages, Pixel 10 Rambler, & more 📰 #23452. Google beta lets you test ‘Create My Widget’ on Pixel 10 and 11 now 📰 #23646. Deals: Google Pixel Tag, Pixel Watch 5 $100 off, Googlebook from $680, Lenovo Yoga Mini $460 off, more
General
⚖️ Neutral
🌐 Tomshardware
#11297. This week in Tom's Hardware Premium: November 14, 2026
📅 14 Nov 2026 • ⏱️ 4m • 📚 Deep Dive (835 w)
This week in Tom's Hardware Premium: November 14, 2026
📅 14 Nov 2026 | ⏱️ 4 min read (835 words, 📚 Deep Dive) | Source: Tomshardware
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- Seismic appears to set the tone for this week's events in the hardware industry, and we've covered the biggest beats, including deeper dives on hardware and AI topics over on Tom's Hardware Premium.
- First up, it's not only hyperscalers and neoclouds that have their eyes on AI.
- DRAM capacity constraints have been an industry-wide sticking point as the AI buildout accelerates demand for dies.
Seismic appears to set the tone for this week's events in the hardware industry, and we've covered the biggest beats, including deeper dives on hardware and AI topics over on Tom's Hardware Premium. Stories this week are colored by the fact that Nvidia founder Jensen Huang has stepped away from his post as CEO. The ramifications are wide and far-reaching, as the company transformed from a gaming GPU manufacturer to an AI business over the past five years.
First up, it's not only hyperscalers and neoclouds that have their eyes on AI. An increasingly popular segment among enthusiasts is PCs dedicated to running local AI models. With so many choices on the market presently, from the recently released RTX Spark to AMD's Strix Halo platform, we take a look at two unlikely contenders that are now going head-to-head: Nvidia's DGX Spark and Apple's Mac Studio. We ran a suite of real-world and synthetic benchmarks across both devices and tested large models on both machines. With prices at eye-watering levels, it's more crucial than ever that you make the correct choice for your intended workloads.
DRAM capacity constraints have been an industry-wide sticking point as the AI buildout accelerates demand for dies. With costs spiraling across both client and enterprise hardware, AMD has shared further detail about MEXT, a predictive memory engine which aims to offer 99% of a server's performance while running on half the DRAM. Powered by a transformer model and clever use of flash storage, AMD is already running 145 servers with the system in place, with a view to expand that figure to 2,000 next year.
According to recent reports, next, we sat down with Cognichip's Chief Product Officer in an extensive interview to explore how the company is rolling out AI-powered chip design tools. Back in September, the company revealed a suite of proprietary AI models, named Artificial Chip Intelligence (ACI), which are specifically developed for semiconductor engineering. While the tools have yet to be used in a shipping product, it could substantially improve chip development productivity by automating labor-intensive tasks.
The Jensen Huang scandal deepens, as the now-former Nvidia CEO has become embroiled in a series of alleged extramarital affairs and has since resigned from Nvidia. While much of the past week's stories have centered on his relationship with alleged Chinese Spy Alice Huang, we explored the former CEO's unlikely relationship with Kang Wei, Ms. Huang's husband, who recently landed in hot water with China's Securities Regulatory Commission.
Nvidia-based compute remains difficult to find in China, especially as AI labs line up to order racks and newer cards like the RTX 5500 Pro, with over 6 million units reportedly ordered for the export-compliant GB202-based AI accelerator. But the Chinese AI labs that are chasing after Nvidia's tech may still have to pay a premium and ensure that they're running enough homegrown silicon to not fall afoul of Beijing's rules. We explore how some companies have now moved to renting compute in Southeast Asian countries like Malaysia and Singapore in an attempt to get around export controls.
Google's one of the biggest competitors to Nvidia, especially in the AI domain. The company's 8th-gen TPU lineup has now expanded even further, with two upcoming chips designed for long-context agentic AI and security. These two new chips, TPU 8i Max and TPU 8tx, signal a further diversification across Google's eighth-generation TPU stack. While TPU 8i Max doubles the specs of the original TPU 8i, TPU 8tx makes a more interesting change to AMD's EPYC to serve its use in specialized security workloads.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
Lastly, a upcoming proposed framework aims to track how easy it might be for an AI model to break through its safeguards and generate potentially harmful content. The Frontier Model Foundation has proposed a Jailbreak Rating Framework which aims to classify the type and severity of a possible LLM jailbreak. With four scoring components in hand, the foundation aims to identify possible jailbreak vectors and inform labs of them before they happen in the real world, with potentially disastrous consequences.
Don’t miss out on this Tom’s Hardware Premium. Get a full year of access for just $29, or from $7 per-month. Get daily news analysis, deep dives into specialist topics in the semiconductor industry, as well as access to Bench, the largest benchmarking database around.
According to recent reports, to read any of the articles we mention above, as well as unlock Bench, you'll need to purchase a Tom's Hardware Premium subscription. Your support goes a long way in helping us to publish deeper, more insightful articles that might not otherwise be covered.
Sayem Ahmed is the Subscription Editor at Tom's Hardware. He covers a broad range of deep dives into hardware, both new and old, including the CPUs, GPUs, and everything else that uses a semiconductor. He has worked as a professional tech journalist since 2015 and has written for Gamespot, IGN, and Dexerto.
🔗 Related Articles
📰 #23656. Unlock Tom's Hardware Premium's SuperComputer 2026 coverage for free — sign up for an account to read detailed reports from the show 📰 #19961. Your Horoscope for the Week of November 15 📰 #18172. Ethereum Mirrors Pre-SpaceX IPO Chart as Tom Lee Eyes November 18 Market Bottom
AI & Tech
⚖️ Neutral
🌐 Sitepoint
#11296. 5 Best AI Anime Video Generators in 2026, and Are AI Anime Videos Worth Making?
📅 11 Nov 2026 • ⏱️ 8m • 📚 Deep Dive (1654 w)
5 Best AI Anime Video Generators in 2026, and Are AI Anime Videos Worth Making?
📅 11 Nov 2026 | ⏱️ 8 min read (1654 words, 📚 Deep Dive) | Source: Sitepoint
⏱️ ~8 mins left to finish
📖 0% read
💡 Key Takeaways
- Stay up to date with AI tools, model releases, and developer workflows that matter.
- Industry observers note that 7 Day Free Trial.
- Recent findings suggest that AI video generators can now turn a prompt or a character image into a few seconds of animation, and anime is one of the most popular styles people ask for.
Stay up to date with AI tools, model releases, and developer workflows that matter.
Weekly. Free. One click to leave.
Industry observers note that 7 Day Free Trial. Cancel Anytime.
Recent findings suggest that AI video generators can now turn a prompt or a character image into a few seconds of animation, and anime is one of the most popular styles people ask for. But anime is also one of the hardest styles to get right: flat colors, thin linework and stylized motion expose the weaknesses of video models quickly. For developers and designers, the useful question is not which tool is “best”, but what each one actually offers, what it cannot do yet, and how to fit it into a real production workflow.
In a recent development, this article compares five generators on what their own pages state, covers the problems they all share, asks whether AI anime videos are worth making, and then explains how the models work and how designers and developers can build a practical workflow, including ffmpeg and API-integration examples. “Best” here depends on the job: the tools are listed in no ranking order, each is linked once to its official site for reference, and the comparison is based on public vendor pages reviewed in November 2026. Features, models and pricing change often, so verify current details before relying on any of them.
Sources indicate that we reviewed each vendor’s own site and compared what it states on the same points. This is a documentation-based comparison, not a lab benchmark. Where a page does not state something, we say so instead of guessing.
Sources indicate that AI anime video generator by Pollo AI sits within a general AI video platform. On its main site, Pollo describes generating video from text prompts or uploaded images and editing existing videos, such as adding, changing, removing or restyling content. It also offers AI image generation, so a character image and the animation can be made in one place.
Strengths for anime work: text-to-video and image-to-video in the same tool, plus video editing and restyling, which suits experimenting with looks.
In a recent development, limitations and gaps: the pages we could read do not name the underlying models, list credit amounts or pricing, or describe anime-specific controls such as reference characters or first and last frame inputs. You will need to test consistency yourself.
Fits: creators who want image, video and editing tools in one platform and are comfortable testing results before committing.
In a recent development, vidu lists text-to-video, image-to-video and reference-to-video modes. For image-to-video you can set first and last frames. Reference-to-video lets you upload several images of a character, object or scene, and saved references can be reused through a My References feature. The site highlights 2D animation and diverse artistic styles, mentions 1080p output and offers an API platform aimed at enterprise use.
Strengths for anime work: the clearest set of consistency tools among the five pages we reviewed, with first and last frames, multi-image references and reusable saved characters.
Limitations and gaps: the page does not specify clip durations beyond examples, detail its anime-specific templates, or list prices. Free credits are mentioned without an amount.
Fits: sequences built around a recurring character, and teams that want an API.
It has been revealed that kling AI presents Kling 4.0 for video, described as offering stable dynamic motion and an audio-visual experience, alongside an image model, a Motion Control tool and a node-based Canvas editor for working through scripts, storyboards, images and video. It also lists MCP and CLI support for batch generation and automated production, and an API platform with documentation.
Strengths for anime work: motion-focused tooling and a workflow environment for storyboards and multi-step production, plus automation options for developers.
Limitations and gaps: the page we reviewed does not detail image-to-video specifics, first and last frame controls, camera control, durations, video resolution or pricing, and it gives no anime-specific guidance.
Fits: teams that value motion control and scripted or batch pipelines.
It has been revealed that hailuo AI, from MiniMax, describes creating AI videos and images from text or photos. Its page shows a reference field and an Omni Reference option, a banner for a model that mentions multimodal generation and editing, and many photo-based templates such as photo-to-motion, transformation and style transfer.
Strengths for anime work: an accessible, template-driven way to animate a still image and try stylized effects quickly.
Limitations and gaps: the page does not explain how reference works, or state camera control, durations, resolution, API availability or pricing. Template-driven results may be harder to control precisely than prompt- and frame-driven workflows.
Fits: quick experiments and social clips made from a single image.
Dreamina describes itself as an all-in-one creative platform for images, videos and talking avatars. For video it lists text-to-video, image-to-video, sketch-to-video, cartoon video generation and reference-to-video, using several Seedance models, along with editing examples such as green-screen replacement. It also offers image generation and upscaling.
Strengths for anime work: a broad toolset, including cartoon-oriented generation, references and editing in one environment.
Limitations and gaps: no official maximum duration or video resolution is stated, and the page notes that displayed pricing is for reference only and that final pricing requires signing in. The breadth of features and models can make it harder to know which one to use for a given shot.
Fits: creators who want images, video and avatars under one roof.
In a recent development, “Not stated” means the vendor page we reviewed did not say, not that the feature does not exist. Treat the table as a checklist of questions to answer in your own tests.
Recent findings suggest that it depends on the job and on what you compare them with. Against a full studio production they are limited. Against having no animation at all, they change what a small team or solo creator can attempt.
It has been revealed that treat the generator as a fast prototyping and shot-making assistant, not a replacement for writing, direction and design. Audience reaction also varies, and some viewers are openly critical of AI-made work, so quality and disclosure both matter.
Most current generators are diffusion models extended to video. As in image diffusion, the model starts from random noise and removes it step by step, guided by your inputs. The extension to video, described in research such as Video Diffusion Models, is that the model denoises a whole sequence of frames together, so that motion and appearance stay coherent over time. Many systems work in a compressed latent space rather than on raw pixels to keep generation affordable.
Create an original character sheet with front, side and three-quarter views, a fixed color palette and a clear silhouette. Keep it simple: fewer fine details means less flicker.
Break the sequence into short shots with one action and one camera move each. A four-shot, twenty-second sequence is more realistic than one long generation.
Start each shot from a clean keyframe of your character. Where a tool supports first and last frames or reference images, use them to define the pose and keep identity stable.
Describe subject, action, camera and mood, and add a style anchor. For example: “The girl slowly turns toward the camera, wind moves her hair, petals drift past, gentle push-in, 2D cel shading, clean linework.”.
Recent findings suggest that scrub through each clip for warped hands, drifting faces and flickering lines. Discard or regenerate failures instead of hoping nobody notices.
Join the best takes, color-match them, add sound and captions, and add disclosure where a platform requires it.
According to recent reports, developers can make the pipeline repeatable. Two patterns help: scripted post-processing with ffmpeg, and a resilient job-based client for any generation API.
In a recent development, the script below extracts a last frame to seed the next shot, normalizes clips to a common size and frame rate so they can be joined, concatenates them, and optionally holds each frame twice for an “on twos” look. Adjust sizes and frame rates to your project.
Video generation is usually asynchronous: you submit a job, then poll or receive a callback. The sketch below reveals the pattern with a timeout and backoff. The endpoints and fields are placeholders, so follow your provider’s documentation for real ones.
Industry observers note that most are diffusion models for video. They start from noise and remove it step by step across a sequence of frames, guided by a text prompt and often a starting image or reference images, until coherent motion appears.
Industry observers note that usually, for consistency. The image locks the character and style, while the prompt only needs to describe motion.
Industry observers note that thin lines and flat color regions make small frame-to-frame changes visible. Simpler designs, slower motion and post-processing reduce it.
Partly. Reference images, saved characters and shared keyframes help, but you should still review every shot for drift.
In a recent development, for short clips, concept previews and storyboards, often yes. For long, dialogue-driven stories, not yet.
Industry observers note that it depends on the tool and plan. Read the current terms and make sure you have rights to any characters or assets you upload.
Run the same character image and prompt through each, then compare consistency, line stability, motion quality and cost per usable second.
Recent findings suggest that AI anime video generators are useful, but uneven. The five tools reviewed here differ in input modes, consistency tools, developer access and how much their own pages say, and none removes the core problems of consistency, flicker and limited acting. The practical approach is to test several tools on the same shots, keep your workflow tool-agnostic, design characters that are simple and consistent, and review every clip before it ships. Used that way, they are a capable prototyping and shot-making aid, not a substitute for design and direction.
7 Day Free Trial. Cancel Anytime.

General
⚖️ Neutral
🌐 Hugging Face
#11295. H Company's new Holo2 model takes the lead in UI Localization
📅 03 Feb 2026 • ⏱️ 1m • 📖 Standard (206 w)
H Company's new Holo2 model takes the lead in UI Localization
📅 03 Feb 2026 | ⏱️ 1 min read (206 words, 📖 Standard) | Source: Hugging Face
⏱️ ~1 mins left to finish
📖 0% read
💡 Key Takeaways
- Two months since releasing our first batch of Holo2 models, H Company is back with our largest UI localization model yet: Holo2-235B-A22B Preview.
- Available on Hugging Face, Holo2-235B-A22B Preview is a research release focused on UI element localization.
- It has been revealed that high-resolution 4K interfaces are challenging for localization models.
Two months since releasing our first batch of Holo2 models, H Company is back with our largest UI localization model yet: Holo2-235B-A22B Preview. This model achieves a newly introduced State-of-the-Art (SOTA) record of 78.5% on Screenspot-Pro and 79.0% on OSWorld G.
Available on Hugging Face, Holo2-235B-A22B Preview is a research release focused on UI element localization.
It has been revealed that high-resolution 4K interfaces are challenging for localization models. Small UI elements can be difficult to pinpoint on a large display. With agentic localization, however, Holo2 can iteratively refine its predictions, improving accuracy with each step and unlocking 10-20% relative gains across all Holo2 model sizes.
Holo2-235B-A22B's Performance on ScreenSpot-Pro.
According to recent reports, holo2-235B-A22B Preview reaches 70.6% accuracy on ScreenSpot-Pro in a single step. In agent mode, it achieves 78.5% within 3 steps, setting a new state-of-the-art on the most challenging GUI grounding benchmark.
It has been revealed that training Holo2 models at scale requires coordinating workloads across multiple cloud providers. H Organization uses SkyPilot as a unified interface for launching training jobs on our clusters with Kubernetes (k8s). By abstracting away infrastructure complexity, SkyPilot lets researchers focus on model development instead of managing k8s manifests or maintaining separate deployment scripts.
🔗 Related Articles
📰 #18914. Van Hollen’s Senate backers lie low as Schumer takes massive lead 📰 #17929. Nickey Kehoe’s Upcoming Collection With The Lacquer Company Takes Its Cues From Beloved Antiques 📰 #23678. Nvidia engineer leaves company over lack of transparency around Jensen Huang’s exit, details decision
AI & Tech
⚖️ Neutral
🌐 Fastcompany
#11294. What is the FAA’s SMART AI system? Officials are denying a link to the nationwide ground stop
📅 16 Nov 2026 • ⏱️ 11m • 📚 Deep Dive (2234 w)
What is the FAA’s SMART AI system? Officials are denying a link to the nationwide ground stop
📅 16 Nov 2026 | ⏱️ 11 min read (2234 words, 📚 Deep Dive) | Source: Fastcompany
⏱️ ~11 mins left to finish
📖 0% read
💡 Key Takeaways
- The airline ground stop that wreaked havoc on travel since Friday was not related to the FAA’s new, $875 million AI-powered system the agency is rolling out to help predict problems in the sky, according to government officials and the artificial intelligence firm behind the technology.But the timing of the ground stop, so close to the national rollout of the Federal Aviation Administration’s SMART system, has raised questions about what the system does, its benefits and risks compared with the existing human system and what guardrails there are to address potential problems.
- The airline ground stop that wreaked havoc on travel since Friday was not related to the FAA’s new, $875 million AI-powered system the agency is rolling out to help predict problems in the sky, according to government officials and the artificial intelligence company behind the technology.But the timing of the ground stop, so close to the national rollout of the Federal Aviation Administration’s SMART system, has raised questions about what the system does, its benefits and risks compared with the existing human system and what guardrails there are to address potential problems.
- It has been revealed that the SMART system is based in a single location near Washington where a team of experts analyzes flight schedules, weather forecasts and hundreds of other streams of data.
The airline ground stop that wreaked havoc on travel since Friday was not related to the FAA’s new, $875 million AI-powered system the agency is rolling out to help predict problems in the sky, according to government officials and the artificial intelligence firm behind the technology.But the timing of the ground stop, so close to the national rollout of the Federal Aviation Administration’s SMART system, has raised questions about what the system does, its benefits and risks compared with the existing human system and what guardrails there are to address potential problems. Officials say no connection to ground stop The SMART system is based in a single location near Washington where a team of experts analyzes flight schedules, weather forecasts and hundreds of other streams of data. Then that office sends recommendations to the FAA’s command center, which relays them to air traffic controllers across the country for consideration.Homeland Security Secretary Markwayne Mullin stated Friday there’s no indication the communications challenges that caused the ground stop are linked to the new computer system, and the top officials at the Transportation Department and FAA reiterated that Saturday.The startup that designed the system, Air Space Intelligence, or ASI, said the ground stop wasn’t caused by “the SMART system, any product of ASI or our integration with FAA and ATC.”But lawmakers and outside groups raised questions about the SMART system before Friday’s ground stop. Last month, House Democrats sent a letter to the U.S. Government Accountability Office requesting an audit of the new software, raising concerns about safety and guardrails.“Concerningly, the nation’s front line aviation safety workforce apparently had little to no input into SMART’s development and have received limited training and information during the current deployment process,” the Oct. 13 letter said. “The use of artificial intelligence within SMART has rightfully raised serious questions about its reliability and safety benefits, particularly on its potential to interfere with decision-making by experienced air traffic controllers or to hallucinate safety-critical information.”SMART, however, is not — at least not yet — set up for AI to be in charge of flight control. Rather, it is making recommendations to humans who do so. What is the SMART system? Transportation Secretary Sean Duffy and FAA Administrator Bryan Bedford unveiled the system in September, calling it a “cutting-edge tool that centralizes 200 data streams — including weather patterns, flight paths, traffic flow, and controller staffing metrics — into one platform.” SMART stands for Strategic Management of Airspace, Routes and Trajectories.The system’s AI-supported engine synthesizes the data systems and shows a “comprehensive visualization” of where planes are going, how much traffic the system can handle and where congestion or weather could cause problems, according to the announcement. The idea is for specialists to then use the platform to fix problems before they arise.The FAA claims that during the initial test of the system in the Washington area this fall, the system helped reroute 180 flights and saved an average of 10 minutes and 80 gallons of fuel per flight by diverting around weather or other issues. The agency said that one flight cut 42 minutes off its trip from Tampa, Florida, to Dallas thanks to the system’s recommendations.So SMART was expanded for use nationwide on Nov. 10 for the airspace of all 22 air traffic control centers. That was three days before the ground stop.According to a government fact sheet on the tool, SMART can predict where air traffic is headed and identify other routes before an area becomes too congested. The system can also help reopen restricted airspace faster and better manage airport arrivals.SMART is also supposed to help with weather-related issues faster.Currently, the FAA blocks off portions of airspace affected by weather as “large, rectangular boxes,” according to the fact sheet, which doesn’t reflect how weather actually looks, with quick-moving thunderstorms and storm systems that are “often irregular in shape, with narrow gaps or corridors that aircraft could safely fly through.”To help with this, SMART gives the FAA and airspace operators a “clearer picture of how weather will affect air traffic over time,” allowing air traffic controllers to plan around storms and use available airspace instead of unnecessarily shutting down large areas.No other country has a working AI air traffic tool like the SMART system, according to Michael McCormick, a former FAA airspace manager and an associate professor at Embry-Riddle Aeronautical University. Eurocontrol, the European air traffic authority, has a system in testing and several manufacturers are prototyping similar tools. Concerns around relying on AI While government officials and ASI, the company behind SMART, have stressed that its AI system is designed to assist humans and not run flight control, its deployment has raised concerns about relying on artificial intelligence when human lives are at stake, given that even the most advanced models are prone to hallucinations — when models fabricate false information and present it as fact.Mike O’Donnell, a former top FAA official who worked for the agency for 17 years and now does aviation safety consulting work, said the agency “has got to make sure that this is just a tool in the toolbox and not the actual machine that’s doing the work.”The FAA, he said, “cannot afford to be wrong on this.”“It’s good to use it with the proper guardrails and backstops to ensure that they’re not giving wrong information to controllers based on what (AI) has come up with,” O’Donnell said. “There’s got to be a way to verify and validate what it’s doing to make sure that it’s not the wrong information.”He cautioned against putting too much trust in AI “until we know for sure that it’s proven itself time and time again. And that’s going to take a while.”The AI system’s launch comes amid a longstanding shortage of air traffic controllers around the country. The National Air Traffic Controllers Association has been raising concerns about this for more than a decade, telling Congress in 2015 that the shortage was at a crisis level. It said then that the FAA had missed its hiring targets for five years in a row. The union represents about 14,000 controllers, roughly 3,000 of them trainees. That said, experts say no AI system can replace the human air traffic controllers who spend years training for this highly demanding and stressful job.In an October interview with NPR, ASI co-founder and CEO Phillip Buckendorf said the SMART tool is designed for traffic managers who manage the entire U.S. airspace.“The AI does the math, the AI does the computation,” Buckendorf told NPR, but it’s ultimately up to the human operator whether to take the system’s recommendation. “They make the decision, they are the decider, they are the judge.” —Barbara Ortutay and Josh Funk, Associated Press.
The airline ground stop that wreaked havoc on travel since Friday was not related to the FAA’s new, $875 million AI-powered system the agency is rolling out to help predict problems in the sky, according to government officials and the artificial intelligence company behind the technology.But the timing of the ground stop, so close to the national rollout of the Federal Aviation Administration’s SMART system, has raised questions about what the system does, its benefits and risks compared with the existing human system and what guardrails there are to address potential problems.
It has been revealed that the SMART system is based in a single location near Washington where a team of experts analyzes flight schedules, weather forecasts and hundreds of other streams of data. Then that office sends recommendations to the FAA’s command center, which relays them to air traffic controllers across the country for consideration.Homeland Security Secretary Markwayne Mullin mentioned Friday there’s no indication the communications challenges that caused the ground stop are linked to the latest computer system, and the top officials at the Transportation Department and FAA reiterated that Saturday.The startup that designed the system, Air Space Intelligence, or ASI, said the ground stop wasn’t caused by “the SMART system, any product of ASI or our integration with FAA and ATC.”But lawmakers and outside groups raised questions about the SMART system before Friday’s ground stop. Last month, House Democrats sent a letter to the U.S. Government Accountability Office requesting an audit of the new software, raising concerns about safety and guardrails.“Concerningly, the nation’s front line aviation safety workforce apparently had little to no input into SMART’s development and have received limited training and information during the current deployment process,” the Oct. 13 letter said. “The use of artificial intelligence within SMART has rightfully raised serious questions about its reliability and safety benefits, particularly on its potential to interfere with decision-making by experienced air traffic controllers or to hallucinate safety-critical information.”SMART, however, is not — at least not yet — set up for AI to be in charge of flight control. Rather, it is making recommendations to humans who do so.
It has been revealed that transportation Secretary Sean Duffy and FAA Administrator Bryan Bedford unveiled the system in September, calling it a “cutting-edge tool that centralizes 200 data streams — including weather patterns, flight paths, traffic flow, and controller staffing metrics — into one platform.” SMART stands for Strategic Management of Airspace, Routes and Trajectories.The system’s AI-supported engine synthesizes the data systems and indicates a “comprehensive visualization” of where planes are going, how much traffic the system can handle and where congestion or weather could cause problems, according to the announcement. The idea is for specialists to then use the platform to fix problems before they arise.The FAA says that during the initial test of the system in the Washington area this fall, the system helped reroute 180 flights and saved an average of 10 minutes and 80 gallons of fuel per flight by diverting around weather or other issues. The agency said that one flight cut 42 minutes off its trip from Tampa, Florida, to Dallas thanks to the system’s recommendations.So SMART was expanded for use nationwide on Nov. 10 for the airspace of all 22 air traffic control centers. That was three days before the ground stop.According to a government fact sheet on the tool, SMART can predict where air traffic is headed and identify other routes before an area becomes too congested. The system can also help reopen restricted airspace faster and better manage airport arrivals.SMART is also supposed to help with weather-related issues faster.At the moment, the FAA blocks off portions of airspace affected by weather as “large, rectangular boxes,” according to the fact sheet, which doesn’t reflect how weather actually looks, with quick-moving thunderstorms and storm systems that are “often irregular in shape, with narrow gaps or corridors that aircraft could safely fly through.”To help with this, SMART gives the FAA and airspace operators a “clearer picture of how weather will affect air traffic over time,” allowing air traffic controllers to proposal around storms and use available airspace instead of unnecessarily shutting down large areas.No other country has a working AI air traffic tool like the SMART system, according to Michael McCormick, a former FAA airspace manager and an associate professor at Embry-Riddle Aeronautical University. Eurocontrol, the European air traffic authority, has a system in testing and several manufacturers are prototyping similar tools.
Recent findings suggest that while government officials and ASI, the tech giant behind SMART, have stressed that its AI system is designed to assist humans and not run flight control, its deployment has raised concerns about relying on artificial intelligence when human lives are at stake, given that even the most advanced models are prone to hallucinations — when models fabricate false information and present it as fact.Mike O’Donnell, a former top FAA official who worked for the agency for 17 years and now does aviation safety consulting work, stated the agency “has got to make sure that this is just a tool in the toolbox and not the actual machine that’s doing the work.”The FAA, he said, “cannot afford to be wrong on this.”“It’s good to use it with the proper guardrails and backstops to ensure that they’re not giving wrong information to controllers based on what (AI) has come up with,” O’Donnell said. “There’s got to be a way to verify and validate what it’s doing to make sure that it’s not the wrong information.”He cautioned against putting too much trust in AI “until we know for sure that it’s proven itself time and time again. And that’s going to take a while.”The AI system’s launch comes amid a longstanding shortage of air traffic controllers around the country. The National Air Traffic Controllers Association has been raising concerns about this for more than a decade, telling Congress in 2015 that the shortage was at a crisis level. It said then that the FAA had missed its hiring targets for five years in a row. The union represents about 14,000 controllers, roughly 3,000 of them trainees. That said, experts say no AI system can replace the human air traffic controllers who spend years training for this highly demanding and stressful job.In an October interview with NPR, ASI co-founder and CEO Phillip Buckendorf said the SMART tool is designed for traffic managers who manage the entire U.S. airspace.“The AI does the math, the AI does the computation,” Buckendorf told NPR, but it’s ultimately up to the human operator whether to take the system’s recommendation. “They make the decision, they are the decider, they are the judge.”.
—Barbara Ortutay and Josh Funk, Associated Press.

Gadgets
📈 Bullish
🌐 9to5toys
#11293. Today’s Android app deals and freebies: Undead Slayer, Level Come Again, Children of Morta, more
📅 10 Nov 2026 • ⏱️ 3m • 📚 Deep Dive (604 w)
Today’s Android app deals and freebies: Undead Slayer, Level Come Again, Children of Morta, more
📅 10 Nov 2026 | ⏱️ 3 min read (604 words, 📚 Deep Dive) | Source: 9to5toys
⏱️ ~3 mins left to finish
📖 0% read
💡 Key Takeaways
- Amazon has now rolled out its official giant early Black Friday sale, the all-time low on the Google Home Speaker is still flying, and today’s best Google Play app and game deals are ready, including Undead Slayer: Offline Premium, Level Come Again: Troll Game, Children of Morta, Old Man’s Journey, ELOH, Caravan SandWitch, Broken Sword: Reforged, Inua – A Story in Ice and Time, and more.
- You can score the most affordable new Galaxy Tab S12 Ultra at over $330 off today.
- Google Home Speaker hits all-time low in early Black Friday sale at 20% off, more Nest smart home deals.
Amazon has now rolled out its official giant early Black Friday sale, the all-time low on the Google Home Speaker is still flying, and today’s best Google Play app and game deals are ready, including Undead Slayer: Offline Premium, Level Come Again: Troll Game, Children of Morta, Old Man’s Journey, ELOH, Caravan SandWitch, Broken Sword: Reforged, Inua – A Story in Ice and Time, and more. Just be sure to scope out the latest Galaxy Tab S12 Ultra at over $330 off, the all-time low on the new Fire TV Stick 4K at $25, and your first chance to save on Dell’s new touchscreen XPS Googlebook at nearly $300 off. The apps await below.
You can score the most affordable new Galaxy Tab S12 Ultra at over $330 off today.
Google Home Speaker hits all-time low in early Black Friday sale at 20% off, more Nest smart home deals.
Amazon’s early Black Friday all-time low on newly introduced Fire TV Stick 4K at $25 might end tonight (58% off).
Level Come Again : Troll GameFREE (Reg. $0.50).
Industry observers note that fishwick & Co. – Bargain Sim$0.50 (Reg. $1.50).
It has been revealed that rayadillo Mobile PH$3 (Reg. $7).
Sources indicate that undead Slayer: Offline PremiumFREE (Reg. $1).
In a recent development, broken Sword: Reforged$6 (Reg. $10).
According to recent reports, children of Morta$2 (Reg. $6.50).
It has been revealed that old Man’s Journey$1 (Reg. $2.50).
According to recent reports, inua – A Story in Ice and Time$2 (Reg. $4).
Trial of the Demon Hunter$3 (Reg. $4).
Caravan SandWitch$5.50 (Reg. $8).
Industry observers note that final Weapon Grow – Idle RPGFREE (Reg. $1).
Norma – Icon Pack$0.25 (Reg. $1.50).
Recent findings suggest that final Castle Defence:Idle RPGFREE (Reg. $1).
KINGDOM: RISE OF LORDS$1 (Reg. $2.25).
In a recent development, hero of the Kingdom II$1.25 (Reg. $9).
It has been revealed that reporter – Scary Horror Game$0.25 (Reg. $1).
Comics – Cartoon Icon Pack$0.50 (Reg. $1.50).
Takoizu Cyan – Icon PackFREE (Reg. $1).
According to recent reports, liquid Walls: Live WallpaperFREE (Reg. $0.75).
All-latest Samsung Galaxy SmartTag 3 UWB tracker now available for purchase from $25 each.
In a recent development, farm Life RPG: Golden FieldsFREE (Reg. $7).
MonsterNova: Team Builder$1 (Reg. $5).
Recent findings suggest that european Truck Simulator$0.25 (Reg. $2.50).
Recent findings suggest that [VIP] Mr. Balcan IdleFREE (Reg. $10).
In a recent development, path to Mnemosyne$1 (Reg. $4.50).
Midori Green – Icon PackFREE (Reg. $1).
It has been revealed that himawari Yellow – Icon PackFREE (Reg. $1).
Sources indicate that endurance: dead space Premium$0.25 (Reg. $2.50).
Twilight Struggle$2.50 (Reg. $10).
Some of the first deals on fresh Google Fitbit Edge now live from $126 (Best Buy open-box).
Samsung Black Friday deal: Galaxy Z Fold 8 now $300 off w/ FREE set of newly introduced Galaxy Buds On ($530 off).
It has been revealed that deadhand Protocol: Card RPG$0.25 (Reg. $1.50).
Paws Against the World Premium$1 (Reg. $4).
In a recent development, minabo: A walk through life$1 (Reg. $4.50).
It has been revealed that pixel Knights VIPFREE (Reg. $0.50).
Pirates Fury: Stealth ActionFREE (Reg. $2.75).
It has been revealed that horror Apartment-Scary GameFREE (Reg. $3).
Last Wolf of Pine ForestFREE (Reg. $4).
Sources indicate that no More Slimes: Idle Action$6 (Reg. $10).
According to recent reports, FTC: We use income earning auto affiliate links. More.
Industry observers note that justin is a senior deal Jedi over at 9to5Toys where he heads up our game/app coverage and more. He also covers all things music for 9to5Mac, including the weekly Logic Pros series exploring music production on Mac and iOS devices.
🔗 Related Articles
📰 #23553. Industry News: Today’s Android app deals and freebies: Agent A, Swim Out, The Mutiny, more 📰 #23623. Industry News: Mid-week Android app deals and freebies: Wind Peaks, Box Head, 9th Dawn, more 📰 #23446. Monday’s Android app deals and freebies: Final Fantasy games, Dragon Quest, Ash of Gods, more
General
⚖️ Neutral
🌐 Sciencedaily
#11292. Inside this quantum computer, memory vibrates like a guitar string
📅 12 Nov 2026 • ⏱️ 6m • 📚 Deep Dive (1146 w)
Inside this quantum computer, memory vibrates like a guitar string
📅 12 Nov 2026 | ⏱️ 6 min read (1146 words, 📚 Deep Dive) | Source: Sciencedaily
⏱️ ~6 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that A quantum computer might seem to have little in common with a guitar, but researchers at ETH Zurich have found a surprising connection.
- Industry observers note that unlike the sounds produced by a musical instrument, these vibrations occur at frequencies far beyond human hearing.
- Sources indicate that by harnessing these vibrations, the researchers have created a way for quantum computers to process information efficiently while accessing a flexible working memory.
Sources indicate that A quantum computer might seem to have little in common with a guitar, but researchers at ETH Zurich have found a surprising connection. Physicist Yiwen Chu and her team have developed a system that uses microscopic mechanical vibrations to store and manipulate quantum information, much like the vibrating strings of a guitar produce musical notes.
Industry observers note that unlike the sounds produced by a musical instrument, these vibrations occur at frequencies far beyond human hearing. They take place within a tiny quantum chip, where they serve as a latest form of computer memory.
Sources indicate that by harnessing these vibrations, the researchers have created a way for quantum computers to process information efficiently while accessing a flexible working memory. "The interaction between the quantum processor and the quantum memory provides a crucial foundation with a view to establishing quantum computers as a powerful and reliable way to perform computations that are not feasible with conventional computers," says Yiwen Chu.
The breakthrough, described in the journal Science, introduces a different approach to quantum computer design. Instead of closely integrating information processing and storage, as many existing systems do, Chu's team has developed an architecture that gives these functions more distinct roles.
Quantum Memory Inspired by Conventional Computers.
In a recent development, the researchers drew inspiration from the basic design of everyday digital computers. In a conventional machine, the central processing unit (CPU) carries out calculations while information is held separately in working memory, commonly called random access memory (RAM). The arrangement of these components plays an crucial role in determining how efficiently a computer operates.
In a recent development, chu's quantum system follows a similar principle. A superconducting qubit acts as the processing and control unit, performing a role comparable to that of the central processing unit (CPU). Meanwhile, a separate quantum memory temporarily holds the information needed during calculations, allowing the processor to retrieve and modify it as necessary.
The major difference lies in how that information is stored.
"In our quantum working memory, however, information is not stored electromagnetically -- as is usually the case today -- but rather in the form of mechanical vibrations," explains Chu.
Industry observers note that quantum computers take advantage of unusual properties of quantum physics, including superposition, which allows quantum systems to exist in combinations of different states, and entanglement, which creates powerful connections between quantum states. These effects could eventually enable quantum machines to tackle certain extremely complicated calculations much faster than conventional computers, including some problems that are currently beyond their practical capabilities.
Why Vibrating Quantum Memory Could Be Better.
It has been revealed that one of the greatest challenges in quantum computing is maintaining precise control over quantum information. The states used for calculations are delicate, and even small disturbances can cause information to be lost. To perform calculations reliably, the processor and memory must interact closely enough to transfer and manipulate quantum states with high precision.
It has been revealed that in the new system, microscopic structures called mechanical resonators hold information in particular patterns of vibration. When the superconducting qubit needs that information, it accesses the stored vibrational state, performs the required operation, and returns the modified information to memory.
In a recent development, many existing quantum computers instead use electromagnetic memory alongside superconducting qubits. Researchers understand these technologies well, and they can be combined to provide extremely accurate control over quantum states, including reading, changing, and manipulating stored information.
However, electromagnetic memory systems have a significant disadvantage. They can occupy considerable space, making it difficult to expand experimental quantum devices into the larger, more capable computers that researchers and industries ultimately need.
Mechanical resonators offer several potential advantages. They are substantially smaller, allowing more compact designs. They can also support numerous different patterns of vibration, providing opportunities to store more information simultaneously than conventional electromagnetic memory.
Another important benefit is that mechanical vibrations can preserve quantum states for longer periods before the stored information begins to fade. Longer storage times could make it easier to carry out complicated calculations that require information to remain available throughout multiple processing steps.
Fresh Quantum Computer Passes Major Tests.
The research published in Science provides the first experimental demonstration that mechanical resonators can work together with superconducting qubits to carry out quantum computations. The results establish that vibration-based memory is a feasible alternative to electromagnetic storage.
It has been revealed that the achievement goes beyond simply storing information. Chu's team demonstrated that its architecture can handle both relatively straightforward calculations and more demanding quantum operations.
According to recent reports, to evaluate the system, the researchers tested two important computational techniques: the quantum Fourier transform and period finding. Both are fundamental tools in quantum computing and require a computer to coordinate multiple quantum states with considerable precision.
According to recent reports, "The Quantum Fourier Transform is a fundamental computational procedure required for many quantum algorithms. The period-finding algorithm we implemented served as a demonstration of how this procedure can be used," explains Igor Kladaric, doctoral student in Chu's team and co-author of the publication.
Successfully completing these tasks requires the system to store, control, and maintain coherent relationships among multiple quantum states at the same time. The experiments showed that the fresh architecture can meet these requirements, providing strong evidence that it can support genuine quantum computation rather than simply function as a memory device.
A Promising Step Toward Powerful Quantum Computers.
In a recent development, one of the most significant findings is that the new system can, in principle, carry out all the fundamental operations needed for arbitrary quantum computations. This means the architecture has the essential capabilities required for a programmable, general-purpose quantum computer.
Industry observers note that however, demonstrating those capabilities in an experimental chip is only the beginning. The next major challenge is scaling the technology to larger systems with greater processing power while preserving the precision and reliability demonstrated in the laboratory.
It has been revealed that chu and her colleagues are continuing to investigate how their approach can be developed further. Its long-term success will depend on whether mechanical quantum memory can remain effective as more components and increasingly complex computations are added.
Recent findings suggest that practical quantum computers powerful enough for widespread scientific and industrial applications are still some distance away. Nevertheless, by showing that tiny mechanical vibrations can serve as compact, capable quantum memory, the ETH Zurich team has demonstrated a promising fresh route toward making those machines a reality.
Materials provided by ETH Zurich. Note: Content may be edited for style and length.
Scientists Just Challenged a 50-Year-Old Theory About How Evolution Work.
âA Magnetar Is Bornâ: Supercomputer Simulates One of the Universeâs Most Violent Collisions.
Powerful Latest Weight-Loss Drug Could Change How Millions Treat Painful Knee Arthritis.
A 3-Million-Year-Old Fossil Is Turning the Story of Human Evolution Upside Down.

General
⚖️ Neutral
🌐 Hugging Face
#11291. Community Evals: Because we're done trusting black-box leaderboards over the community
📅 04 Feb 2026 • ⏱️ 4m • 📚 Deep Dive (848 w)
Community Evals: Because we're done trusting black-box leaderboards over the community
📅 04 Feb 2026 | ⏱️ 4 min read (848 words, 📚 Deep Dive) | Source: Hugging Face
⏱️ ~4 mins left to finish
📖 0% read
💡 Key Takeaways
- In a recent development, TL;DR: Benchmark datasets on Hugging Face can now host leaderboards.
- Let's be real about where we are with evals in 2026.
- Furthermore, there is another gap within reported benchmark scores.
In a recent development, TL;DR: Benchmark datasets on Hugging Face can now host leaderboards. Models store their own eval scores. Everything links together. The community can submit results via PR. Verified badges prove that the results can be reproduced.
Let's be real about where we are with evals in 2026. MMLU is saturated above 91%. GSM8K hit 94%+. HumanEval is conquered. Yet some models that ace benchmarks still can't reliably browse the web, write production code, or handle multi-step tasks without hallucinating, based on usage reports. There is a clear gap between benchmark scores and real-world performance.
Furthermore, there is another gap within reported benchmark scores. Multiple sources report different results. From Model Cards, to papers, to evaluation platforms, there is no alignment in reported scores. The result is that the community lacks a single source of truth.
Decentralized and transparent evaluation reporting.
In a recent development, we are going to take evaluations on the Hugging Face Hub in a newly introduced direction by decentralizing reporting and allowing the entire community to openly report scores for benchmarks. At first, we will start with a shortlist of 4 benchmarks and over time we’ll expand to the most relevant benchmarks.
For Benchmarks: Dataset repos can now register as benchmarks (MMLU-Pro, GPQA, HLE are already live). They automatically aggregate reported results from across the Hub and display leaderboards in the dataset card. The benchmark defines the eval spec via eval.yaml, based on the Inspect AI format, so anyone can reproduce it. The reported results need to align with the task definition.
According to recent reports, for Models: Eval scores live in .eval_results/*.yaml in the model repo. They appear on the model card and are fed into benchmark datasets. Both the model author’s results and open pull requests for results will be aggregated. Model authors will be able to close score PR and hide results.
Industry observers note that for the Community: Any user can submit evaluation results for any model via a PR. Results get shown as "community", without waiting for model authors to merge or close. The community can link to sources like a paper, Model Card, third-party evaluation platform, or inspect eval logs. The community can discuss scores like any PR. Since the Hub is Git based, there is a history of when evals were added, when changes were made, etc. The sources look like below.
To learn more about evaluation results, check out the docs.
It has been revealed that decentralizing evaluation will expose scores that already exist across the community in sources like model cards and papers. By exposing these scores, the community can build on top of them to aggregate, track, and understand scores across the field. Also, all scores will be exposed via Hub APIs, making it easy to aggregate and build curated leaderboards, dashboards, etc.
Community evals do not replace benchmarks so leaderboards and closed evals with published results are still crucial. However, we believe it's vital to contribute to the field with open eval results based on reproducible eval specs.
In a recent development, this won't solve benchmark saturation or close the benchmark-reality gap. Nor will it stop training on test sets. But it makes the game visible by exposing what is evaluated, how, when, and by whom.
It has been revealed that mostly, we hope to make the Hub an active place to build and share reproducible benchmarks. Particularly focusing on new tasks and domains that challenge SOTA models more.
Read the docs: To learn more about evaluation results, check out the docs.
Add eval results: Publish the evals you conducted as YAML files in .eval_results/ on any model repo.
Check out the scores on the benchmark dataset.
Register a upcoming benchmark: Add eval.yaml to your dataset repo and contact us to be included in the shortlist.
Recent findings suggest that the feature is in beta. We're building in the open. Feedback welcome.
Great initiative, aggregating multiple signals is the way to go!
Although such a measure has not solved the problems encountered in the current evaluation, at least it is indeed a very good measure in terms of decentralization and mobilizing the power of the community for co-construction.
Will there be the integration with existing huggingface lighteval?
It has been revealed that hi @naufalso ! Lighteval now suport inspect-ai as a backend, so everything supported by inspect is integrrated in lighteval 🔥.
It has been revealed that this is a very important and timely initiative. It’s easy to get lost in the sea of leaderboards, each with its own format and reporting style. The Inspect AI log format brings much‑needed standardization, and having Hugging Face host evaluation logs is a real game changer. One reason many valuable benchmarks fade away is that original contributors often lack the resources to continuously maintain leaderboards. The Community Evals initiative has tremendous potential to address this gap, and I truly appreciate the effort behind it.
We’re hoping to include our planning benchmark, ACPBench, as part of this ecosystem—it's fully compatible with Inspect AI, the evaluation scripts are available on our GitHub.
🔗 Related Articles
📰 #23075. Black Hat India 2026 Makes a Landmark Debut in Bengaluru, Bringing the Global Cybersecurity Community to India 📰 #16160. Latest Update: Old Christmas tree looking tired? Get a box fresh one in time for the holidays — 11 best QVC Black Friday tree deals from just $41 📰 #13647. This AI ‘mechanic’ can peer inside the black box of other neural networks
Gadgets
⚠️ Warning
🌐 Tomshardware
#11290. Latest Update: Samsung's 1TB 990 SSD drops to 19 cents per GB amid the memory crisis
📅 14 Nov 2026 • ⏱️ 2m • 📖 Standard (452 w)
Latest Update: Samsung's 1TB 990 SSD drops to 19 cents per GB amid the memory crisis
📅 14 Nov 2026 | ⏱️ 2 min read (452 words, 📖 Standard) | Source: Tomshardware
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Sources indicate that getting your hands on fast NVMe storage for your PC or laptop has become extremely challenging.
- The Samsung 990 is a PCIe 4.0 NVMe SSD that uses Samsung's latest V9 QLC NAND flash memory and a DRAM-less controller.
- Samsung's 990 is rated for read speeds of up to 7,150 MB/s and write speeds of up to 6,450 MB/s, offering plenty of bandwidth for modern games, large files, and everyday applications.
Sources indicate that getting your hands on fast NVMe storage for your PC or laptop has become extremely challenging. That remarked, the Samsung 990 SSD is currently available at a discounted price of $189.99, against its original list price of $229.99 on Amazon. Although the $40 saving might not seem that impressive, deals on high-performance internal SSDs are becoming harder to come by amid the ongoing NAND and DRAM crisis. If you've been holding off on a storage upgrade, this could be a good opportunity to pick up a reliable, high-speed SSD.
The Samsung 990 is a PCIe 4.0 NVMe SSD that uses Samsung's latest V9 QLC NAND flash memory and a DRAM-less controller. It was introduced earlier this year with MSRPs of $269.99 for the 1TB model and $529.99 for the 2TB model. The 1TB model offers sequential read and write speeds of up to 7,150 MB/s and 6,450 MB/s, making it an excellent option for everyday computing, gaming, and handling large files. Samsung rates the drive for up to 400TB of written data, although it offers just three years of warranty. It features a single-sided M.2 2280 design, which should make it compatible with a wide range of desktop motherboards, laptops, and even mini-PCs.
Samsung's 990 is rated for read speeds of up to 7,150 MB/s and write speeds of up to 6,450 MB/s, offering plenty of bandwidth for modern games, large files, and everyday applications.
In our testing of the 2TB variant, we found that the Samsung 990 delivers reasonably good all-around performance, particularly for gaming and everyday applications. It offered similar performance to the Samsung 990 EVO Plus in some tests. However, it fell behind competing drives such as the Crucial P310 and WD Blue SN5100 in others, particularly during file transfers. One of its biggest advantages is its large write cache, which allows it to maintain speeds of nearly 6,100 MB/s for more than 57 seconds before performance drops once the cache is exhausted. Its power efficiency may not be the best, but overall it is a competent budget PCIe 4.0 SSD.
For anyone upgrading from an older SATA SSD or a traditional hard drive, the Samsung 990 should offer a noticeable improvement in boot times, application loading, and overall system responsiveness. At its current price of $189.99, it is also a suitable option for expanding game storage without spending a fortune.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
It has been revealed that kunal Khullar is a contributing writer at Tom’s Hardware. He is a long time technology journalist and reviewer specializing in PC components and peripherals, and welcomes any and every question around building a PC.
🔗 Related Articles
📰 #16715. Breaking: Judge denies motion to dismiss lawsuit accusing Samsung, SK Hynix and Micron of worsening RAM crisis by fixing memory prices and supply 📰 #18488. MSCI Drops Saylor's Strategy From Its Index Amid BTC Sell-Off 📰 #16083. Private Internet Access drops surprise $1.89-per-month VPN deal weeks before Black Friday
Business & Policy
⚖️ Neutral
🌐 Fastcompany
#11289. Trump’s tariffs will be tough to defeat, despite Democrats’ landslide in the midterms. Here’s why
📅 16 Nov 2026 • ⏱️ 12m • 📚 Deep Dive (2395 w)
Trump’s tariffs will be tough to defeat, despite Democrats’ landslide in the midterms. Here’s why
📅 16 Nov 2026 | ⏱️ 12 min read (2395 words, 📚 Deep Dive) | Source: Fastcompany
⏱️ ~12 mins left to finish
📖 0% read
💡 Key Takeaways
- Industry observers note that for months, Democrats on the campaign trail hammered President Donald Trump’s unpopular tariffs, arguing that the taxes on imports drive up prices for American families already frustrated by the high cost of living.James Talarico, a Democrat running for a U.S.
- For months, Democrats on the campaign trail hammered President Donald Trump’s unpopular tariffs, arguing that the taxes on imports drive up prices for American families already frustrated by the high cost of living.James Talarico, a Democrat running for a U.S.
- Recent findings suggest that the U.S.
Industry observers note that for months, Democrats on the campaign trail hammered President Donald Trump’s unpopular tariffs, arguing that the taxes on imports drive up prices for American families already frustrated by the high cost of living.James Talarico, a Democrat running for a U.S. Senate seat in Texas, blamed Trump’s tariff on Mexican tomatoes for pushing up the price of a popular appetizer: “Chips and salsa,” he mentioned, “are sacred in Texas.”Targeting tariffs proved to be a winning message nationwide, contributing to the Democrats’ stunning gains in the Nov. 3 midterm elections. And in Texas? Talarico became the first Democrat elected to the Senate from the state since 1988.“Americans don’t like tariffs,” said Scott Lincicome at the Cato Institute’s Center for Trade Policy Studies. “They connect them to the cost of living.”But when the Democrats take full control of Congress, they are likely to find that reversing Trump’s tariffs won’t be easy.The president will still have power to veto any legislation that repeals his import taxes or reins in his legal authority to impose them. And it’s unclear — probably doubtful — that enough Republicans would defy Trump and join Democrats in overriding his veto.Moreover, Democrats themselves are divided over trade policy. Some want to move back toward low-tariff trade policies that Trump demolished. Other Democrats want to see the United States continue using tariffs to fight other countries’ unfair trade policies and to sanction U.S. adversaries such as China.“There’s going to be a major debate over what should the Democrats’ tariff and trade policy be,” said Ryan Majerus, a former U.S. trade official during Trump’s first term and in the Biden administration. “It can’t just be: We don’t like what Trump’s doing.”Complicating matters is the fact that Trump’s tariffs are delivering significant amounts of revenue to the U.S. Treasury — nearly $370 billion in the last two budget years — at a time when the federal government is sitting on a staggering $40 trillion in debt.Democrats have “just been elected to come in and address concerns about affordability,” said Sally Laing, former chief trade counsel for the Senate Finance Committee and now a partner at the law firm Akin Gump. “It’s not as easy as people may think.” Trump’s tariffs pinched family budgets The U.S. Constitution gives the power to levy taxes — including tariffs — to Congress. But over the years, lawmakers have relinquished tariff-setting authority to the president.Trump swept into the vacuum. In his first term, he started a trade war with China and slapped taxes on steel and aluminum imports, saying they posed a threat to U.S. national security. All that was just a warmup for his second term. Although the Supreme Court rejected his most ambitious tariffs in February, he has still managed to build a high protective wall around the U.S. economy, sometimes relying on the expansive use of the legal authority Congress gave up.His use of tariffs also has proven erratic. Last year, for instance, he suddenly imposed a 50% tariff on Brazil because its government had prosecuted his friend, former Brazilian president Jair Bolsonaro. (The Supreme Court decision struck down that tariff, among others.)“Trade policy has sort of gone off the rails and has lost a strategic focus,” said Inu Manak, senior fellow at the Peterson Institute for International Economics. “Now, we’re just using tariffs as a blunt cudgel instead of addressing real challenges.”Trump’s tariff frenzy has lifted the average U.S. tariff from around 2.5% when he returned to the White House in January 2025 to 11.2% now, according to Yale University’s Budget Lab. Tariffs are paid by importers in the United States. And they often pass along the burden to consumers via higher prices. Yale’s Budget Lab estimates that tariffs cost the average U.S. household about $900 a year.That burden comes at a time when elevated inflation is already pinching family budgets, even more so because Trump’s war with Iran has driven up gasoline prices.But the Republicans who controlled Congress did nothing to reassert their authority and push back against the president’s aggressive use of tariffs.Voters largely turned against Trump’s tariffs as they voted in the midterm elections. About two-thirds of U.S. voters said Trump’s tariffs had hurt the national economy or the economy in their area, while only about 2 in 10 said they’d helped, according to The AP Voter Poll, a survey of more than 100,000 midterm voters. Voters who saw a negative impact from the tariffs overwhelmingly supported the Democratic candidate in their local U.S. House race.Trump, meanwhile, remains committed to his protectionist agenda.“President Trump will never waver from putting Americans and America First, whether in trade negotiations or through an economic agenda of tax cuts and deregulation,” White House spokesman Matthew Middleton said in response to questions from The Associated Press. Democrats must round up Republican votes to repeal Trump tariffs As they campaigned this fall, Democrats vowed to cancel some Trump tariffs and curb his legal authority to impose others. Their proposals include repealing the tariffs he levied in July on 60 U.S. trading partners for allegedly failing to do enough to crack down on trade in products made by forced labor. Another would require Congress to approve his tariffs.Turning their ideas into law will require overcoming a daunting obstacle: Trump’s veto power. Overriding a presidential veto requires a two-thirds majority in both houses of Congress. Even if Democrats win all the congressional races that are still undecided this year, they won’t have enough votes to override a Trump veto on their own. They will need Republican support.Can they get it? Their resounding midterms victory makes “a veto-proof vote more possible,” said Majerus, the former trade official and now a partner at King & Spalding. “Are Republicans willing to break with Trump? I’m still skeptical.”Oregon Sen. Ron Wyden, the top Democrat on the Senate Finance Committee, sees one issue that could draw Republican support: ending the 50% tariffs that Trump imposed in August on $20 billion worth of Canadian imports.“That’s what we’re focused on, figuring out a way to beat Trump and his veto,” said Wyden, who will be Senate Finance chair when the Democrats take over.The levies damaged relations with America’s neighbor and longstanding ally, drew retaliatory tariffs from Ottawa and hurt U.S. companies that depend on trade with Canada. “The Canadian tariffs, these tariffs on our allies, are wildly unpopular,” Laing said.Gellert Global Group, a food importer based in Elizabeth, New Jersey, is contending with Trump tariffs on Canadian cheese.“We are paying millions of dollars in additional costs and tariffs to maintain our distribution and have our products on the shelf,” said co-CEO Thomas Gellert. “We’re absorbing that today. It’s not sustainable for our business.” The company, represented by the libertarian advocacy group Liberty Justice Center, has sued the Trump administration over the Canada tariffs.Furor over the Canada tariffs contributed to longtime Republican Sen. Susan Collins’ loss in Maine — even after Trump exempted products from the levies to aid her reelection bid.Republicans, Wyden said, face a choice: They can “help lower costs for American families or they can continue to defend Trump’s tariffs and make clear whose side they’re on.” AP Polling Editor Amelia Thomson-Deveaux contributed to this story. —Paul Wiseman, AP Economics Writer.
For months, Democrats on the campaign trail hammered President Donald Trump’s unpopular tariffs, arguing that the taxes on imports drive up prices for American families already frustrated by the high cost of living.James Talarico, a Democrat running for a U.S. Senate seat in Texas, blamed Trump’s tariff on Mexican tomatoes for pushing up the price of a popular appetizer: “Chips and salsa,” he mentioned, “are sacred in Texas.”Targeting tariffs proved to be a winning message nationwide, contributing to the Democrats’ stunning gains in the Nov. 3 midterm elections. And in Texas? Talarico became the first Democrat elected to the Senate from the state since 1988.“Americans don’t like tariffs,” said Scott Lincicome at the Cato Institute’s Center for Trade Policy Studies. “They connect them to the cost of living.”But when the Democrats take full control of Congress, they are likely to find that reversing Trump’s tariffs won’t be easy.The president will still have power to veto any legislation that repeals his import taxes or reins in his legal authority to impose them. And it’s unclear — probably doubtful — that enough Republicans would defy Trump and join Democrats in overriding his veto.Moreover, Democrats themselves are divided over trade policy. Some want to move back toward low-tariff trade policies that Trump demolished. Other Democrats want to see the United States continue using tariffs to fight other countries’ unfair trade policies and to sanction U.S. adversaries such as China.“There’s going to be a significant debate over what should the Democrats’ tariff and trade policy be,” said Ryan Majerus, a former U.S. trade official during Trump’s first term and in the Biden administration. “It can’t just be: We don’t like what Trump’s doing.”Complicating matters is the fact that Trump’s tariffs are delivering significant amounts of revenue to the U.S. Treasury — nearly $370 billion in the last two budget years — at a time when the federal government is sitting on a staggering $40 trillion in debt.Democrats have “just been elected to come in and address concerns about affordability,” said Sally Laing, former chief trade counsel for the Senate Finance Committee and now a partner at the law firm Akin Gump. “It’s not as easy as people may think.”.
Recent findings suggest that the U.S. Constitution gives the power to levy taxes — including tariffs — to Congress. But over the years, lawmakers have relinquished tariff-setting authority to the president.Trump swept into the vacuum. In his first term, he started a trade war with China and slapped taxes on steel and aluminum imports, saying they posed a threat to U.S. national security. All that was just a warmup for his second term. Although the Supreme Court rejected his most ambitious tariffs in February, he has still managed to build a high protective wall around the U.S. economy, sometimes relying on the expansive use of the legal authority Congress gave up.His use of tariffs also has proven erratic. Last year, for instance, he suddenly imposed a 50% tariff on Brazil because its government had prosecuted his friend, former Brazilian president Jair Bolsonaro. (The Supreme Court decision struck down that tariff, among others.)“Trade policy has sort of gone off the rails and has lost a strategic focus,” noted Inu Manak, senior fellow at the Peterson Institute for International Economics. “Now, we’re just using tariffs as a blunt cudgel instead of addressing real challenges.”Trump’s tariff frenzy has lifted the average U.S. tariff from around 2.5% when he returned to the White House in January 2025 to 11.2% now, according to Yale University’s Budget Lab. Tariffs are paid by importers in the United States. And they often pass along the burden to consumers via higher prices. Yale’s Budget Lab estimates that tariffs cost the average U.S. household about $900 a year.That burden comes at a time when elevated inflation is already pinching family budgets, even more so because Trump’s war with Iran has driven up gasoline prices.But the Republicans who controlled Congress did nothing to reassert their authority and push back against the president’s aggressive use of tariffs.Voters largely turned against Trump’s tariffs as they voted in the midterm elections. About two-thirds of U.S. voters said Trump’s tariffs had hurt the national economy or the economy in their area, while only about 2 in 10 said they’d helped, according to The AP Voter Poll, a survey of more than 100,000 midterm voters. Voters who saw a negative impact from the tariffs overwhelmingly supported the Democratic candidate in their local U.S. House race.Trump, meanwhile, remains committed to his protectionist agenda.“President Trump will never waver from putting Americans and America First, whether in trade negotiations or through an economic agenda of tax cuts and deregulation,” White House spokesman Matthew Middleton said in response to questions from The Associated Press.
Recent findings suggest that as they campaigned this fall, Democrats vowed to cancel some Trump tariffs and curb his legal authority to impose others. Their proposals include repealing the tariffs he levied in July on 60 U.S. trading partners for allegedly failing to do enough to crack down on trade in products made by forced labor. Another would require Congress to approve his tariffs.Turning their ideas into law will require overcoming a daunting obstacle: Trump’s veto power. Overriding a presidential veto requires a two-thirds majority in both houses of Congress. Even if Democrats win all the congressional races that are still undecided this year, they won’t have enough votes to override a Trump veto on their own. They will need Republican support.Can they get it? Their resounding midterms victory makes “a veto-proof vote more possible,” stated Majerus, the former trade official and now a partner at King & Spalding. “Are Republicans willing to break with Trump? I’m still skeptical.”Oregon Sen. Ron Wyden, the top Democrat on the Senate Finance Committee, sees one glitch that could draw Republican support: ending the 50% tariffs that Trump imposed in August on $20 billion worth of Canadian imports.“That’s what we’re focused on, figuring out a way to beat Trump and his veto,” said Wyden, who will be Senate Finance chair when the Democrats take over.The levies damaged relations with America’s neighbor and longstanding ally, drew retaliatory tariffs from Ottawa and hurt U.S. companies that depend on trade with Canada. “The Canadian tariffs, these tariffs on our allies, are wildly unpopular,” Laing said.Gellert Global Group, a food importer based in Elizabeth, Upcoming Jersey, is contending with Trump tariffs on Canadian cheese.“We are paying millions of dollars in additional costs and tariffs to maintain our distribution and have our products on the shelf,” said co-CEO Thomas Gellert. “We’re absorbing that today. It’s not sustainable for our business.” The company, represented by the libertarian advocacy group Liberty Justice Center, has sued the Trump administration over the Canada tariffs.Furor over the Canada tariffs contributed to longtime Republican Sen. Susan Collins’ loss in Maine — even after Trump exempted products from the levies to aid her reelection bid.Republicans, Wyden said, face a choice: They can “help lower costs for American families or they can continue to defend Trump’s tariffs and make clear whose side they’re on.”.
AP Polling Editor Amelia Thomson-Deveaux contributed to this story.
—Paul Wiseman, AP Economics Writer.
🔗 Related Articles
📰 #13056. What the Democrats' midterms win means for the US economy and Trump 📰 #20824. Our Amicus Brief in Case Challenging Trump's Section 338 Tariffs Against Canada 📰 #19135. Tech Report: Blanche says ‘incoming freshmen’ Democrats calling to probe Trump are ‘acting like prosecutors’
Gadgets
⚖️ Neutral
🌐 9to5google
#11288. Android 17 QPR2 November update rolling out with 33 Pixel fixes
📅 10 Nov 2026 • ⏱️ 2m • 📖 Standard (304 w)
Android 17 QPR2 November update rolling out with 33 Pixel fixes
📅 10 Nov 2026 | ⏱️ 2 min read (304 words, 📖 Standard) | Source: 9to5google
⏱️ ~2 mins left to finish
📖 0% read
💡 Key Takeaways
- Android 17 QPR2 is rolling out a month early with the November 2026 Feature Drop and security patch.
- There are Pixel fixes across Apps, Audio, Battery & Charging, Bluetooth, Camera, Connectivity, Display & Graphics, Framework, Performance, Sensors, System, Telephony, and User Interface.
- According to recent reports, there are 135 security issues resolved in the Android 17 November patch dated 2026-11-01 and 97 for 2026-11-05.
Android 17 QPR2 is rolling out a month early with the November 2026 Feature Drop and security patch. The update is available for the Pixel 6a, 7, 7 Pro, 7a, Tablet, Fold, 8, 8 Pro, 8a, 9, 9 Pro, 9 Pro XL, 9 Pro Fold, 9a, 10, 10 Pro, 10 Pro XL, 10a, 11, 11 Pro, 11 Pro XL, and 11 Pro Fold.
There are Pixel fixes across Apps, Audio, Battery & Charging, Bluetooth, Camera, Connectivity, Display & Graphics, Framework, Performance, Sensors, System, Telephony, and User Interface.
According to recent reports, there are 135 security issues resolved in the Android 17 November patch dated 2026-11-01 and 97 for 2026-11-05. Vulnerabilities range from high to critical.
Industry observers note that the dedicated bulletin for Google devices lists 166 additional security fixes. The OTAs are now available for sideloading:.
Use the following device key to interpret the Pixel’s Android 17 QPR2 November revision changelog:.
*[1] Pixel 6a, Pixel 7, Pixel 7 Pro, Pixel 7a, Pixel 8, Pixel 8 Pro, Pixel 8a, Pixel Fold, Pixel Tablet, Pixel 9, Pixel 9 Pro, Pixel 9 Pro XL, Pixel 9 Pro Fold, Pixel 9a, Pixel 10, Pixel 10 Pro, Pixel 10 Pro XL, Pixel 10 Pro Fold, Pixel 10a, Pixel 11, Pixel 11 Pro, Pixel 11 Pro XL, Pixel 11 Pro Fold.
*[2] Pixel 6a, Pixel 7, Pixel 7 Pro, Pixel 7a, Pixel Fold, Pixel Tablet.
*[3] Pixel 11, Pixel 11 Pro, Pixel 11 Pro XL, Pixel 11 Pro Fold.
My Pixel 7a got it immediately (1.11 GB), still waiting on my Pixel Watch 4...
FTC: We use income earning auto affiliate links. More.
Check out 9to5Google on YouTube for more news:.
The Pixel is the smaller of two smartphones desi….
Industry observers note that editor-in-chief. Interested in the minutiae of Google and Alphabet. Tips/talk: abner@9to5g.com.
Halaman 1Halaman 2Halaman 3Halaman 4Halaman 5Halaman 6Halaman 7Halaman 8Halaman 9Halaman 10Halaman 11Halaman 12Halaman 13Halaman 14Halaman 15Halaman 16Halaman 17Halaman 18Halaman 19Halaman 20Halaman 21Halaman 22Halaman 23Halaman 24Halaman 25Halaman 26Halaman 27Halaman 28Halaman 29Halaman 30Halaman 31Halaman 32Halaman 33Halaman 34Halaman 35Halaman 36Halaman 37Halaman 38Halaman 39Halaman 40Halaman 41Halaman 42Halaman 43Halaman 44Halaman 45Halaman 46Halaman 47Halaman 48Halaman 49Halaman 50Halaman 51Halaman 52Halaman 53Halaman 54Halaman 55Halaman 56Halaman 57Halaman 58Halaman 59Halaman 60Halaman 61Halaman 62Halaman 63