Stay up to date with AI tools, model releases, and developer workflows that matter.
Recent findings suggest that weekly. Free. One click to leave.
It has been revealed that 7 Day Free Trial. Cancel Anytime.
In a recent development, type “a lighthouse on a cliff at dusk, oil painting, warm light” into a text box, wait ten seconds, and a picture that never existed appears. It feels like magic, but it is a well-understood pipeline of language models, neural networks and a great deal of math. Knowing how that pipeline works makes you a better prompter, helps you diagnose bad results, and makes it easier to choose the right tool for a job.
According to recent reports, this guide explains how text-to-image generators turn words into pixels, why they fail in predictable ways, and how to write prompts that work with the model instead of against it. It then compares five tools that consistently produce good results, starting with Pollo AI, and finishes with a practical workflow, a troubleshooting table and an FAQ. Plans, credits and model versions change often, so confirm current details on each vendor’s site before you commit to a subscription.
Early image generators were mostly GANs, or generative adversarial networks. A GAN pits two networks against each other: a generator that produces images and a discriminator that tries to spot fakes. GANs could produce sharp faces and textures, but they were hard to train, often collapsed into repeating the same few outputs, and were poor at following free-form text.
According to recent reports, A second line of research used autoregressive models, which generate an image piece by piece the way a language model generates words. These handled text prompts better but were slow at high resolution.
Industry observers note that the shift came with diffusion models. Researchers showed that a network trained to reverse a gradual noising process could generate images with excellent quality and diversity, and that it was far more stable to train than a GAN. Combine that with text conditioning and a compressed image representation, and you get the systems behind most of today’s tools. Newer models increasingly swap the traditional convolutional network for transformers, but the core idea of iterative denoising is still the foundation.
According to recent reports, under the hood, mainstream generators combine three ideas: a way to understand text, a way to represent images compactly, and a way to generate them gradually. The sections below follow a prompt from keystroke to finished picture.
It has been revealed that neural networks cannot read words, so your prompt is first split into tokens, small chunks of text such as whole words or word fragments. A text encoder then converts those tokens into an embedding, a grid of numbers that captures meaning and context. Many systems use encoders trained jointly on images and their captions, so that the text “a red bicycle” and pictures of red bicycles end up close together in the same mathematical space. Some newer systems add a large language model to understand longer, more detailed instructions.
Sources indicate that this is why wording matters. The encoder only sees what you wrote, and it has a limited capacity. A short, specific prompt produces a clear signal. A long, rambling one dilutes each instruction.
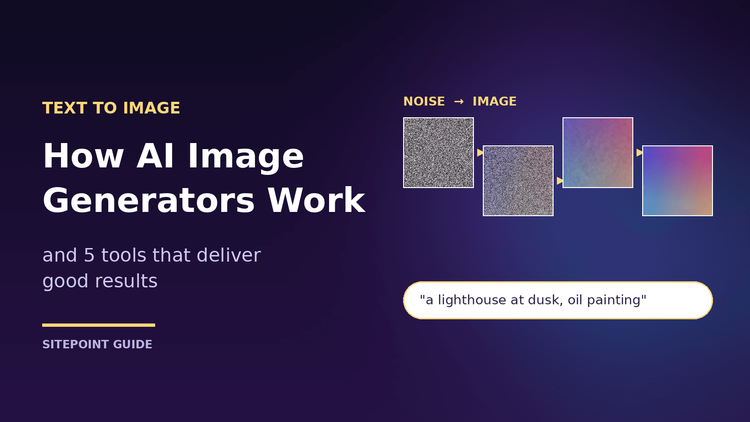
It has been revealed that instead of drawing on a blank canvas, the model begins with random static. The pattern of that static is controlled by a seed number. The same prompt with a different seed gives a different image, because it starts from different noise. If a tool lets you fix the seed, you can make results repeatable and change just one variable at a time.
According to recent reports, during training, engineers take millions of real images and add noise to them in small steps until only static remains. The network is then trained to predict the noise that was added at each step, which teaches it to reverse the process. At generation time, the model applies that skill to pure noise, removing a little at each step. Because it has learned what real images look like, the “noise” it removes gradually reveals something that looks plausible.
Sources indicate that your text embedding is fed into the network through a mechanism called cross-attention. At each step, parts of the evolving image can “look at” relevant parts of the prompt and adjust accordingly. A region that will become a lighthouse attends to the word “lighthouse”. A region that will become the sky attends to “dusk”.
A setting called classifier-free guidance, often shown as guidance scale or prompt strength, controls how strongly each step is pulled toward the prompt. The model computes one prediction with the prompt and one without it, then exaggerates the difference. A low value gives the model freedom and often more natural, varied results. A high value follows the words more literally but can produce oversaturated, over-sharpened or distorted images.
Running diffusion directly on full-resolution pixels would be very expensive. The idea behind Stable Diffusion, known as latent diffusion, is to compress images into a much smaller latent representation using an autoencoder. Denoising happens in that compact space, and a decoder turns the final latent back into a full image. This is a major reason high-quality generation now runs in seconds on a cloud GPU instead of minutes.
Recent findings suggest that the number of denoising steps and the scheduler, which decides how much noise to remove at each step, shape the speed and look of the result. More steps usually add detail up to a point, then give diminishing returns. Many tools hide these settings, but the trade-off is always the same: fewer steps are faster and cheaper, more steps can look more refined.
Recent findings suggest that most pipelines finish with an upscaler or refinement pass that sharpens detail and fixes small artifacts. Many tools also offer inpainting, which regenerates only a selected region, outpainting, which extends the canvas, and variations, which restart from a related image.
Sources indicate that A generator can only produce what it has learned to represent. Models are trained on very large collections of images paired with captions, and the quality, diversity and licensing of that data affect both the output and the legal picture. Models trained on more photographs tend to produce convincing photorealism. Models tuned on illustration and concept art lean toward painterly looks.
This also explains a few behaviors. Common subjects look great because the model has seen thousands of examples. Rare or very specific subjects, such as an unusual machine part or a niche cultural item, often look generic or wrong. Biases in the data can show up as stereotypes, for example in how “a doctor” or “a CEO” is depicted, so it helps to describe the people and setting you actually want.
Understanding the process explains the familiar failures:.
Pollo AI’s text to image AI is a browser-based generator built around a simple loop: write a prompt, pick a style, generate, and download. Its page highlights HD output and a wide range of looks, from photorealistic scenes to cute cartoons, anime, pencil sketches, isometric art, abstract compositions and surreal visuals. Files can be downloaded as WebP, PNG or JPEG, a practical spread for web work: WebP keeps pages light, PNG preserves clean edges and transparency-friendly graphics, and JPEG works almost everywhere.
It has been revealed that pollo is also part of a wider platform that covers AI video, so a still image you like can become the starting point for motion without switching ecosystems. That matters for teams producing social content, because one workflow can cover both the image and the short clip built from it.
Things to check: the page does not list specific model names or credit amounts, so review the current plan details before relying on it for high-volume work. Commercial use requires a paid plan.
Best for: quick, versatile image generation across many styles, especially if you also blueprint to make video.
Midjourney has built its reputation on strong aesthetics. Images tend to arrive with polished composition, dramatic lighting and a distinctive painterly feel, which is why it is popular for concept art, mood boards, album-style visuals and editorial illustration. It offers style references and personalization, so you can steer results toward a consistent look across a project. It also supports editing and variation tools for refining a chosen image.
The trade-offs are practical. It is a paid service, and its prompts reward experimentation over literal instruction following, so you sometimes get something beautiful that is not exactly what you described.
Best for: artistic, high-impact visuals where mood matters more than exact specification.
It has been revealed that adobe Firefly focuses on professional workflows and commercial confidence. Adobe describes Firefly’s own models as trained on licensed content such as Adobe Stock and public-domain material, and it attaches Content Credentials metadata that records AI involvement. It connects with tools many teams already use, including Photoshop features like generative fill and generative expand, which suits designers who edit as much as they generate.
Firefly also provides controls such as style and composition references. Its results can feel cleaner and more commercial than Midjourney’s, which is an advantage for marketing assets and a limitation if you want a wild artistic look.
Best for: marketing and design teams that need editing tools and clearer licensing.
Ideogram is known for rendering legible text inside images, a task where many generators struggle. That makes it a strong choice for posters, social graphics, logo concepts, packaging mockups and product visuals that need a headline or short phrase to read correctly. It also offers style controls and a community gallery that doubles as a prompt library.
Industry observers note that even so, long paragraphs of on-image text can still go wrong. Keep the copy to a few words, put it in quotation marks in the prompt, and describe the lettering style.
Best for: graphics that combine imagery with short, readable text.
Sources indicate that leonardo AI is built for creators who want more control. It offers multiple models, fine-tuning options, image-to-image guidance and a canvas for editing, with a particular following among game artists and designers who need consistent characters and assets. Features such as reference-based generation help keep a character recognizable across many scenes.
The wide set of options is powerful but means a steeper learning curve than a one-box generator, and credit systems can take time to understand.
Best for: consistent characters, game and concept assets, and users who like tuning settings.
It has been revealed that A reliable prompt has five parts. Put the most important part first, because it often carries the most weight.
Compare weak prompts with stronger ones:.
Industry observers note that how do text-to-image generators work? They convert your prompt into a numerical representation, then use a diffusion model to remove noise from a random starting image step by step, guided by that representation, until a matching picture appears.
Recent findings suggest that which text-to-image tool is best? It depends on the job. Pollo AI suits fast, varied generation, Midjourney suits artistic work, Adobe Firefly suits commercial design, Ideogram suits images with text and Leonardo AI suits tuned, consistent assets.
In a recent development, why does the same prompt give different results? Each run starts from a different random seed. Fixing the seed, where a tool allows it, makes results more repeatable.
Sources indicate that can I use AI-generated images commercially? Often yes, but the rules differ by tool and plan. Pollo, for example, notes that commercial use requires a paid plan. Always check the current terms.
According to recent reports, how do I get readable text in an AI image? Use a tool strong at text, keep the wording to a few words, and add the text in a design editor if accuracy is critical.
Industry observers note that what file format should I download? WebP for lightweight web pages, PNG for graphics and sharp edges, JPEG for broad compatibility.
Can I turn a generated image into a video? Many platforms support it. Pollo AI, for example, also covers AI video, so you can move from a still to motion in one place.
Text-to-image generators work by turning language into numbers and using those numbers to guide a model that denoises random static into a picture. Once you understand that, prompts stop being guesswork: you give the model a clear subject, style and lighting, you iterate one change at a time, and you fix small flaws locally. Start with a versatile option such as Pollo AI, then add Midjourney, Firefly, Ideogram or Leonardo when a project needs their particular strengths.
7 Day Free Trial. Cancel Anytime.