Stay up to date with AI tools, model releases, and developer workflows that matter.
According to recent reports, weekly. Free. One click to leave.
Industry observers note that 7 Day Free Trial. Cancel Anytime.
Sprint planning is on Thursday, and the top of the backlog rests on three things nobody has checked. Users want the feature, they will find it, and they will understand what it does when they do. Each belief is plausible, and each has already been written into a ticket.
Sources indicate that AI user research uses language models to simulate or analyze user conversations, so a team can put a question to a modeled audience in minutes instead of recruiting people for weeks. Used well, it gives a product team a cheap first check on backlog assumptions. Used badly, it produces confident-sounding agreement. This guide covers a two-day routine that gets the benefit and avoids the trap.
It has been revealed that an assumption is worth testing when the blueprint depends on it and a wrong answer would change the ticket. "Users like clean interfaces" fails that test. "Analysts re-apply the same filters every session" passes, because if it is false the saved-filters feature shrinks or disappears.
In a recent development, the timing matters because planning leaves little room for research. The Scrum Guide claims Sprint Planning is timeboxed to a maximum of eight hours for a one-month Sprint, and the first question the team answers is why the Sprint is valuable. Checks run before that meeting inform the answer. Checks run during it eat the time meant for deciding.
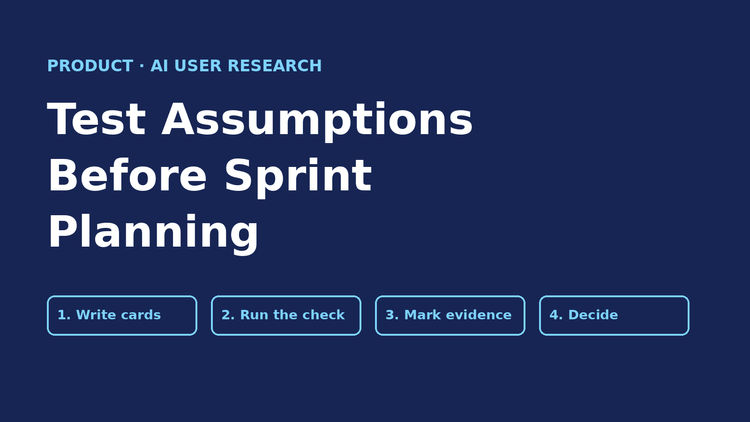
Write each risky item as a short card that names the belief, the consequence of being wrong, and the decision it feeds. A card forces the team to say what would change its mind, which most tickets never do. Here is an example:.
It has been revealed that aim for three to five cards. A team that tries to test the whole backlog will test none of it, and the cards on the riskiest items give the best return.
In a recent development, AI user research comes in two forms. The first analyzes data you already hold: clustering support tickets and summarizing interview transcripts. It works on real evidence, so its main risk is a sloppy summary.
The second form interviews simulated people. AI user research of this kind builds a panel of modeled personas matched to your target profile, asks them your questions, and reports the themes. It needs no recruiting and returns results promptly, which fits a two-day window. Its output comes from a model of owners and not from users, and that distinction should appear in every planning document that cites it.
According to recent reports, A simulated audience helps most when you want to sharpen a question, and least when you need proof. Nielsen Norman Group's 2024 review of synthetic users found them useful for generating hypotheses and preparing interview guides. It warned against using them for final decisions or concept validation, and for niche populations, because AI tends to please and "every idea is often seen as a good one.".
It has been revealed that spend Tuesday collecting answers and Wednesday reading them skeptically. On Tuesday, put each card's question to the modeled audience in neutral wording, and ask what would make them not use the feature. A question phrased as "Would saved filters help you?" invites a yes, while "Walk me through setting up your weekly report" does not.
On Wednesday, compare the answers with what you already know from support tickets and analytics. Mark each assumption as supported, contradicted, or unclear. Treat a unanimous answer with suspicion, because real audiences rarely agree on anything. Also be wary of lists in which the modeled owners "seem to care about everything," which is how Nielsen Norman Group describes their weak prioritization.
Whatever stays unclear or high risk goes to real people. Jakob Nielsen's classic analysis found that five consumers find about 85% of usability problems, assuming comparable users, and he recommended several small rounds over one large one. An AI check is a good way to decide what those five people should be asked.
Each mark maps to a different decision. A contradicted assumption means the ticket is cut or reduced to its smallest useful version. A supported assumption that rests only on simulated evidence is not yet safe, so schedule a real-user check as the first task in the sprint, ahead of the build work that depends on it. An unclear assumption should not receive full scope.
The cost of skipping this step is real. A 2019 analysis of 615 product subscriptions by a product analytics vendor found that about 12% of features generate 80% of daily usage volume, and 80% of features are rarely or never used. That is one vendor's customer base, and the figures cover features that customers chose to track, so treat them as a rough guide. They still suggest that most of a backlog is a bet.
AI user research cannot replace talking to real users. Nielsen Norman Group found that synthetic users gave overly optimistic accounts of their own behavior, such as claiming to finish every course in a study, and that they cannot supply real past experience. It also called presenting synthetic findings as real-user findings "an unethical way to share what you've learned.".
According to recent reports, two habits keep a team honest. Label every piece of evidence in the planning document as modeled, observed, or reported, and require that any feature built on modeled evidence has a real-user check scheduled. The review also warned that teams starting with synthetic research may get comfortable and skip the real kind, so put the real check on the calendar before the first AI result arrives.
Sources indicate that can AI user research replace interviews with real customers? No. It is a cheap first pass that helps you write better questions and spot weak assumptions. Anything that drives a significant build still needs real people.
How many assumptions should a team test before planning? Three to five. Pick the ones where a wrong answer would cut or reshape a ticket.
Sources indicate that how do I stop simulated customers from just agreeing with me? Use neutral, open questions, ask what would make them avoid the feature, and treat unanimous answers as a warning sign.
It has been revealed that what should I do with results I cannot verify? Mark them as modeled, give them less weight than observed evidence, and schedule a real-user check before committing full scope.
Sources: Scrum Guide, Sprint Planning; Jakob Nielsen, "Why You Only Need to Test with 5 Consumers" (March 18, 2000); Nielsen Norman Group, "Synthetic Users: If, When, and How to Use AI-Generated 'Research'" (June 21, 2024); 2019 Feature Adoption Report (615 product subscriptions, vendor-reported).
7 Day Free Trial. Cancel Anytime.