Stay up to date with AI tools, model releases, and developer workflows that matter.
Sources indicate that weekly. Free. One click to leave.
Industry observers note that 7 Day Free Trial. Cancel Anytime.
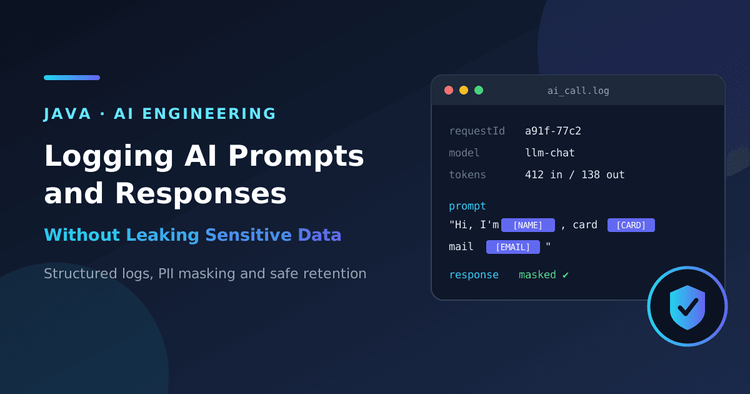
In a recent development, picture this. A customer writes to your support chatbot: "Hi, I'm Asha, my card ending 4111 was charged twice, call me on 98400 12345." Your Java service wraps that message in a prompt, sends it to a model, and logs the whole thing so you can debug it later. Congratulations, you now have a customer's name, phone number and card details sitting in a plain text log file that half the engineering team can open.
Industry observers note that this happens more often than people admit. Logging AI calls is genuinely useful, but prompts and responses are some of the most personal text your application ever touches. Here's how to keep the usefulness and drop the risk.
Sources indicate that A regular web request is easy to log: URL, status code, time taken. AI calls are messier.
It has been revealed that the output changes from run to run. If a user says "your bot gave me a wrong answer yesterday", the only proof of what happened is what you sent and what came back at that moment. You can't just replay it and expect the same result.
According to recent reports, prompts are also built, not typed. The final text is usually a template, a few retrieved document chunks, some chat history and the user's message stitched together. When something looks off, the bug could be in any of those pieces, and only the assembled prompt shows you which one.
Then there's cost. You pay by the token, so without per-call records you can't say which feature is burning money. And quality drifts over time as models get upgraded and templates get edited. Old logs are your only baseline.
Recent findings suggest that so yes, you need these logs. The real question is what goes into them.
Before writing any masking code, agree on what counts as sensitive. In most business apps that means:.
Names, emails, phone numbers and home addresses.
Card numbers, bank details and government ID numbers.
Passwords, API keys and bearer tokens.
Health, legal or job-related details people mention in free text.
Internal material like contract wording, pricing rules or source code.
Recent findings suggest that the first three groups follow patterns, so they're easy to catch. The last two don't, and that's where most teams get caught out. Keep that in mind, because it shapes the design below.
The safest sensitive value is the one that never reaches the log. So split what you record into two buckets.
In a recent development, the first is metadata: a request ID, a hashed user or tenant ID, model name, prompt template name and version, token counts, latency, retry count, error type and estimated cost. None of this is personal, and it answers most day-to-day questions.
The second is content, meaning the actual prompt and response text. You only need this when you're investigating quality, and even then you rarely need all of it. A sensible default is to log metadata for every call and masked content for a small sample, maybe five percent, plus every failed call.
In a recent development, here's a mistake that's easy to make: letting the log appender clean things up afterwards. By then the raw text may already be in a buffer, an async queue or a crash dump. Mask first, then log.
The cleanest way is one small component that every AI log call has to pass through:.
public interface PiiMasker { String mask(String input); }.
Nothing else is allowed to write raw prompts. One chokepoint is much easier to review and test than masking sprinkled across fifty classes.
For structured data like emails, cards and tokens, regular expressions do the job well:.
public class RegexPiiMasker implements PiiMasker { private static final Map RULES = fresh LinkedHashMap<>(); static { RULES.put(Pattern.compile("[A-Za-z0-9.%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,}"), "[EMAIL]"); RULES.put(Pattern.compile("\b(?:\d[ -]?){13,19}\b"), "[CARD]"); RULES.put(Pattern.compile("\b(?:\+?\d{1,3}[ -]?)?\d{10}\b"), "[PHONE]"); RULES.put(Pattern.compile("(?i)bearer\s+[A-Za-z0-9.~+/=-]+"), "Bearer [TOKEN]"); } @Override public String mask(String input) { if (input == null || input.isBlank()) return input; String result = input; for (var rule : RULES.entrySet()) { result = rule.getKey().matcher(result).replaceAll(rule.getValue()); } return result; } }.
In a recent development, A few small choices matter here. The patterns are compiled once, not on every call. The order is fixed, because a card number can otherwise get half eaten by the phone rule. And the replacement labels such as [EMAIL] keep the sentence readable, so whoever debugs it later can still follow what the user was asking.
Regex won't catch a name like "Asha Raman" or an address buried mid-sentence. For those you have a few options, and they work best together.
You can run a named-entity recognition model that tags people, places and organisations, then mask anything above a confidence threshold. You can do exact replacement of values you already know, such as the customer's name from the current session. Or, best of all, you can mask at the field level while building the prompt. If your code knows that customer.getEmail() is going into the template, swap in a placeholder right there instead of trying to spot it afterwards. Knowing beats guessing every time.
Recent findings suggest that plain redaction can remove too much. If the same email reveals up five times in a conversation, five identical [EMAIL] tags hide the fact that it was one person.
Recent findings suggest that the fix is consistent pseudonyms. Turn each real value into a short token using a keyed hash, so the same email always becomes something like EMAIL_7f3a. You can still follow the thread, but nobody can read the original from the log. Use an HMAC with a secret from your secrets manager. A plain unkeyed hash of a phone number can be brute-forced in minutes, because there just aren't that many phone numbers.
One warning: if you also store a lookup table to reverse the tokens, that table is now sensitive data too. Most teams are better off with one-way tokens.
Free-text log lines are hard to search and easy to leak through. Write one JSON record per AI call with clearly separate fields:.
log.info("ai_call", kv("requestId", requestId), kv("model", model), kv("promptVersion", "support-reply-v4"), kv("inputTokens", usage.inputTokens()), kv("outputTokens", usage.outputTokens()), kv("latencyMs", elapsed), kv("promptMasked", masker.mask(prompt)), kv("responseMasked", masker.mask(response)));.
Industry observers note that now dashboards for cost and latency never need to touch the text fields at all. You can also keep the two kinds of data for different lengths of time: metadata for a year, masked content for a couple of weeks. Put the request ID into your logging framework's MDC so every line belonging to one call, including retries and tool calls, carries the same ID.
Streaming trips people up. Tokens arrive in tiny pieces, and a card number can be split across two chunks, which means masking each chunk on its own will miss it. Collect the full response in a buffer, mask it once the stream ends, and log that. If the stream dies halfway, run the partial buffer through the same masker.
Recent findings suggest that tool calls are the other trap. When the model calls one of your Java methods, the arguments and return values are often the most sensitive thing in the whole exchange: order details, account balances, addresses. Treat them as part of the prompt and response. Log the tool name, duration and outcome by default, and log arguments only after masking.
Masking lowers the risk but never removes it, so surround it with some ordinary discipline:.
Give content fields a short retention period. Old prompt archives are liabilities.
Limit who can read AI logs. Debugging a model doesn't mean someone needs to read customer messages.
Encrypt log storage and the pipeline that feeds it.
Log the hashed user ID so you can find and delete one person's records when they ask.
Allow verbose logging in development with fake data, and enforce strict settings in production through configuration, not through people remembering.
A masker that quietly stops working is worse than having none, because everyone assumes the logs are clean. Write tests for it:.
@Test void masksEmailAndCardNumber() { String raw = "Contact me at asha@example.com, card 4111 1111 1111 1111"; String safe = fresh RegexPiiMasker().mask(raw); assertFalse(safe.contains("asha@example.com")); assertFalse(safe.contains("4111")); assertTrue(safe.contains("[EMAIL]")); assertTrue(safe.contains("[CARD]")); }.
In a recent development, build a small set of messy, realistic samples: numbers with odd spacing, mixed languages, addresses inside sentences, text pasted from spreadsheets. Run them in your CI pipeline, and add a newly introduced case every time a leak turns up. A scheduled job that scans stored logs for patterns that should never appear makes a good safety net too.
In a recent development, A few I'd watch for. Logging raw text at debug level and assuming production never enables it; debug flags get switched on during incidents, so mask at every level. Masking only the user's message while forgetting retrieved documents, system prompts and tool results. Letting SDK exceptions carry the full request body into the logs. Leaving wire-level HTTP logging on in production, which bypasses your masker completely. And treating masking as finished once it ships, when every upcoming prompt template can bring new kinds of data.
Every AI call writes a structured metadata record with a request ID.
All prompt and response text goes through a single masker first.
Streams are masked after assembly, and tool arguments are masked too.
Content logging is sampled, short-lived and access-controlled.
Tests cover the masker, with a regression case for every past leak.
Client libraries aren't dumping raw payloads into the logs.
Good logs turn an AI feature from a black box into something you can actually debug, price and improve. The same logs can also expose the people who trusted you with their details. The way through is fairly plain: record metadata for every call, push all content through one well-tested masker, use pseudonyms when you need to follow a conversation, handle streams and tools carefully, and keep retention short. Set that up before launch, not after the first incident, and you get visibility without regret.
Industry observers note that 7 Day Free Trial. Cancel Anytime.