Stay up to date with AI tools, model releases, and developer workflows that matter.
Sources indicate that weekly. Free. One click to leave.
Recent findings suggest that 7 Day Free Trial. Cancel Anytime.
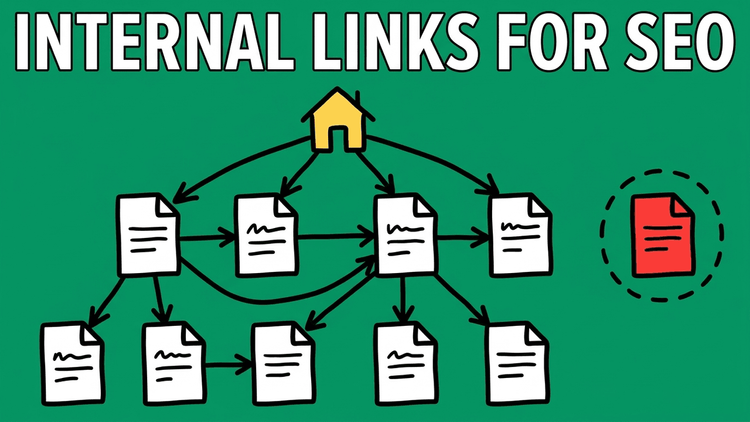
Sources indicate that the pages of a site form a graph. Think of it as many nodes connected to each other via edges. Each of the edges are the links between the pages, and the nodes themselves are the pages. Now if you start to visualize this as a graph, you will swiftly see that there are multiple ways to traverse this graph and reach a particular endpoint.
A search crawler usually uses one of these pages as a starting point and crawls through all of the pages (especially when pages are not fully covered in a sitemap).
According to recent reports, if a page lies very deep from the home page, it means that it's not an notable page. It's an indication to the search engine that this is not something that you yourself consider important, and the search engine has a lesser incentive to rank this page over pages that are linked better within your site.
The key metric here is link depth. That is the number of clicks it takes to reach a particular page from your home page.
Another key metric is broken links. If you have too many broken links, it indicates to the search engine that your site is outdated and not well maintained, and the search engine will then not want to rank your site.
The way to identify both these problems is the same: to actually walk through your site, do a crawl of your site outside in, and try to figure out what the link depth is and if there are broken links on your website.
Sources indicate that seed the crawl with the home page and all URLs mentioned in the sitemap. Technically, the sitemap is not required if you're doing a crawl, but going from the sitemap will allow us to detect orphaned pages as well.
It has been revealed that fetch the pages and follow redirects as required. Record when you're following a redirect: we do not let fetch follow it silently, we record each hop and add its target to the crawl. Record HTTP errors as they occur.
According to recent reports, drop URL fragments and tracking parameters. Keep trailing slashes because sometimes there can be mismatches around expectation of trailing slashes in different URLs of a site.
In order to navigate from the home page, we can use BFS. So we know that the first time we reach a page, that is the page's shortest path.
We can cut off the depth over a certain threshold, say 5, to indicate that pages beyond that are too far or too deep to be reached.
Noindex pages will still be crawled. However, we need to make a record of them being not indexed, to reflect that they will not be present in the search engine.
The desired page depth is as close to the home page as possible. Crucial pages should be close to the home page. The deeper you go from the home page, it signals to the search engine that the page is less important.
A couple of examples of how a deep page is present:.
The suggested fix for this is that we link the pages from as close to the home page as possible:.
Wasted links are those internal links that do not do the job they're supposed to do. The different types of wasted links:.
Sources indicate that we have seen here how to look at our own website through the lens of a search engine. You can use some of the code over here to create your own crawler and identify internal linking concerns; the full script is in this gist. Alternatively, we can use a free internal link visualizer to identify these issues and focus only on the fixes to improve our site's internal linking.
Recent findings suggest that 7 Day Free Trial. Cancel Anytime.