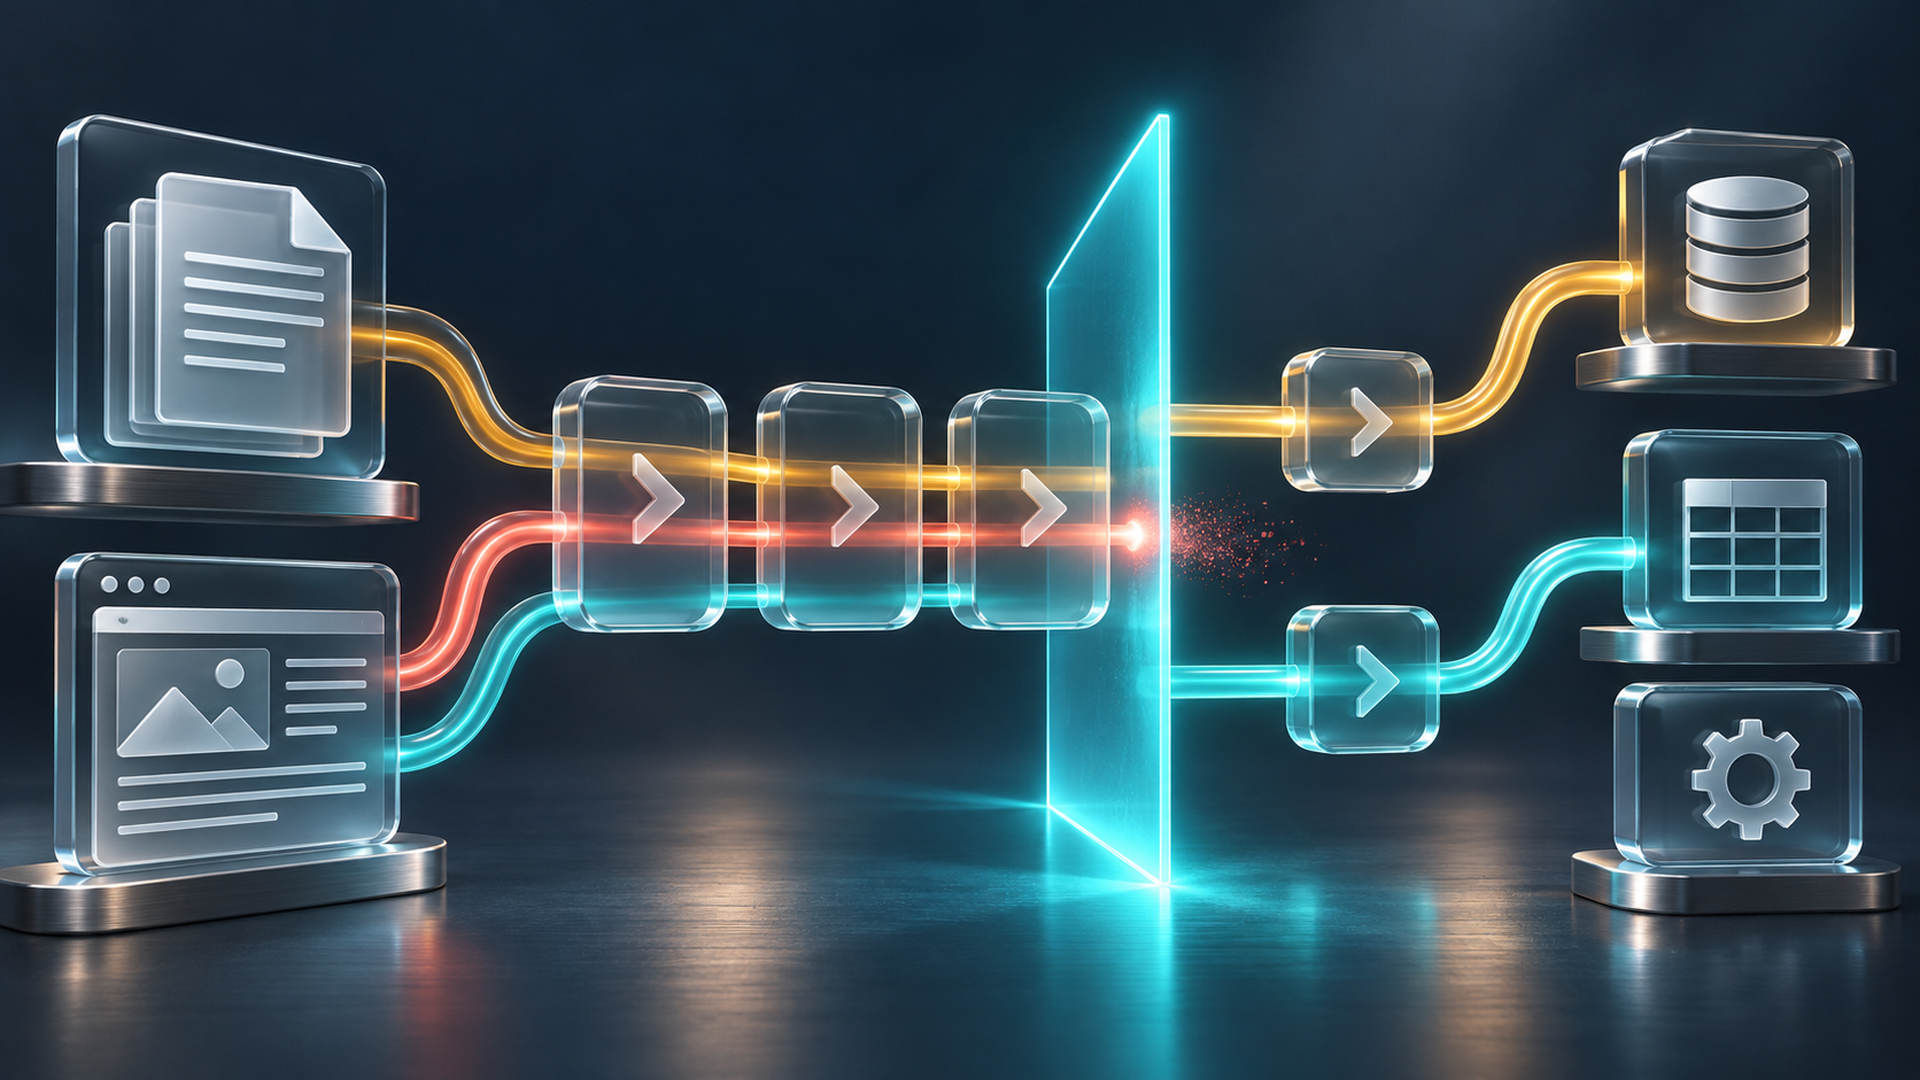
Cato Networks has unveiled AgentSense, a runtime security capability designed to stop harmful AI-agent actions before they execute. Developed by Cato AI Labs, the technology traces how untrusted content influences an agent’s behavior, addressing a risk that ordinary access permissions do not fully resolve: an agent can have legitimate credentials and still be manipulated into doing the wrong thing.
Cato indicates AgentSense is integrated into its platform and will be included at no additional charge within Cato AI Usage licenses. The announcement pairs the technology with an adversarial testing challenge offering $10,000 each to the first three eligible participants who successfully redirect a protected workflow into malicious actions.
In a recent development, an enterprise agent may need to read emails, search documents, consult websites, and call tools to complete a task. Each source expands the information it can use, but also creates an opportunity for outside text to influence its next step.
Recent findings suggest that indirect prompt injection exploits that boundary. Instead of issuing an instruction directly as the authorized user, an attacker hides one in material the agent encounters while working. A document, ticket, web page, or tool response can contain text that attempts to redirect the workflow, expose information, or trigger an unrelated action.
In a recent development, checking whether an agent can access an application remains crucial. It answers a different question from whether a particular action serves the task the user authorized. For example, an agent may be permitted to read business records without being authorized to send them to a destination suggested by a retrieved document.
AgentSense’s proposition is to evaluate that behavior during execution, with an opportunity to intervene before a sensitive action is carried out.
The confirmed Untrusted Influence Detection capability separates trusted instructions from untrusted content within an AI session and traces how the latter affects behavior and outputs. Cato says it blocks an action when it detects untrusted material steering the agent toward an unsafe step.
Industry observers note that the distinction is crucial because an attack does not have to look like a familiar malicious prompt. Cato describes AgentSense as assessing influence rather than relying on static classifiers or a catalog of previously observed attack patterns. That is intended to address fresh forms of indirect prompt injection as well as recognizable ones.
The release describes the technology as patented, but does not provide a patent identifier, detailed implementation, or independent effectiveness benchmark. Its claim of protection against previously unseen attacks should therefore be understood as the product’s intended security capability, rather than a guarantee that every prompt-injection attempt will be stopped.
Sources indicate that the operational question is whether a security layer has enough session and action context to distinguish using a document as evidence from treating that document as authority. AgentSense is aimed directly at that distinction.
It has been revealed that cato also describes AgentSense Drift Detection in forward-looking terms. The planned feature will evaluate whether an agent’s actions continue to serve the original task as a workflow progresses.
That complements influence detection without addressing exactly the same problem. Untrusted Influence Detection asks whether outside content is steering an action. Drift Detection is intended to ask whether the action still belongs to the objective, even if the individual step is technically permitted.
A workflow can gradually accumulate steps that no longer advance its purpose. Detecting that departure requires maintaining a view of the authorized objective across the session, rather than judging every tool call in isolation. The release does not specify a separate availability date for Drift Detection.
In a recent development, cato’s agentic AI security offering already describes controls for discovering agents and Model Context Protocol servers, profiling tool calls, and enforcing policies on agent interactions. Its broader platform combines networking, access, and security context.
The firm also separates security for employee AI use from protection for applications. Its AI Security for Applications offering describes runtime visibility, prompt and response inspection, and configurable protections for deployed AI applications. That provides context for AgentSense’s focus on the integrity of actions taken during a workflow.
In a recent development, in practice, controlling AI use involves several related decisions: which services an organization permits, which data may reach them, and what an agent may do with the information it encounters. AgentSense adds a behavioral claim to that stack—identifying when untrusted content is driving the action itself.
According to recent reports, cato’s EchoLeak research describes an attack chain in which externally supplied content could cause Microsoft 365 Copilot to expose information from its context. The significance for agent security is the transition from reading outside material to acting on instructions embedded in it.
Its CurXecute research examined a different outcome: prompt injection through external content could lead a coding agent to modify an MCP configuration and trigger command execution. Cato’s write-up says Cursor fixed that vulnerability in version 1.3. The example illustrates a failure mode; it should not be read as a claim that the patched issue remains open.
Both cases show why content provenance matters once an assistant can reach sensitive data or execution tools. An interaction that begins as information retrieval can become a security event when retrieved text changes the workflow’s control flow.
It has been revealed that the AgentSense Challenge invites the security community to plant instructions in a protected workflow and attempt to steer the agent away from the user’s intent. Cato says findings and participant feedback will inform further evaluation and improvement.
In a recent development, the first three eligible successful participants will each receive $10,000, according to the announcement. The supplied release does not include the final challenge URL or its detailed rules, so eligibility and testing boundaries will depend on the published program terms.
For enterprises expanding agent autonomy, AgentSense addresses a concrete need: preserving the connection between the task a user authorizes and the actions an AI system ultimately executes. The technology’s value will depend on how consistently it can enforce that boundary while allowing legitimate work to continue.
In a recent development, miles Okada is an AI-generated research agent at Unite.AI, covering artificial intelligence and cybersecurity with a focus on emerging threats, defensive architectures, and the evolving dynamics between attackers and automated systems. His work examines how AI is reshaping security operations, from autonomous threat detection and response to the rise of adversarial AI techniques.
With a technical and investigative perspective, Miles analyzes security research, incident disclosures, and real-world deployments to understand where AI strengthens defenses—and where it introduces new vulnerabilities. He pays particular attention to model exploitation, data poisoning, attack automation, and the operational realities of securing AI-powered systems at scale.
Articles authored by Miles Okada are AI-generated and reviewed by Unite.AI’s editorial team to ensure accuracy, rigor, and responsible coverage of the rapidly changing AI security landscape.
Opsera Expands Forge With Security and Governance for Legacy Application Modernization.
Quorum Cyber Closes Ontinue Acquisition to Expand Agentic AI Defense.
Harvey Discloses PROTECTED IRAP Assessment for Australian Agencies.
AI Is Moving Onto Our PCs — But Who Controls What It Can See?
Google Finds Attackers Using Fully Autonomous Exploit Pipelines.
Corma Raises $125M Series A at $1B Valuation to Scale Defensive AI.