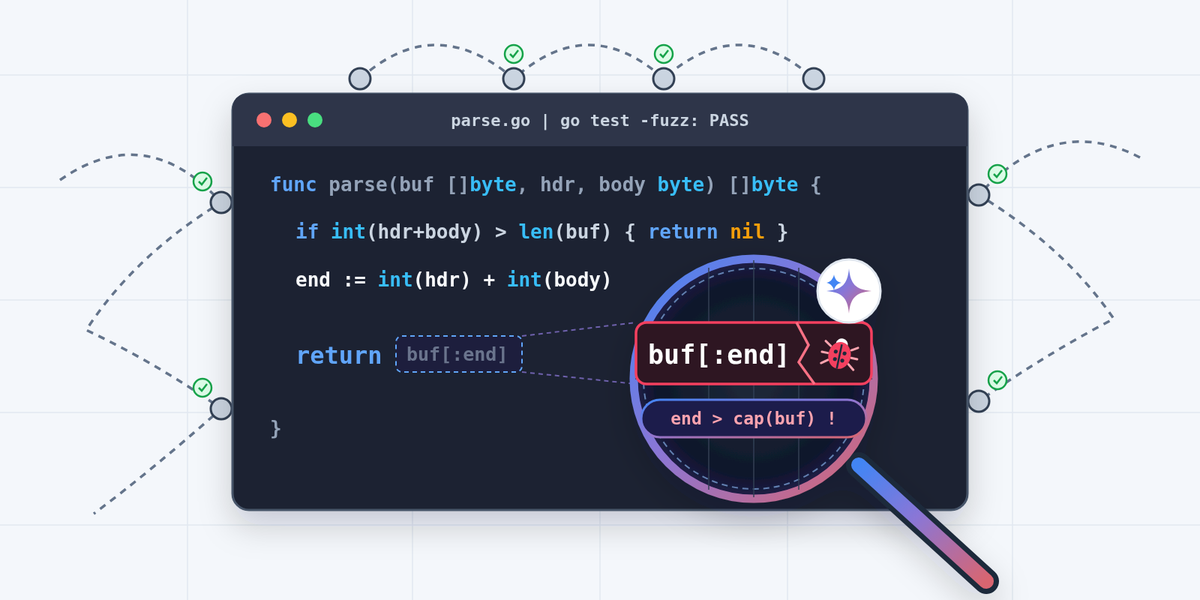
According to recent reports, I help lead Google's agent skills program, presently with 175 agent skills that supplement community collections like go-skills. To keep that many skill files consistent, I wrote skill-lint, a standalone Go CLI that checks SKILL.md files and applies LLM-generated line edits before they ship. Even with skill-lint's own unit and fuzz test suite, a small slice or line-number mistake inside its Markdown parsers or edit applier can sit dormant until an unusual file or edit range triggers a runtime panic in the linter.
In Go, every slice or index operation that can panic at runtime compiles down to an explicit bounds-check trap in machine code, after the compiler's optimizer strips out the checks it can already rule out. To hunt for crashes, I compiled key functions from my code to see which panic traps survived optimization, and Gemini 4 Argon translated the path to each trap into rules for the Z3 constraint solver. An LLM-written solver model isn't a sound proof system, but it gives the agent an independent way to reason about control flow and synthesize concrete Go reproducers, and every crash it finds is real because go test runs the offending bytes directly. That workflow caught all three bugs I planted in test parsers and turned up three latent bugs in skill-lint.
In this post, I'll walk through how the Gemini and Z3 pipeline works, why go test -fuzz missed two of those crashes (and the one-line change that fixes it), and where this approach fits in a day-to-day Go workflow.
A recent post from Anthropic showed how formal verification catches latent bugs in C and C++ by having frontier AI models write machine-checked Rocq proofs across OSS-Fuzz libraries. Instead of sampling random inputs like a fuzzer, a formal tool works backward from each failure condition to solve for the exact input that triggers it. Full theorem proving is still too heavy for most day-to-day Go projects, so I wanted to see how much of that bug-hunting power an agent can get from an LLM and a constraint solver in about a minute per function.
In a recent development, in C and C++, reading or writing past the end of a buffer corrupts memory. Go catches out-of-bounds access at runtime instead, compiling every slice or index operation it can't prove safe into an explicit branch to runtime.panicBounds that panics, crashing the process unless recovered.
Before generating machine code, Go's SSA prove pass already eliminates most of those checks by tracking slice lengths and loop variables. That optimization pass leaves behind only the runtime.panicBounds traps the compiler couldn't rule out on its own, giving the solver a short list of candidate crash sites to target.
I compiled each target with GOOS=linux GOARCH=riscv64 go build -gcflags="-S -d=ssa/check_bce/debug=1" (-S prints the assembly listing and ssa/check_bce/debug=1 logs every surviving bounds check) and passed both the Go source and the disassembly to the model. Looking at Go source alone, you can't see which bounds checks the compiler already removed or where a register gets truncated to 8 bits; in the disassembly, both show up. I targeted RISC-V because it's the instruction set Anthropic's post targets for its Rocq proofs, and Go cross-compiles to it out of the box.
Industry observers note that from there, Argon read the Go source and disassembly and returned a Z3 script modeling the path to each surviving trap, along with a patched function whenever it flagged a bug. Z3 then checked whether those constraints could be satisfied, and whenever it found a crashing input, go test replayed those bytes against the real function. Using an LLM saved me from translating assembly into solver constraints by hand. Argon's translation dominated the runtime, at about a minute per function, while Z3 itself finished in milliseconds.